mirror of
https://github.com/denizsafak/abogen.git
synced 2026-09-20 19:50:59 +02:00
Compare commits
533
Commits
v1.2.4
...
aaa6ac112b
| Author | SHA1 | Date | |
|---|---|---|---|
 Deniz Şafak |
aaa6ac112b | ||
|
Deniz Şafak
|
11274ad6bf | ||
|
Deniz Şafak
|
f340b976db | ||
|
Deniz Şafak
|
9da15aefa4 | ||
|
Deniz Şafak
|
919aea9295 | ||
|
SimonFoobar648
|
ce1fc0c880 | ||
|
Artem Akymenko
|
94e6b3f62e | ||
|
Artem Akymenko
|
d334266238 | ||
|
Artem Akymenko
|
2d18501839 | ||
|
Artem Akymenko
|
464bf8e17d | ||
|
Artem Akymenko
|
9bf4f8e809 | ||
|
Artem Akymenko
|
f802fb2af6 | ||
|
Artem Akymenko
|
c293cc90f6 | ||
|
Artem Akymenko
|
696ce1ebd0 | ||
|
Artem Akymenko
|
d3ded8af0e | ||
|
Artem Akymenko
|
c706f7714a | ||
|
Artem Akymenko
|
2b70b9ca45 | ||
|
Artem Akymenko
|
953bef1e71 | ||
|
Artem Akymenko
|
146cc81271 | ||
|
Artem Akymenko
|
61204cc389 | ||
|
Artem Akymenko
|
f7a224cc46 | ||
|
Artem Akymenko
|
98ab2d925e | ||
|
Artem Akymenko
|
625b6610e2 | ||
|
Artem Akymenko
|
0dc491e420 | ||
|
Artem Akymenko
|
713abdfd73 | ||
|
Artem Akymenko
|
73f42e9563 | ||
|
Artem Akymenko
|
2c61f55f81 | ||
|
Artem Akymenko
|
6497e8c47a | ||
|
Artem Akymenko
|
0b953d48e8 | ||
|
Artem Akymenko
|
f516cf1985 | ||
|
Artem Akymenko
|
3857c27aae | ||
|
Artem Akymenko
|
7ed2addb11 | ||
|
Artem Akymenko
|
cfc7de7abf | ||
|
Artem Akymenko
|
654c395943 | ||
|
Artem Akymenko
|
d1a84cfb8b | ||
|
Artem Akymenko
|
332934c0cf | ||
|
Artem Akymenko
|
c79838a5a1 | ||
|
Artem Akymenko
|
d51a9118e4 | ||
|
Artem Akymenko
|
3311bef2f7 | ||
|
Artem Akymenko
|
4123cadd87 | ||
|
Artem Akymenko
|
2f83d10a1e | ||
|
Artem Akymenko
|
a1241ee9ca | ||
|
Artem Akymenko
|
0ee5bb0496 | ||
|
Artem Akymenko
|
7d28b7eb52 | ||
|
Deniz Şafak
|
9201f58770 | ||
|
Deniz Şafak
|
6274a02d5e | ||
|
Deniz Şafak
|
342ea0dfac | ||
|
Deniz Şafak
|
27f88b759d | ||
|
Deniz Şafak
|
dbcbb1c8a9 | ||
|
Deniz Şafak
|
bd99ee1ba1 | ||
|
Deniz Şafak
|
d5cddb9749 | ||
|
Deniz Şafak
|
ec55918b04 | ||
|
Deniz Şafak
|
14913b45e9 | ||
|
Deniz Şafak
|
a0fdabd81f | ||
|
Deniz Şafak
|
473631b84e | ||
|
Deniz Şafak
|
0f5003dfdd | ||
|
Artem Akymenko
|
fcec4e9fe5 | ||
|
Artem Akymenko
|
72d5e3d1db | ||
|
Artem Akymenko
|
d3682e7672 | ||
|
Artem Akymenko
|
0805e9fdae | ||
|
Artem Akymenko
|
4aef73ff85 | ||
|
Artem Akymenko
|
f6a8008f51 | ||
|
Artem Akymenko
|
dc5257252f | ||
|
Artem Akymenko
|
c4cebb8822 | ||
|
Artem Akymenko
|
93f5a46485 | ||
|
Artem Akymenko
|
5f169a4921 | ||
|
Artem Akymenko
|
df5705779e | ||
|
Artem Akymenko
|
d0fe221176 | ||
|
Artem Akymenko
|
17700426fd | ||
|
Artem Akymenko
|
16b3f7d8a8 | ||
|
Artem Akymenko
|
1a3741ec50 | ||
|
Artem Akymenko
|
7f317ca784 | ||
|
Artem Akymenko
|
d0e42ee691 | ||
|
Artem Akymenko
|
b1392084e1 | ||
|
Artem Akymenko
|
71916aa39f | ||
|
Artem Akymenko
|
4c4434c309 | ||
|
Artem Akymenko
|
7973de3868 | ||
|
Artem Akymenko
|
fd659d0f4f | ||
|
Artem Akymenko
|
e53251ef81 | ||
|
Artem Akymenko
|
cd3cc9bce7 | ||
|
Artem Akymenko
|
75a3ad517a | ||
|
Artem Akymenko
|
a6b7ce69aa | ||
|
Artem Akymenko
|
680418fa1d | ||
|
Artem Akymenko
|
53b850ef41 | ||
|
Artem Akymenko
|
7ed4eca68c | ||
|
Artem Akymenko
|
e1e49e8a0f | ||
|
Artem Akymenko
|
28998e1e5c | ||
|
Artem Akymenko
|
8a220a936c | ||
|
Artem Akymenko
|
ccc2cdb166 | ||
|
Artem Akymenko
|
79ff7e4682 | ||
|
Artem Akymenko
|
2a54b8fdf1 | ||
|
Artem Akymenko
|
68e5adb091 | ||
|
Artem Akymenko
|
c4870eece6 | ||
|
Artem Akymenko
|
8144a7a507 | ||
|
Artem Akymenko
|
f38700025a | ||
|
Artem Akymenko
|
804517f5b2 | ||
|
Artem Akymenko
|
5d30903149 | ||
|
Artem Akymenko
|
476063bc3d | ||
|
Artem Akymenko
|
079e185108 | ||
|
Artem Akymenko
|
69c398ebf0 | ||
|
Artem Akymenko
|
dbe73254a4 | ||
|
Artem Akymenko
|
64e8a8f4e6 | ||
|
Artem Akymenko
|
aec3462f1f | ||
|
Artem Akymenko
|
1193185833 | ||
|
Artem Akymenko
|
a99cf58c79 | ||
|
Artem Akymenko
|
fe62b6b44c | ||
|
Artem Akymenko
|
0e216f3786 | ||
|
Artem Akymenko
|
380cdee0cb | ||
|
Artem Akymenko
|
c76cf74efc | ||
|
Sanjay Santhanam
|
7340d52ebb | ||
|
Artem Akymenko
|
a299947bb1 | ||
|
Artem Akymenko
|
957c6778f6 | ||
|
Artem Akymenko
|
fcdaf2b2a8 | ||
|
Artem Akymenko
|
d8634f812d | ||
|
Artem Akymenko
|
85b5851786 | ||
|
Artem Akymenko
|
e77c8b3372 | ||
|
Artem Akymenko
|
294069e53e | ||
|
Artem Akymenko
|
4ff09be664 | ||
|
Artem Akymenko
|
a1d93820b1 | ||
|
Artem Akymenko
|
0c1a3c1904 | ||
|
Artem Akymenko
|
2228f37c06 | ||
|
Artem Akymenko
|
832e2c5197 | ||
|
Artem Akymenko
|
17229b2390 | ||
|
Artem Akymenko
|
c2c584e741 | ||
|
Artem Akymenko
|
8ccdc85ccb | ||
|
Artem Akymenko
|
ef07a8b5b2 | ||
|
Artem Akymenko
|
1268a83cff | ||
|
Artem Akymenko
|
ef6faff2e8 | ||
|
Artem Akymenko
|
da9d5e7eb9 | ||
|
Artem Akymenko
|
acb000b9e6 | ||
|
Artem Akymenko
|
d6c66dc18a | ||
|
Artem Akymenko
|
0d46076bf6 | ||
|
Artem Akymenko
|
7fef9c1d93 | ||
|
Artem Akymenko
|
56cfd0810d | ||
|
Artem Akymenko
|
7bd3177241 | ||
|
Artem Akymenko
|
d5c2a81733 | ||
|
Artem Akymenko
|
514e29a761 | ||
|
Artem Akymenko
|
86042a3315 | ||
|
Artem Akymenko
|
50d75eb2fc | ||
|
Artem Akymenko
|
ae9ab70421 | ||
|
Artem Akymenko
|
4364276a5b | ||
|
Artem Akymenko
|
914e77de46 | ||
|
Artem Akymenko
|
1d7a2aeed6 | ||
|
Artem Akymenko
|
a26e02b017 | ||
|
Artem Akymenko
|
c94347b33b | ||
|
Artem Akymenko
|
b7a48e3204 | ||
|
Artem Akymenko
|
feb38a24ec | ||
|
Artem Akymenko
|
f63590932d | ||
|
Artem Akymenko
|
7777e58f1d | ||
|
Artem Akymenko
|
364c179bd6 | ||
|
Artem Akymenko
|
60ba01557e | ||
|
Artem Akymenko
|
39eac9b032 | ||
|
Artem Akymenko
|
1499a3b426 | ||
|
Artem Akymenko
|
013c80b92c | ||
|
Artem Akymenko
|
62f42a9f79 | ||
|
Bryan Nathan
|
2c4d13bf56 | ||
|
Artem Akymenko
|
b7026a666d | ||
|
Artem Akymenko
|
c380a58496 | ||
|
Artem Akymenko
|
b8386b43f7 | ||
|
Artem Akymenko
|
26e71cc2ac | ||
|
Artem Akymenko
|
d8fcfb1cce | ||
|
Artem Akymenko
|
c85ea9d64f | ||
|
Artem Akymenko
|
f151a1ae0d | ||
|
Artem Akymenko
|
096ea58d74 | ||
|
Artem Akymenko
|
65cb0c75e5 | ||
|
Artem Akymenko
|
780e9bd780 | ||
|
Artem Akymenko
|
c094b94704 | ||
|
Artem Akymenko
|
735098d7cd | ||
|
Artem Akymenko
|
5d1e7165bb | ||
|
Artem Akymenko
|
9150a80459 | ||
|
Artem Akymenko
|
a76d338931 | ||
|
Artem Akymenko
|
985e16f1f8 | ||
|
Artem Akymenko
|
25d45ffd36 | ||
|
Artem Akymenko
|
6284c501ed | ||
|
Artem Akymenko
|
23f1efcc62 | ||
|
Artem Akymenko
|
a05357bab9 | ||
|
Artem Akymenko
|
d129b0abe8 | ||
|
Artem Akymenko
|
6eda8516cc | ||
|
Artem Akymenko
|
0f568120f4 | ||
|
Artem Akymenko
|
79b3d26f66 | ||
|
Artem Akymenko
|
f1cc6deae8 | ||
|
Artem Akymenko
|
6f25fc06d0 | ||
|
Artem Akymenko
|
32c4d533c9 | ||
|
Artem Akymenko
|
146000886d | ||
|
Artem Akymenko
|
31f95137dd | ||
|
Artem Akymenko
|
6f02fda41c | ||
|
Artem Akymenko
|
a3c3462348 | ||
|
Artem Akymenko
|
79332204d3 | ||
|
Artem Akymenko
|
6deec3b9b6 | ||
|
Artem Akymenko
|
c4d14112d4 | ||
|
Artem Akymenko
|
f4cb2c2329 | ||
|
Artem Akymenko
|
783738882f | ||
|
Artem Akymenko
|
e94ba5257e | ||
|
Artem Akymenko
|
49d66839dc | ||
|
Artem Akymenko
|
d0e316ea7b | ||
|
Artem Akymenko
|
bb96ae502c | ||
|
Artem Akymenko
|
a4d25accc1 | ||
|
Artem Akymenko
|
66964bfd0b | ||
|
Artem Akymenko
|
f8f72624f8 | ||
|
Artem Akymenko
|
e7a88a513a | ||
|
Artem Akymenko
|
2277f16d0a | ||
|
Artem Akymenko
|
1d50429b87 | ||
|
Artem Akymenko
|
29681a5fbb | ||
|
Artem Akymenko
|
50fa2e5b9e | ||
|
Artem Akymenko
|
5816feb6da | ||
|
Artem Akymenko
|
b95df8f217 | ||
|
Artem Akymenko
|
245e67284e | ||
|
Artem Akymenko
|
e2557d961b | ||
|
Artem Akymenko
|
9c6b3774b4 | ||
|
Artem Akymenko
|
fd9fe5579a | ||
|
Artem Akymenko
|
f079373821 | ||
|
Deniz Şafak
|
fbb5d4e368 | ||
|
Artem Akymenko
|
57fec453e2 | ||
|
Artem Akymenko
|
58fe22e3d5 | ||
|
Deniz Şafak
|
ab8cbc4911 | ||
|
Deniz Şafak
|
5e2048072a | ||
|
Artem Akymenko
|
66ed2a202d | ||
|
Artem Akymenko
|
45e859dac4 | ||
|
Deniz Şafak
|
56d3e414b3 | ||
|
Deniz Şafak
|
b942bcb820 | ||
|
Artem Akymenko
|
47efcb4420 | ||
|
Artem Akymenko
|
7b3f9d8615 | ||
|
Artem Akymenko
|
9833bb0843 | ||
|
Deniz Şafak
|
cbc05ead42 | ||
|
Artem Akymenko
|
50b4d6872a | ||
|
Yash
|
da68f38b9b | ||
|
Deniz Şafak
|
9fa81fbe1e | ||
|
JoaGamo
|
9fd9fad238 | ||
|
Deniz Şafak
|
ca5c5ee62d | ||
|
olandir
|
e51be95bc1 | ||
|
olandirandClaude Sonnet 4.6
|
2223f46c9e | ||
|
Deniz Şafak
|
8322f7f416 | ||
|
Vladimir Sol
|
2c15d2f78a | ||
|
Deniz Şafak
|
cc9c2a22ba | ||
|
Deniz Şafak
|
d1366b445d | ||
|
Andrei Benea
|
c224cdbb56 | ||
|
Deniz Şafak
|
d30415ffe7 | ||
|
Deniz Şafak
|
083f1eb09b | ||
|
Deniz Şafak
|
30929e8f4e | ||
|
Deniz Şafak
|
ded73843c9 | ||
|
Deniz ŞafakandCopilot
|
7b1f4f54ee | ||
|
Deniz ŞafakandCopilot
|
8cbfc15028 | ||
|
Deniz Şafak
|
79957d09ed | ||
|
Deniz Şafak
|
925ef51edc | ||
|
Deniz Şafak
|
be7c7baa75 | ||
|
Deniz Şafak
|
6ab863e65f | ||
|
Deniz Şafak
|
950eb317f0 | ||
|
Deniz Şafak
|
bd30939d27 | ||
|
Deniz Şafak
|
ace1022da4 | ||
|
Mohan Krishnan
|
eb7d135bc3 | ||
|
Deniz Şafak
|
5ae153f841 | ||
|
Deniz Şafak
|
3c800df450 | ||
|
Deniz Şafak
|
fc0af420c6 | ||
|
Deniz Şafak
|
7677f5a1e2 | ||
|
Deniz Şafak
|
0e726b97c4 | ||
|
JB
|
b5b157879f | ||
|
JB
|
27041c6475 | ||
|
JB
|
7df4345486 | ||
|
JB
|
5b174737ad | ||
|
JB
|
1219b408b5 | ||
|
JB
|
b2058ef3ee | ||
|
JB
|
d1e0e0a536 | ||
|
JB
|
4272c847f7 | ||
|
JB
|
89645682f1 | ||
|
JB
|
e2b2f610a6 | ||
|
Deniz Şafak
|
76cab1192c | ||
|
Mohan Krishnan
|
1fdd1c8540 | ||
|
JB
|
ede5343e0c | ||
|
JB
|
63d179ba19 | ||
|
JB
|
90786d2bed | ||
|
JB
|
c2209eeb2a | ||
|
JB
|
899c9f5aa5 | ||
|
JB
|
938e122166 | ||
|
JB
|
5303dcf681 | ||
|
JB
|
b47952b857 | ||
|
JB
|
0fe8ee0ad4 | ||
|
JB
|
5dd53354a1 | ||
|
JB
|
eb57744533 | ||
|
JB
|
de8debb6b1 | ||
|
JB
|
e47536e2ab | ||
|
JB
|
32f616e90b | ||
|
JB
|
19e98c3ad6 | ||
|
JB
|
eabfe87ffb | ||
|
JB
|
9a72c209b3 | ||
|
JB
|
888c737293 | ||
|
JB
|
77eb58bdff | ||
|
JB
|
95d5921e67 | ||
|
JB
|
08ebedc177 | ||
|
Deniz Şafak
|
1c33a99554 | ||
|
JB
|
015435adb6 | ||
|
JB
|
0afaaf561b | ||
|
JB
|
fdf95dbae7 | ||
|
JB
|
05d7c28128 | ||
|
JB
|
aa71783e5a | ||
|
cedarhillgoods
|
0c8a7cdf81 | ||
|
JB
|
daf4d78766 | ||
|
Deniz Şafak
|
66a97835f0 | ||
|
Deniz Şafak
|
0d097f562a | ||
|
Deniz Şafak
|
a7ae13558c | ||
|
Deniz Şafak
|
5735f05be0 | ||
|
Deniz Şafak
|
c3673b6dc7 | ||
|
Your Name
|
675ed437c8 | ||
|
Deniz Şafak
|
5010616e85 | ||
|
Deniz Şafak
|
65eecbcfee | ||
|
Deniz Şafak
|
c9b17b6f49 | ||
|
Deniz Şafak
|
7722863435 | ||
|
Deniz Şafak
|
6a1928483b | ||
|
Deniz Şafak
|
2a20dfab6f | ||
|
Deniz Şafak
|
a2f186e7a1 | ||
|
Deniz Şafak
|
56f81ef892 | ||
|
Deniz Şafak
|
968c673e58 | ||
|
Deniz Şafak
|
174ff4232f | ||
|
Deniz Şafak
|
c43659005e | ||
|
Deniz Şafak
|
e3cdd1a9ca | ||
|
Deniz Şafak
|
ed31aaf632 | ||
|
Deniz Şafak
|
0820c40b14 | ||
|
Deniz Şafak
|
0ac2810515 | ||
|
Deniz Şafak
|
1c3fd9e4cf | ||
|
JB
|
ef2b045b69 | ||
|
JB
|
196e2cdf2e | ||
|
JB
|
a501e96b12 | ||
|
JB
|
1e13c901fe | ||
|
JB
|
609af66748 | ||
|
JB
|
2e1e9af995 | ||
|
JB
|
40eb294fec | ||
|
JB
|
b502ff9068 | ||
|
JB
|
a14469c1d0 | ||
|
JB
|
aa53438acf | ||
|
JB
|
baef01ad45 | ||
|
JB
|
7eceb601f8 | ||
|
JB
|
b3aaa94831 | ||
|
JB
|
c7dd8cf13a | ||
|
JB
|
7db1779ca5 | ||
|
JB
|
76b3aae341 | ||
|
JB
|
07c78255e8 | ||
|
JB
|
040bce1bc1 | ||
|
JB
|
540b191d5b | ||
|
JB
|
079c36702e | ||
|
JB
|
59c8568348 | ||
|
JB
|
f2ba8f692c | ||
|
JB
|
2e1f38a98b | ||
|
JB
|
3d073e8e55 | ||
|
JB
|
cc641cec78 | ||
|
JB
|
aa45228844 | ||
|
JB
|
6cc2b4e8a4 | ||
|
JB
|
252be6d4b7 | ||
|
JB
|
bce1419d92 | ||
|
JB
|
b0a3e1dbd9 | ||
|
JB
|
8a2bd7ec50 | ||
|
Deniz Şafak
|
e96c19ace6 | ||
|
JB
|
a5f2bf7fbe | ||
|
JB
|
4bfce0f900 | ||
|
JB
|
5b548cc155 | ||
|
JB
|
c69e5af54d | ||
|
JB
|
48e9534b68 | ||
|
JB
|
a9489dec2d | ||
|
JB
|
94983c39bb | ||
|
JB
|
963b020c0f | ||
|
JB
|
83e0841274 | ||
|
JB
|
726decfaf4 | ||
|
JB
|
319037fe8c | ||
|
JB
|
c00cbaef69 | ||
|
JB
|
124e5b33db | ||
|
JB
|
fd93e1c9e9 | ||
|
JB
|
d08cbcfdc9 | ||
|
JB
|
0a2b3533f4 | ||
|
JB
|
ad70c630c7 | ||
|
JB
|
39628453de | ||
|
Deniz Şafak
|
4e678c7e13 | ||
|
JB
|
7cc60aacf6 | ||
|
Deniz Şafak
|
7ee40d6aca | ||
|
JB
|
775e05f94c | ||
|
JB
|
550fdbf537 | ||
|
JB
|
d0532347be | ||
|
JB
|
3ef95900cc | ||
|
JB
|
71dfbd49b6 | ||
|
JB
|
166162931c | ||
|
JB
|
aba72524ce | ||
|
JB
|
028384e6ee | ||
|
JB
|
504b5ab5e5 | ||
|
JB
|
95f0307be1 | ||
|
JB
|
67453ed17c | ||
|
JB
|
4491674fac | ||
|
JB
|
387d324ea0 | ||
|
JB
|
acede32559 | ||
|
JB
|
4e06601b04 | ||
|
JB
|
f2ab62aeab | ||
|
JB
|
72b2ada9ac | ||
|
JB
|
af90da0b99 | ||
|
JB
|
d238524cbb | ||
|
JB
|
2d61674e90 | ||
|
JB
|
28652d9e78 | ||
|
JB
|
1d9dcf8800 | ||
|
JB
|
5322c6406d | ||
|
JB
|
1d4316ad18 | ||
|
JB
|
8aaf183f75 | ||
|
JB
|
eb28b01c06 | ||
|
JB
|
65ec77180d | ||
|
JB
|
0906b590a6 | ||
|
JB
|
b9e3fb5e1c | ||
|
JB
|
fe5419565d | ||
|
JB
|
688d550f13 | ||
|
JB
|
c7356338c2 | ||
|
JB
|
13c6b120c9 | ||
|
JB
|
9acec3c309 | ||
|
JB
|
013c5c2dbb | ||
|
JB
|
e7f6f0221d | ||
|
JB
|
963ef71647 | ||
|
JB
|
b8a6ca7091 | ||
|
JB
|
cf6ccf0171 | ||
|
JB
|
eb4704bc26 | ||
|
JB
|
0fc32e9f3a | ||
|
JB
|
67f4493d06 | ||
|
JB
|
de0f17cd57 | ||
|
JB
|
6e536c6e3b | ||
|
JB
|
9d35e39e89 | ||
|
JB
|
a81ed70b14 | ||
|
JB
|
7951a4d992 | ||
|
JB
|
10cd2c993c | ||
|
JB
|
0259963eb8 | ||
|
JB
|
6b5255a80d | ||
|
JB
|
0a6d09445d | ||
|
JB
|
6ae8b827d2 | ||
|
JB
|
6248dfdc0c | ||
|
JB
|
7ca030d67d | ||
|
JB
|
bccfd9f5c5 | ||
|
JB
|
f7541388e6 | ||
|
JB
|
62d4acc4d6 | ||
|
JB
|
0922ad4727 | ||
|
JB
|
a5543528ba | ||
|
JB
|
14cc7103cf | ||
|
JB
|
1f0cfef310 | ||
|
JB
|
5971630803 | ||
|
JB
|
b3dc73cb15 | ||
|
JB
|
0f549a56e4 | ||
|
JB
|
cab5221c46 | ||
|
JB
|
d114ae60fe | ||
|
JB
|
3e54007baa | ||
|
JB
|
ded405ff70 | ||
|
JB
|
eb78347a85 | ||
|
JB
|
a2c08b1b4d | ||
|
JB
|
9ee53fc886 | ||
|
JB
|
82d780db0d | ||
|
JB
|
17534d7890 | ||
|
JB
|
b4c9a1ced8 | ||
|
JB
|
8e9c9e6077 | ||
|
JB
|
7d11ebc338 | ||
|
JB
|
e6d2649d5d | ||
|
JB
|
091a3785e6 | ||
|
JB
|
ec6dc25e23 | ||
|
JB
|
f8d2e860fe | ||
|
JB
|
b8b0aea890 | ||
|
JB
|
7203037a42 | ||
|
JB
|
93fe48f601 | ||
|
JB
|
610091c0d9 | ||
|
JB
|
6266819670 | ||
|
JB
|
4a62363064 | ||
|
JB
|
ccf5a11222 | ||
|
JB
|
8ed5202ab8 | ||
|
JB
|
4b0aa50da6 | ||
|
JB
|
97fd8b85fc | ||
|
JB
|
5be4da1cce | ||
|
JB
|
3e7bbd648c | ||
|
JB
|
e15d2b12a3 | ||
|
JB
|
aed0df1b09 | ||
|
JB
|
60fe7e7ffb | ||
|
JB
|
20327faf0c | ||
|
JB
|
be37f03109 | ||
|
JB
|
f35b35c7a9 | ||
|
JB
|
283651e7dd | ||
|
JB
|
4f46eb74f4 | ||
|
JB
|
15c1220ba3 | ||
|
JB
|
443dee09b6 | ||
|
JB
|
3a91e79cb6 | ||
|
JB
|
258c3549f7 | ||
|
JB
|
e7408a06b8 | ||
|
JB
|
e37ef99856 | ||
|
JB
|
01a6267c7a | ||
|
JB
|
f0b6976d12 | ||
|
JB
|
6bd301b707 | ||
|
JB
|
205c435e72 | ||
|
JB
|
9828730061 | ||
|
JB
|
da0c453205 | ||
|
JB
|
63f9474741 | ||
|
JB
|
b0875c7486 | ||
|
JB
|
881717c4cb | ||
|
JB
|
d01887f31b | ||
|
JB
|
1bae37477b | ||
|
JB
|
3b07df9708 | ||
|
JB
|
b0cfd8d687 | ||
|
JB
|
41f56a8491 | ||
|
JB
|
bacf1b2f9e | ||
|
JB
|
6181f12bd4 | ||
|
JB
|
da56966247 | ||
|
JB
|
783dbcf8f2 | ||
|
JB
|
b35ab7b002 | ||
|
JB
|
4b3aa227b7 | ||
|
JB
|
42334e92a4 | ||
|
JB
|
a51fd25271 | ||
|
JB
|
02da72434b | ||
|
JB
|
0dd74412d1 | ||
|
JB
|
ea1c7bd93e | ||
|
JB
|
718a3fa1c0 | ||
|
JB
|
85310ad916 | ||
|
JB
|
c8e9eb6fd2 | ||
|
JB
|
43bee0b76e | ||
|
JB
|
fd8ede318f | ||
|
JB
|
e76701ab32 | ||
|
JB
|
0d74171bb5 | ||
|
JB
|
477c5055b4 | ||
|
JB
|
523e55d8a4 | ||
|
JB
|
c19050261c | ||
|
JB
|
dc7a115e2e | ||
|
JB
|
153d5ba92c | ||
|
JB
|
26e0e764db | ||
|
JB
|
7d132e6fcc | ||
|
JB
|
b75e1c1b2e | ||
|
JB
|
fc4c41c7cf | ||
|
JB
|
f3aaeda37b | ||
|
JB
|
323ab08f38 | ||
|
JB
|
54bc632b2e | ||
|
JB
|
5497697741 | ||
|
JB
|
1b907be322 | ||
|
JB
|
e44ba1e903 | ||
|
JB
|
97d81d78e2 | ||
|
JB
|
01209f6878 | ||
|
JB
|
2e402f6b5b | ||
|
JB
|
0c47067cb8 | ||
|
JB
|
b718dae1b3 | ||
|
JB
|
9ba2362528 | ||
|
JB
|
1629d3e80c | ||
|
JB
|
66a0679e18 | ||
|
JB
|
338ff104e8 |
@@ -0,0 +1,44 @@
|
|||||||
|
# Copy this file to `.env` and customize the paths to match your environment.
|
||||||
|
# Relative paths are resolved from the repository root when running locally.
|
||||||
|
# Each `*_DIR` value below points to a directory on the host. Docker Compose
|
||||||
|
# mounts it into the container at the standard path noted in the comment.
|
||||||
|
|
||||||
|
# Host directory that stores JSON settings. Mounted to /config in Docker.
|
||||||
|
ABOGEN_SETTINGS_DIR=./config
|
||||||
|
|
||||||
|
# Host directory for rendered audio/subtitle files. Mounted to /data/outputs
|
||||||
|
# in Docker.
|
||||||
|
ABOGEN_OUTPUT_DIR=./storage/output
|
||||||
|
|
||||||
|
# Temporary working directory. When running in Docker, keep this inside the
|
||||||
|
# mounted data volume (or another writable host path) so non-root users can
|
||||||
|
# write to it. Only audio conversion scratch files are staged here by default;
|
||||||
|
# other library caches remain inside the container volume. For local
|
||||||
|
# (non-Docker) usage, change this to a path that makes sense on your machine or
|
||||||
|
# comment it out to fall back to the OS cache directory. Mounted to /data/cache
|
||||||
|
# in Docker.
|
||||||
|
ABOGEN_TEMP_DIR=./storage/tmp
|
||||||
|
|
||||||
|
# UID/GID used when running the Docker container. 1000:1000 matches most Linux hosts.
|
||||||
|
# Find your current values with:
|
||||||
|
# id -u # UID
|
||||||
|
# id -g # GID
|
||||||
|
ABOGEN_UID=1000
|
||||||
|
ABOGEN_GID=1000
|
||||||
|
|
||||||
|
# Network mode for the Docker container. Options:
|
||||||
|
# bridge (default) - Isolated container network, uses port mapping
|
||||||
|
# host - Container uses host's network directly, required for
|
||||||
|
# accessing LAN resources like Calibre OPDS servers
|
||||||
|
# ABOGEN_NETWORK_MODE=host
|
||||||
|
|
||||||
|
# Optional: Seed the web UI with working defaults for the LLM-powered
|
||||||
|
# text normalization features. Leave these blank to configure everything
|
||||||
|
# from the Settings page.
|
||||||
|
ABOGEN_LLM_BASE_URL=http://localhost:11434 # Supply the server root; /v1 is added automatically.
|
||||||
|
ABOGEN_LLM_API_KEY=ollama
|
||||||
|
ABOGEN_LLM_MODEL=llama3.1:8b
|
||||||
|
ABOGEN_LLM_TIMEOUT=45
|
||||||
|
ABOGEN_LLM_CONTEXT_MODE=sentence
|
||||||
|
# For custom prompts, keep the text on a single line or escape newlines.
|
||||||
|
#ABOGEN_LLM_PROMPT=Provide regex replacements for any apostrophes in {{sentence}} using apply_regex_replacements.
|
||||||
@@ -0,0 +1,15 @@
|
|||||||
|
*.py text eol=lf
|
||||||
|
*.md text eol=lf
|
||||||
|
*.yml text eol=lf
|
||||||
|
*.yaml text eol=lf
|
||||||
|
*.toml text eol=lf
|
||||||
|
*.json text eol=lf
|
||||||
|
*.txt text eol=lf
|
||||||
|
*.html text eol=lf
|
||||||
|
*.css text eol=lf
|
||||||
|
*.js text eol=lf
|
||||||
|
*.sh text eol=lf
|
||||||
|
*.cfg text eol=lf
|
||||||
|
*.ini text eol=lf
|
||||||
|
*.svg text eol=lf
|
||||||
|
*.j2 text eol=lf
|
||||||
@@ -0,0 +1,15 @@
|
|||||||
|
# These are supported funding model platforms
|
||||||
|
|
||||||
|
github: [jborza, jeremiahsb, mohangk, k0sm0naft]
|
||||||
|
patreon: # Replace with a single Patreon username
|
||||||
|
open_collective: # Replace with a single Open Collective username
|
||||||
|
ko_fi: # Replace with a single Ko-fi username
|
||||||
|
tidelift: # Replace with a single Tidelift platform-name/package-name e.g., npm/babel
|
||||||
|
community_bridge: # Replace with a single Community Bridge project-name e.g., cloud-foundry
|
||||||
|
liberapay: # Replace with a single Liberapay username
|
||||||
|
issuehunt: # Replace with a single IssueHunt username
|
||||||
|
lfx_crowdfunding: # Replace with a single LFX Crowdfunding project-name e.g., cloud-foundry
|
||||||
|
polar: # Replace with a single Polar username
|
||||||
|
buy_me_a_coffee: # Replace with a single Buy Me a Coffee username
|
||||||
|
thanks_dev: # Replace with a single thanks.dev username
|
||||||
|
custom: # Replace with up to 4 custom sponsorship URLs e.g., ['link1', 'link2']
|
||||||
@@ -1,7 +1,9 @@
|
|||||||
name: pip install
|
name: CI
|
||||||
run-name: pip install
|
run-name: CI
|
||||||
|
|
||||||
on:
|
on:
|
||||||
push:
|
push:
|
||||||
|
branches: [main]
|
||||||
paths:
|
paths:
|
||||||
- '**.py'
|
- '**.py'
|
||||||
- 'pyproject.toml'
|
- 'pyproject.toml'
|
||||||
@@ -11,23 +13,41 @@ on:
|
|||||||
- 'pyproject.toml'
|
- 'pyproject.toml'
|
||||||
- '.github/workflows/**'
|
- '.github/workflows/**'
|
||||||
workflow_dispatch:
|
workflow_dispatch:
|
||||||
|
|
||||||
jobs:
|
jobs:
|
||||||
install-and-run:
|
test:
|
||||||
strategy:
|
strategy:
|
||||||
matrix:
|
matrix:
|
||||||
os: [ubuntu-latest, macos-latest, windows-latest]
|
os: [ubuntu-latest, macos-14, windows-latest]
|
||||||
python-version: ['3.12']
|
python-version: ['3.12']
|
||||||
fail-fast: false
|
fail-fast: false
|
||||||
continue-on-error: true
|
|
||||||
runs-on: ${{ matrix.os }}
|
runs-on: ${{ matrix.os }}
|
||||||
steps:
|
steps:
|
||||||
- name: Checkout repository
|
- name: Checkout repository
|
||||||
uses: actions/checkout@v4
|
uses: actions/checkout@v7
|
||||||
|
|
||||||
- name: Set up Python
|
- name: Set up Python
|
||||||
uses: actions/setup-python@v5
|
uses: actions/setup-python@v6
|
||||||
with:
|
with:
|
||||||
python-version: ${{ matrix.python-version }}
|
python-version: ${{ matrix.python-version }}
|
||||||
- name: Install from repository
|
|
||||||
run: python -m pip install .
|
- name: Install uv
|
||||||
#- name: Run abogen
|
uses: astral-sh/setup-uv@v8.3.1
|
||||||
# run: abogen
|
with:
|
||||||
|
enable-cache: true
|
||||||
|
prune-cache: false
|
||||||
|
cache-dependency-glob: pyproject.toml
|
||||||
|
|
||||||
|
- name: Install system dependencies (Ubuntu)
|
||||||
|
if: runner.os == 'Linux'
|
||||||
|
run: sudo apt-get update && sudo apt-get install -y libegl1
|
||||||
|
|
||||||
|
- name: Install dependencies
|
||||||
|
run: uv pip install --system .[dev]
|
||||||
|
env:
|
||||||
|
UV_LINK_MODE: copy
|
||||||
|
|
||||||
|
- name: Run tests
|
||||||
|
env:
|
||||||
|
QT_QPA_PLATFORM: offscreen
|
||||||
|
run: pytest tests/ -v --tb=short
|
||||||
|
|||||||
@@ -18,7 +18,7 @@ jobs:
|
|||||||
build:
|
build:
|
||||||
runs-on: ubuntu-latest
|
runs-on: ubuntu-latest
|
||||||
steps:
|
steps:
|
||||||
- uses: actions/checkout@v4
|
- uses: actions/checkout@v7
|
||||||
|
|
||||||
- name: Login to Github Container Registry
|
- name: Login to Github Container Registry
|
||||||
# Only if we need to push an image
|
# Only if we need to push an image
|
||||||
|
|||||||
+10
@@ -19,6 +19,7 @@ __pycache__/
|
|||||||
env/
|
env/
|
||||||
venv/
|
venv/
|
||||||
.env/
|
.env/
|
||||||
|
.env
|
||||||
.venv/
|
.venv/
|
||||||
test/
|
test/
|
||||||
|
|
||||||
@@ -30,6 +31,15 @@ python_embedded/
|
|||||||
|
|
||||||
# abogen
|
# abogen
|
||||||
*config.json
|
*config.json
|
||||||
|
config/
|
||||||
|
storage/
|
||||||
build/
|
build/
|
||||||
dist/
|
dist/
|
||||||
.old/
|
.old/
|
||||||
|
test_assets/
|
||||||
|
dev_notes/
|
||||||
|
.claude/
|
||||||
|
.coverage
|
||||||
|
|
||||||
|
# CodeGraph index (local, machine-specific)
|
||||||
|
.codegraph/
|
||||||
|
|||||||
@@ -0,0 +1 @@
|
|||||||
|
3.12
|
||||||
+22
-2
@@ -1,3 +1,23 @@
|
|||||||
|
# 1.3.0
|
||||||
|
- Special thanks to [@jeremiahsb](https://github.com/jeremiahsb) for his [massive contribution](https://github.com/denizsafak/abogen/pull/120) (>55k lines!) that brought the Web UI, EPUB 3 pipeline, and core architectural improvements to life.
|
||||||
|
- Added an EPUB 3 packaging pipeline that builds media-overlay EPUBs from generated audio and chunk metadata.
|
||||||
|
- Persisted chunk timing metadata in job artifacts and exercised the exporter with automated tests.
|
||||||
|
- Added Flask-based Web UI (`abogen-web`) for Docker and headless server deployments.
|
||||||
|
- Reorganized codebase to support both PyQt6 desktop GUI and Web UI from a shared core.
|
||||||
|
- Added Supertonic TTS engine support with GPU acceleration.
|
||||||
|
- Added entity analysis and pronunciation override system for proper nouns.
|
||||||
|
- Added speaker/role assignment for multi-voice "theatrical" audiobooks.
|
||||||
|
- Added Calibre OPDS and Audiobookshelf integration.
|
||||||
|
|
||||||
|
# 1.2.5
|
||||||
|
- Added new option: `Override item settings with current selection` in the queue manager. When enabled, all items in the queue will be processed using the current global settings selected in the main GUI, overriding their individual settings. When disabled, each item will retain its own specific settings.
|
||||||
|
- Fixed `Error "Could not load the Qt platform plugin "xcb"` error that occurred in some Linux distributions due to missing `libxcb-cursor0` library by conditionally loading the bundled library when the system version is unavailable, issue mentioned by @bmcgonag in #101.
|
||||||
|
- Fixed the `No module named pip` error that occurred for users who installed Abogen via the [**uv**](https://github.com/astral-sh/uv) installer.
|
||||||
|
- Fixed defaults for `replace_single_newlines` not being applied correctly in some cases.
|
||||||
|
- Fixed `Save chapters separately for queued epubs is ignored`, issue mentioned by @dymas-cz in #109.
|
||||||
|
- Fixed incorrect sentence segmentation when using spaCy, where text would erroneously split after opening parentheses.
|
||||||
|
- Improvements in code and documentation.
|
||||||
|
|
||||||
# 1.2.4
|
# 1.2.4
|
||||||
- **Subtitle generation is now available for all languages!** Abogen now supports subtitle generation for non-English languages using audio duration-based timing. Available modes include `Line`, `Sentence`, and `Sentence + Comma`. (Note: Word-level subtitle modes remain English-only due to Kokoro's timestamp token limitations.)
|
- **Subtitle generation is now available for all languages!** Abogen now supports subtitle generation for non-English languages using audio duration-based timing. Available modes include `Line`, `Sentence`, and `Sentence + Comma`. (Note: Word-level subtitle modes remain English-only due to Kokoro's timestamp token limitations.)
|
||||||
- New option: **"Use spaCy for sentence segmentation"** You can now use [spaCy](https://spacy.io/) to automatically detect sentence boundaries and produce cleaner, more readable subtitles. Quick summary:
|
- New option: **"Use spaCy for sentence segmentation"** You can now use [spaCy](https://spacy.io/) to automatically detect sentence boundaries and produce cleaner, more readable subtitles. Quick summary:
|
||||||
@@ -44,7 +64,7 @@
|
|||||||
- Fixed `/` and `\` path display by normalizing paths.
|
- Fixed `/` and `\` path display by normalizing paths.
|
||||||
- Fixed book reprocessing issue where books were being processed every time the chapters window was opened, improving performance when reopening the same book.
|
- Fixed book reprocessing issue where books were being processed every time the chapters window was opened, improving performance when reopening the same book.
|
||||||
- Fixed taskbar icon not appearing correctly in Windows.
|
- Fixed taskbar icon not appearing correctly in Windows.
|
||||||
- Fixed “Go to folder” button not opening the chapter output directory when only separate chapters were generated.
|
- Fixed "Go to folder" button not opening the chapter output directory when only separate chapters were generated.
|
||||||
- Improvements in code and documentation.
|
- Improvements in code and documentation.
|
||||||
|
|
||||||
# 1.1.9
|
# 1.1.9
|
||||||
@@ -173,7 +193,7 @@
|
|||||||
- Improved invalid profile handling in the voice mixer.
|
- Improved invalid profile handling in the voice mixer.
|
||||||
|
|
||||||
# v1.0.3
|
# v1.0.3
|
||||||
- Added voice mixing, allowing multiple voices to be combined into a single “Mixed Voice”, a feature mentioned by @PulsarFTW in #1. Special thanks to @jborza for making this possible through his contributions in #5.
|
- Added voice mixing, allowing multiple voices to be combined into a single "Mixed Voice", a feature mentioned by @PulsarFTW in #1. Special thanks to @jborza for making this possible through his contributions in #5.
|
||||||
- Added profile system to voice mixer, allowing users to create and manage multiple voice profiles.
|
- Added profile system to voice mixer, allowing users to create and manage multiple voice profiles.
|
||||||
- Improvements in the voice mixer, mostly for organizing controls and enhancing user experience.
|
- Improvements in the voice mixer, mostly for organizing controls and enhancing user experience.
|
||||||
- Added icons for flags and genders in the GUI, making it easier to identify different options.
|
- Added icons for flags and genders in the GUI, making it easier to identify different options.
|
||||||
|
|||||||
@@ -4,6 +4,7 @@
|
|||||||
[](https://github.com/denizsafak/abogen/releases/latest)
|
[](https://github.com/denizsafak/abogen/releases/latest)
|
||||||
[](https://pypi.org/project/abogen/)
|
[](https://pypi.org/project/abogen/)
|
||||||
[](https://github.com/denizsafak/abogen/releases/latest)
|
[](https://github.com/denizsafak/abogen/releases/latest)
|
||||||
|
[](https://pypi.org/project/abogen/)
|
||||||
[](https://github.com/psf/black)
|
[](https://github.com/psf/black)
|
||||||
[](https://opensource.org/licenses/MIT)
|
[](https://opensource.org/licenses/MIT)
|
||||||
|
|
||||||
@@ -17,14 +18,14 @@ Abogen is a powerful text-to-speech conversion tool that makes it easy to turn e
|
|||||||
|
|
||||||
https://github.com/user-attachments/assets/094ba3df-7d66-494a-bc31-0e4b41d0b865
|
https://github.com/user-attachments/assets/094ba3df-7d66-494a-bc31-0e4b41d0b865
|
||||||
|
|
||||||
> This demo was generated in just 5 seconds, producing ∼1 minute of audio with perfectly synced subtitles. To create a similar video, see [the demo guide](https://github.com/denizsafak/abogen/tree/main/demo).
|
> This demo was generated in just 5 seconds, producing ∼1 minute of audio with perfectly synced subtitles. To create a similar video, see [the demo guide](https://github.com/denizsafak/abogen/tree/main/demo).
|
||||||
|
|
||||||
## `How to install?` <a href="https://pypi.org/project/abogen/" target="_blank"><img src="https://img.shields.io/pypi/pyversions/abogen" alt="Abogen Compatible PyPi Python Versions" align="right" style="margin-top:6px;"></a>
|
## `How to install?` <a href="https://pypi.org/project/abogen/" target="_blank"><img src="https://img.shields.io/pypi/pyversions/abogen" alt="Abogen Compatible PyPi Python Versions" align="right" style="margin-top:6px;"></a>
|
||||||
|
|
||||||
### Windows
|
### `Windows`
|
||||||
Go to [espeak-ng latest release](https://github.com/espeak-ng/espeak-ng/releases/latest) download and run the *.msi file.
|
Go to [espeak-ng latest release](https://github.com/espeak-ng/espeak-ng/releases/latest) download and run the *.msi file.
|
||||||
|
|
||||||
#### OPTION 1: Install using script
|
#### <b>OPTION 1: Install using script</b>
|
||||||
1. [Download](https://github.com/denizsafak/abogen/archive/refs/heads/main.zip) the repository
|
1. [Download](https://github.com/denizsafak/abogen/archive/refs/heads/main.zip) the repository
|
||||||
2. Extract the ZIP file
|
2. Extract the ZIP file
|
||||||
3. Run `WINDOWS_INSTALL.bat` by double-clicking it
|
3. Run `WINDOWS_INSTALL.bat` by double-clicking it
|
||||||
@@ -34,7 +35,26 @@ This method handles everything automatically - installing all dependencies inclu
|
|||||||
> [!NOTE]
|
> [!NOTE]
|
||||||
> You don't need to install Python separately. The script will install Python automatically.
|
> You don't need to install Python separately. The script will install Python automatically.
|
||||||
|
|
||||||
#### OPTION 2: Install using pip
|
#### <b>OPTION 2: Install using uv</b>
|
||||||
|
First, [install uv](https://docs.astral.sh/uv/getting-started/installation/) if you haven't already.
|
||||||
|
|
||||||
|
```bash
|
||||||
|
# For NVIDIA GPUs (CUDA 12.8) - Recommended
|
||||||
|
uv tool install --python 3.12 abogen[cuda] --extra-index-url https://download.pytorch.org/whl/cu128 --index-strategy unsafe-best-match
|
||||||
|
|
||||||
|
# For NVIDIA GPUs (CUDA 12.6) - Older drivers
|
||||||
|
uv tool install --python 3.12 abogen[cuda126] --extra-index-url https://download.pytorch.org/whl/cu126 --index-strategy unsafe-best-match
|
||||||
|
|
||||||
|
# For NVIDIA GPUs (CUDA 13.0) - Newer drivers
|
||||||
|
uv tool install --python 3.12 abogen[cuda130] --extra-index-url https://download.pytorch.org/whl/cu130 --index-strategy unsafe-best-match
|
||||||
|
|
||||||
|
# For AMD GPUs or without GPU - If you have AMD GPU, you need to use Linux for GPU acceleration, because ROCm is not available on Windows.
|
||||||
|
uv tool install --python 3.12 abogen
|
||||||
|
```
|
||||||
|
|
||||||
|
<details>
|
||||||
|
<summary><b>Alternative: Install using pip (click to expand)</b></summary>
|
||||||
|
|
||||||
```bash
|
```bash
|
||||||
# Create a virtual environment (optional)
|
# Create a virtual environment (optional)
|
||||||
mkdir abogen && cd abogen
|
mkdir abogen && cd abogen
|
||||||
@@ -52,7 +72,26 @@ pip install torch==2.8.0+cu128 torchvision==0.23.0+cu128 torchaudio==2.8.0 --ind
|
|||||||
pip install abogen
|
pip install abogen
|
||||||
```
|
```
|
||||||
|
|
||||||
### Mac
|
</details>
|
||||||
|
|
||||||
|
### `Mac`
|
||||||
|
|
||||||
|
First, [install uv](https://docs.astral.sh/uv/getting-started/installation/) if you haven't already.
|
||||||
|
|
||||||
|
```bash
|
||||||
|
# Install espeak-ng
|
||||||
|
brew install espeak-ng
|
||||||
|
|
||||||
|
# For Silicon Mac (M1, M2 etc.)
|
||||||
|
uv tool install --python 3.13 abogen --with "kokoro @ git+https://github.com/hexgrad/kokoro.git,numpy<2"
|
||||||
|
|
||||||
|
# For Intel Mac
|
||||||
|
uv tool install --python 3.12 abogen --with "kokoro @ git+https://github.com/hexgrad/kokoro.git,numpy<2"
|
||||||
|
```
|
||||||
|
|
||||||
|
<details>
|
||||||
|
<summary><b>Alternative: Install using pip (click to expand)</b></summary>
|
||||||
|
|
||||||
```bash
|
```bash
|
||||||
# Install espeak-ng
|
# Install espeak-ng
|
||||||
brew install espeak-ng
|
brew install espeak-ng
|
||||||
@@ -69,7 +108,29 @@ pip3 install abogen
|
|||||||
# After installing abogen, we need to install Kokoro's development version which includes MPS support.
|
# After installing abogen, we need to install Kokoro's development version which includes MPS support.
|
||||||
pip3 install git+https://github.com/hexgrad/kokoro.git
|
pip3 install git+https://github.com/hexgrad/kokoro.git
|
||||||
```
|
```
|
||||||
### Linux
|
|
||||||
|
</details>
|
||||||
|
|
||||||
|
### `Linux`
|
||||||
|
|
||||||
|
First, [install uv](https://docs.astral.sh/uv/getting-started/installation/) if you haven't already.
|
||||||
|
|
||||||
|
```bash
|
||||||
|
# Install espeak-ng
|
||||||
|
sudo apt install espeak-ng # Ubuntu/Debian
|
||||||
|
sudo pacman -S espeak-ng # Arch Linux
|
||||||
|
sudo dnf install espeak-ng # Fedora
|
||||||
|
|
||||||
|
# For NVIDIA GPUs or without GPU - No need to include [cuda] in here.
|
||||||
|
uv tool install --python 3.12 abogen
|
||||||
|
|
||||||
|
# For AMD GPUs (ROCm 6.4)
|
||||||
|
uv tool install --python 3.12 abogen[rocm] --extra-index-url https://download.pytorch.org/whl/nightly/rocm6.4 --index-strategy unsafe-best-match
|
||||||
|
```
|
||||||
|
|
||||||
|
<details>
|
||||||
|
<summary><b>Alternative: Install using pip (click to expand)</b></summary>
|
||||||
|
|
||||||
```bash
|
```bash
|
||||||
# Install espeak-ng
|
# Install espeak-ng
|
||||||
sudo apt install espeak-ng # Ubuntu/Debian
|
sudo apt install espeak-ng # Ubuntu/Debian
|
||||||
@@ -92,6 +153,8 @@ pip3 install abogen
|
|||||||
pip3 uninstall torch
|
pip3 uninstall torch
|
||||||
pip3 install --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/rocm6.4
|
pip3 install --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/rocm6.4
|
||||||
```
|
```
|
||||||
|
</details>
|
||||||
|
|
||||||
|
|
||||||
> See [How to fix "CUDA GPU is not available. Using CPU" warning?](#cuda-warning)
|
> See [How to fix "CUDA GPU is not available. Using CPU" warning?](#cuda-warning)
|
||||||
|
|
||||||
@@ -101,16 +164,32 @@ pip3 install --pre torch torchvision torchaudio --index-url https://download.pyt
|
|||||||
|
|
||||||
> See [How to fix "[WinError 1114] A dynamic link library (DLL) initialization routine failed" error?](#WinError-1114)
|
> See [How to fix "[WinError 1114] A dynamic link library (DLL) initialization routine failed" error?](#WinError-1114)
|
||||||
|
|
||||||
> See [How to use "uv" instead of "pip"?](#use-uv-instead-of-pip)
|
|
||||||
|
|
||||||
> Special thanks to [@hg000125](https://github.com/hg000125) for his contribution in [#23](https://github.com/denizsafak/abogen/issues/23). AMD GPU support is possible thanks to his work.
|
> Special thanks to [@hg000125](https://github.com/hg000125) for his contribution in [#23](https://github.com/denizsafak/abogen/issues/23). AMD GPU support is possible thanks to his work.
|
||||||
|
|
||||||
|
|
||||||
|
## Interfaces
|
||||||
|
|
||||||
|
Abogen offers **two interfaces**, but currently they have different feature sets. The **Web UI** contains newer features that are still being integrated into the desktop application.
|
||||||
|
|
||||||
|
| Command | Interface | Features |
|
||||||
|
|---------|-----------|----------|
|
||||||
|
| `abogen` | PyQt6 Desktop GUI | Stable core features |
|
||||||
|
| `abogen-web` | Flask Web UI | Core features + **Supertonic TTS**, **LLM Normalization**, **Audiobookshelf Integration** and more! |
|
||||||
|
|
||||||
|
> **Note:** The Web UI is under active development. We are working to integrate these new features into the PyQt desktop app. until then, the Web UI provides the most feature-rich experience.
|
||||||
|
|
||||||
|
> Special thanks to [@jeremiahsb](https://github.com/jeremiahsb) for making this possible! I was honestly surprised by his [massive contribution](https://github.com/denizsafak/abogen/pull/120) (>55,000 lines!) that brought the entire Web UI to life.
|
||||||
|
|
||||||
|
# 🖥️ Desktop Application (PyQt)
|
||||||
|
|
||||||
## `How to run?`
|
## `How to run?`
|
||||||
If you installed using pip, you can simply run the following command to start Abogen:
|
|
||||||
|
You can simply run this command to start Abogen Desktop GUI:
|
||||||
|
|
||||||
```bash
|
```bash
|
||||||
abogen
|
abogen
|
||||||
```
|
```
|
||||||
|
|
||||||
> [!TIP]
|
> [!TIP]
|
||||||
> If you installed Abogen using the Windows installer `(WINDOWS_INSTALL.bat)`, It should have created a shortcut in the same folder, or your desktop. You can run it from there. If you lost the shortcut, Abogen is located in `python_embedded/Scripts/abogen.exe`. You can run it from there directly.
|
> If you installed Abogen using the Windows installer `(WINDOWS_INSTALL.bat)`, It should have created a shortcut in the same folder, or your desktop. You can run it from there. If you lost the shortcut, Abogen is located in `python_embedded/Scripts/abogen.exe`. You can run it from there directly.
|
||||||
|
|
||||||
@@ -127,7 +206,7 @@ abogen
|
|||||||
## `In action`
|
## `In action`
|
||||||
<img title="Abogen in action" src='https://raw.githubusercontent.com/denizsafak/abogen/refs/heads/main/demo/abogen.gif'>
|
<img title="Abogen in action" src='https://raw.githubusercontent.com/denizsafak/abogen/refs/heads/main/demo/abogen.gif'>
|
||||||
|
|
||||||
Here’s Abogen in action: in this demo, it processes ∼3,000 characters of text in just 11 seconds and turns it into 3 minutes and 28 seconds of audio, and I have a low-end **RTX 2060 Mobile laptop GPU**. Your results may vary depending on your hardware.
|
Here’s Abogen in action: in this demo, it processes ∼3,000 characters of text in just 11 seconds and turns it into 3 minutes and 28 seconds of audio, and I have a low-end **RTX 2060 Mobile laptop GPU**. Your results may vary depending on your hardware.
|
||||||
|
|
||||||
## `Configuration`
|
## `Configuration`
|
||||||
|
|
||||||
@@ -191,14 +270,181 @@ With voice mixer, you can create custom voices by mixing different voice models.
|
|||||||
|
|
||||||
Abogen supports **queue mode**, allowing you to add multiple files to a processing queue. This is useful if you want to convert several files in one batch.
|
Abogen supports **queue mode**, allowing you to add multiple files to a processing queue. This is useful if you want to convert several files in one batch.
|
||||||
|
|
||||||
- You can add text files (`.txt`) directly using the **Add files** button in the Queue Manager. To add PDF, EPUB, or markdown files, use the input box in the main window and click the **Add to Queue** button.
|
- You can add text files (`.txt`) and subtitle files (`.srt`, `.ass`, `.vtt`) directly using the **Add files** button in the Queue Manager or by dragging and dropping them into the queue list. To add PDF, EPUB, or markdown files, use the input box in the main window and click the **Add to Queue** button.
|
||||||
- Each file in the queue keeps the configuration settings that were active when it was added. Changing the main window configuration afterward does **not** affect files already in the queue.
|
- Each file in the queue keeps the configuration settings that were active when it was added. Changing the main window configuration afterward does **not** affect files already in the queue.
|
||||||
|
- You can enable the **Override item settings with current selection** option to force all items in the queue to use the configuration currently selected in the main window, overriding their saved settings.
|
||||||
- You can view each file's configuration by hovering over them.
|
- You can view each file's configuration by hovering over them.
|
||||||
|
|
||||||
Abogen will process each item in the queue automatically, saving outputs as configured.
|
Abogen will process each item in the queue automatically, saving outputs as configured.
|
||||||
|
|
||||||
> Special thanks to [@jborza](https://github.com/jborza) for adding queue mode in PR [#35](https://github.com/denizsafak/abogen/pull/35)
|
> Special thanks to [@jborza](https://github.com/jborza) for adding queue mode in PR [#35](https://github.com/denizsafak/abogen/pull/35)
|
||||||
|
|
||||||
|
---
|
||||||
|
# 🌐 Web Application (WebUI)
|
||||||
|
|
||||||
|
## `How to run?`
|
||||||
|
|
||||||
|
Run this command to start the Web UI:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
abogen-web
|
||||||
|
```
|
||||||
|
Then open http://localhost:8808 and drag in your documents. Jobs run in the background worker and the browser updates automatically.
|
||||||
|
|
||||||
|
<img title="Abogen in action" src='https://raw.githubusercontent.com/denizsafak/abogen/refs/heads/main/demo/abogen-webui.png'>
|
||||||
|
|
||||||
|
## `Using the web UI`
|
||||||
|
1. Upload a document (drag & drop or use the upload button).
|
||||||
|
2. Choose voice, language, speed, subtitle style, and output format.
|
||||||
|
3. Click **Create job**. The job immediately appears in the queue.
|
||||||
|
4. Watch progress and logs update live. Download audio/subtitle assets when complete.
|
||||||
|
5. Cancel or delete jobs any time. Download logs for troubleshooting.
|
||||||
|
|
||||||
|
Multiple jobs can run sequentially; the worker processes them in order.
|
||||||
|
|
||||||
|
## `Container image`
|
||||||
|
You can build a lightweight container image directly from the repository root:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
docker build -t abogen .
|
||||||
|
mkdir -p ~/abogen-data/uploads ~/abogen-data/outputs
|
||||||
|
docker run --rm \
|
||||||
|
-p 8808:8808 \
|
||||||
|
-v ~/abogen-data:/data \
|
||||||
|
--name abogen \
|
||||||
|
abogen
|
||||||
|
```
|
||||||
|
|
||||||
|
Browse to http://localhost:8808. Uploaded source files are stored in `/data/uploads` and rendered audio/subtitles appear in `/data/outputs`.
|
||||||
|
|
||||||
|
### Container environment variables
|
||||||
|
| Variable | Default | Purpose |
|
||||||
|
|----------|---------|---------|
|
||||||
|
| `ABOGEN_HOST` | `0.0.0.0` | Bind address for the Flask server |
|
||||||
|
| `ABOGEN_PORT` | `8808` | HTTP port |
|
||||||
|
| `ABOGEN_DEBUG` | `false` | Enable Flask debug mode |
|
||||||
|
| `ABOGEN_UPLOAD_ROOT` | `/data/uploads` | Directory where uploaded files are stored |
|
||||||
|
| `ABOGEN_OUTPUT_ROOT` | `/data/outputs` | Directory for generated audio and subtitles (legacy alias of `ABOGEN_OUTPUT_DIR`) |
|
||||||
|
| `ABOGEN_OUTPUT_DIR` | `/data/outputs` | Container path for rendered audio/subtitles |
|
||||||
|
| `ABOGEN_SETTINGS_DIR` | `/config` | Container path for JSON settings/configuration |
|
||||||
|
| `ABOGEN_TEMP_DIR` | `/data/cache` (Docker) or platform cache dir | Container path for temporary audio working files |
|
||||||
|
| `ABOGEN_UID` | `1000` | UID that the container should run as (matches host user) |
|
||||||
|
| `ABOGEN_GID` | `1000` | GID that the container should run as (matches host group) |
|
||||||
|
| `ABOGEN_LLM_BASE_URL` | `""` | OpenAI-compatible endpoint used to seed the Settings → LLM panel |
|
||||||
|
| `ABOGEN_LLM_API_KEY` | `""` | API key passed to the endpoint above |
|
||||||
|
| `ABOGEN_LLM_MODEL` | `""` | Default model selected when you refresh the model list |
|
||||||
|
| `ABOGEN_LLM_TIMEOUT` | `30` | Timeout (seconds) for server-side LLM requests |
|
||||||
|
| `ABOGEN_LLM_CONTEXT_MODE` | `sentence` | Default prompt context window (`sentence`, `paragraph`, `document`) |
|
||||||
|
| `ABOGEN_LLM_PROMPT` | `""` | Custom normalization prompt template seeded into the UI |
|
||||||
|
|
||||||
|
Set any of these with `-e VAR=value` when starting the container.
|
||||||
|
|
||||||
|
To discover your local UID/GID for matching file permissions inside the container, run:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
id -u
|
||||||
|
id -g
|
||||||
|
```
|
||||||
|
|
||||||
|
Use those values to populate `ABOGEN_UID` / `ABOGEN_GID` in your `.env` file.
|
||||||
|
|
||||||
|
When running via Docker Compose, set `ABOGEN_SETTINGS_DIR`,
|
||||||
|
`ABOGEN_OUTPUT_DIR`, and `ABOGEN_TEMP_DIR` in your `.env` file to the host
|
||||||
|
directories you want mounted into the container. Compose maps them to
|
||||||
|
`/config`, `/data/outputs`, and `/data/cache` respectively while exporting
|
||||||
|
those in-container paths to the application. Non-audio caches (e.g., Hugging
|
||||||
|
Face downloads) stick to the container's internal cache under `/tmp/abogen-home/.cache`
|
||||||
|
by default, so only conversion scratch data touches the mounted `ABOGEN_TEMP_DIR`.
|
||||||
|
Ensure each host directory exists and is writable by the UID/GID you configure
|
||||||
|
before starting the stack.
|
||||||
|
|
||||||
|
### Docker Compose (GPU by default)
|
||||||
|
The repo includes `docker-compose.yaml`, which targets GPU hosts out of the box. Install the NVIDIA Container Toolkit and run:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
docker compose up -d --build
|
||||||
|
```
|
||||||
|
|
||||||
|
Key build/runtime knobs:
|
||||||
|
|
||||||
|
- `TORCH_VERSION` – pin a specific PyTorch release that matches your driver (leave blank for the latest on the configured index).
|
||||||
|
- `TORCH_INDEX_URL` – swap out the PyTorch download index when targeting a different CUDA build.
|
||||||
|
- `ABOGEN_DATA` – host path that stores uploads/outputs (defaults to `./data`).
|
||||||
|
|
||||||
|
CPU-only deployment: comment out the `deploy.resources.reservations.devices` block (and the optional `runtime: nvidia` line) inside the compose file. Compose will then run without requesting a GPU. If you prefer the classic CLI:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
docker build -f abogen/Dockerfile -t abogen-gpu .
|
||||||
|
docker run --rm \
|
||||||
|
--gpus all \
|
||||||
|
-p 8808:8808 \
|
||||||
|
-v ~/abogen-data:/data \
|
||||||
|
abogen-gpu
|
||||||
|
```
|
||||||
|
|
||||||
|
## `LLM-assisted text normalization`
|
||||||
|
Abogen can hand tricky apostrophes and contractions to an OpenAI-compatible large language model. Configure it from **Settings → LLM**:
|
||||||
|
|
||||||
|
1. Enter the base URL for your endpoint (Ollama, OpenAI proxy, etc.) and an API key if required. Use the server root (for Ollama: `http://localhost:11434`)—Abogen appends `/v1/...` automatically, but it also accepts inputs that already end in `/v1`.
|
||||||
|
2. Click **Refresh models** to load the catalog, pick a default model, and adjust the timeout or prompt template.
|
||||||
|
3. Use the preview box to test the prompt, then save the settings. The Normalization panel can synthesize a short audio preview with the current configuration.
|
||||||
|
|
||||||
|
When you are running inside Docker or a CI pipeline, seed the form automatically with `ABOGEN_LLM_*` variables in your `.env` file. The `.env.example` file includes sample values for a local Ollama server.
|
||||||
|
|
||||||
|
## `Audiobookshelf integration`
|
||||||
|
Abogen can push finished audiobooks directly into Audiobookshelf. Configure this under **Settings → Integrations → Audiobookshelf** by providing:
|
||||||
|
|
||||||
|
- **Base URL** – the HTTPS origin (and optional path prefix) where your Audiobookshelf server is reachable, for example `https://abs.example.com` or `https://media.example.com/abs`. Do **not** append `/api`.
|
||||||
|
- **Library ID** – the identifier of the target Audiobookshelf library (copy it from the library’s settings page in ABS).
|
||||||
|
- **Folder (name or ID)** – the destination folder inside that library. Enter the folder name exactly as it appears in Audiobookshelf (Abogen resolves it to the correct ID automatically), paste the raw `folderId`, or click **Browse folders** to fetch the available folders and populate the field.
|
||||||
|
- **API token** – a personal access token generated in Audiobookshelf under *Account → API tokens*.
|
||||||
|
|
||||||
|
You can enable automatic uploads for future jobs or trigger individual uploads from the queue once the connection succeeds.
|
||||||
|
|
||||||
|
### Reverse proxy checklist (Nginx Proxy Manager)
|
||||||
|
When Audiobookshelf sits behind Nginx Proxy Manager (NPM), make sure the API paths and headers reach the backend untouched:
|
||||||
|
|
||||||
|
1. Create a **Proxy Host** that points to your ABS container or host (default forward port `13378`).
|
||||||
|
2. Under the **SSL** tab, enable your certificate and tick **Force SSL** if you want HTTPS only.
|
||||||
|
3. In the **Advanced** tab, append the snippet below so bearer tokens, client IPs, and large uploads survive the proxy hop:
|
||||||
|
```nginx
|
||||||
|
proxy_set_header Host $host;
|
||||||
|
proxy_set_header X-Real-IP $remote_addr;
|
||||||
|
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
|
||||||
|
proxy_set_header X-Forwarded-Proto $scheme;
|
||||||
|
proxy_set_header X-Forwarded-Host $host;
|
||||||
|
proxy_set_header X-Forwarded-Port $server_port;
|
||||||
|
proxy_set_header Authorization $http_authorization;
|
||||||
|
client_max_body_size 5g;
|
||||||
|
proxy_read_timeout 300s;
|
||||||
|
proxy_connect_timeout 300s;
|
||||||
|
```
|
||||||
|
4. Disable **Block Common Exploits** (it strips Authorization headers in some NPM builds).
|
||||||
|
5. Enable **Websockets Support** on the main proxy screen (Audiobookshelf uses it for the web UI, and it keeps the reverse proxy configuration consistent).
|
||||||
|
6. If you publish Audiobookshelf under a path prefix (for example `/abs`), add a **Custom Location** with `Location: /abs/` and set the **Forward Path** to `/`. That rewrite strips the `/abs` prefix before traffic reaches Audiobookshelf so `/abs/api/...` on the internet becomes `/api/...` on the backend. Use the same prefixed URL in Abogen’s “Base URL” field.
|
||||||
|
|
||||||
|
After saving the proxy host, test the API from the machine running Abogen:
|
||||||
|
|
||||||
|
```bash
|
||||||
|
curl -i "https://abs.example.com/api/libraries" \
|
||||||
|
-H "Authorization: Bearer YOUR_API_TOKEN"
|
||||||
|
```
|
||||||
|
|
||||||
|
If you still receive `Cannot GET /api/...`, the proxy is rewriting paths. Double-check the **Custom Locations** table (the `Forward Path` column should be empty for `/abs/`) and review the NPM access/error logs while issuing the curl request to confirm the backend sees the full `/api/libraries` URL.
|
||||||
|
|
||||||
|
A JSON response confirming the libraries list means the proxy is routing API calls correctly. You can then use **Browse folders** to confirm the library contents, run **Test connection** in Abogen’s settings (it verifies the library and resolves the folder), and use the “Send to Audiobookshelf” button on completed jobs.
|
||||||
|
|
||||||
|
## `JSON endpoints`
|
||||||
|
Need machine-readable status updates? The dashboard calls a small set of helper endpoints you can reuse:
|
||||||
|
- `GET /api/jobs/<id>` returns job metadata, progress, and log lines in JSON.
|
||||||
|
- `GET /partials/jobs` renders the live job list as HTML (htmx uses this for polling).
|
||||||
|
- `GET /partials/jobs/<id>/logs` renders just the log window.
|
||||||
|
|
||||||
|
More automation hooks are planned; contributions are very welcome if you need additional routes.
|
||||||
|
|
||||||
|
---
|
||||||
|
# Core Features (Available in Both)
|
||||||
|
|
||||||
## `About Chapter Markers`
|
## `About Chapter Markers`
|
||||||
When you process ePUB, PDF or markdown files, Abogen converts them into text files stored in your cache directory. When you click "Edit," you're actually modifying these converted text files. In these text files, you'll notice tags that look like this:
|
When you process ePUB, PDF or markdown files, Abogen converts them into text files stored in your cache directory. When you click "Edit," you're actually modifying these converted text files. In these text files, you'll notice tags that look like this:
|
||||||
|
|
||||||
@@ -272,6 +518,9 @@ For a complete list of supported languages and voices, refer to Kokoro's [VOICES
|
|||||||
|
|
||||||
> See [How to fix Japanese audio not working?](#japanese-audio-not-working)
|
> See [How to fix Japanese audio not working?](#japanese-audio-not-working)
|
||||||
|
|
||||||
|
---
|
||||||
|
# Guides & Troubleshooting
|
||||||
|
|
||||||
## `MPV Config`
|
## `MPV Config`
|
||||||
I highly recommend using [MPV](https://mpv.io/installation/) to play your audio files, as it supports displaying subtitles even without a video track. Here's my `mpv.conf`:
|
I highly recommend using [MPV](https://mpv.io/installation/) to play your audio files, as it supports displaying subtitles even without a video track. Here's my `mpv.conf`:
|
||||||
```
|
```
|
||||||
@@ -290,43 +539,6 @@ audio-samplerate=48000
|
|||||||
volume-max=200
|
volume-max=200
|
||||||
```
|
```
|
||||||
|
|
||||||
## `Docker Guide`
|
|
||||||
If you want to run Abogen in a Docker container:
|
|
||||||
1) [Download the repository](https://github.com/denizsafak/abogen/archive/refs/heads/main.zip) and extract, or clone it using git.
|
|
||||||
2) Go to `abogen` folder. You should see `Dockerfile` there.
|
|
||||||
3) Open your termminal in that directory and run the following commands:
|
|
||||||
|
|
||||||
```bash
|
|
||||||
# Build the Docker image:
|
|
||||||
docker build --progress plain -t abogen .
|
|
||||||
|
|
||||||
# Note that building the image may take a while.
|
|
||||||
# After building is complete, run the Docker container:
|
|
||||||
|
|
||||||
# Windows
|
|
||||||
docker run --name abogen -v %cd%:/shared -p 5800:5800 -p 5900:5900 --gpus all abogen
|
|
||||||
|
|
||||||
# Linux
|
|
||||||
docker run --name abogen -v $(pwd):/shared -p 5800:5800 -p 5900:5900 --gpus all abogen
|
|
||||||
|
|
||||||
# MacOS
|
|
||||||
docker run --name abogen -v $(pwd):/shared -p 5800:5800 -p 5900:5900 abogen
|
|
||||||
|
|
||||||
# We expose port 5800 for use by a web browser, 5900 if you want to connect with a VNC client.
|
|
||||||
```
|
|
||||||
|
|
||||||
Abogen launches automatically inside the container.
|
|
||||||
- You can access it via a web browser at [http://localhost:5800](http://localhost:5800) or connect to it using a VNC client at `localhost:5900`.
|
|
||||||
- You can use `/shared` directory to share files between your host and the container.
|
|
||||||
- For later use, start it with `docker start abogen` and stop it with `docker stop abogen`.
|
|
||||||
- Pass in `-e WEB_AUDIO="1"` for `docker run` to enable audio.
|
|
||||||
|
|
||||||
Known issues:
|
|
||||||
- Audio preview is not working inside container (ALSA error) if using a VNC client.
|
|
||||||
- `Open cache directory` and `Open configuration directory` options in settings not working. (Tried pcmanfm, did not work with Abogen).
|
|
||||||
|
|
||||||
> Special thanks to [@geo38](https://www.reddit.com/user/geo38/) from Reddit, who provided the Dockerfile and instructions in [this comment](https://www.reddit.com/r/selfhosted/comments/1k8x1yo/comment/mpe0bz8/).
|
|
||||||
|
|
||||||
## `Similar Projects`
|
## `Similar Projects`
|
||||||
Abogen is a standalone project, but it is inspired by and shares some similarities with other projects. Here are a few:
|
Abogen is a standalone project, but it is inspired by and shares some similarities with other projects. Here are a few:
|
||||||
- [audiblez](https://github.com/santinic/audiblez): Generate audiobooks from e-books. **(Has CLI and GUI support)**
|
- [audiblez](https://github.com/santinic/audiblez): Generate audiobooks from e-books. **(Has CLI and GUI support)**
|
||||||
@@ -388,6 +600,16 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
> ```
|
> ```
|
||||||
>
|
>
|
||||||
> If you have an AMD GPU, you need to use Linux and follow the Linux/ROCm [instructions](#linux). If you want to keep running on CPU, no action is required, but performance will just be reduced. See [#32](https://github.com/denizsafak/abogen/issues/32) for more details.
|
> If you have an AMD GPU, you need to use Linux and follow the Linux/ROCm [instructions](#linux). If you want to keep running on CPU, no action is required, but performance will just be reduced. See [#32](https://github.com/denizsafak/abogen/issues/32) for more details.
|
||||||
|
>
|
||||||
|
> If you used `uv` to install Abogen, you can uninstall and try reinstalling with another CUDA version:
|
||||||
|
> ```bash
|
||||||
|
> # First uninstall Abogen
|
||||||
|
> uv tool uninstall abogen
|
||||||
|
> # Try CUDA 12.6 for older drivers
|
||||||
|
> uv tool install --python 3.12 abogen[cuda126] --extra-index-url https://download.pytorch.org/whl/cu126 --index-strategy unsafe-best-match
|
||||||
|
> # If that doesn't work, try CUDA 13.0 for newer drivers
|
||||||
|
> uv tool install --python 3.12 abogen[cuda130] --extra-index-url https://download.pytorch.org/whl/cu130 --index-strategy unsafe-best-match
|
||||||
|
> ```
|
||||||
|
|
||||||
</details>
|
</details>
|
||||||
|
|
||||||
@@ -406,7 +628,7 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
<a name="no-matching-distribution-found">How to fix "No matching distribution found" error?<a>
|
<a name="no-matching-distribution-found">How to fix "No matching distribution found" error?<a>
|
||||||
</b></summary>
|
</b></summary>
|
||||||
|
|
||||||
> Try installing Abogen on supported Python (3.10 to 3.12) versions. You can use [pyenv](https://github.com/pyenv/pyenv) to manage multiple Python versions easily in Linux. Watch this [video](https://www.youtube.com/watch?v=MVyb-nI4KyI) by NetworkChuck for a quick guide.
|
> Try installing Abogen on supported Python (3.10 to 3.12) versions. I recommend installing with [uv](https://docs.astral.sh/uv/getting-started/installation/). You can also use [pyenv](https://github.com/pyenv/pyenv) to manage multiple Python versions easily on Linux. Watch this [video](https://www.youtube.com/watch?v=MVyb-nI4KyI) by NetworkChuck for a quick guide.
|
||||||
|
|
||||||
</details>
|
</details>
|
||||||
|
|
||||||
@@ -421,7 +643,7 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
> ```
|
> ```
|
||||||
> If you installed Abogen using pip, open your terminal in the virtual environment and run:
|
> If you installed Abogen using pip, open your terminal in the virtual environment and run:
|
||||||
> ```bash
|
> ```bash
|
||||||
> pip install torch==2.8.0 torchaudio==2.8.0 torchvision==0.23.0
|
> pip install torch==2.8.0 torchaudio==2.8.0 torchvision==0.23.0 --index-url https://download.pytorch.org/whl/cu128
|
||||||
> ```
|
> ```
|
||||||
|
|
||||||
</details>
|
</details>
|
||||||
@@ -435,18 +657,6 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
|
|
||||||
</details>
|
</details>
|
||||||
|
|
||||||
<details><summary><b>
|
|
||||||
<a name="use-uv-instead-of-pip">How to use "uv" instead of "pip"?</a>
|
|
||||||
</b></summary>
|
|
||||||
|
|
||||||
> Abogen needs "pip", because Kokoro uses pip to download voice models from HuggingFace Hub. If you want to use "uv" instead of "pip", you can use the following command to run Abogen:
|
|
||||||
>
|
|
||||||
> ```bash
|
|
||||||
> uvx --with pip abogen
|
|
||||||
> ```
|
|
||||||
|
|
||||||
</details>
|
|
||||||
|
|
||||||
<details><summary><b>
|
<details><summary><b>
|
||||||
<a name="use-uv-instead-of-pip">How to uninstall Abogen?</a>
|
<a name="use-uv-instead-of-pip">How to uninstall Abogen?</a>
|
||||||
</b></summary>
|
</b></summary>
|
||||||
@@ -458,6 +668,11 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
>pip uninstall abogen # uninstalls abogen
|
>pip uninstall abogen # uninstalls abogen
|
||||||
>pip cache purge # removes pip cache
|
>pip cache purge # removes pip cache
|
||||||
>```
|
>```
|
||||||
|
>- If you installed Abogen using uv, type:
|
||||||
|
>```bash
|
||||||
|
>uv tool uninstall abogen # uninstalls abogen
|
||||||
|
>uv cache clear # removes uv cache
|
||||||
|
>```
|
||||||
> - If you installed Abogen using the Windows installer (WINDOWS_INSTALL.bat), just remove the folder that contains Abogen. It installs everything inside `python_embedded` folder, no other directories are created.
|
> - If you installed Abogen using the Windows installer (WINDOWS_INSTALL.bat), just remove the folder that contains Abogen. It installs everything inside `python_embedded` folder, no other directories are created.
|
||||||
> - If you installed espeak-ng, you need to remove it separately.
|
> - If you installed espeak-ng, you need to remove it separately.
|
||||||
|
|
||||||
@@ -465,18 +680,35 @@ This will start Abogen in command-line mode and display detailed error messages.
|
|||||||
|
|
||||||
## `Contributing`
|
## `Contributing`
|
||||||
I welcome contributions! If you have ideas for new features, improvements, or bug fixes, please fork the repository and submit a pull request.
|
I welcome contributions! If you have ideas for new features, improvements, or bug fixes, please fork the repository and submit a pull request.
|
||||||
|
|
||||||
### For developers and contributors
|
### For developers and contributors
|
||||||
If you'd like to modify the code and contribute to development, you can [download the repository](https://github.com/denizsafak/abogen/archive/refs/heads/main.zip), extract it and run the following commands to build **or** install the package:
|
If you'd like to modify the code and contribute to development, you can [download the repository](https://github.com/denizsafak/abogen/archive/refs/heads/main.zip), extract it and run the following commands to build **or** install the package:
|
||||||
```bash
|
```bash
|
||||||
# Go to the directory where you extracted the repository and run:
|
# Go to the directory where you extracted the repository and run:
|
||||||
pip install -e . # Installs the package in editable mode
|
pip install -e .[dev] # Installs the package in editable mode with build dependencies
|
||||||
pip install build # Install the build package
|
|
||||||
python -m build # Builds the package in dist folder (optional)
|
python -m build # Builds the package in dist folder (optional)
|
||||||
abogen # Opens the GUI
|
abogen # Opens the GUI
|
||||||
```
|
```
|
||||||
|
> Make sure you are using Python 3.10 to 3.12. You need to create a virtual environment if needed.
|
||||||
|
|
||||||
|
<details>
|
||||||
|
<summary><b>Alternative: Using uv (click to expand)</b></summary>
|
||||||
|
|
||||||
|
```bash
|
||||||
|
# Go to the directory where you extracted the repository and run:
|
||||||
|
uv venv --python 3.12 # Creates a virtual environment with Python 3.12
|
||||||
|
# After activating the virtual environment, run:
|
||||||
|
uv pip install -e . # Installs the package in editable mode
|
||||||
|
uv build # Builds the package in dist folder (optional)
|
||||||
|
abogen # Opens the GUI
|
||||||
|
```
|
||||||
|
|
||||||
|
</details>
|
||||||
|
|
||||||
Feel free to explore the code and make any changes you like.
|
Feel free to explore the code and make any changes you like.
|
||||||
|
|
||||||
## `Credits`
|
## `Credits`
|
||||||
|
- Web UI implementation by [@jeremiahsb](https://github.com/jeremiahsb)
|
||||||
- Abogen uses [Kokoro](https://github.com/hexgrad/kokoro) for its high-quality, natural-sounding text-to-speech synthesis. Huge thanks to the Kokoro team for making this possible.
|
- Abogen uses [Kokoro](https://github.com/hexgrad/kokoro) for its high-quality, natural-sounding text-to-speech synthesis. Huge thanks to the Kokoro team for making this possible.
|
||||||
- Thanks to the [spaCy](https://spacy.io/) project for its sentence-segmentation tools, which help Abogen produce cleaner, more natural sentence segmentation.
|
- Thanks to the [spaCy](https://spacy.io/) project for its sentence-segmentation tools, which help Abogen produce cleaner, more natural sentence segmentation.
|
||||||
- Thanks to [@wojiushixiaobai](https://github.com/wojiushixiaobai) for [Embedded Python](https://github.com/wojiushixiaobai/Python-Embed-Win64) packages. These modified packages include pip pre-installed, enabling Abogen to function as a standalone application without requiring users to separately install Python in Windows.
|
- Thanks to [@wojiushixiaobai](https://github.com/wojiushixiaobai) for [Embedded Python](https://github.com/wojiushixiaobai/Python-Embed-Win64) packages. These modified packages include pip pre-installed, enabling Abogen to function as a standalone application without requiring users to separately install Python in Windows.
|
||||||
@@ -489,7 +721,7 @@ This project is available under the MIT License - see the [LICENSE](https://gith
|
|||||||
[Kokoro](https://github.com/hexgrad/kokoro) is licensed under [Apache-2.0](https://github.com/hexgrad/kokoro/blob/main/LICENSE) which allows commercial use, modification, distribution, and private use.
|
[Kokoro](https://github.com/hexgrad/kokoro) is licensed under [Apache-2.0](https://github.com/hexgrad/kokoro/blob/main/LICENSE) which allows commercial use, modification, distribution, and private use.
|
||||||
|
|
||||||
## `Star History`
|
## `Star History`
|
||||||
[](https://www.star-history.com/#denizsafak/abogen&Date)
|
[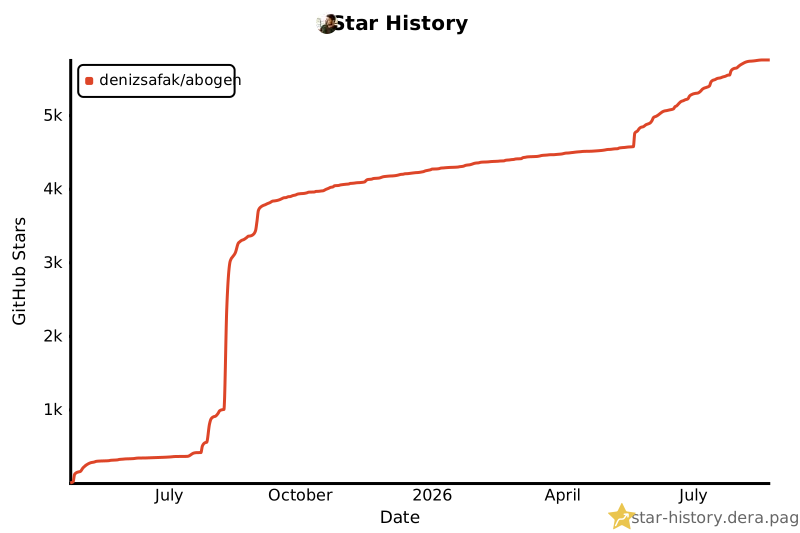](https://star-history.dera.page/#denizsafak/abogen&Date)
|
||||||
|
|
||||||
> [!NOTE]
|
> [!NOTE]
|
||||||
> Abogen supports subtitle generation for all languages. However, word-level subtitle modes (e.g., "1 word", "2 words", "3 words", etc.) are only available for English because [Kokoro provides timestamp tokens only for English text](https://github.com/hexgrad/kokoro/blob/6d87f4ae7abc2d14dbc4b3ef2e5f19852e861ac2/kokoro/pipeline.py#L383). For non-English languages, Abogen uses a duration-based fallback that supports sentence-level and comma-based subtitle modes ("Line", "Sentence", "Sentence + Comma"). If you need word-level subtitles for other languages, please request that feature in the [Kokoro project](https://github.com/hexgrad/kokoro).
|
> Abogen supports subtitle generation for all languages. However, word-level subtitle modes (e.g., "1 word", "2 words", "3 words", etc.) are only available for English because [Kokoro provides timestamp tokens only for English text](https://github.com/hexgrad/kokoro/blob/6d87f4ae7abc2d14dbc4b3ef2e5f19852e861ac2/kokoro/pipeline.py#L383). For non-English languages, Abogen uses a duration-based fallback that supports sentence-level and comma-based subtitle modes ("Line", "Sentence", "Sentence + Comma"). If you need word-level subtitles for other languages, please request that feature in the [Kokoro project](https://github.com/hexgrad/kokoro).
|
||||||
|
|||||||
+50
-15
@@ -20,6 +20,7 @@ set MISAKI_LANG=en
|
|||||||
for /f "delims=: tokens=*" %%A in ('findstr /b ::: "%~f0"') do @echo(%%A
|
for /f "delims=: tokens=*" %%A in ('findstr /b ::: "%~f0"') do @echo(%%A
|
||||||
|
|
||||||
set CURRENT_DIR="%CD%"
|
set CURRENT_DIR="%CD%"
|
||||||
|
set "UV_CACHE_DIR=%~dp0.uv_cache"
|
||||||
set NAME=abogen
|
set NAME=abogen
|
||||||
set PROJECTFOLDER=abogen
|
set PROJECTFOLDER=abogen
|
||||||
set RUN=python_embedded\Scripts\abogen.exe
|
set RUN=python_embedded\Scripts\abogen.exe
|
||||||
@@ -29,6 +30,28 @@ set refrenv=%PROJECTFOLDER%\refrenv.bat
|
|||||||
set PYTHON_PATH=python_embedded\pythonw.exe
|
set PYTHON_PATH=python_embedded\pythonw.exe
|
||||||
set PYTHON_CONSOLE_PATH=python_embedded\python.exe
|
set PYTHON_CONSOLE_PATH=python_embedded\python.exe
|
||||||
|
|
||||||
|
:: ---------------------------------------------------------
|
||||||
|
:: Version Selection
|
||||||
|
:: ---------------------------------------------------------
|
||||||
|
echo.
|
||||||
|
echo Select installation version:
|
||||||
|
echo [1] Stable (PyPI) - Safer, recommended for most users.
|
||||||
|
echo [2] Dev (Local) - Install from current folder (may include commits after the latest release).
|
||||||
|
echo.
|
||||||
|
choice /C 12 /M "Your choice"
|
||||||
|
|
||||||
|
if errorlevel 2 (
|
||||||
|
set INSTALL_SOURCE=dev
|
||||||
|
echo.
|
||||||
|
echo Selected: Dev - Local Editable
|
||||||
|
) else (
|
||||||
|
set INSTALL_SOURCE=pypi
|
||||||
|
echo.
|
||||||
|
echo Selected: Stable - PyPI
|
||||||
|
)
|
||||||
|
echo.
|
||||||
|
:: ---------------------------------------------------------
|
||||||
|
|
||||||
:: Check for updates
|
:: Check for updates
|
||||||
echo Checking for updates...
|
echo Checking for updates...
|
||||||
set VERSION_FILE=%PROJECTFOLDER%\VERSION
|
set VERSION_FILE=%PROJECTFOLDER%\VERSION
|
||||||
@@ -197,18 +220,19 @@ if not "%~1"=="" (
|
|||||||
echo Open with: "%~1"
|
echo Open with: "%~1"
|
||||||
)
|
)
|
||||||
|
|
||||||
:: Update pip
|
:: Update pip and install uv
|
||||||
echo Updating pip...
|
echo Updating pip and installing uv...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install --upgrade pip --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m pip install --upgrade pip --no-warn-script-location
|
||||||
|
%PYTHON_CONSOLE_PATH% -m pip install uv --no-warn-script-location
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to update pip.
|
echo Failed to install uv.
|
||||||
pause
|
pause
|
||||||
exit /b
|
exit /b
|
||||||
)
|
)
|
||||||
|
|
||||||
:: Install docopt's fixed version
|
:: Install docopt's fixed version
|
||||||
echo Installing fixed version of docopt...
|
echo Installing fixed version of docopt...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install --force-reinstall https://github.com/denizsafak/abogen/raw/refs/heads/main/abogen/resources/docopt-0.6.2-py2.py3-none-any.whl --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system --force-reinstall https://github.com/denizsafak/abogen/raw/refs/heads/main/abogen/resources/docopt-0.6.2-py2.py3-none-any.whl
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install fixed version of docopt.
|
echo Failed to install fixed version of docopt.
|
||||||
pause
|
pause
|
||||||
@@ -217,7 +241,7 @@ if errorlevel 1 (
|
|||||||
|
|
||||||
:: Install progress's fixed version
|
:: Install progress's fixed version
|
||||||
echo Installing fixed version of progress...
|
echo Installing fixed version of progress...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install --force-reinstall https://github.com/denizsafak/abogen/raw/refs/heads/main/abogen/resources/progress-1.6-py3-none-any.whl --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system --force-reinstall https://github.com/denizsafak/abogen/raw/refs/heads/main/abogen/resources/progress-1.6-py3-none-any.whl
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install fixed version of progress.
|
echo Failed to install fixed version of progress.
|
||||||
pause
|
pause
|
||||||
@@ -226,7 +250,7 @@ if errorlevel 1 (
|
|||||||
|
|
||||||
:: Install setup requirements
|
:: Install setup requirements
|
||||||
echo Installing setup requirements...
|
echo Installing setup requirements...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install --upgrade setuptools setuptools-scm wheel sphinx hatchling editables --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system --upgrade setuptools setuptools-scm wheel sphinx hatchling editables
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install setup requirements.
|
echo Failed to install setup requirements.
|
||||||
pause
|
pause
|
||||||
@@ -235,18 +259,28 @@ if errorlevel 1 (
|
|||||||
|
|
||||||
:: Install gpustat
|
:: Install gpustat
|
||||||
echo Installing gpustat...
|
echo Installing gpustat...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install gpustat --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system gpustat
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install gpustat.
|
echo Failed to install gpustat.
|
||||||
pause
|
pause
|
||||||
exit /b
|
exit /b
|
||||||
)
|
)
|
||||||
|
|
||||||
:: Install project and dependencies from pyproject.toml
|
:: Install project based on user selection
|
||||||
|
if "%INSTALL_SOURCE%"=="pypi" (
|
||||||
|
echo Installing stable version from PyPI...
|
||||||
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system abogen
|
||||||
|
if errorlevel 1 (
|
||||||
|
echo Failed to install abogen from PyPI.
|
||||||
|
pause
|
||||||
|
exit /b
|
||||||
|
)
|
||||||
|
) else (
|
||||||
echo Checking and installing project dependencies...
|
echo Checking and installing project dependencies...
|
||||||
if exist %PYPROJECT_FILE% (
|
if exist %PYPROJECT_FILE% (
|
||||||
echo Installing project from pyproject.toml...
|
echo Installing project from pyproject.toml using uv...
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install -e . --no-warn-script-location
|
:: Using uv pip install --system --editable
|
||||||
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system --editable .
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install from pyproject.toml.
|
echo Failed to install from pyproject.toml.
|
||||||
pause
|
pause
|
||||||
@@ -256,11 +290,12 @@ if exist %PYPROJECT_FILE% (
|
|||||||
echo Warning: pyproject.toml not found in current directory.
|
echo Warning: pyproject.toml not found in current directory.
|
||||||
pause
|
pause
|
||||||
)
|
)
|
||||||
|
)
|
||||||
|
|
||||||
:: Install misaki again if MISAKI_LANG is not set to "en"
|
:: Install misaki again if MISAKI_LANG is not set to "en" via uv
|
||||||
if "%MISAKI_LANG%" NEQ "en" (
|
if "%MISAKI_LANG%" NEQ "en" (
|
||||||
echo Configuring language pack: %MISAKI_LANG%
|
echo Configuring language pack: %MISAKI_LANG%
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install misaki[%MISAKI_LANG%] --upgrade --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system misaki[%MISAKI_LANG%] --upgrade
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install misaki language pack.
|
echo Failed to install misaki language pack.
|
||||||
pause
|
pause
|
||||||
@@ -275,13 +310,13 @@ for /f %%i in ('%PYTHON_CONSOLE_PATH% -c "from abogen.is_nvidia import check; pr
|
|||||||
echo.
|
echo.
|
||||||
echo Checking CUDA availability...
|
echo Checking CUDA availability...
|
||||||
if /I "%IS_NVIDIA%"=="true" (
|
if /I "%IS_NVIDIA%"=="true" (
|
||||||
for /f %%i in ('%PYTHON_CONSOLE_PATH% -c "from torch.cuda import is_available; print(is_available())"') do set cuda_available=%%i
|
for /f %%i in ('%PYTHON_CONSOLE_PATH% %PROJECTFOLDER%\check_cuda.py') do set cuda_available=%%i
|
||||||
|
|
||||||
if "%cuda_available%"=="False" (
|
if "%cuda_available%"=="False" (
|
||||||
echo "Installing PyTorch with CUDA (12.8) support..."
|
echo "Installing PyTorch with CUDA (12.8) support..."
|
||||||
:: We need to use an older version of PyTorch (2.8.0) until this issue is fixed: https://github.com/pytorch/pytorch/issues/166628
|
:: We need to use an older version of PyTorch (2.8.0) until this issue is fixed: https://github.com/pytorch/pytorch/issues/166628
|
||||||
:: Solution mentioned by @mazenemam19 in #99:
|
:: Solution mentioned by @mazenemam19 in #99:
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install torch==2.8.0+cu128 torchvision==0.23.0+cu128 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128 --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system torch==2.8.0+cu128 torchvision==0.23.0+cu128 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
|
||||||
echo.
|
echo.
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install PyTorch.
|
echo Failed to install PyTorch.
|
||||||
@@ -307,7 +342,7 @@ if /I "%IS_NVIDIA%"=="true" (
|
|||||||
echo "Installing PyTorch with CUDA (12.8) support..."
|
echo "Installing PyTorch with CUDA (12.8) support..."
|
||||||
:: We need to use an older version of PyTorch (2.8.0) until this issue is fixed: https://github.com/pytorch/pytorch/issues/166628
|
:: We need to use an older version of PyTorch (2.8.0) until this issue is fixed: https://github.com/pytorch/pytorch/issues/166628
|
||||||
:: Solution mentioned by @mazenemam19 in #99:
|
:: Solution mentioned by @mazenemam19 in #99:
|
||||||
%PYTHON_CONSOLE_PATH% -m pip install torch==2.8.0+cu128 torchvision==0.23.0+cu128 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128 --no-warn-script-location
|
%PYTHON_CONSOLE_PATH% -m uv pip install --system torch==2.8.0+cu128 torchvision==0.23.0+cu128 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128
|
||||||
if errorlevel 1 (
|
if errorlevel 1 (
|
||||||
echo Failed to install PyTorch.
|
echo Failed to install PyTorch.
|
||||||
pause
|
pause
|
||||||
|
|||||||
@@ -1,44 +0,0 @@
|
|||||||
# Special thanks to @geo38 from Reddit, who provided this Dockerfile:
|
|
||||||
# https://www.reddit.com/r/selfhosted/comments/1k8x1yo/comment/mpe0bz8/
|
|
||||||
|
|
||||||
# Use a docker base image that runs a window manager that can be viewed
|
|
||||||
# outside the image with a web browser or VNC client.
|
|
||||||
# https://github.com/jlesage/docker-baseimage-gui
|
|
||||||
FROM jlesage/baseimage-gui:debian-12-v4
|
|
||||||
|
|
||||||
# Load stuff needed by abogen
|
|
||||||
RUN apt-get update \
|
|
||||||
&& apt-get install -y \
|
|
||||||
python3 \
|
|
||||||
python3-venv \
|
|
||||||
python3-pip \
|
|
||||||
python3-pyqt6 \
|
|
||||||
espeak-ng \
|
|
||||||
libxcb-cursor0 \
|
|
||||||
libgl1 \
|
|
||||||
&& apt-get clean \
|
|
||||||
&& rm -rf /var/lib/apt/lists/*
|
|
||||||
|
|
||||||
# The base image will run /startapp.sh on launch.
|
|
||||||
#
|
|
||||||
# The base image runs that script as user 'app' uid=1000. That user
|
|
||||||
# does not exist in the base image but is created at run time.
|
|
||||||
#
|
|
||||||
# We need to install abogen in python venv (requirement of newer python3).
|
|
||||||
#
|
|
||||||
# The python venv has to be writable by the 'app' user as abogen dynamically
|
|
||||||
# installs python packages, so create the venv as that user
|
|
||||||
#
|
|
||||||
# We intend to share the /shared directory with the host using a bind volume
|
|
||||||
# in order to access any source files and the created files.
|
|
||||||
|
|
||||||
RUN echo '#!/bin/bash\nsource /app/venv/bin/activate\nexec abogen' > /startapp.sh \
|
|
||||||
&& chmod 555 /startapp.sh \
|
|
||||||
&& mkdir /app /shared \
|
|
||||||
&& chown 1000:1000 /app /shared \
|
|
||||||
&& chmod 755 /app /shared
|
|
||||||
USER 1000:1000
|
|
||||||
RUN python3 -m venv /app/venv
|
|
||||||
RUN /bin/bash -c "source /app/venv/bin/activate && pip install abogen"
|
|
||||||
# Change back to user ROOT as the startup scripts inside base image needs it
|
|
||||||
USER root
|
|
||||||
+1
-1
@@ -1 +1 @@
|
|||||||
1.2.4
|
1.3.1
|
||||||
@@ -0,0 +1,8 @@
|
|||||||
|
"""Application layer for conversion flow unification.
|
||||||
|
|
||||||
|
This package contains the application-level orchestration logic
|
||||||
|
that bridges UI adapters (PyQt, WebUI) with domain functions.
|
||||||
|
|
||||||
|
The main entry point is ConversionService.run() which coordinates
|
||||||
|
planning, execution, and finalization of a conversion job.
|
||||||
|
"""
|
||||||
@@ -0,0 +1,62 @@
|
|||||||
|
"""Chapter selection helpers for the application layer.
|
||||||
|
|
||||||
|
Builds chapter payloads with smart defaults (preselection based on
|
||||||
|
supplement score) and character counts. Used by both WebUI and PyQt.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, List
|
||||||
|
|
||||||
|
from abogen.domain.chapter_classification import (
|
||||||
|
ensure_at_least_one_chapter_enabled,
|
||||||
|
should_preselect_chapter,
|
||||||
|
)
|
||||||
|
from abogen.domain.text_utils import calculate_text_length
|
||||||
|
|
||||||
|
|
||||||
|
def build_chapter_payload(
|
||||||
|
chapters: List[Any],
|
||||||
|
source_name: str = "",
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
"""Build a chapter payload with preselection and character counts.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
chapters: List of chapter-like objects with ``title`` and ``text`` attributes.
|
||||||
|
source_name: Fallback title for the placeholder chapter when *chapters* is empty.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
List of chapter dicts ready for ``PendingJob.chapters`` or ``ChapterChunkConfig``.
|
||||||
|
"""
|
||||||
|
total = len(chapters)
|
||||||
|
payload: List[Dict[str, Any]] = []
|
||||||
|
|
||||||
|
for index, chapter in enumerate(chapters):
|
||||||
|
title = getattr(chapter, "title", "") or ""
|
||||||
|
text = getattr(chapter, "text", "") or ""
|
||||||
|
enabled = should_preselect_chapter(title, text, index, total)
|
||||||
|
payload.append(
|
||||||
|
{
|
||||||
|
"id": f"{index:04d}",
|
||||||
|
"index": index,
|
||||||
|
"title": title,
|
||||||
|
"text": text,
|
||||||
|
"characters": calculate_text_length(text),
|
||||||
|
"enabled": enabled,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
if not payload:
|
||||||
|
payload.append(
|
||||||
|
{
|
||||||
|
"id": "0000",
|
||||||
|
"index": 0,
|
||||||
|
"title": source_name,
|
||||||
|
"text": "",
|
||||||
|
"characters": 0,
|
||||||
|
"enabled": True,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
ensure_at_least_one_chapter_enabled(payload)
|
||||||
|
return payload
|
||||||
@@ -0,0 +1,73 @@
|
|||||||
|
"""Application-layer cleanup — global resource disposal.
|
||||||
|
|
||||||
|
Handles:
|
||||||
|
- GPU/CUDA memory flush
|
||||||
|
- TTS engine disposal (PluginManager)
|
||||||
|
- UI-specific cleanup callbacks (registered by entry points)
|
||||||
|
|
||||||
|
Called by shutdown.py at process exit and by run_conversion() per-conversion.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import gc
|
||||||
|
from typing import Callable
|
||||||
|
|
||||||
|
_UI_CLEANUPS: list[Callable[[], None]] = []
|
||||||
|
|
||||||
|
|
||||||
|
def flush_cuda() -> None:
|
||||||
|
"""Run GC and release CUDA cache. Safe to call multiple times."""
|
||||||
|
gc.collect()
|
||||||
|
try:
|
||||||
|
import torch
|
||||||
|
if torch.cuda.is_available():
|
||||||
|
torch.cuda.empty_cache()
|
||||||
|
torch.cuda.ipc_collect()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
def dispose_engines() -> None:
|
||||||
|
"""Dispose all cached TTS engines via PluginManager."""
|
||||||
|
try:
|
||||||
|
from abogen.tts_plugin.plugin_manager import get_plugin_manager
|
||||||
|
get_plugin_manager().dispose_all()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
def _clear_global_voice_cache() -> None:
|
||||||
|
"""Reset the global voice download cache state."""
|
||||||
|
try:
|
||||||
|
from abogen.voice_cache import clear_voice_cache
|
||||||
|
clear_voice_cache()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
def register_ui_cleanup(fn: Callable[[], None]) -> None:
|
||||||
|
"""Register a UI-specific cleanup callback (e.g. preview threads, temp files)."""
|
||||||
|
_UI_CLEANUPS.append(fn)
|
||||||
|
|
||||||
|
|
||||||
|
def cleanup() -> None:
|
||||||
|
"""Run all application-level cleanups. Idempotent."""
|
||||||
|
dispose_engines()
|
||||||
|
flush_cuda()
|
||||||
|
_clear_global_voice_cache()
|
||||||
|
|
||||||
|
for fn in _UI_CLEANUPS:
|
||||||
|
try:
|
||||||
|
fn()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
_UI_CLEANUPS.clear()
|
||||||
|
|
||||||
|
|
||||||
|
__all__ = [
|
||||||
|
"flush_cuda",
|
||||||
|
"dispose_engines",
|
||||||
|
"register_ui_cleanup",
|
||||||
|
"cleanup",
|
||||||
|
]
|
||||||
@@ -0,0 +1,95 @@
|
|||||||
|
"""Feature config objects for ConversionRequest.
|
||||||
|
|
||||||
|
Each config object groups parameters for a specific feature.
|
||||||
|
If the object is None, the feature is disabled.
|
||||||
|
|
||||||
|
This keeps ConversionRequest clean: no boolean flags for feature toggles,
|
||||||
|
no scattered parameters across unrelated fields.
|
||||||
|
|
||||||
|
Domain config types (PronunciationConfig, SubtitleConfig) live in
|
||||||
|
domain/config_types.py — domain defines the contract, app fills them.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional
|
||||||
|
|
||||||
|
from abogen.domain.config_types import CoverConfig, PronunciationConfig, SubtitleConfig
|
||||||
|
from abogen.domain.enums import OutputFormat, SaveMode
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class WordSubstitutionConfig:
|
||||||
|
"""Word substitution settings.
|
||||||
|
|
||||||
|
When present on ConversionRequest, word substitution is applied
|
||||||
|
to the source text before chapter parsing.
|
||||||
|
"""
|
||||||
|
substitutions_list: str = ""
|
||||||
|
case_sensitive: bool = False
|
||||||
|
replace_caps: bool = False
|
||||||
|
replace_numerals: bool = False
|
||||||
|
fix_punctuation: bool = False
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class SubtitleInputConfig:
|
||||||
|
"""Subtitle file input settings.
|
||||||
|
|
||||||
|
When present on ConversionRequest, the source is treated as a
|
||||||
|
subtitle file (.srt/.ass/.vtt) or timestamp text, and the
|
||||||
|
subtitle-to-audio pipeline is used instead of normal text conversion.
|
||||||
|
"""
|
||||||
|
is_timestamp_text: bool = False
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class Epub3ExportConfig:
|
||||||
|
"""EPUB3 export settings.
|
||||||
|
|
||||||
|
When present on ConversionRequest, an EPUB3 package with
|
||||||
|
synchronized audio narration is generated after conversion.
|
||||||
|
"""
|
||||||
|
book_id: str = ""
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class ChapterChunkConfig:
|
||||||
|
"""Chapter and chunk configuration.
|
||||||
|
|
||||||
|
Groups chapter overrides, chunk data, and speaker settings
|
||||||
|
used by the planner to build segments.
|
||||||
|
"""
|
||||||
|
chapter_overrides: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
chunks: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
chunk_level: str = "paragraph"
|
||||||
|
speaker_mode: str = "single"
|
||||||
|
speakers: Dict[str, Any] = field(default_factory=dict)
|
||||||
|
|
||||||
|
def __post_init__(self) -> None:
|
||||||
|
_VALID_CHUNK_LEVELS = ("paragraph", "sentence")
|
||||||
|
_VALID_SPEAKER_MODES = ("single", "multi")
|
||||||
|
if self.chunk_level not in _VALID_CHUNK_LEVELS:
|
||||||
|
raise ValueError(
|
||||||
|
f"chunk_level must be one of {_VALID_CHUNK_LEVELS}, got {self.chunk_level!r}"
|
||||||
|
)
|
||||||
|
if self.speaker_mode not in _VALID_SPEAKER_MODES:
|
||||||
|
raise ValueError(
|
||||||
|
f"speaker_mode must be one of {_VALID_SPEAKER_MODES}, got {self.speaker_mode!r}"
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class SaveConfig:
|
||||||
|
"""Save/output settings.
|
||||||
|
|
||||||
|
Groups save mode, output folder, chapter splitting, and merge options.
|
||||||
|
"""
|
||||||
|
mode: SaveMode = SaveMode.SAVE_NEXT_TO_INPUT
|
||||||
|
output_folder: Optional[Path] = None
|
||||||
|
save_chapters_separately: bool = False
|
||||||
|
merge_chapters_at_end: bool = True
|
||||||
|
separate_chapters_format: OutputFormat = OutputFormat.WAV
|
||||||
|
save_as_project: bool = False
|
||||||
@@ -0,0 +1,660 @@
|
|||||||
|
"""Unified conversion executor.
|
||||||
|
|
||||||
|
Takes a ConversionPlan and ports, executes the TTS conversion,
|
||||||
|
and returns a ConversionResult. No UI imports allowed.
|
||||||
|
|
||||||
|
This is Stage 6 of the conversion flow unification plan.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
import time
|
||||||
|
from contextlib import ExitStack
|
||||||
|
from typing import Any, Callable, Dict, List, Optional, Set, Tuple
|
||||||
|
|
||||||
|
from abogen.application.conversion_models import (
|
||||||
|
ConversionPlan,
|
||||||
|
)
|
||||||
|
from abogen.application.conversion_ports import (
|
||||||
|
AudioSink,
|
||||||
|
ConversionEvents,
|
||||||
|
PipelineProvider,
|
||||||
|
SubtitleWriter,
|
||||||
|
VoiceResolver,
|
||||||
|
)
|
||||||
|
from abogen.application.conversion_result import ConversionResult
|
||||||
|
from abogen.domain.audio_sink import open_audio_sink
|
||||||
|
from abogen.domain.conversion_engine import (
|
||||||
|
SegmentStats,
|
||||||
|
SynthParams,
|
||||||
|
process_and_write_subtitles,
|
||||||
|
synthesize_text,
|
||||||
|
)
|
||||||
|
from abogen.domain.enums import OutputFormat, SubtitleMode
|
||||||
|
from abogen.domain.normalization import TTSContext
|
||||||
|
from abogen.domain.chapter_titles import (
|
||||||
|
apply_chapter_text_transforms,
|
||||||
|
headings_equivalent as _headings_equivalent,
|
||||||
|
)
|
||||||
|
from abogen.domain.output_paths import sanitize_filename_for_chapter
|
||||||
|
from abogen.infrastructure.subtitle_writer import make_subtitle_writer
|
||||||
|
|
||||||
|
|
||||||
|
# ─── MarkerCollector ───
|
||||||
|
|
||||||
|
|
||||||
|
class MarkerCollector:
|
||||||
|
"""Observes execution events and accumulates chapter/chunk markers.
|
||||||
|
|
||||||
|
Separates marker collection from synthesis logic.
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(self) -> None:
|
||||||
|
self._chapter_markers: List[Dict[str, Any]] = []
|
||||||
|
self._chunk_markers: List[Dict[str, Any]] = []
|
||||||
|
self._current_chapter_voices: Set[Tuple[str, str]] = set()
|
||||||
|
self._current_chapter_index: int = 0
|
||||||
|
self._current_chapter_title: str = ""
|
||||||
|
self._current_chapter_start: float = 0.0
|
||||||
|
|
||||||
|
def on_chapter_start(
|
||||||
|
self, index: int, title: str, start_time: float
|
||||||
|
) -> None:
|
||||||
|
"""Record chapter start."""
|
||||||
|
self._current_chapter_index = index
|
||||||
|
self._current_chapter_title = title
|
||||||
|
self._current_chapter_start = start_time
|
||||||
|
self._current_chapter_voices.clear()
|
||||||
|
|
||||||
|
def on_segment(
|
||||||
|
self,
|
||||||
|
provider: str,
|
||||||
|
voice: Any,
|
||||||
|
voice_spec: str,
|
||||||
|
speaker_id: str = "narrator",
|
||||||
|
) -> None:
|
||||||
|
"""Record a voice used in this chapter (for multi-speaker tracking)."""
|
||||||
|
self._current_chapter_voices.add((provider, voice_spec))
|
||||||
|
|
||||||
|
def on_chunk(
|
||||||
|
self,
|
||||||
|
chunk_id: str,
|
||||||
|
chapter_index: int,
|
||||||
|
chunk_index: int,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
speaker_id: str,
|
||||||
|
provider: str,
|
||||||
|
voice_spec: str,
|
||||||
|
level: str,
|
||||||
|
characters: int,
|
||||||
|
) -> None:
|
||||||
|
"""Record a chunk marker."""
|
||||||
|
self._chunk_markers.append({
|
||||||
|
"id": chunk_id,
|
||||||
|
"chapter_index": chapter_index,
|
||||||
|
"chunk_index": chunk_index,
|
||||||
|
"start": start,
|
||||||
|
"end": end,
|
||||||
|
"speaker_id": speaker_id,
|
||||||
|
"voice": {"provider": provider, "voice": voice_spec},
|
||||||
|
"level": level,
|
||||||
|
"characters": characters,
|
||||||
|
})
|
||||||
|
|
||||||
|
def on_chapter_end(self, end_time: float) -> None:
|
||||||
|
"""Record chapter end and build chapter marker."""
|
||||||
|
voices = [
|
||||||
|
{"provider": p, "voice": v}
|
||||||
|
for p, v in sorted(self._current_chapter_voices)
|
||||||
|
]
|
||||||
|
self._chapter_markers.append({
|
||||||
|
"chapter_index": self._current_chapter_index,
|
||||||
|
"index": self._current_chapter_index + 1,
|
||||||
|
"title": self._current_chapter_title,
|
||||||
|
"start": self._current_chapter_start,
|
||||||
|
"end": end_time,
|
||||||
|
"voices": voices,
|
||||||
|
})
|
||||||
|
|
||||||
|
def on_outro(
|
||||||
|
self,
|
||||||
|
start_time: float,
|
||||||
|
end_time: float,
|
||||||
|
provider: str,
|
||||||
|
voice_spec: str,
|
||||||
|
) -> None:
|
||||||
|
"""Record outro chapter marker."""
|
||||||
|
self._chapter_markers.append({
|
||||||
|
"chapter_index": len(self._chapter_markers),
|
||||||
|
"index": len(self._chapter_markers) + 1,
|
||||||
|
"title": "Outro",
|
||||||
|
"start": start_time,
|
||||||
|
"end": end_time,
|
||||||
|
"voices": [{"provider": provider, "voice": voice_spec}],
|
||||||
|
})
|
||||||
|
|
||||||
|
@property
|
||||||
|
def chapter_markers(self) -> List[Dict[str, Any]]:
|
||||||
|
return self._chapter_markers
|
||||||
|
|
||||||
|
@property
|
||||||
|
def chunk_markers(self) -> List[Dict[str, Any]]:
|
||||||
|
return self._chunk_markers
|
||||||
|
|
||||||
|
|
||||||
|
def execute_conversion(
|
||||||
|
plan: ConversionPlan,
|
||||||
|
events: ConversionEvents,
|
||||||
|
pipeline_provider: PipelineProvider,
|
||||||
|
voice_resolver: VoiceResolver,
|
||||||
|
tts_context: TTSContext,
|
||||||
|
*,
|
||||||
|
check_cancelled: Optional[Callable[[], None]] = None,
|
||||||
|
) -> ConversionResult:
|
||||||
|
"""Execute a conversion plan and return the result.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
plan: The conversion plan from build_conversion_plan()
|
||||||
|
events: UI-specific callbacks (log, progress, check_cancelled)
|
||||||
|
pipeline_provider: Provides TTS backends
|
||||||
|
voice_resolver: Resolves voice specs into loaded voices
|
||||||
|
tts_context: Normalization context for text processing
|
||||||
|
check_cancelled: Optional cancellation checker (overrides events.check_cancelled)
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
ConversionResult with paths and markers
|
||||||
|
|
||||||
|
Raises:
|
||||||
|
ConversionCancelled: If conversion is cancelled
|
||||||
|
"""
|
||||||
|
request = plan.request
|
||||||
|
result = ConversionResult(metadata=plan.metadata)
|
||||||
|
collector = MarkerCollector()
|
||||||
|
|
||||||
|
logging.info(
|
||||||
|
"[executor] Starting: chapters=%d intro=%s outro=%s merge=%s",
|
||||||
|
len(plan.chapters),
|
||||||
|
bool(plan.intro and plan.intro.enabled),
|
||||||
|
bool(plan.outro and plan.outro.enabled),
|
||||||
|
request.save.merge_chapters_at_end,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Determine cancellation checker
|
||||||
|
if check_cancelled is None:
|
||||||
|
check_cancelled = lambda: events.check_cancelled()
|
||||||
|
|
||||||
|
# Stats for progress tracking
|
||||||
|
total_characters = sum(
|
||||||
|
len(ch.body_text) for ch in plan.chapters
|
||||||
|
)
|
||||||
|
if plan.intro and plan.intro.enabled:
|
||||||
|
total_characters += len(plan.intro.text)
|
||||||
|
if plan.outro and plan.outro.enabled:
|
||||||
|
total_characters += len(plan.outro.text)
|
||||||
|
|
||||||
|
stats = SegmentStats(
|
||||||
|
processed_chars=0,
|
||||||
|
current_time=0.0,
|
||||||
|
etr_start_time=time.time(),
|
||||||
|
total_characters=total_characters,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Compute subtitle flag once (used in every synthesize_text call)
|
||||||
|
use_spacy = request.subtitle.mode not in (SubtitleMode.DISABLED, SubtitleMode.LINE)
|
||||||
|
|
||||||
|
# Output paths
|
||||||
|
output_layout = plan.output_layout
|
||||||
|
if not output_layout:
|
||||||
|
raise ValueError("ConversionPlan must have an output_layout")
|
||||||
|
|
||||||
|
# Determine if merged output is needed
|
||||||
|
merge_chapters = request.save.merge_chapters_at_end or not request.save.save_chapters_separately
|
||||||
|
if request.output_format == OutputFormat.M4B:
|
||||||
|
merge_chapters = True
|
||||||
|
|
||||||
|
# Resolve voices
|
||||||
|
base_voice_spec = request.voice or "M1"
|
||||||
|
logging.info("[executor] Resolving base voice: spec=%s", base_voice_spec)
|
||||||
|
base_provider, base_voice_choice, base_speed, base_steps = _resolve_voice(
|
||||||
|
voice_resolver, base_voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
logging.info("[executor] Base voice resolved: provider=%s voice=%s speed=%.2f", base_provider, base_voice_choice, base_speed)
|
||||||
|
|
||||||
|
# Use ExitStack for resource management
|
||||||
|
with ExitStack() as stack:
|
||||||
|
# Open merged audio sink
|
||||||
|
audio_sink: Optional[AudioSink] = None
|
||||||
|
audio_path = None
|
||||||
|
if merge_chapters:
|
||||||
|
audio_path = output_layout.audio_dir / f"{_base_name(request)}{request.output_format.dot_ext}"
|
||||||
|
meta = plan.metadata if plan.metadata else None
|
||||||
|
audio_sink = stack.enter_context(
|
||||||
|
open_audio_sink(
|
||||||
|
audio_path,
|
||||||
|
request.output_format,
|
||||||
|
metadata=meta,
|
||||||
|
cancel_check=check_cancelled,
|
||||||
|
)
|
||||||
|
)
|
||||||
|
result.audio_path = audio_path
|
||||||
|
|
||||||
|
# Open subtitle writer if needed
|
||||||
|
subtitle_writer: Optional[SubtitleWriter] = None
|
||||||
|
if request.subtitle.mode != SubtitleMode.DISABLED and audio_sink:
|
||||||
|
subtitle_writer = make_subtitle_writer(
|
||||||
|
audio_path,
|
||||||
|
request.subtitle,
|
||||||
|
)
|
||||||
|
if subtitle_writer:
|
||||||
|
subtitle_writer.open()
|
||||||
|
stack.callback(subtitle_writer.close)
|
||||||
|
result.subtitle_paths.append(subtitle_writer.path)
|
||||||
|
|
||||||
|
effective_subtitle_mode = request.subtitle.mode if subtitle_writer else SubtitleMode.DISABLED
|
||||||
|
|
||||||
|
synth = SynthParams(
|
||||||
|
tts_context=tts_context,
|
||||||
|
stats=stats,
|
||||||
|
check_cancel=check_cancelled,
|
||||||
|
on_progress=lambda pct, etr: events.progress(pct, etr),
|
||||||
|
audio_sink=audio_sink,
|
||||||
|
subtitle_mode=effective_subtitle_mode,
|
||||||
|
max_subtitle_words=request.subtitle.max_words,
|
||||||
|
language=request.language,
|
||||||
|
use_spacy_segmentation=use_spacy,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Chapter directory
|
||||||
|
chapter_dir = None
|
||||||
|
if request.save.save_chapters_separately and len(plan.chapters) > 1:
|
||||||
|
chapter_dir = output_layout.audio_dir / "chapters"
|
||||||
|
chapter_dir.mkdir(parents=True, exist_ok=True)
|
||||||
|
|
||||||
|
# Process intro
|
||||||
|
intro_emitted = False
|
||||||
|
if plan.intro and plan.intro.enabled and merge_chapters:
|
||||||
|
events.log(f"Title intro: {plan.intro.text[:80]}")
|
||||||
|
intro_provider, intro_voice, intro_speed, intro_steps = _resolve_voice(
|
||||||
|
voice_resolver, plan.intro.voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
intro_backend = pipeline_provider.get(intro_provider, request.language, request.use_gpu)
|
||||||
|
synthesize_text(
|
||||||
|
text=plan.intro.text,
|
||||||
|
params=synth,
|
||||||
|
backend=intro_backend,
|
||||||
|
voice=intro_voice,
|
||||||
|
speed=intro_speed or request.speed,
|
||||||
|
total_steps=intro_steps,
|
||||||
|
chapter_sink=None,
|
||||||
|
preview_callback=lambda text: events.log(f" {text[:80]}"),
|
||||||
|
)
|
||||||
|
intro_emitted = True
|
||||||
|
events.log("Intro synthesized.")
|
||||||
|
|
||||||
|
# Chapter loop
|
||||||
|
for chapter_idx, chapter in enumerate(plan.chapters, 1):
|
||||||
|
check_cancelled()
|
||||||
|
|
||||||
|
chapter_display = f"Chapter {chapter_idx}/{len(plan.chapters)}: {chapter.title}"
|
||||||
|
events.log(f"Processing {chapter_display}")
|
||||||
|
logging.info("[executor] Chapter %d/%d: %s", chapter_idx, len(plan.chapters), chapter.title)
|
||||||
|
|
||||||
|
# Resolve chapter voice
|
||||||
|
chapter_provider, chapter_voice, chapter_speed, chapter_steps = _resolve_voice(
|
||||||
|
voice_resolver, chapter.voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
logging.info("[executor] Chapter %d voice: provider=%s voice=%s speed=%.2f", chapter_idx, chapter_provider, chapter_voice, chapter_speed)
|
||||||
|
chapter_backend = pipeline_provider.get(chapter_provider, request.language, request.use_gpu)
|
||||||
|
|
||||||
|
# Record chapter start for markers
|
||||||
|
collector.on_chapter_start(chapter_idx - 1, chapter.title, stats.current_time)
|
||||||
|
|
||||||
|
# Per-chapter sink
|
||||||
|
chapter_sink: Optional[AudioSink] = None
|
||||||
|
chapter_path = None
|
||||||
|
if chapter_dir:
|
||||||
|
chapter_filename = sanitize_filename_for_chapter(chapter.title, chapter_idx)
|
||||||
|
chapter_path = chapter_dir / f"{chapter_filename}.{request.save.separate_chapters_format}"
|
||||||
|
chapter_sink = stack.enter_context(
|
||||||
|
open_audio_sink(
|
||||||
|
chapter_path,
|
||||||
|
request.save.separate_chapters_format,
|
||||||
|
cancel_check=check_cancelled,
|
||||||
|
)
|
||||||
|
)
|
||||||
|
result.chapter_paths.append(chapter_path)
|
||||||
|
|
||||||
|
# Per-chapter subtitle writer
|
||||||
|
chapter_subtitle_writer: Optional[SubtitleWriter] = None
|
||||||
|
if chapter_dir and request.subtitle.mode != SubtitleMode.DISABLED and chapter_sink:
|
||||||
|
from abogen.infrastructure.subtitle_writer import resolve_subtitle_format
|
||||||
|
|
||||||
|
chapter_filename = sanitize_filename_for_chapter(chapter.title, chapter_idx)
|
||||||
|
subtitle_ext, _ = resolve_subtitle_format(
|
||||||
|
request.subtitle
|
||||||
|
)
|
||||||
|
chapter_subtitle_path = chapter_dir / f"{chapter_filename}.{subtitle_ext}"
|
||||||
|
chapter_subtitle_writer = make_subtitle_writer(
|
||||||
|
chapter_subtitle_path,
|
||||||
|
request.subtitle,
|
||||||
|
)
|
||||||
|
if chapter_subtitle_writer:
|
||||||
|
chapter_subtitle_writer.open()
|
||||||
|
result.subtitle_paths.append(chapter_subtitle_writer.path)
|
||||||
|
|
||||||
|
# Intro delay before first chapter
|
||||||
|
if not intro_emitted and plan.intro and plan.intro.enabled:
|
||||||
|
# Intro will be emitted with first chapter
|
||||||
|
intro_provider, intro_voice, intro_speed, intro_steps = _resolve_voice(
|
||||||
|
voice_resolver, plan.intro.voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
intro_backend = pipeline_provider.get(intro_provider, request.language, request.use_gpu)
|
||||||
|
synthesize_text(
|
||||||
|
text=plan.intro.text,
|
||||||
|
params=synth,
|
||||||
|
backend=intro_backend,
|
||||||
|
voice=intro_voice,
|
||||||
|
speed=intro_speed or request.speed,
|
||||||
|
total_steps=intro_steps,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
preview_callback=lambda text: events.log(f" Intro: {text[:80]}"),
|
||||||
|
)
|
||||||
|
intro_emitted = True
|
||||||
|
if request.chapter_intro_delay > 0:
|
||||||
|
_append_silence(
|
||||||
|
request.chapter_intro_delay,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
audio_sink=audio_sink,
|
||||||
|
stats=stats,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Process heading
|
||||||
|
heading_text = ""
|
||||||
|
if chapter.title:
|
||||||
|
heading_text = _format_heading(chapter.title, chapter_idx, request)
|
||||||
|
if heading_text:
|
||||||
|
synthesize_text(
|
||||||
|
text=heading_text,
|
||||||
|
params=synth,
|
||||||
|
backend=chapter_backend,
|
||||||
|
voice=chapter_voice,
|
||||||
|
speed=chapter_speed or request.speed,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
preview_callback=lambda text: events.log(f" Title: {text[:80]}"),
|
||||||
|
)
|
||||||
|
if request.chapter_intro_delay > 0:
|
||||||
|
_append_silence(
|
||||||
|
request.chapter_intro_delay,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
audio_sink=audio_sink,
|
||||||
|
stats=stats,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Heading dedup: check if first line of body matches heading
|
||||||
|
pending_heading_strip = False
|
||||||
|
if heading_text and chapter.body_text:
|
||||||
|
first_line = next(
|
||||||
|
(line.strip() for line in chapter.body_text.splitlines() if line.strip()),
|
||||||
|
"",
|
||||||
|
)
|
||||||
|
if first_line and _headings_equivalent(first_line, heading_text):
|
||||||
|
pending_heading_strip = True
|
||||||
|
|
||||||
|
# Process body segments
|
||||||
|
for seg_idx, segment in enumerate(chapter.segments):
|
||||||
|
check_cancelled()
|
||||||
|
|
||||||
|
# Apply heading dedup to first segment (consume-once)
|
||||||
|
seg_text = segment.text
|
||||||
|
if pending_heading_strip and seg_text.strip():
|
||||||
|
seg_text, heading_removed, _ = apply_chapter_text_transforms(
|
||||||
|
seg_text,
|
||||||
|
heading_text=heading_text,
|
||||||
|
raw_title=chapter.title,
|
||||||
|
strip_heading=True,
|
||||||
|
normalize_caps=False,
|
||||||
|
)
|
||||||
|
if heading_removed:
|
||||||
|
pending_heading_strip = False
|
||||||
|
if not seg_text.strip():
|
||||||
|
continue
|
||||||
|
|
||||||
|
# Resolve segment voice (may differ from chapter voice)
|
||||||
|
if segment.voice_spec != chapter.voice_spec:
|
||||||
|
seg_provider, seg_voice, seg_speed, seg_steps = _resolve_voice(
|
||||||
|
voice_resolver, segment.voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
seg_backend = pipeline_provider.get(seg_provider, request.language, request.use_gpu)
|
||||||
|
else:
|
||||||
|
seg_provider = chapter_provider
|
||||||
|
seg_voice = chapter_voice
|
||||||
|
seg_speed = chapter_speed
|
||||||
|
seg_steps = chapter_steps
|
||||||
|
seg_backend = chapter_backend
|
||||||
|
|
||||||
|
# Track voice for chapter marker
|
||||||
|
collector.on_segment(seg_provider, seg_voice, segment.voice_spec)
|
||||||
|
|
||||||
|
# spaCy pre-TTS segmentation
|
||||||
|
from abogen.domain.conversion_pipeline import spacy_pre_tts_segmentation
|
||||||
|
|
||||||
|
is_subtitle_input = bool(
|
||||||
|
request.subtitle_input
|
||||||
|
)
|
||||||
|
spacy_segments, active_split = spacy_pre_tts_segmentation(
|
||||||
|
seg_text,
|
||||||
|
request.language,
|
||||||
|
request.subtitle.mode,
|
||||||
|
is_subtitle_input=is_subtitle_input,
|
||||||
|
use_spacy_segmentation=use_spacy,
|
||||||
|
log_callback=lambda msg: events.log(msg),
|
||||||
|
)
|
||||||
|
|
||||||
|
seg_start_time = stats.current_time
|
||||||
|
accumulated_tokens: List[Dict[str, Any]] = []
|
||||||
|
for spacy_seg in spacy_segments:
|
||||||
|
if not spacy_seg.strip():
|
||||||
|
continue
|
||||||
|
_, seg_tokens = synthesize_text(
|
||||||
|
text=spacy_seg,
|
||||||
|
params=synth,
|
||||||
|
backend=seg_backend,
|
||||||
|
voice=seg_voice,
|
||||||
|
speed=seg_speed or request.speed,
|
||||||
|
total_steps=seg_steps,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
preview_callback=lambda text: events.log(f" {text[:80]}"),
|
||||||
|
split_pattern_override=active_split,
|
||||||
|
)
|
||||||
|
accumulated_tokens.extend(seg_tokens)
|
||||||
|
|
||||||
|
# Process subtitles
|
||||||
|
if audio_sink and accumulated_tokens:
|
||||||
|
if subtitle_writer:
|
||||||
|
process_and_write_subtitles(
|
||||||
|
accumulated_tokens,
|
||||||
|
subtitle_writer,
|
||||||
|
subtitle=request.subtitle,
|
||||||
|
language=request.language,
|
||||||
|
use_spacy_segmentation=use_spacy,
|
||||||
|
fallback_end_time=stats.current_time,
|
||||||
|
)
|
||||||
|
if chapter_subtitle_writer:
|
||||||
|
process_and_write_subtitles(
|
||||||
|
accumulated_tokens,
|
||||||
|
chapter_subtitle_writer,
|
||||||
|
subtitle=request.subtitle,
|
||||||
|
language=request.language,
|
||||||
|
use_spacy_segmentation=use_spacy,
|
||||||
|
fallback_end_time=stats.current_time,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Record chunk marker
|
||||||
|
if segment.source in ("chunk", "voice_marker"):
|
||||||
|
collector.on_chunk(
|
||||||
|
chunk_id=segment.chunk_id or "",
|
||||||
|
chapter_index=chapter_idx - 1,
|
||||||
|
chunk_index=segment.chunk_index or seg_idx,
|
||||||
|
start=seg_start_time,
|
||||||
|
end=stats.current_time,
|
||||||
|
speaker_id=segment.speaker_id or "narrator",
|
||||||
|
provider=seg_provider,
|
||||||
|
voice_spec=segment.voice_spec,
|
||||||
|
level=segment.level or (request.chapter_chunk.chunk_level if request.chapter_chunk else "paragraph"),
|
||||||
|
characters=len(segment.text),
|
||||||
|
)
|
||||||
|
|
||||||
|
# Silence between chapters
|
||||||
|
if chapter_idx < len(plan.chapters) and request.silence_between_chapters > 0:
|
||||||
|
_append_silence(
|
||||||
|
request.silence_between_chapters,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
audio_sink=audio_sink,
|
||||||
|
stats=stats,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Close chapter sink
|
||||||
|
if chapter_sink:
|
||||||
|
chapter_sink.close()
|
||||||
|
|
||||||
|
# Close chapter subtitle writer
|
||||||
|
if chapter_subtitle_writer:
|
||||||
|
chapter_subtitle_writer.close()
|
||||||
|
|
||||||
|
# Record chapter end for markers
|
||||||
|
collector.on_chapter_end(stats.current_time)
|
||||||
|
logging.info("[executor] Chapter %d/%d done: time=%.1fs", chapter_idx, len(plan.chapters), stats.current_time)
|
||||||
|
|
||||||
|
logging.info("[executor] All chapters done: total=%.1fs", stats.current_time)
|
||||||
|
|
||||||
|
# Process outro
|
||||||
|
if plan.outro and plan.outro.enabled and merge_chapters:
|
||||||
|
events.log(f"Closing outro: {plan.outro.text[:80]}")
|
||||||
|
outro_provider, outro_voice, outro_speed, outro_steps = _resolve_voice(
|
||||||
|
voice_resolver, plan.outro.voice_spec, request,
|
||||||
|
log_callback=lambda msg: events.log(msg, level="warning"),
|
||||||
|
)
|
||||||
|
outro_backend = pipeline_provider.get(outro_provider, request.language, request.use_gpu)
|
||||||
|
|
||||||
|
# Silence before outro
|
||||||
|
if request.silence_between_chapters > 0:
|
||||||
|
_append_silence(
|
||||||
|
request.silence_between_chapters,
|
||||||
|
chapter_sink=None,
|
||||||
|
audio_sink=audio_sink,
|
||||||
|
stats=stats,
|
||||||
|
)
|
||||||
|
|
||||||
|
outro_start = stats.current_time
|
||||||
|
synthesize_text(
|
||||||
|
text=plan.outro.text,
|
||||||
|
params=synth,
|
||||||
|
backend=outro_backend,
|
||||||
|
voice=outro_voice,
|
||||||
|
speed=outro_speed or request.speed,
|
||||||
|
total_steps=outro_steps,
|
||||||
|
chapter_sink=None,
|
||||||
|
preview_callback=lambda text: events.log(f" {text[:80]}"),
|
||||||
|
)
|
||||||
|
# Record outro marker
|
||||||
|
collector.on_outro(outro_start, stats.current_time, outro_provider, plan.outro.voice_spec)
|
||||||
|
events.log("Outro synthesized.")
|
||||||
|
|
||||||
|
# Set result metadata
|
||||||
|
result.chapter_markers = collector.chapter_markers
|
||||||
|
result.chunk_markers = collector.chunk_markers
|
||||||
|
result.total_chapters = len(plan.chapters)
|
||||||
|
result.total_segments = sum(len(ch.segments) for ch in plan.chapters)
|
||||||
|
result.total_characters = total_characters
|
||||||
|
|
||||||
|
if output_layout.project_root:
|
||||||
|
result.project_root = output_layout.project_root
|
||||||
|
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
# ─── Helpers ────────────────────────────────────────────────────────
|
||||||
|
|
||||||
|
|
||||||
|
def _resolve_voice(
|
||||||
|
resolver: VoiceResolver,
|
||||||
|
voice_spec: str,
|
||||||
|
request: Any,
|
||||||
|
*,
|
||||||
|
log_callback: Optional[Callable[[str], None]] = None,
|
||||||
|
) -> Tuple[str, Any, Optional[float], Optional[int]]:
|
||||||
|
"""Resolve a voice spec and return (provider, voice, speed, steps)."""
|
||||||
|
try:
|
||||||
|
resolved = resolver.resolve(voice_spec)
|
||||||
|
return (
|
||||||
|
resolved.provider,
|
||||||
|
resolved.voice,
|
||||||
|
resolved.speed,
|
||||||
|
resolved.supertonic_steps,
|
||||||
|
)
|
||||||
|
except Exception as exc:
|
||||||
|
# Fallback to base voice
|
||||||
|
base_spec = request.voice or "M1"
|
||||||
|
if log_callback:
|
||||||
|
log_callback(
|
||||||
|
f"Voice '{voice_spec}' failed to resolve: {exc}. "
|
||||||
|
f"Falling back to '{base_spec}'."
|
||||||
|
)
|
||||||
|
try:
|
||||||
|
resolved = resolver.resolve(base_spec)
|
||||||
|
except Exception as fallback_exc:
|
||||||
|
raise RuntimeError(
|
||||||
|
f"Both voice '{voice_spec}' and fallback '{base_spec}' failed to resolve. "
|
||||||
|
f"Primary error: {exc}; Fallback error: {fallback_exc}"
|
||||||
|
) from fallback_exc
|
||||||
|
return (
|
||||||
|
resolved.provider,
|
||||||
|
resolved.voice,
|
||||||
|
resolved.speed,
|
||||||
|
resolved.supertonic_steps,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _base_name(request: Any) -> str:
|
||||||
|
"""Get base name for output file."""
|
||||||
|
from abogen.domain.output_paths import sanitize_output_stem
|
||||||
|
|
||||||
|
if request.original_filename:
|
||||||
|
return sanitize_output_stem(request.original_filename)
|
||||||
|
return "output"
|
||||||
|
|
||||||
|
|
||||||
|
def _format_heading(title: str, index: int, request: Any) -> str:
|
||||||
|
"""Format chapter heading for TTS."""
|
||||||
|
from abogen.domain.chapter_titles import format_spoken_chapter_title
|
||||||
|
|
||||||
|
if request.auto_prefix_chapter_titles:
|
||||||
|
return format_spoken_chapter_title(title, index, apply_prefix=True)
|
||||||
|
return title
|
||||||
|
|
||||||
|
|
||||||
|
def _append_silence(
|
||||||
|
duration: float,
|
||||||
|
*,
|
||||||
|
chapter_sink: Optional[AudioSink],
|
||||||
|
audio_sink: Optional[AudioSink],
|
||||||
|
stats: SegmentStats,
|
||||||
|
) -> None:
|
||||||
|
"""Append silence to sinks."""
|
||||||
|
from abogen.domain.audio_buffer import create_silence
|
||||||
|
|
||||||
|
silence = create_silence(duration)
|
||||||
|
if silence.size == 0:
|
||||||
|
return
|
||||||
|
if chapter_sink:
|
||||||
|
chapter_sink.write(silence)
|
||||||
|
if audio_sink:
|
||||||
|
audio_sink.write(silence)
|
||||||
|
stats.current_time += duration
|
||||||
@@ -0,0 +1,97 @@
|
|||||||
|
"""Core models for conversion planning.
|
||||||
|
|
||||||
|
These dataclasses represent the structured plan for a conversion job.
|
||||||
|
They are UI-agnostic and describe WHAT to convert, not HOW to do it.
|
||||||
|
|
||||||
|
The planning flow:
|
||||||
|
ConversionRequest -> ConversionPlan -> ConversionResult
|
||||||
|
|
||||||
|
ConversionPlan contains:
|
||||||
|
- ChapterPlan[]: chapters with their segments
|
||||||
|
- SegmentPlan[]: individual text segments with voice specs
|
||||||
|
- OutputLayout: where to write outputs
|
||||||
|
- IntroOutroSpec: optional intro/outro
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import TYPE_CHECKING, Any, Dict, List, Optional
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.text_extractor import ExtractionResult
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SegmentPlan:
|
||||||
|
"""A single text segment with its voice specification.
|
||||||
|
|
||||||
|
This is the unified model for:
|
||||||
|
- Regular chapter body text
|
||||||
|
- PyQt voice markers (<<VOICE:F1>>)
|
||||||
|
- WebUI chunks with per-chunk voice/speaker
|
||||||
|
- Intro/outro text
|
||||||
|
- Chapter headings
|
||||||
|
"""
|
||||||
|
|
||||||
|
text: str
|
||||||
|
voice_spec: str
|
||||||
|
kind: str = "body" # intro, heading, body, outro
|
||||||
|
speaker_id: str = "narrator"
|
||||||
|
chunk_id: Optional[str] = None
|
||||||
|
chunk_index: Optional[int] = None
|
||||||
|
level: Optional[str] = None # chunk level (paragraph, sentence, etc.)
|
||||||
|
source: str = "chapter" # chapter, voice_marker, chunk
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ChapterPlan:
|
||||||
|
"""A chapter with its metadata and segments."""
|
||||||
|
|
||||||
|
index: int
|
||||||
|
title: str
|
||||||
|
original_title: str
|
||||||
|
body_text: str
|
||||||
|
segments: List[SegmentPlan]
|
||||||
|
voice_spec: str # default voice for this chapter
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class OutputLayout:
|
||||||
|
"""Resolved output paths for a conversion job."""
|
||||||
|
|
||||||
|
parent_dir: Path
|
||||||
|
merged_path: Optional[Path] = None
|
||||||
|
chapter_dir: Optional[Path] = None
|
||||||
|
project_root: Optional[Path] = None
|
||||||
|
audio_dir: Optional[Path] = None
|
||||||
|
subtitle_dir: Optional[Path] = None
|
||||||
|
metadata_dir: Optional[Path] = None
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class IntroOutroSpec:
|
||||||
|
"""Intro/outro specification with resolved text and voice."""
|
||||||
|
|
||||||
|
enabled: bool = False
|
||||||
|
text: str = ""
|
||||||
|
voice_spec: str = ""
|
||||||
|
kind: str = "intro" # intro or outro
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ConversionPlan:
|
||||||
|
"""Complete plan for a conversion job.
|
||||||
|
|
||||||
|
This is the output of the planning phase and input to the executor.
|
||||||
|
"""
|
||||||
|
|
||||||
|
request: ConversionRequest
|
||||||
|
metadata: Dict[str, Any]
|
||||||
|
chapters: List[ChapterPlan]
|
||||||
|
intro: Optional[IntroOutroSpec] = None
|
||||||
|
outro: Optional[IntroOutroSpec] = None
|
||||||
|
output_layout: Optional[OutputLayout] = None
|
||||||
|
extraction: Optional[ExtractionResult] = None
|
||||||
@@ -0,0 +1,393 @@
|
|||||||
|
"""Unified conversion planner.
|
||||||
|
|
||||||
|
Pure functions that take a ConversionRequest and produce a ConversionPlan.
|
||||||
|
No side effects, no I/O — all complexity from both UIs in one place.
|
||||||
|
|
||||||
|
This is Stage 2 of the conversion flow unification plan.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
from typing import Any, Dict, List, Optional, Tuple
|
||||||
|
|
||||||
|
from abogen.application.conversion_models import (
|
||||||
|
ChapterPlan,
|
||||||
|
ConversionPlan,
|
||||||
|
IntroOutroSpec,
|
||||||
|
SegmentPlan,
|
||||||
|
)
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.application.output_layout_service import resolve_output_layout
|
||||||
|
from abogen.domain.chapter_overrides import apply_chapter_overrides
|
||||||
|
from abogen.domain.file_type import auto_select_relevant_chapters
|
||||||
|
from abogen.domain.intro_outro import resolve_intro, resolve_outro
|
||||||
|
from abogen.domain.metadata_extraction import extract_metadata_for_file
|
||||||
|
from abogen.domain.metadata_merge import merge_metadata
|
||||||
|
from abogen.domain.voice_markers import split_text_by_voice_markers
|
||||||
|
|
||||||
|
|
||||||
|
def build_conversion_plan(request: ConversionRequest) -> ConversionPlan:
|
||||||
|
"""Build a complete conversion plan from a request.
|
||||||
|
|
||||||
|
This is the single entry point that both UIs will call.
|
||||||
|
It handles all the planning logic that was previously duplicated
|
||||||
|
in both PyQt and WebUI conversion runners.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
request: Normalized conversion request
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
ConversionPlan with all chapters, segments, and output layout
|
||||||
|
|
||||||
|
Raises:
|
||||||
|
ValueError: If request is invalid (no source, no chapters, etc.)
|
||||||
|
"""
|
||||||
|
# 1. Extract and validate source
|
||||||
|
source_text = _extract_source_text(request)
|
||||||
|
if not source_text or not source_text.strip():
|
||||||
|
raise ValueError("No text content to convert")
|
||||||
|
|
||||||
|
# 2. Extract metadata
|
||||||
|
metadata, extraction = _extract_metadata(request)
|
||||||
|
|
||||||
|
# 3. Parse chapters
|
||||||
|
raw_chapters = _parse_chapters(source_text, request)
|
||||||
|
|
||||||
|
# 4. Apply chapter selection/overrides
|
||||||
|
selected_chapters = _apply_selection(raw_chapters, request)
|
||||||
|
|
||||||
|
# 5. Build segments for each chapter
|
||||||
|
chapters = _build_chapters(selected_chapters, request)
|
||||||
|
|
||||||
|
# 6. Build intro/outro
|
||||||
|
intro, outro = _build_intro_outro(metadata, request)
|
||||||
|
|
||||||
|
# 7. Resolve output layout
|
||||||
|
output_layout = resolve_output_layout(request)
|
||||||
|
|
||||||
|
logging.info(
|
||||||
|
"[planner] Plan built: chapters=%d intro=%s outro=%s",
|
||||||
|
len(chapters),
|
||||||
|
bool(intro and intro.enabled),
|
||||||
|
bool(outro and outro.enabled),
|
||||||
|
)
|
||||||
|
|
||||||
|
return ConversionPlan(
|
||||||
|
request=request,
|
||||||
|
metadata=metadata,
|
||||||
|
chapters=chapters,
|
||||||
|
intro=intro,
|
||||||
|
outro=outro,
|
||||||
|
output_layout=output_layout,
|
||||||
|
extraction=extraction,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _extract_source_text(request: ConversionRequest) -> Optional[str]:
|
||||||
|
"""Extract text from request source."""
|
||||||
|
from abogen.subtitle_utils import clean_text
|
||||||
|
|
||||||
|
if request.direct_text:
|
||||||
|
text = clean_text(request.direct_text)
|
||||||
|
elif request.source_path and request.source_path.exists():
|
||||||
|
encoding = "utf-8"
|
||||||
|
try:
|
||||||
|
with open(request.source_path, "r", encoding=encoding, errors="replace") as f:
|
||||||
|
text = f.read()
|
||||||
|
except Exception:
|
||||||
|
return None
|
||||||
|
text = clean_text(text)
|
||||||
|
else:
|
||||||
|
return None
|
||||||
|
|
||||||
|
# Apply word substitutions if configured
|
||||||
|
if request.word_substitution:
|
||||||
|
from abogen.word_substitution import apply_word_substitutions
|
||||||
|
|
||||||
|
ws = request.word_substitution
|
||||||
|
text = apply_word_substitutions(
|
||||||
|
text,
|
||||||
|
ws.substitutions_list,
|
||||||
|
ws.case_sensitive,
|
||||||
|
ws.replace_caps,
|
||||||
|
ws.replace_numerals,
|
||||||
|
ws.fix_punctuation,
|
||||||
|
)
|
||||||
|
|
||||||
|
return text
|
||||||
|
|
||||||
|
|
||||||
|
def _extract_metadata(
|
||||||
|
request: ConversionRequest,
|
||||||
|
) -> Tuple[Dict[str, Any], Optional[Any]]:
|
||||||
|
"""Extract metadata from source file.
|
||||||
|
|
||||||
|
Returns (metadata, extraction) tuple.
|
||||||
|
"""
|
||||||
|
if request.direct_text:
|
||||||
|
return dict(request.metadata_tags), None
|
||||||
|
|
||||||
|
if request.source_path and request.source_path.exists():
|
||||||
|
try:
|
||||||
|
extraction = extract_metadata_for_file(
|
||||||
|
str(request.source_path), is_direct_text=False
|
||||||
|
)
|
||||||
|
metadata = dict(extraction.metadata) if extraction.metadata else {}
|
||||||
|
except Exception:
|
||||||
|
extraction = None
|
||||||
|
metadata = {}
|
||||||
|
metadata = merge_metadata(metadata, request.metadata_tags)
|
||||||
|
return metadata, extraction
|
||||||
|
|
||||||
|
return dict(request.metadata_tags), None
|
||||||
|
|
||||||
|
|
||||||
|
def _parse_chapters(
|
||||||
|
source_text: str, request: ConversionRequest
|
||||||
|
) -> List[Tuple[str, str, str]]:
|
||||||
|
"""Parse source text into raw chapters.
|
||||||
|
|
||||||
|
Returns list of (title, body_text, default_voice) tuples.
|
||||||
|
"""
|
||||||
|
from abogen.domain.text_chapters import parse_chapters_from_text
|
||||||
|
|
||||||
|
# Text is already cleaned in _extract_source_text, so clean=False here
|
||||||
|
chapters = parse_chapters_from_text(source_text, default_title="text", clean=False)
|
||||||
|
|
||||||
|
# Default voice from request
|
||||||
|
default_voice = request.voice or "M1"
|
||||||
|
|
||||||
|
return [(title, text, default_voice) for title, text in chapters]
|
||||||
|
|
||||||
|
|
||||||
|
def _apply_selection(
|
||||||
|
raw_chapters: List[Tuple[str, str, str]], request: ConversionRequest
|
||||||
|
) -> List[Tuple[str, str, str]]:
|
||||||
|
"""Apply chapter selection and overrides."""
|
||||||
|
from abogen.text_extractor import ExtractedChapter
|
||||||
|
|
||||||
|
# Convert to ExtractedChapter objects for auto_select_relevant_chapters
|
||||||
|
extracted = [
|
||||||
|
ExtractedChapter(title=title, text=text)
|
||||||
|
for title, text, _ in raw_chapters
|
||||||
|
]
|
||||||
|
|
||||||
|
# If user specified chapters, apply overrides
|
||||||
|
chapter_chunk = request.chapter_chunk
|
||||||
|
if chapter_chunk and chapter_chunk.chapter_overrides:
|
||||||
|
selected, _, diagnostics = apply_chapter_overrides(extracted, chapter_chunk.chapter_overrides)
|
||||||
|
if selected:
|
||||||
|
# Map back to (title, text, voice) tuples
|
||||||
|
result = []
|
||||||
|
for ch in selected:
|
||||||
|
# Find matching original chapter to get voice
|
||||||
|
voice = request.voice or "M1"
|
||||||
|
for orig_title, orig_text, orig_voice in raw_chapters:
|
||||||
|
if orig_title == ch.title:
|
||||||
|
voice = orig_voice
|
||||||
|
break
|
||||||
|
result.append((ch.title, ch.text or "", voice))
|
||||||
|
return result
|
||||||
|
# If no chapters selected, fall through to auto-selection
|
||||||
|
|
||||||
|
# Auto-select relevant chapters
|
||||||
|
from abogen.domain.file_type import infer_file_type
|
||||||
|
|
||||||
|
file_type = infer_file_type(request.source_path) if request.source_path else "text"
|
||||||
|
result = auto_select_relevant_chapters(extracted, file_type)
|
||||||
|
filtered = result.kept
|
||||||
|
|
||||||
|
if filtered:
|
||||||
|
# Map back to (title, text, voice) tuples
|
||||||
|
result = []
|
||||||
|
for ch in filtered:
|
||||||
|
voice = request.voice or "M1"
|
||||||
|
for orig_title, orig_text, orig_voice in raw_chapters:
|
||||||
|
if orig_title == ch.title:
|
||||||
|
voice = orig_voice
|
||||||
|
break
|
||||||
|
result.append((ch.title, ch.text or "", voice))
|
||||||
|
return result
|
||||||
|
|
||||||
|
# Fall back to all chapters
|
||||||
|
return raw_chapters
|
||||||
|
|
||||||
|
|
||||||
|
def _build_chapters(
|
||||||
|
selected_chapters: List[Tuple[str, str, str]], request: ConversionRequest
|
||||||
|
) -> List[ChapterPlan]:
|
||||||
|
"""Build ChapterPlan with SegmentPlan for each chapter."""
|
||||||
|
from abogen.domain.chapter_titles import normalize_chapter_opening_caps
|
||||||
|
|
||||||
|
chapters = []
|
||||||
|
|
||||||
|
for idx, (title, body_text, default_voice) in enumerate(selected_chapters, 1):
|
||||||
|
# Apply caps normalization to body text if enabled
|
||||||
|
if request.normalize_chapter_opening_caps and body_text:
|
||||||
|
body_text, _ = normalize_chapter_opening_caps(body_text)
|
||||||
|
|
||||||
|
# Build segments for this chapter (idx is 1-based, chunks use 0-based)
|
||||||
|
segments = _build_segments(body_text, default_voice, request, chapter_index=idx - 1)
|
||||||
|
|
||||||
|
chapter = ChapterPlan(
|
||||||
|
index=idx,
|
||||||
|
title=title,
|
||||||
|
original_title=title,
|
||||||
|
body_text=body_text,
|
||||||
|
segments=segments,
|
||||||
|
voice_spec=default_voice,
|
||||||
|
)
|
||||||
|
chapters.append(chapter)
|
||||||
|
|
||||||
|
return chapters
|
||||||
|
|
||||||
|
|
||||||
|
def _build_segments(
|
||||||
|
body_text: str, default_voice: str, request: ConversionRequest,
|
||||||
|
chapter_index: int = 0,
|
||||||
|
) -> List[SegmentPlan]:
|
||||||
|
"""Build SegmentPlan list for a chapter's body text.
|
||||||
|
|
||||||
|
Handles voice markers (PyQt) and chunks (WebUI).
|
||||||
|
"""
|
||||||
|
segments = []
|
||||||
|
|
||||||
|
# Check for chunks (WebUI style)
|
||||||
|
chapter_chunk = request.chapter_chunk
|
||||||
|
if chapter_chunk and chapter_chunk.chunks:
|
||||||
|
# Group chunks by chapter index
|
||||||
|
from abogen.domain.chunk_utils import group_chunks_by_chapter
|
||||||
|
|
||||||
|
chunk_groups = group_chunks_by_chapter(chapter_chunk.chunks)
|
||||||
|
chunks_for_chapter = chunk_groups.get(chapter_index, [])
|
||||||
|
|
||||||
|
for chunk_idx, chunk in enumerate(chunks_for_chapter):
|
||||||
|
chunk_text = chunk.get("normalized_text") or chunk.get("text", "")
|
||||||
|
if not chunk_text or not chunk_text.strip():
|
||||||
|
continue
|
||||||
|
|
||||||
|
chunk_voice = _resolve_chunk_voice(chunk, default_voice, request)
|
||||||
|
speaker_id = chunk.get("speaker_id", "narrator")
|
||||||
|
|
||||||
|
segments.append(
|
||||||
|
SegmentPlan(
|
||||||
|
text=chunk_text.strip(),
|
||||||
|
voice_spec=chunk_voice,
|
||||||
|
kind="body",
|
||||||
|
speaker_id=speaker_id,
|
||||||
|
chunk_id=chunk.get("id"),
|
||||||
|
chunk_index=chunk.get("chunk_index", chunk_idx),
|
||||||
|
level=chunk.get("level", chapter_chunk.chunk_level),
|
||||||
|
source="chunk",
|
||||||
|
)
|
||||||
|
)
|
||||||
|
return segments
|
||||||
|
|
||||||
|
# Check for voice markers (PyQt style)
|
||||||
|
# Detect markers even if validation fails (voice names may not be loaded yet)
|
||||||
|
from abogen.domain.voice_markers import _VOICE_MARKER_SEARCH_PATTERN
|
||||||
|
|
||||||
|
has_voice_markers = bool(_VOICE_MARKER_SEARCH_PATTERN.search(body_text))
|
||||||
|
voice_segments, last_voice, valid_count, invalid_count = split_text_by_voice_markers(
|
||||||
|
body_text, default_voice
|
||||||
|
)
|
||||||
|
|
||||||
|
if has_voice_markers or (len(voice_segments) > 1):
|
||||||
|
# Voice markers were used
|
||||||
|
for voice_name, segment_text in voice_segments:
|
||||||
|
if not segment_text or not segment_text.strip():
|
||||||
|
continue
|
||||||
|
segments.append(
|
||||||
|
SegmentPlan(
|
||||||
|
text=segment_text.strip(),
|
||||||
|
voice_spec=voice_name,
|
||||||
|
kind="body",
|
||||||
|
source="voice_marker",
|
||||||
|
)
|
||||||
|
)
|
||||||
|
return segments
|
||||||
|
|
||||||
|
# No voice markers — single segment for entire body
|
||||||
|
if body_text and body_text.strip():
|
||||||
|
segments.append(
|
||||||
|
SegmentPlan(
|
||||||
|
text=body_text.strip(),
|
||||||
|
voice_spec=default_voice,
|
||||||
|
kind="body",
|
||||||
|
source="chapter",
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
return segments
|
||||||
|
|
||||||
|
|
||||||
|
def _resolve_chunk_voice(
|
||||||
|
chunk: Dict[str, Any], default_voice: str, request: ConversionRequest
|
||||||
|
) -> str:
|
||||||
|
"""Resolve voice for a chunk."""
|
||||||
|
# Check for speaker-based voice
|
||||||
|
speaker_id = chunk.get("speaker_id", "narrator")
|
||||||
|
speakers = request.chapter_chunk.speakers if request.chapter_chunk else {}
|
||||||
|
if speaker_id and speaker_id != "narrator" and speakers:
|
||||||
|
speaker_config = speakers.get(speaker_id, {})
|
||||||
|
if isinstance(speaker_config, dict):
|
||||||
|
voice = speaker_config.get("voice")
|
||||||
|
if voice:
|
||||||
|
return voice
|
||||||
|
|
||||||
|
# Check for direct voice field
|
||||||
|
voice = chunk.get("voice")
|
||||||
|
if voice:
|
||||||
|
return voice
|
||||||
|
|
||||||
|
return default_voice
|
||||||
|
|
||||||
|
|
||||||
|
def _build_intro_outro(
|
||||||
|
metadata: Dict[str, Any], request: ConversionRequest
|
||||||
|
) -> Tuple[Optional[IntroOutroSpec], Optional[IntroOutroSpec]]:
|
||||||
|
"""Build intro and outro specs."""
|
||||||
|
intro_spec = None
|
||||||
|
outro_spec = None
|
||||||
|
|
||||||
|
# Intro
|
||||||
|
if request.read_title_intro:
|
||||||
|
resolved = resolve_intro(
|
||||||
|
metadata,
|
||||||
|
request.original_filename,
|
||||||
|
True,
|
||||||
|
request.voice or "M1",
|
||||||
|
request.voice or "M1",
|
||||||
|
[],
|
||||||
|
)
|
||||||
|
if resolved.enabled:
|
||||||
|
intro_spec = IntroOutroSpec(
|
||||||
|
enabled=True,
|
||||||
|
text=resolved.text,
|
||||||
|
voice_spec=resolved.voice_spec,
|
||||||
|
kind="intro",
|
||||||
|
)
|
||||||
|
|
||||||
|
# Outro
|
||||||
|
if request.read_closing_outro:
|
||||||
|
resolved = resolve_outro(
|
||||||
|
metadata,
|
||||||
|
request.original_filename,
|
||||||
|
True,
|
||||||
|
request.voice or "M1",
|
||||||
|
request.voice or "M1",
|
||||||
|
[],
|
||||||
|
)
|
||||||
|
if resolved.enabled:
|
||||||
|
outro_spec = IntroOutroSpec(
|
||||||
|
enabled=True,
|
||||||
|
text=resolved.text,
|
||||||
|
voice_spec=resolved.voice_spec,
|
||||||
|
kind="outro",
|
||||||
|
)
|
||||||
|
|
||||||
|
return intro_spec, outro_spec
|
||||||
|
|
||||||
|
|
||||||
|
# Output layout resolution is now in application/output_layout_service.py
|
||||||
@@ -0,0 +1,112 @@
|
|||||||
|
"""Ports / interfaces for the conversion service.
|
||||||
|
|
||||||
|
These protocols define how the conversion service communicates with
|
||||||
|
the outside world (UI, TTS backends, voice resolvers).
|
||||||
|
|
||||||
|
The service ONLY depends on these interfaces, never on concrete
|
||||||
|
implementations (PyQt signals, Flask Job, etc.).
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Protocol
|
||||||
|
|
||||||
|
|
||||||
|
class ConversionCancelled(Exception):
|
||||||
|
"""Raised when conversion is cancelled by user."""
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
class ConversionEvents(Protocol):
|
||||||
|
"""UI-specific actions the conversion service delegates back to the caller.
|
||||||
|
|
||||||
|
Implementations:
|
||||||
|
- PyQt: emits signals (log_updated, progress_updated, etc.)
|
||||||
|
- WebUI: updates Job attributes (job.add_log, job.progress, etc.)
|
||||||
|
"""
|
||||||
|
|
||||||
|
def log(self, message: str, level: str = "info") -> None:
|
||||||
|
"""Log a message to the UI."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def progress(self, processed: int, total: int, etr: str) -> None:
|
||||||
|
"""Update progress display."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def check_cancelled(self) -> None:
|
||||||
|
"""Check if conversion was cancelled.
|
||||||
|
|
||||||
|
Should raise ConversionCancelled (or UI-specific exception)
|
||||||
|
if cancellation is requested. Normal return means "continue".
|
||||||
|
"""
|
||||||
|
...
|
||||||
|
|
||||||
|
|
||||||
|
class PipelineProvider(Protocol):
|
||||||
|
"""Provides access to TTS backends (Kokoro, SuperTonic, etc.).
|
||||||
|
|
||||||
|
Implementations:
|
||||||
|
- PyQt: wraps self.backend (single pipeline)
|
||||||
|
- WebUI: wraps PipelinePool (multi-provider)
|
||||||
|
"""
|
||||||
|
|
||||||
|
def get(self, provider: str, language: str, use_gpu: bool) -> Any:
|
||||||
|
"""Get a TTS backend instance."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def dispose_all(self) -> None:
|
||||||
|
"""Dispose all backend resources."""
|
||||||
|
...
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ResolvedVoice:
|
||||||
|
"""A resolved voice ready for TTS synthesis."""
|
||||||
|
|
||||||
|
provider: str
|
||||||
|
resolved_spec: str
|
||||||
|
voice: Any # loaded voice tensor or name
|
||||||
|
speed: float
|
||||||
|
supertonic_steps: int
|
||||||
|
|
||||||
|
|
||||||
|
class VoiceResolver(Protocol):
|
||||||
|
"""Resolves voice specs into loaded voice objects.
|
||||||
|
|
||||||
|
Implementations:
|
||||||
|
- PyQt: wraps load_voice_cached + VoiceCache
|
||||||
|
- WebUI: wraps resolve_voice_choice + PipelinePool + VoiceCache
|
||||||
|
"""
|
||||||
|
|
||||||
|
def resolve(self, voice_spec: str) -> ResolvedVoice:
|
||||||
|
"""Resolve a voice spec into a loaded voice."""
|
||||||
|
...
|
||||||
|
|
||||||
|
|
||||||
|
class SubtitleWriter(Protocol):
|
||||||
|
"""Writes subtitle entries to a file."""
|
||||||
|
|
||||||
|
def open(self) -> None:
|
||||||
|
"""Open the subtitle file for writing."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def write_entry(self, start: float, end: float, text: str) -> None:
|
||||||
|
"""Write a single subtitle entry."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def close(self) -> None:
|
||||||
|
"""Close the subtitle file."""
|
||||||
|
...
|
||||||
|
|
||||||
|
|
||||||
|
class AudioSink(Protocol):
|
||||||
|
"""Writes audio data to a file."""
|
||||||
|
|
||||||
|
def write(self, audio: Any) -> None:
|
||||||
|
"""Write audio samples to the sink."""
|
||||||
|
...
|
||||||
|
|
||||||
|
def close(self) -> None:
|
||||||
|
"""Close the audio file."""
|
||||||
|
...
|
||||||
@@ -0,0 +1,155 @@
|
|||||||
|
"""ConversionRequest — normalized input for a conversion job.
|
||||||
|
|
||||||
|
This is NOT a WebUI Job and NOT a PyQt ConversionThread state.
|
||||||
|
It describes the TASK, not the UI.
|
||||||
|
|
||||||
|
UI adapters are responsible for converting their respective state
|
||||||
|
into a ConversionRequest before calling ConversionService.run().
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import dataclasses
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional
|
||||||
|
|
||||||
|
from abogen.application.conversion_config import (
|
||||||
|
ChapterChunkConfig,
|
||||||
|
CoverConfig,
|
||||||
|
Epub3ExportConfig,
|
||||||
|
PronunciationConfig,
|
||||||
|
SaveConfig,
|
||||||
|
SubtitleConfig,
|
||||||
|
SubtitleInputConfig,
|
||||||
|
WordSubstitutionConfig,
|
||||||
|
)
|
||||||
|
from abogen.domain.enums import Language, OutputFormat
|
||||||
|
|
||||||
|
|
||||||
|
class ConversionRequestError(ValueError):
|
||||||
|
"""Raised when ConversionRequest has invalid field values."""
|
||||||
|
|
||||||
|
|
||||||
|
# Numeric field constraints: attr -> (min, max)
|
||||||
|
_NUMERIC_CONSTRAINTS: dict[str, tuple[float, float | None]] = {
|
||||||
|
"speed": (0.5, 3.0),
|
||||||
|
"supertonic_total_steps": (2, 15),
|
||||||
|
"silence_between_chapters": (0.0, None),
|
||||||
|
"chapter_intro_delay": (0.0, None),
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ConversionRequest:
|
||||||
|
"""Normalized request for a conversion job.
|
||||||
|
|
||||||
|
Only contains fields that describe the conversion task itself.
|
||||||
|
UI-only fields (display, logging, user prompts) stay in adapters.
|
||||||
|
|
||||||
|
Feature toggles use config objects (None = disabled):
|
||||||
|
- word_substitution, subtitle_input, chapter_chunk, epub3_export
|
||||||
|
- pronunciation (raw data, compiled by app layer)
|
||||||
|
- subtitle, save, cover (grouped parameters)
|
||||||
|
|
||||||
|
Validation runs on creation via __post_init__:
|
||||||
|
- None values → replaced with field default (from declaration)
|
||||||
|
- Numeric fields → clamped to valid range
|
||||||
|
"""
|
||||||
|
|
||||||
|
# --- Source ---
|
||||||
|
source_path: Optional[Path] = None
|
||||||
|
direct_text: Optional[str] = None
|
||||||
|
original_filename: str = ""
|
||||||
|
|
||||||
|
# --- TTS Settings ---
|
||||||
|
language: Language = Language.EN_US
|
||||||
|
tts_provider: str = "kokoro"
|
||||||
|
voice: str = "M1"
|
||||||
|
voice_profile: Optional[str] = None
|
||||||
|
speed: float = 1.0
|
||||||
|
use_gpu: bool = True
|
||||||
|
supertonic_total_steps: int = 5
|
||||||
|
|
||||||
|
# --- Output Format ---
|
||||||
|
output_format: OutputFormat = OutputFormat.WAV
|
||||||
|
|
||||||
|
# --- Timing ---
|
||||||
|
silence_between_chapters: float = 2.0
|
||||||
|
chapter_intro_delay: float = 0.0
|
||||||
|
|
||||||
|
# --- Content Processing ---
|
||||||
|
replace_single_newlines: bool = False
|
||||||
|
read_title_intro: bool = False
|
||||||
|
read_closing_outro: bool = True
|
||||||
|
auto_prefix_chapter_titles: bool = True
|
||||||
|
normalize_chapter_opening_caps: bool = False
|
||||||
|
|
||||||
|
# --- Metadata ---
|
||||||
|
metadata_tags: Dict[str, Any] = field(default_factory=dict)
|
||||||
|
|
||||||
|
# --- Grouped configs ---
|
||||||
|
subtitle: SubtitleConfig = field(default_factory=SubtitleConfig)
|
||||||
|
save: SaveConfig = field(default_factory=SaveConfig)
|
||||||
|
cover: CoverConfig = field(default_factory=CoverConfig)
|
||||||
|
pronunciation: PronunciationConfig = field(default_factory=PronunciationConfig)
|
||||||
|
|
||||||
|
# --- Feature configs (None = disabled) ---
|
||||||
|
epub3_export: Optional[Epub3ExportConfig] = None
|
||||||
|
word_substitution: Optional[WordSubstitutionConfig] = None
|
||||||
|
subtitle_input: Optional[SubtitleInputConfig] = None
|
||||||
|
chapter_chunk: Optional[ChapterChunkConfig] = None
|
||||||
|
|
||||||
|
def __post_init__(self) -> None:
|
||||||
|
"""Resolve None → default, then validate and clamp."""
|
||||||
|
_apply_none_defaults(self)
|
||||||
|
if not self.tts_provider:
|
||||||
|
self.tts_provider = "kokoro"
|
||||||
|
_coerce_enums(self)
|
||||||
|
_clamp_numerics(self)
|
||||||
|
|
||||||
|
|
||||||
|
def _apply_none_defaults(obj: ConversionRequest) -> None:
|
||||||
|
"""Replace None values with field defaults from dataclass declaration."""
|
||||||
|
for f in dataclasses.fields(obj):
|
||||||
|
if getattr(obj, f.name) is not None:
|
||||||
|
continue
|
||||||
|
if f.default is not dataclasses.MISSING:
|
||||||
|
setattr(obj, f.name, f.default)
|
||||||
|
elif f.default_factory is not dataclasses.MISSING:
|
||||||
|
setattr(obj, f.name, f.default_factory())
|
||||||
|
|
||||||
|
|
||||||
|
# Enum fields that accept string coercion: attr -> (enum_class, fallback)
|
||||||
|
_ENUM_COERCIONS: dict[str, tuple[type, Any]] = {
|
||||||
|
"language": (Language, Language.EN_US),
|
||||||
|
"output_format": (OutputFormat, OutputFormat.WAV),
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def _coerce_enums(obj: ConversionRequest) -> None:
|
||||||
|
"""Coerce string values to their expected enum types."""
|
||||||
|
for attr, (enum_cls, fallback) in _ENUM_COERCIONS.items():
|
||||||
|
val = getattr(obj, attr)
|
||||||
|
if isinstance(val, enum_cls):
|
||||||
|
continue
|
||||||
|
try:
|
||||||
|
setattr(obj, attr, enum_cls.from_str(str(val)))
|
||||||
|
except (ValueError, AttributeError):
|
||||||
|
setattr(obj, attr, fallback)
|
||||||
|
|
||||||
|
|
||||||
|
def _clamp_numerics(obj: ConversionRequest) -> None:
|
||||||
|
"""Clamp numeric fields to valid ranges."""
|
||||||
|
for attr, (min_v, max_v) in _NUMERIC_CONSTRAINTS.items():
|
||||||
|
val = getattr(obj, attr)
|
||||||
|
if val is None:
|
||||||
|
continue
|
||||||
|
if not isinstance(val, (int, float)):
|
||||||
|
raise ConversionRequestError(
|
||||||
|
f"{attr} must be a number, got {type(val).__name__}"
|
||||||
|
)
|
||||||
|
clamped = max(min_v, float(val))
|
||||||
|
if max_v is not None:
|
||||||
|
clamped = min(max_v, clamped)
|
||||||
|
setattr(obj, attr, clamped)
|
||||||
@@ -0,0 +1,50 @@
|
|||||||
|
"""ConversionResult — output of a successful conversion.
|
||||||
|
|
||||||
|
Returned by ConversionService.run() after all synthesis and finalization.
|
||||||
|
UI adapters consume this to update their respective state (Job, signals, etc.).
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ConversionResult:
|
||||||
|
"""Output of a successful conversion job."""
|
||||||
|
|
||||||
|
# --- Primary outputs ---
|
||||||
|
audio_path: Optional[Path] = None
|
||||||
|
subtitle_paths: List[Path] = field(default_factory=list)
|
||||||
|
chapter_paths: List[Path] = field(default_factory=list)
|
||||||
|
|
||||||
|
# --- Markers (for metadata/audiobookshelf) ---
|
||||||
|
chapter_markers: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
chunk_markers: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
|
||||||
|
# --- Metadata ---
|
||||||
|
metadata: Dict[str, Any] = field(default_factory=dict)
|
||||||
|
|
||||||
|
# --- Artifacts ---
|
||||||
|
artifacts: Dict[str, Path] = field(default_factory=dict)
|
||||||
|
project_root: Optional[Path] = None
|
||||||
|
epub_path: Optional[Path] = None
|
||||||
|
|
||||||
|
# --- Stats ---
|
||||||
|
total_chapters: int = 0
|
||||||
|
total_segments: int = 0
|
||||||
|
total_characters: int = 0
|
||||||
|
|
||||||
|
# --- Override usage tracking ---
|
||||||
|
usage_counter: Dict[str, int] = field(default_factory=dict)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ConversionError:
|
||||||
|
"""Error information when conversion fails."""
|
||||||
|
|
||||||
|
message: str
|
||||||
|
details: Optional[str] = None
|
||||||
|
is_cancelled: bool = False
|
||||||
@@ -0,0 +1,250 @@
|
|||||||
|
"""ConversionService — main orchestrator for the conversion flow.
|
||||||
|
|
||||||
|
Ties together planner, executor, and finalizers into a single entry point.
|
||||||
|
Both UIs (PyQt, WebUI) call ConversionService.run() to execute a conversion.
|
||||||
|
|
||||||
|
Responsibilities:
|
||||||
|
- Prepare TTSContext (normalization settings, pronunciation rules)
|
||||||
|
- Build ConversionPlan via planner
|
||||||
|
- Execute conversion via executor
|
||||||
|
- Handle lifecycle (cleanup, error handling)
|
||||||
|
- Return ConversionResult
|
||||||
|
|
||||||
|
The service NEVER imports from PyQt or WebUI.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
from collections import defaultdict
|
||||||
|
from typing import Any, Dict
|
||||||
|
|
||||||
|
from abogen.application.conversion_executor import execute_conversion
|
||||||
|
from abogen.application.conversion_models import ConversionPlan
|
||||||
|
from abogen.application.conversion_planner import build_conversion_plan
|
||||||
|
from abogen.application.conversion_ports import ConversionEvents
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.application.conversion_result import ConversionResult
|
||||||
|
from abogen.domain.normalization import build_tts_context
|
||||||
|
|
||||||
|
|
||||||
|
def run_conversion(
|
||||||
|
request: ConversionRequest,
|
||||||
|
events: ConversionEvents,
|
||||||
|
) -> ConversionResult:
|
||||||
|
"""Execute a conversion request and return the result.
|
||||||
|
|
||||||
|
This is the single entry point for both UIs. It orchestrates:
|
||||||
|
1. Voice infrastructure setup (pool, cache, resolver)
|
||||||
|
2. TTS context preparation
|
||||||
|
3. Conversion planning
|
||||||
|
4. Conversion execution
|
||||||
|
5. Resource cleanup
|
||||||
|
|
||||||
|
Args:
|
||||||
|
request: Normalized conversion request
|
||||||
|
events: UI-specific callbacks (log, progress, check_cancelled)
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
ConversionResult with paths and markers
|
||||||
|
|
||||||
|
Raises:
|
||||||
|
ConversionCancelled: If conversion was cancelled
|
||||||
|
ValueError: If request is invalid
|
||||||
|
Exception: On TTS or I/O errors
|
||||||
|
"""
|
||||||
|
from abogen.domain.pipeline_factory import PipelinePool
|
||||||
|
from abogen.domain.voice_loader import VoiceCache
|
||||||
|
|
||||||
|
pool = PipelinePool()
|
||||||
|
voice_cache = VoiceCache()
|
||||||
|
|
||||||
|
try:
|
||||||
|
# Stage 0: Create voice resolver
|
||||||
|
events.log("Preparing conversion pipeline")
|
||||||
|
logging.info(
|
||||||
|
"[app] run_conversion: provider=%s language=%s voice=%s speed=%.2f",
|
||||||
|
request.tts_provider, request.language, request.voice, request.speed,
|
||||||
|
)
|
||||||
|
resolver = _create_voice_resolver(request, pool, voice_cache)
|
||||||
|
|
||||||
|
# Stage 1: Prepare TTS context
|
||||||
|
usage_counter: Dict[str, int] = defaultdict(int)
|
||||||
|
tts_context = build_tts_context(
|
||||||
|
language=request.language,
|
||||||
|
subtitle=request.subtitle,
|
||||||
|
pronunciation=request.pronunciation,
|
||||||
|
usage_counter=usage_counter,
|
||||||
|
log_callback=lambda level, msg: events.log(msg, level=level),
|
||||||
|
)
|
||||||
|
|
||||||
|
# Stage 2: Build conversion plan
|
||||||
|
events.log("Building conversion plan")
|
||||||
|
plan = build_conversion_plan(request)
|
||||||
|
|
||||||
|
# Stage 3: Execute conversion
|
||||||
|
events.log("Starting conversion")
|
||||||
|
result = execute_conversion(
|
||||||
|
plan=plan,
|
||||||
|
events=events,
|
||||||
|
pipeline_provider=pool,
|
||||||
|
voice_resolver=resolver,
|
||||||
|
tts_context=tts_context,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Propagate usage counter to result
|
||||||
|
result.usage_counter = dict(usage_counter)
|
||||||
|
|
||||||
|
# Stage 4: Finalize (m4b metadata embedding, EPUB3 generation)
|
||||||
|
_finalize(request, result, plan, events)
|
||||||
|
|
||||||
|
events.log("Conversion complete")
|
||||||
|
logging.info("[app] run_conversion completed successfully")
|
||||||
|
return result
|
||||||
|
|
||||||
|
except Exception as e:
|
||||||
|
events.log(f"Conversion failed: {e}", level="error")
|
||||||
|
logging.exception("[app] run_conversion failed: %s", e)
|
||||||
|
raise
|
||||||
|
finally:
|
||||||
|
pool.dispose_all()
|
||||||
|
voice_cache.clear()
|
||||||
|
from abogen.application.cleanup import flush_cuda
|
||||||
|
flush_cuda()
|
||||||
|
|
||||||
|
|
||||||
|
def _create_voice_resolver(
|
||||||
|
request: ConversionRequest,
|
||||||
|
pool: Any,
|
||||||
|
cache: Any,
|
||||||
|
) -> Any:
|
||||||
|
"""Create AppVoiceResolver with loaded profiles.
|
||||||
|
|
||||||
|
Loads voice profiles from disk, normalizes them, and creates
|
||||||
|
an AppVoiceResolver that can resolve voice specs into loaded voices.
|
||||||
|
"""
|
||||||
|
from abogen.application.voice_resolver import AppVoiceResolver
|
||||||
|
from abogen.voice_profiles import load_profiles, normalize_profile_entry
|
||||||
|
|
||||||
|
try:
|
||||||
|
profiles = load_profiles()
|
||||||
|
except Exception:
|
||||||
|
profiles = {}
|
||||||
|
|
||||||
|
normalized_profiles: Dict[str, Dict[str, Any]] = {}
|
||||||
|
for name, entry in (profiles or {}).items():
|
||||||
|
normalized = normalize_profile_entry(entry)
|
||||||
|
if normalized:
|
||||||
|
normalized_profiles[str(name)] = normalized
|
||||||
|
|
||||||
|
return AppVoiceResolver(request, normalized_profiles, pool, cache)
|
||||||
|
|
||||||
|
|
||||||
|
def _finalize(
|
||||||
|
request: ConversionRequest,
|
||||||
|
result: ConversionResult,
|
||||||
|
plan: ConversionPlan,
|
||||||
|
events: ConversionEvents,
|
||||||
|
) -> None:
|
||||||
|
"""Post-conversion finalization (m4b metadata embedding, EPUB3 generation, etc.)."""
|
||||||
|
from abogen.domain.enums import OutputFormat
|
||||||
|
|
||||||
|
# m4b metadata embedding
|
||||||
|
if (
|
||||||
|
result.audio_path
|
||||||
|
and request.output_format == OutputFormat.M4B
|
||||||
|
):
|
||||||
|
|
||||||
|
from abogen.infrastructure.exporters import ExportService
|
||||||
|
|
||||||
|
export_svc = ExportService()
|
||||||
|
|
||||||
|
try:
|
||||||
|
export_svc.embed_m4b_metadata(
|
||||||
|
audio_path=result.audio_path,
|
||||||
|
metadata=result.metadata or {},
|
||||||
|
chapters=result.chapter_markers or [],
|
||||||
|
cover=request.cover,
|
||||||
|
log_callback=lambda msg, level="info": events.log(msg, level=level),
|
||||||
|
)
|
||||||
|
except Exception as exc:
|
||||||
|
events.log(f"Failed to embed m4b metadata: {exc}", level="error")
|
||||||
|
raise RuntimeError(f"Failed to embed m4b metadata: {exc}") from exc
|
||||||
|
|
||||||
|
# EPUB3 generation
|
||||||
|
if request.epub3_export and plan.extraction:
|
||||||
|
audio_asset = result.audio_path
|
||||||
|
if not audio_asset and result.chapter_paths:
|
||||||
|
audio_asset = result.chapter_paths[0]
|
||||||
|
|
||||||
|
if audio_asset:
|
||||||
|
try:
|
||||||
|
|
||||||
|
from abogen.epub3.exporter import build_epub3_package
|
||||||
|
|
||||||
|
epub_root = result.project_root or plan.output_layout.parent_dir
|
||||||
|
from abogen.domain.output_paths import build_output_path
|
||||||
|
|
||||||
|
epub_output_path = build_output_path(epub_root, request.original_filename, "epub")
|
||||||
|
events.log("Generating EPUB 3 package...")
|
||||||
|
epub_path = build_epub3_package(
|
||||||
|
output_path=epub_output_path,
|
||||||
|
book_id=request.epub3_export.book_id,
|
||||||
|
extraction=plan.extraction,
|
||||||
|
metadata_tags=result.metadata or {},
|
||||||
|
chapter_markers=result.chapter_markers or [],
|
||||||
|
chunk_markers=result.chunk_markers or [],
|
||||||
|
chunks=request.chapter_chunk.chunks if request.chapter_chunk else [],
|
||||||
|
audio_path=audio_asset,
|
||||||
|
speaker_mode=request.chapter_chunk.speaker_mode if request.chapter_chunk else "single",
|
||||||
|
cover=request.cover,
|
||||||
|
)
|
||||||
|
result.epub_path = epub_path
|
||||||
|
result.artifacts["epub3"] = epub_path
|
||||||
|
events.log(f"EPUB 3 package created at {epub_path}")
|
||||||
|
except Exception as exc:
|
||||||
|
events.log(f"Failed to generate EPUB 3: {exc}", level="error")
|
||||||
|
else:
|
||||||
|
events.log("Skipped EPUB 3 generation: audio output unavailable.", level="warning")
|
||||||
|
|
||||||
|
# Build metadata payload and write metadata.json
|
||||||
|
if plan.output_layout and plan.output_layout.metadata_dir:
|
||||||
|
from abogen.domain.metadata_helpers import build_metadata_payload
|
||||||
|
|
||||||
|
metadata_payload = build_metadata_payload(
|
||||||
|
metadata=result.metadata,
|
||||||
|
chapter_markers=result.chapter_markers,
|
||||||
|
chunk_markers=result.chunk_markers,
|
||||||
|
chunk_level=request.chapter_chunk.chunk_level if request.chapter_chunk else None,
|
||||||
|
speaker_mode=request.chapter_chunk.speaker_mode if request.chapter_chunk else None,
|
||||||
|
speakers=request.chapter_chunk.speakers if request.chapter_chunk else None,
|
||||||
|
generate_epub3=bool(request.epub3_export),
|
||||||
|
)
|
||||||
|
|
||||||
|
metadata_dir = plan.output_layout.metadata_dir
|
||||||
|
metadata_dir.mkdir(parents=True, exist_ok=True)
|
||||||
|
metadata_file = metadata_dir / "metadata.json"
|
||||||
|
|
||||||
|
import json
|
||||||
|
|
||||||
|
metadata_file.write_text(json.dumps(metadata_payload, indent=2), encoding="utf-8")
|
||||||
|
result.artifacts["metadata"] = metadata_file
|
||||||
|
events.log(f"Metadata written to {metadata_file}")
|
||||||
|
|
||||||
|
# Record override usage
|
||||||
|
if result.usage_counter:
|
||||||
|
try:
|
||||||
|
from abogen.normalization_settings import record_override_usage
|
||||||
|
|
||||||
|
record_override_usage(result.usage_counter)
|
||||||
|
except Exception as exc:
|
||||||
|
events.log(f"Failed to record override usage: {exc}", level="debug")
|
||||||
|
|
||||||
|
# Post-conversion hooks (Audiobookshelf, etc.)
|
||||||
|
from abogen.application.integration_hooks import PostConversionHooks
|
||||||
|
|
||||||
|
hooks = PostConversionHooks()
|
||||||
|
hooks.run(request, result, events)
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
@@ -0,0 +1,164 @@
|
|||||||
|
"""Post-conversion integration hooks.
|
||||||
|
|
||||||
|
Called by ConversionService after finalization.
|
||||||
|
Each integration is a method on PostConversionHooks — isolated, testable,
|
||||||
|
and easy to extend with new hooks (Plex, Navidrome, etc.).
|
||||||
|
|
||||||
|
The service NEVER imports from PyQt or WebUI.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.application.conversion_ports import ConversionEvents
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.application.conversion_result import ConversionResult
|
||||||
|
from abogen.domain.metadata_helpers import (
|
||||||
|
build_audiobookshelf_metadata as _build_abs_metadata,
|
||||||
|
load_audiobookshelf_chapters as _load_abs_chapters,
|
||||||
|
)
|
||||||
|
from abogen.domain.settings_core import (
|
||||||
|
build_audiobookshelf_config,
|
||||||
|
coerce_bool,
|
||||||
|
load_audiobookshelf_config,
|
||||||
|
stored_integration_config,
|
||||||
|
)
|
||||||
|
from abogen.integrations.audiobookshelf import (
|
||||||
|
AudiobookshelfClient,
|
||||||
|
AudiobookshelfUploadError,
|
||||||
|
)
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
|
||||||
|
class PostConversionHooks:
|
||||||
|
"""Runs post-conversion integrations (Audiobookshelf, etc.).
|
||||||
|
|
||||||
|
Usage::
|
||||||
|
|
||||||
|
hooks = PostConversionHooks()
|
||||||
|
hooks.run(request, result, events)
|
||||||
|
"""
|
||||||
|
|
||||||
|
def run(
|
||||||
|
self,
|
||||||
|
request: ConversionRequest,
|
||||||
|
result: ConversionResult,
|
||||||
|
events: ConversionEvents,
|
||||||
|
) -> None:
|
||||||
|
"""Run all registered post-conversion hooks."""
|
||||||
|
self._maybe_send_to_audiobookshelf(request, result, events)
|
||||||
|
|
||||||
|
# ------------------------------------------------------------------
|
||||||
|
# Audiobookshelf
|
||||||
|
# ------------------------------------------------------------------
|
||||||
|
|
||||||
|
def _maybe_send_to_audiobookshelf(
|
||||||
|
self,
|
||||||
|
request: ConversionRequest,
|
||||||
|
result: ConversionResult,
|
||||||
|
events: ConversionEvents,
|
||||||
|
) -> None:
|
||||||
|
"""Upload finished audiobook to Audiobookshelf if enabled."""
|
||||||
|
abs_settings = stored_integration_config("audiobookshelf")
|
||||||
|
if not abs_settings:
|
||||||
|
return
|
||||||
|
|
||||||
|
enabled = coerce_bool(abs_settings.get("enabled"), False)
|
||||||
|
auto_send = coerce_bool(abs_settings.get("auto_send"), False)
|
||||||
|
if not (enabled and auto_send):
|
||||||
|
return
|
||||||
|
|
||||||
|
config = build_audiobookshelf_config(abs_settings)
|
||||||
|
if config is None:
|
||||||
|
events.log(
|
||||||
|
"Audiobookshelf upload skipped: configure base URL, API token, "
|
||||||
|
"library ID, and folder ID first.",
|
||||||
|
level="warning",
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
|
audio_path = result.audio_path
|
||||||
|
if not audio_path or not audio_path.exists():
|
||||||
|
events.log(
|
||||||
|
"Audiobookshelf upload skipped: audio output not found.",
|
||||||
|
level="warning",
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
|
# Build metadata
|
||||||
|
filename = request.original_filename or "Audiobook"
|
||||||
|
lang = request.language.value if hasattr(request.language, "value") else str(request.language)
|
||||||
|
metadata = _build_abs_metadata(
|
||||||
|
result.metadata or {},
|
||||||
|
language=lang,
|
||||||
|
filename=Path(filename).stem,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Load chapters from metadata artifact
|
||||||
|
chapters = None
|
||||||
|
if config.send_chapters:
|
||||||
|
metadata_artifact = result.artifacts.get("metadata")
|
||||||
|
if metadata_artifact:
|
||||||
|
metadata_path = (
|
||||||
|
metadata_artifact
|
||||||
|
if isinstance(metadata_artifact, Path)
|
||||||
|
else Path(str(metadata_artifact))
|
||||||
|
)
|
||||||
|
chapters = _load_abs_chapters(metadata_path)
|
||||||
|
|
||||||
|
# Resolve cover
|
||||||
|
cover_path = None
|
||||||
|
if config.send_cover and request.cover and request.cover.path:
|
||||||
|
candidate = request.cover.path
|
||||||
|
if isinstance(candidate, Path) and candidate.exists():
|
||||||
|
cover_path = candidate
|
||||||
|
|
||||||
|
# Resolve subtitles
|
||||||
|
subtitles = None
|
||||||
|
if config.send_subtitles and result.subtitle_paths:
|
||||||
|
subtitles = [
|
||||||
|
p for p in result.subtitle_paths
|
||||||
|
if isinstance(p, Path) and p.exists()
|
||||||
|
]
|
||||||
|
|
||||||
|
# Upload
|
||||||
|
client = AudiobookshelfClient(config)
|
||||||
|
display_title = metadata.get("title") or audio_path.stem
|
||||||
|
|
||||||
|
try:
|
||||||
|
existing_items = client.find_existing_items(
|
||||||
|
display_title, folder_id=config.folder_id,
|
||||||
|
)
|
||||||
|
except AudiobookshelfUploadError as exc:
|
||||||
|
events.log(f"Audiobookshelf lookup failed: {exc}", level="error")
|
||||||
|
return
|
||||||
|
|
||||||
|
if existing_items:
|
||||||
|
events.log(
|
||||||
|
f"Removing existing Audiobookshelf item(s) for '{display_title}'.",
|
||||||
|
level="info",
|
||||||
|
)
|
||||||
|
try:
|
||||||
|
client.delete_items(existing_items)
|
||||||
|
except Exception as exc:
|
||||||
|
events.log(
|
||||||
|
f"Failed to remove existing item(s): {exc}", level="warning",
|
||||||
|
)
|
||||||
|
|
||||||
|
try:
|
||||||
|
client.upload_audiobook(
|
||||||
|
audio_path,
|
||||||
|
metadata=metadata,
|
||||||
|
cover_path=cover_path,
|
||||||
|
chapters=chapters,
|
||||||
|
subtitles=subtitles,
|
||||||
|
)
|
||||||
|
events.log("Audiobookshelf upload queued.", level="info")
|
||||||
|
except AudiobookshelfUploadError as exc:
|
||||||
|
events.log(f"Audiobookshelf upload failed: {exc}", level="error")
|
||||||
|
except Exception as exc:
|
||||||
|
events.log(f"Audiobookshelf integration error: {exc}", level="error")
|
||||||
@@ -0,0 +1,149 @@
|
|||||||
|
"""Output layout resolution service.
|
||||||
|
|
||||||
|
Determines where conversion outputs (audio, subtitles, metadata) should be written.
|
||||||
|
Extracted from conversion_planner.py as a standalone service per plan Stage 5.
|
||||||
|
|
||||||
|
Responsibilities:
|
||||||
|
- Resolve base output directory from save_mode and source_path
|
||||||
|
- Determine base filename from original_filename
|
||||||
|
- Find unique output path to avoid overwrites
|
||||||
|
- Resolve project layout (audio_dir, subtitle_dir, metadata_dir)
|
||||||
|
- Force merged output for m4b format
|
||||||
|
- Return OutputLayout dataclass
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from pathlib import Path
|
||||||
|
|
||||||
|
from abogen.application.conversion_models import OutputLayout
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.domain.enums import OutputFormat, SaveMode, SubtitleFormat
|
||||||
|
from abogen.domain.output_paths import (
|
||||||
|
resolve_project_layout,
|
||||||
|
resolve_unique_path,
|
||||||
|
sanitize_output_stem,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_output_layout(request: ConversionRequest) -> OutputLayout:
|
||||||
|
"""Resolve output paths for a conversion request.
|
||||||
|
|
||||||
|
This is the single entry point for output path resolution,
|
||||||
|
used by both UIs and the conversion service.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
request: Normalized conversion request
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
OutputLayout with resolved paths
|
||||||
|
"""
|
||||||
|
# Determine base output directory
|
||||||
|
if request.save.mode == SaveMode.CUSTOM_FOLDER and request.save.output_folder:
|
||||||
|
parent_dir = Path(request.save.output_folder)
|
||||||
|
elif request.source_path:
|
||||||
|
parent_dir = request.source_path.parent
|
||||||
|
else:
|
||||||
|
parent_dir = Path.cwd()
|
||||||
|
|
||||||
|
# Determine base name
|
||||||
|
if request.original_filename:
|
||||||
|
base_name = sanitize_output_stem(request.original_filename)
|
||||||
|
elif request.source_path:
|
||||||
|
base_name = sanitize_output_stem(request.source_path.stem)
|
||||||
|
else:
|
||||||
|
base_name = "output"
|
||||||
|
|
||||||
|
# Find unique output path
|
||||||
|
allowed_exts = {request.output_format, SubtitleFormat.SRT, SubtitleFormat.ASS, "vtt", "mp4", OutputFormat.M4B}
|
||||||
|
unique_base = resolve_unique_path(
|
||||||
|
parent_dir, base_name, "", allowed_extensions=allowed_exts
|
||||||
|
)
|
||||||
|
|
||||||
|
# Resolve project layout
|
||||||
|
project_root = None
|
||||||
|
audio_dir = parent_dir
|
||||||
|
subtitle_dir = None
|
||||||
|
metadata_dir = None
|
||||||
|
|
||||||
|
if request.save.save_as_project:
|
||||||
|
project_root, audio_dir, subtitle_dir, metadata_dir = resolve_project_layout(
|
||||||
|
original_filename=request.original_filename,
|
||||||
|
save_as_project=True,
|
||||||
|
base_dir=parent_dir,
|
||||||
|
)
|
||||||
|
|
||||||
|
return OutputLayout(
|
||||||
|
parent_dir=parent_dir,
|
||||||
|
project_root=project_root,
|
||||||
|
audio_dir=audio_dir,
|
||||||
|
subtitle_dir=subtitle_dir,
|
||||||
|
metadata_dir=metadata_dir,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_merged_path(
|
||||||
|
layout: OutputLayout,
|
||||||
|
request: ConversionRequest,
|
||||||
|
) -> Path:
|
||||||
|
"""Resolve the merged output audio file path.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
layout: Resolved output layout
|
||||||
|
request: Conversion request
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Path to the merged output file
|
||||||
|
"""
|
||||||
|
base_name = sanitize_output_stem(
|
||||||
|
request.original_filename or "output"
|
||||||
|
)
|
||||||
|
return layout.audio_dir / f"{base_name}{request.output_format.dot_ext}"
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_chapter_path(
|
||||||
|
layout: OutputLayout,
|
||||||
|
request: ConversionRequest,
|
||||||
|
chapter_title: str,
|
||||||
|
chapter_index: int,
|
||||||
|
) -> Path:
|
||||||
|
"""Resolve the output path for a separate chapter file.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
layout: Resolved output layout
|
||||||
|
request: Conversion request
|
||||||
|
chapter_title: Chapter title for filename
|
||||||
|
chapter_index: Chapter number (1-based)
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Path to the chapter output file
|
||||||
|
"""
|
||||||
|
import re
|
||||||
|
|
||||||
|
slug = re.sub(r'[^\w\s-]', '', chapter_title.lower())
|
||||||
|
slug = re.sub(r'[\s_]+', '_', slug).strip('_')
|
||||||
|
if not slug:
|
||||||
|
slug = f"chapter_{chapter_index}"
|
||||||
|
filename = f"{chapter_index:02d}_{slug}.{request.save.separate_chapters_format}"
|
||||||
|
return layout.audio_dir / "chapters" / filename
|
||||||
|
|
||||||
|
|
||||||
|
def should_merge_output(request: ConversionRequest) -> bool:
|
||||||
|
"""Determine if merged output is required.
|
||||||
|
|
||||||
|
Rules:
|
||||||
|
- m4b format always forces merged output
|
||||||
|
- If save_chapters_separately is False, merged is required
|
||||||
|
- Otherwise, use merge_chapters_at_end setting
|
||||||
|
|
||||||
|
Args:
|
||||||
|
request: Conversion request
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
True if merged output should be created
|
||||||
|
"""
|
||||||
|
if request.output_format == OutputFormat.M4B:
|
||||||
|
return True
|
||||||
|
if not request.save.save_chapters_separately:
|
||||||
|
return True
|
||||||
|
return request.save.merge_chapters_at_end
|
||||||
@@ -0,0 +1,81 @@
|
|||||||
|
"""AppVoiceResolver — voice resolution inside the application layer.
|
||||||
|
|
||||||
|
Resolves voice specs into loaded voices using profiles, pipeline pool,
|
||||||
|
and voice cache. Replaces UI-specific resolvers (WebUIVoiceResolver,
|
||||||
|
PyQtVoiceResolver) with a single app-layer implementation.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
from typing import Any, Dict, Optional
|
||||||
|
|
||||||
|
from abogen.application.conversion_ports import ResolvedVoice, VoiceResolver
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.domain.pipeline_factory import PipelinePool
|
||||||
|
from abogen.domain.voice_loader import VoiceCache, resolve_voice
|
||||||
|
from abogen.domain.voice_utils import resolve_voice_target
|
||||||
|
|
||||||
|
|
||||||
|
class AppVoiceResolver:
|
||||||
|
"""App-layer implementation of VoiceResolver protocol.
|
||||||
|
|
||||||
|
Uses ConversionRequest instead of Job. Loads profiles, creates
|
||||||
|
resolver internally — UIs don't need to manage this.
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(
|
||||||
|
self,
|
||||||
|
request: ConversionRequest,
|
||||||
|
normalized_profiles: Dict[str, Dict[str, Any]],
|
||||||
|
pool: PipelinePool,
|
||||||
|
cache: VoiceCache,
|
||||||
|
):
|
||||||
|
self._request = request
|
||||||
|
self._profiles = normalized_profiles
|
||||||
|
self._cache = cache
|
||||||
|
self._pool = pool
|
||||||
|
|
||||||
|
def resolve(self, voice_spec: str) -> ResolvedVoice:
|
||||||
|
"""Resolve a voice spec into a loaded voice."""
|
||||||
|
provider, resolved, speed, steps = resolve_voice_target(
|
||||||
|
voice_spec,
|
||||||
|
self._profiles,
|
||||||
|
job_voice=self._request.voice,
|
||||||
|
job_tts_provider=self._request.tts_provider,
|
||||||
|
job_supertonic_total_steps=self._request.supertonic_total_steps,
|
||||||
|
job_speed=self._request.speed,
|
||||||
|
)
|
||||||
|
|
||||||
|
cache_key = f"{provider}:{resolved}" if resolved else provider
|
||||||
|
cached = self._cache.get(cache_key)
|
||||||
|
if cached is not None:
|
||||||
|
logging.info("[resolver] Cache hit: spec=%s -> provider=%s resolved=%s", voice_spec, provider, resolved)
|
||||||
|
return ResolvedVoice(
|
||||||
|
provider=provider,
|
||||||
|
resolved_spec=resolved,
|
||||||
|
voice=cached,
|
||||||
|
speed=speed,
|
||||||
|
supertonic_steps=steps or 0,
|
||||||
|
)
|
||||||
|
|
||||||
|
if provider == "kokoro":
|
||||||
|
kokoro_backend = self._pool.get(
|
||||||
|
"kokoro", self._request.language, self._request.use_gpu,
|
||||||
|
)
|
||||||
|
loaded = resolve_voice(
|
||||||
|
resolved, kokoro_backend, self._request.use_gpu, cache=self._cache,
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
loaded = resolved
|
||||||
|
|
||||||
|
self._cache.set(cache_key, loaded)
|
||||||
|
logging.info("[resolver] Resolved: spec=%s -> provider=%s resolved=%s speed=%.2f steps=%s",
|
||||||
|
voice_spec, provider, resolved, speed, steps)
|
||||||
|
return ResolvedVoice(
|
||||||
|
provider=provider,
|
||||||
|
resolved_spec=resolved,
|
||||||
|
voice=loaded,
|
||||||
|
speed=speed,
|
||||||
|
supertonic_steps=steps or 0,
|
||||||
|
)
|
||||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,30 @@
|
|||||||
|
import sys
|
||||||
|
import os
|
||||||
|
import platform
|
||||||
|
import ctypes
|
||||||
|
import importlib.util
|
||||||
|
|
||||||
|
def check_cuda_with_fix():
|
||||||
|
"""
|
||||||
|
Check if CUDA is available, with a fix for PyTorch DLL loading issue
|
||||||
|
([WinError 1114]) on Windows.
|
||||||
|
"""
|
||||||
|
# Fix PyTorch DLL loading issue ([WinError 1114]) on Windows
|
||||||
|
try:
|
||||||
|
if platform.system() == "Windows":
|
||||||
|
spec = importlib.util.find_spec("torch")
|
||||||
|
if spec and spec.origin:
|
||||||
|
dll_path = os.path.join(os.path.dirname(spec.origin), "lib", "c10.dll")
|
||||||
|
if os.path.exists(dll_path):
|
||||||
|
ctypes.CDLL(os.path.normpath(dll_path))
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
try:
|
||||||
|
from torch.cuda import is_available
|
||||||
|
print(is_available())
|
||||||
|
except ImportError:
|
||||||
|
print("False")
|
||||||
|
|
||||||
|
if __name__ == "__main__":
|
||||||
|
check_cuda_with_fix()
|
||||||
@@ -0,0 +1,275 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Dict, Iterable, Iterator, List, Literal, Optional, Tuple
|
||||||
|
from typing import Pattern
|
||||||
|
|
||||||
|
import re
|
||||||
|
|
||||||
|
from abogen.kokoro_text_normalization import ApostropheConfig, normalize_for_pipeline
|
||||||
|
from abogen.normalization_settings import build_apostrophe_config, get_runtime_settings
|
||||||
|
|
||||||
|
ChunkLevel = Literal["paragraph", "sentence"]
|
||||||
|
|
||||||
|
_SENTENCE_SPLIT_REGEX = re.compile(r"(?<!\b[A-Z])[.!?][\s\n]+")
|
||||||
|
_WHITESPACE_REGEX = re.compile(r"\s+")
|
||||||
|
_PARAGRAPH_SPLIT_REGEX = re.compile(r"(?:\r?\n){2,}")
|
||||||
|
_ABBREVIATION_END_RE = re.compile(
|
||||||
|
r"\b(?:Mr|Mrs|Ms|Dr|Prof|Rev|Sr|Jr|St|Gen|Lt|Col|Sgt|Capt|Adm|Cmdr|vs|etc)\.$",
|
||||||
|
re.IGNORECASE,
|
||||||
|
)
|
||||||
|
|
||||||
|
_PIPELINE_APOSTROPHE_CONFIG = ApostropheConfig()
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class Chunk:
|
||||||
|
id: str
|
||||||
|
chapter_index: int
|
||||||
|
chunk_index: int
|
||||||
|
level: ChunkLevel
|
||||||
|
text: str
|
||||||
|
speaker_id: str = "narrator"
|
||||||
|
voice: Optional[str] = None
|
||||||
|
voice_profile: Optional[str] = None
|
||||||
|
voice_formula: Optional[str] = None
|
||||||
|
display_text: Optional[str] = None
|
||||||
|
|
||||||
|
def as_dict(self) -> Dict[str, object]:
|
||||||
|
return {
|
||||||
|
"id": self.id,
|
||||||
|
"chapter_index": self.chapter_index,
|
||||||
|
"chunk_index": self.chunk_index,
|
||||||
|
"level": self.level,
|
||||||
|
"text": self.text,
|
||||||
|
"speaker_id": self.speaker_id,
|
||||||
|
"voice": self.voice,
|
||||||
|
"voice_profile": self.voice_profile,
|
||||||
|
"voice_formula": self.voice_formula,
|
||||||
|
"display_text": self.display_text,
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def _iter_paragraphs(text: str) -> Iterator[str]:
|
||||||
|
for raw_segment in _PARAGRAPH_SPLIT_REGEX.split(text.strip()):
|
||||||
|
normalized = raw_segment.strip()
|
||||||
|
if normalized:
|
||||||
|
yield normalized
|
||||||
|
|
||||||
|
|
||||||
|
def _iter_sentences(paragraph: str) -> Iterator[Tuple[str, str]]:
|
||||||
|
if not paragraph:
|
||||||
|
return
|
||||||
|
start = 0
|
||||||
|
for match in _SENTENCE_SPLIT_REGEX.finditer(paragraph):
|
||||||
|
end = match.end()
|
||||||
|
raw_segment = paragraph[start:end]
|
||||||
|
candidate = raw_segment.strip()
|
||||||
|
if candidate:
|
||||||
|
yield candidate, raw_segment
|
||||||
|
start = match.end()
|
||||||
|
tail_raw = paragraph[start:]
|
||||||
|
tail = tail_raw.strip()
|
||||||
|
if tail:
|
||||||
|
yield tail, tail_raw
|
||||||
|
|
||||||
|
|
||||||
|
def _normalize_whitespace(value: str) -> str:
|
||||||
|
return _WHITESPACE_REGEX.sub(" ", value).strip()
|
||||||
|
|
||||||
|
|
||||||
|
def _normalize_chunk_text(value: str) -> str:
|
||||||
|
settings = get_runtime_settings()
|
||||||
|
config = build_apostrophe_config(
|
||||||
|
settings=settings, base=_PIPELINE_APOSTROPHE_CONFIG
|
||||||
|
)
|
||||||
|
normalized = normalize_for_pipeline(value, config=config, settings=settings)
|
||||||
|
return _normalize_whitespace(normalized)
|
||||||
|
|
||||||
|
|
||||||
|
def _split_sentences(paragraph: str) -> List[Tuple[str, str]]:
|
||||||
|
sentences = list(_iter_sentences(paragraph))
|
||||||
|
if not sentences:
|
||||||
|
return []
|
||||||
|
|
||||||
|
merged: List[Tuple[str, str]] = []
|
||||||
|
buffer_norm: List[str] = []
|
||||||
|
buffer_raw: List[str] = []
|
||||||
|
|
||||||
|
for normalized_sentence, raw_sentence in sentences:
|
||||||
|
if buffer_norm:
|
||||||
|
buffer_norm.append(normalized_sentence)
|
||||||
|
buffer_raw.append(raw_sentence)
|
||||||
|
else:
|
||||||
|
buffer_norm = [normalized_sentence]
|
||||||
|
buffer_raw = [raw_sentence]
|
||||||
|
|
||||||
|
if _ABBREVIATION_END_RE.search(normalized_sentence.rstrip()):
|
||||||
|
continue
|
||||||
|
|
||||||
|
merged.append((" ".join(buffer_norm), "".join(buffer_raw)))
|
||||||
|
buffer_norm = []
|
||||||
|
buffer_raw = []
|
||||||
|
|
||||||
|
if buffer_norm:
|
||||||
|
merged.append((" ".join(buffer_norm), "".join(buffer_raw)))
|
||||||
|
|
||||||
|
return merged
|
||||||
|
|
||||||
|
|
||||||
|
def chunk_text(
|
||||||
|
*,
|
||||||
|
chapter_index: int,
|
||||||
|
chapter_title: str,
|
||||||
|
text: str,
|
||||||
|
level: ChunkLevel,
|
||||||
|
speaker_id: str = "narrator",
|
||||||
|
voice: Optional[str] = None,
|
||||||
|
voice_profile: Optional[str] = None,
|
||||||
|
voice_formula: Optional[str] = None,
|
||||||
|
chunk_prefix: Optional[str] = None,
|
||||||
|
) -> List[Dict[str, object]]:
|
||||||
|
"""Split text into ordered chunk dictionaries."""
|
||||||
|
|
||||||
|
prefix = chunk_prefix or f"chap{chapter_index:04d}"
|
||||||
|
chunks: List[Dict[str, object]] = []
|
||||||
|
|
||||||
|
if level == "paragraph":
|
||||||
|
paragraphs = list(_iter_paragraphs(text)) or [text.strip()]
|
||||||
|
for para_index, paragraph in enumerate(paragraphs):
|
||||||
|
normalized = _normalize_whitespace(paragraph)
|
||||||
|
if not normalized:
|
||||||
|
continue
|
||||||
|
chunk_id = f"{prefix}_p{para_index:04d}"
|
||||||
|
payload = Chunk(
|
||||||
|
id=chunk_id,
|
||||||
|
chapter_index=chapter_index,
|
||||||
|
chunk_index=len(chunks),
|
||||||
|
level=level,
|
||||||
|
text=normalized,
|
||||||
|
speaker_id=speaker_id,
|
||||||
|
voice=voice,
|
||||||
|
voice_profile=voice_profile,
|
||||||
|
voice_formula=voice_formula,
|
||||||
|
).as_dict()
|
||||||
|
payload["normalized_text"] = _normalize_chunk_text(paragraph)
|
||||||
|
payload["original_text"] = paragraph
|
||||||
|
chunks.append(payload)
|
||||||
|
_attach_display_text(text, chunks)
|
||||||
|
return chunks
|
||||||
|
|
||||||
|
# Sentence level – flatten paragraphs into individual sentences
|
||||||
|
sentence_index = 0
|
||||||
|
for para_index, paragraph in enumerate(
|
||||||
|
list(_iter_paragraphs(text)) or [text.strip()]
|
||||||
|
):
|
||||||
|
normalized_para = _normalize_whitespace(paragraph)
|
||||||
|
if not normalized_para:
|
||||||
|
continue
|
||||||
|
sentence_pairs = _split_sentences(paragraph) or [(normalized_para, paragraph)]
|
||||||
|
for sent_local_index, (normalized_sentence, raw_sentence) in enumerate(
|
||||||
|
sentence_pairs
|
||||||
|
):
|
||||||
|
normalized_sentence = _normalize_whitespace(normalized_sentence)
|
||||||
|
if not normalized_sentence:
|
||||||
|
continue
|
||||||
|
chunk_id = f"{prefix}_p{para_index:04d}_s{sent_local_index:04d}"
|
||||||
|
payload = Chunk(
|
||||||
|
id=chunk_id,
|
||||||
|
chapter_index=chapter_index,
|
||||||
|
chunk_index=sentence_index,
|
||||||
|
level=level,
|
||||||
|
text=normalized_sentence,
|
||||||
|
speaker_id=speaker_id,
|
||||||
|
voice=voice,
|
||||||
|
voice_profile=voice_profile,
|
||||||
|
voice_formula=voice_formula,
|
||||||
|
).as_dict()
|
||||||
|
payload["normalized_text"] = _normalize_chunk_text(raw_sentence)
|
||||||
|
payload["display_text"] = raw_sentence
|
||||||
|
payload["original_text"] = raw_sentence
|
||||||
|
chunks.append(payload)
|
||||||
|
sentence_index += 1
|
||||||
|
|
||||||
|
_attach_display_text(text, chunks)
|
||||||
|
return chunks
|
||||||
|
|
||||||
|
|
||||||
|
_DISPLAY_PATTERN_CACHE: Dict[str, Pattern[str]] = {}
|
||||||
|
|
||||||
|
|
||||||
|
def _build_display_pattern(text: str) -> Pattern[str]:
|
||||||
|
cached = _DISPLAY_PATTERN_CACHE.get(text)
|
||||||
|
if cached is not None:
|
||||||
|
return cached
|
||||||
|
escaped = re.escape(text)
|
||||||
|
escaped = escaped.replace(r"\ ", r"\s+")
|
||||||
|
pattern = re.compile(r"(\s*" + escaped + r"\s*)", re.DOTALL)
|
||||||
|
_DISPLAY_PATTERN_CACHE[text] = pattern
|
||||||
|
return pattern
|
||||||
|
|
||||||
|
|
||||||
|
def _search_source_span(
|
||||||
|
source: str, normalized: str, start: int
|
||||||
|
) -> Optional[Tuple[int, int]]:
|
||||||
|
if not normalized:
|
||||||
|
return None
|
||||||
|
pattern = _build_display_pattern(normalized)
|
||||||
|
match = pattern.search(source, start)
|
||||||
|
if not match:
|
||||||
|
return None
|
||||||
|
return match.start(1), match.end(1)
|
||||||
|
|
||||||
|
|
||||||
|
def _attach_display_text(source: str, chunks: List[Dict[str, object]]) -> None:
|
||||||
|
if not source or not chunks:
|
||||||
|
return
|
||||||
|
cursor = 0
|
||||||
|
for chunk in chunks:
|
||||||
|
candidate = str(chunk.get("display_text") or chunk.get("text") or "")
|
||||||
|
if not candidate:
|
||||||
|
continue
|
||||||
|
match = _search_source_span(source, candidate, cursor)
|
||||||
|
if match is None and cursor:
|
||||||
|
match = _search_source_span(source, candidate, 0)
|
||||||
|
if match is None:
|
||||||
|
chunk.setdefault("display_text", candidate)
|
||||||
|
chunk.setdefault("original_text", chunk.get("display_text") or candidate)
|
||||||
|
continue
|
||||||
|
start, end = match
|
||||||
|
chunk["display_text"] = source[start:end]
|
||||||
|
chunk["original_text"] = source[start:end]
|
||||||
|
cursor = end
|
||||||
|
|
||||||
|
|
||||||
|
def build_chunks_for_chapters(
|
||||||
|
chapters: Iterable[Dict[str, object]],
|
||||||
|
*,
|
||||||
|
level: ChunkLevel,
|
||||||
|
speaker_id: str = "narrator",
|
||||||
|
) -> List[Dict[str, object]]:
|
||||||
|
"""Generate chunk dictionaries for a sequence of chapter payloads."""
|
||||||
|
all_chunks: List[Dict[str, object]] = []
|
||||||
|
for chapter_index, entry in enumerate(chapters):
|
||||||
|
if not isinstance(entry, dict): # defensive
|
||||||
|
continue
|
||||||
|
text = str(entry.get("text", "") or "").strip()
|
||||||
|
if not text:
|
||||||
|
continue
|
||||||
|
voice = entry.get("voice")
|
||||||
|
voice_profile = entry.get("voice_profile")
|
||||||
|
voice_formula = entry.get("voice_formula")
|
||||||
|
prefix = entry.get("id") or f"chap{chapter_index:04d}"
|
||||||
|
chapter_chunks = chunk_text(
|
||||||
|
chapter_index=chapter_index,
|
||||||
|
chapter_title=str(entry.get("title") or f"Chapter {chapter_index + 1}"),
|
||||||
|
text=text,
|
||||||
|
level=level,
|
||||||
|
speaker_id=speaker_id,
|
||||||
|
voice=str(voice) if voice else None,
|
||||||
|
voice_profile=str(voice_profile) if voice_profile else None,
|
||||||
|
voice_formula=str(voice_formula) if voice_formula else None,
|
||||||
|
chunk_prefix=str(prefix),
|
||||||
|
)
|
||||||
|
all_chunks.extend(chapter_chunks)
|
||||||
|
return all_chunks
|
||||||
+31
-75
@@ -1,4 +1,5 @@
|
|||||||
from abogen.utils import get_version
|
from abogen.utils import get_version
|
||||||
|
from abogen.domain.enums import Language
|
||||||
|
|
||||||
# Program Information
|
# Program Information
|
||||||
PROGRAM_NAME = "abogen"
|
PROGRAM_NAME = "abogen"
|
||||||
@@ -16,8 +17,22 @@ SUBTITLE_FORMATS = [
|
|||||||
("ass_centered_narrow", "ASS (centered narrow)"),
|
("ass_centered_narrow", "ASS (centered narrow)"),
|
||||||
]
|
]
|
||||||
|
|
||||||
# Language description mapping
|
# Language description mapping (Language enum → human-readable label).
|
||||||
LANGUAGE_DESCRIPTIONS = {
|
LANGUAGE_DESCRIPTIONS = {
|
||||||
|
Language.EN_US: "American English",
|
||||||
|
Language.EN_GB: "British English",
|
||||||
|
Language.ES: "Spanish",
|
||||||
|
Language.FR: "French",
|
||||||
|
Language.HI: "Hindi",
|
||||||
|
Language.IT: "Italian",
|
||||||
|
Language.JA: "Japanese",
|
||||||
|
Language.PT_BR: "Brazilian Portuguese",
|
||||||
|
Language.ZH: "Mandarin Chinese",
|
||||||
|
}
|
||||||
|
|
||||||
|
# Display-only mapping for kokoro codes → labels.
|
||||||
|
# Used by voice catalog and PyQt (legacy) where kokoro codes are still present.
|
||||||
|
KOKORO_CODE_LABELS = {
|
||||||
"a": "American English",
|
"a": "American English",
|
||||||
"b": "British English",
|
"b": "British English",
|
||||||
"e": "Spanish",
|
"e": "Spanish",
|
||||||
@@ -55,83 +70,24 @@ SUPPORTED_INPUT_FORMATS = [
|
|||||||
"vtt",
|
"vtt",
|
||||||
]
|
]
|
||||||
|
|
||||||
# Supported languages for subtitle generation
|
# Supported languages for subtitle generation.
|
||||||
# Currently, only 'a (American English)' and 'b (British English)' are supported for subtitle generation.
|
# All languages are supported: only English emits per-word timestamped tokens
|
||||||
# This is because tokens that contain timestamps are not generated for other languages in the Kokoro pipeline.
|
# in the Kokoro pipeline, but other languages fall back to segment-level fake
|
||||||
# Please refer to: https://github.com/hexgrad/kokoro/blob/6d87f4ae7abc2d14dbc4b3ef2e5f19852e861ac2/kokoro/pipeline.py
|
# tokens (see abogen.domain.tokens.FakeToken), so subtitles are still
|
||||||
# 383 English processing (unchanged)
|
# generated at segment granularity.
|
||||||
# 384 if self.lang_code in 'ab':
|
SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION = list(Language)
|
||||||
SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION = list(LANGUAGE_DESCRIPTIONS.keys())
|
|
||||||
|
|
||||||
# Voice and sample text constants
|
|
||||||
VOICES_INTERNAL = [
|
|
||||||
"af_alloy",
|
|
||||||
"af_aoede",
|
|
||||||
"af_bella",
|
|
||||||
"af_heart",
|
|
||||||
"af_jessica",
|
|
||||||
"af_kore",
|
|
||||||
"af_nicole",
|
|
||||||
"af_nova",
|
|
||||||
"af_river",
|
|
||||||
"af_sarah",
|
|
||||||
"af_sky",
|
|
||||||
"am_adam",
|
|
||||||
"am_echo",
|
|
||||||
"am_eric",
|
|
||||||
"am_fenrir",
|
|
||||||
"am_liam",
|
|
||||||
"am_michael",
|
|
||||||
"am_onyx",
|
|
||||||
"am_puck",
|
|
||||||
"am_santa",
|
|
||||||
"bf_alice",
|
|
||||||
"bf_emma",
|
|
||||||
"bf_isabella",
|
|
||||||
"bf_lily",
|
|
||||||
"bm_daniel",
|
|
||||||
"bm_fable",
|
|
||||||
"bm_george",
|
|
||||||
"bm_lewis",
|
|
||||||
"ef_dora",
|
|
||||||
"em_alex",
|
|
||||||
"em_santa",
|
|
||||||
"ff_siwis",
|
|
||||||
"hf_alpha",
|
|
||||||
"hf_beta",
|
|
||||||
"hm_omega",
|
|
||||||
"hm_psi",
|
|
||||||
"if_sara",
|
|
||||||
"im_nicola",
|
|
||||||
"jf_alpha",
|
|
||||||
"jf_gongitsune",
|
|
||||||
"jf_nezumi",
|
|
||||||
"jf_tebukuro",
|
|
||||||
"jm_kumo",
|
|
||||||
"pf_dora",
|
|
||||||
"pm_alex",
|
|
||||||
"pm_santa",
|
|
||||||
"zf_xiaobei",
|
|
||||||
"zf_xiaoni",
|
|
||||||
"zf_xiaoxiao",
|
|
||||||
"zf_xiaoyi",
|
|
||||||
"zm_yunjian",
|
|
||||||
"zm_yunxi",
|
|
||||||
"zm_yunxia",
|
|
||||||
"zm_yunyang",
|
|
||||||
]
|
|
||||||
|
|
||||||
# Voice and sample text mapping
|
# Voice and sample text mapping
|
||||||
SAMPLE_VOICE_TEXTS = {
|
SAMPLE_VOICE_TEXTS = {
|
||||||
"a": "This is a sample of the selected voice.",
|
Language.EN_US: "This is a sample of the selected voice.",
|
||||||
"b": "This is a sample of the selected voice.",
|
Language.EN_GB: "This is a sample of the selected voice.",
|
||||||
"e": "Este es una muestra de la voz seleccionada.",
|
Language.ES: "Este es una muestra de la voz seleccionada.",
|
||||||
"f": "Ceci est un exemple de la voix sélectionnée.",
|
Language.FR: "Ceci est un exemple de la voix sélectionnée.",
|
||||||
"h": "यह चयनित आवाज़ का एक नमूना है।",
|
Language.HI: "यह चयनित आवाज़ का एक नमूना है।",
|
||||||
"i": "Questo è un esempio della voce selezionata.",
|
Language.IT: "Questo è un esempio della voce selezionata.",
|
||||||
"j": "これは選択した声のサンプルです。",
|
Language.JA: "これは選択した声のサンプルです。",
|
||||||
"p": "Este é um exemplo da voz selecionada.",
|
Language.PT_BR: "Este é um exemplo da voz selecionada.",
|
||||||
"z": "这是所选语音的示例。",
|
Language.ZH: "这是所选语音的示例。",
|
||||||
}
|
}
|
||||||
|
|
||||||
COLORS = {
|
COLORS = {
|
||||||
|
|||||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,390 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import tempfile
|
||||||
|
import zipfile
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Iterable, List, Sequence
|
||||||
|
|
||||||
|
|
||||||
|
MARKER_PREFIX = "[[ABOGEN-DBG:"
|
||||||
|
MARKER_SUFFIX = "]]"
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class DebugTTSSample:
|
||||||
|
code: str
|
||||||
|
label: str
|
||||||
|
text: str
|
||||||
|
|
||||||
|
|
||||||
|
DEBUG_TTS_SAMPLES: Sequence[DebugTTSSample] = (
|
||||||
|
DebugTTSSample(
|
||||||
|
code="APOS_001",
|
||||||
|
label="Apostrophes & contractions (1)",
|
||||||
|
text="It's a beautiful day, isn't it? Let's see what we'll do.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="APOS_002",
|
||||||
|
label="Apostrophes & contractions (2)",
|
||||||
|
text="I'm sure you're ready; we'd better go before it's too late.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="APOS_003",
|
||||||
|
label="Apostrophes & contractions (3)",
|
||||||
|
text="He'll say it's fine, but I can't promise it'll work.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="APOS_004",
|
||||||
|
label="Apostrophes & contractions (4)",
|
||||||
|
text="They've done it, and I'd agree they've earned it.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="APOS_005",
|
||||||
|
label="Apostrophes & contractions (5)",
|
||||||
|
text="She's here, we're late, they're waiting, and you're right.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="POS_001",
|
||||||
|
label="Plural possessives (1)",
|
||||||
|
text="The dogs' bowls were empty, but the boss's office was quiet.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="POS_002",
|
||||||
|
label="Plural possessives (2)",
|
||||||
|
text="The teachers' lounge was closed during the students' exams.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="POS_003",
|
||||||
|
label="Plural possessives (3)",
|
||||||
|
text="The actresses' roles changed, and the directors' notes piled up.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="POS_004",
|
||||||
|
label="Plural possessives (4)",
|
||||||
|
text="The Joneses' car was parked by the neighbors' fence.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="POS_005",
|
||||||
|
label="Plural possessives (5)",
|
||||||
|
text="The bosses' meeting ended before the witnesses' statements began.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="NUM_001",
|
||||||
|
label="Grouped numbers (1)",
|
||||||
|
text="There are 1,234 apples, 56 oranges, and 7.89 liters of juice.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="NUM_002",
|
||||||
|
label="Grouped numbers (2)",
|
||||||
|
text="The population is 10,000,000 and the area is 123.45 square miles.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="NUM_003",
|
||||||
|
label="Grouped numbers (3)",
|
||||||
|
text="Set the timer for 0.5 seconds, then wait 2.0 minutes.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="NUM_004",
|
||||||
|
label="Grouped numbers (4)",
|
||||||
|
text="We measured 3.1415 radians and wrote down 2,718.28 as well.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="NUM_005",
|
||||||
|
label="Grouped numbers (5)",
|
||||||
|
text="The sequence is 1, 2, 3, 4, 5, and then 13.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="YEAR_001",
|
||||||
|
label="Years and decades (1)",
|
||||||
|
text="In 1999, people said the '90s were over.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="YEAR_002",
|
||||||
|
label="Years and decades (2)",
|
||||||
|
text="In 2001, the show premiered; by 2010 it was everywhere.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="YEAR_003",
|
||||||
|
label="Years and decades (3)",
|
||||||
|
text="The 1980s were loud, and the 1970s were groovy.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="YEAR_004",
|
||||||
|
label="Years and decades (4)",
|
||||||
|
text="She loved the '80s, but he preferred the '60s.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="YEAR_005",
|
||||||
|
label="Years and decades (5)",
|
||||||
|
text="In 2024, we looked back at 2020 and planned for 2030.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="DATE_001",
|
||||||
|
label="Dates (1)",
|
||||||
|
text="On 2023-01-01, we celebrated the new year.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="DATE_002",
|
||||||
|
label="Dates (2)",
|
||||||
|
text="The deadline is 1999-12-31 at midnight.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="DATE_003",
|
||||||
|
label="Dates (3)",
|
||||||
|
text="Leap day happens on 2024-02-29.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="DATE_004",
|
||||||
|
label="Dates (4)",
|
||||||
|
text="Some formats look like 01/02/2003 and can be ambiguous.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="DATE_005",
|
||||||
|
label="Dates (5)",
|
||||||
|
text="We met on March 5, 2020 and again on Apr. 7, 2021.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="CUR_001",
|
||||||
|
label="Currency symbols (1)",
|
||||||
|
text="The price is $10.50, but it was £8.00 yesterday.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="CUR_002",
|
||||||
|
label="Currency symbols (2)",
|
||||||
|
text="Tickets cost €12, and the fine was $0.99.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="CUR_003",
|
||||||
|
label="Currency symbols (3)",
|
||||||
|
text="The bill was ¥500 and the refund was $-3.25.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="CUR_004",
|
||||||
|
label="Currency symbols (4)",
|
||||||
|
text="He paid £1,234.56 for the instrument.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="CUR_005",
|
||||||
|
label="Currency symbols (5)",
|
||||||
|
text="The subscription is $5 per month, or $50 per year.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="TITLE_001",
|
||||||
|
label="Titles and abbreviations (1)",
|
||||||
|
text="Dr. Smith lives on Elm St. near the U.S. border.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="TITLE_002",
|
||||||
|
label="Titles and abbreviations (2)",
|
||||||
|
text="Mr. and Mrs. Doe met Prof. Adams at 5 p.m.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="TITLE_003",
|
||||||
|
label="Titles and abbreviations (3)",
|
||||||
|
text="Gen. Smith spoke to Sgt. Rivera on Main St.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="TITLE_004",
|
||||||
|
label="Titles and abbreviations (4)",
|
||||||
|
text="The report came from the U.K. office, not the U.S.A. team.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="TITLE_005",
|
||||||
|
label="Titles and abbreviations (5)",
|
||||||
|
text="St. John's is different from St. Louis.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="PUNC_001",
|
||||||
|
label="Terminal punctuation (1)",
|
||||||
|
text="This sentence ends without punctuation",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="PUNC_002",
|
||||||
|
label="Terminal punctuation (2)",
|
||||||
|
text="An ellipsis is already present...",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="PUNC_003",
|
||||||
|
label="Terminal punctuation (3)",
|
||||||
|
text="A question without a mark",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="PUNC_004",
|
||||||
|
label="Terminal punctuation (4)",
|
||||||
|
text="An exclamation without a bang",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="PUNC_005",
|
||||||
|
label="Terminal punctuation (5)",
|
||||||
|
text='A quote ends here"',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="QUOTE_001",
|
||||||
|
label="ALL CAPS inside quotes (1)",
|
||||||
|
text='He shouted, "THIS IS IMPORTANT!" and then whispered, "ok."',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="QUOTE_002",
|
||||||
|
label="ALL CAPS inside quotes (2)",
|
||||||
|
text='She said, "NO WAY", but he replied, "maybe".',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="QUOTE_003",
|
||||||
|
label="ALL CAPS inside quotes (3)",
|
||||||
|
text='The sign read "DO NOT ENTER" and the note read "pls knock".',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="QUOTE_004",
|
||||||
|
label="ALL CAPS inside quotes (4)",
|
||||||
|
text='He muttered, "OK", then yelled, "STOP!"',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="QUOTE_005",
|
||||||
|
label="ALL CAPS inside quotes (5)",
|
||||||
|
text='They chanted, "USA!" and someone wrote "idk".',
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="FOOT_001",
|
||||||
|
label="Footnote indicators (1)",
|
||||||
|
text="This is a sentence with a footnote[1] and another[12].",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="FOOT_002",
|
||||||
|
label="Footnote indicators (2)",
|
||||||
|
text="Some books use multiple footnotes like this[2][3] in a row.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="FOOT_003",
|
||||||
|
label="Footnote indicators (3)",
|
||||||
|
text="A footnote can appear mid-sentence[4] and continue afterward.",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="FOOT_004",
|
||||||
|
label="Footnote indicators (4)",
|
||||||
|
text="Edge cases include [0] or very large indices like [1234].",
|
||||||
|
),
|
||||||
|
DebugTTSSample(
|
||||||
|
code="FOOT_005",
|
||||||
|
label="Footnote indicators (5)",
|
||||||
|
text="Sometimes a footnote follows punctuation.[5] Sometimes it doesn't[6]",
|
||||||
|
),
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def marker_for(code: str) -> str:
|
||||||
|
return f"{MARKER_PREFIX}{code}{MARKER_SUFFIX}"
|
||||||
|
|
||||||
|
|
||||||
|
def build_debug_epub(dest_path: Path, *, title: str = "abogen debug samples") -> Path:
|
||||||
|
"""Create a tiny EPUB containing all debug samples.
|
||||||
|
|
||||||
|
The text includes stable marker codes so developers can report failures
|
||||||
|
precisely.
|
||||||
|
"""
|
||||||
|
|
||||||
|
dest_path = Path(dest_path)
|
||||||
|
dest_path.parent.mkdir(parents=True, exist_ok=True)
|
||||||
|
|
||||||
|
chapter_lines: List[str] = [
|
||||||
|
'<?xml version="1.0" encoding="utf-8"?>',
|
||||||
|
"<!DOCTYPE html>",
|
||||||
|
'<html xmlns="http://www.w3.org/1999/xhtml">',
|
||||||
|
"<head>",
|
||||||
|
f" <title>{title}</title>",
|
||||||
|
' <meta charset="utf-8" />',
|
||||||
|
"</head>",
|
||||||
|
"<body>",
|
||||||
|
f" <h1>{title}</h1>",
|
||||||
|
" <p>Each paragraph begins with a stable debug code marker.</p>",
|
||||||
|
]
|
||||||
|
|
||||||
|
for sample in DEBUG_TTS_SAMPLES:
|
||||||
|
safe_label = sample.label.replace("&", "and")
|
||||||
|
chapter_lines.append(f" <h2>{safe_label}</h2>")
|
||||||
|
chapter_lines.append(
|
||||||
|
" <p><strong>"
|
||||||
|
+ marker_for(sample.code)
|
||||||
|
+ "</strong> "
|
||||||
|
+ sample.text
|
||||||
|
+ "</p>"
|
||||||
|
)
|
||||||
|
|
||||||
|
chapter_lines += ["</body>", "</html>"]
|
||||||
|
chapter_xhtml = "\n".join(chapter_lines)
|
||||||
|
|
||||||
|
container_xml = """<?xml version="1.0" encoding="UTF-8"?>
|
||||||
|
<container version="1.0" xmlns="urn:oasis:names:tc:opendocument:xmlns:container">
|
||||||
|
<rootfiles>
|
||||||
|
<rootfile full-path="OEBPS/content.opf" media-type="application/oebps-package+xml"/>
|
||||||
|
</rootfiles>
|
||||||
|
</container>
|
||||||
|
"""
|
||||||
|
|
||||||
|
content_opf = """<?xml version="1.0" encoding="utf-8"?>
|
||||||
|
<package xmlns="http://www.idpf.org/2007/opf" unique-identifier="bookid" version="3.0">
|
||||||
|
<metadata xmlns:dc="http://purl.org/dc/elements/1.1/">
|
||||||
|
<dc:identifier id="bookid">abogen-debug-samples</dc:identifier>
|
||||||
|
<dc:title>abogen debug samples</dc:title>
|
||||||
|
<dc:language>en</dc:language>
|
||||||
|
</metadata>
|
||||||
|
<manifest>
|
||||||
|
<item id="chapter" href="chapter.xhtml" media-type="application/xhtml+xml" />
|
||||||
|
<item id="nav" href="nav.xhtml" media-type="application/xhtml+xml" properties="nav" />
|
||||||
|
</manifest>
|
||||||
|
<spine>
|
||||||
|
<itemref idref="chapter" />
|
||||||
|
</spine>
|
||||||
|
</package>
|
||||||
|
"""
|
||||||
|
|
||||||
|
nav_xhtml = """<?xml version="1.0" encoding="utf-8"?>
|
||||||
|
<!DOCTYPE html>
|
||||||
|
<html xmlns="http://www.w3.org/1999/xhtml">
|
||||||
|
<head>
|
||||||
|
<title>Navigation</title>
|
||||||
|
<meta charset="utf-8" />
|
||||||
|
</head>
|
||||||
|
<body>
|
||||||
|
<nav epub:type="toc" id="toc">
|
||||||
|
<h2>Table of Contents</h2>
|
||||||
|
<ol>
|
||||||
|
<li><a href="chapter.xhtml">Debug samples</a></li>
|
||||||
|
</ol>
|
||||||
|
</nav>
|
||||||
|
</body>
|
||||||
|
</html>
|
||||||
|
"""
|
||||||
|
|
||||||
|
with tempfile.TemporaryDirectory() as tmp:
|
||||||
|
tmp_path = Path(tmp)
|
||||||
|
(tmp_path / "mimetype").write_text("application/epub+zip", encoding="utf-8")
|
||||||
|
meta_inf = tmp_path / "META-INF"
|
||||||
|
meta_inf.mkdir(parents=True, exist_ok=True)
|
||||||
|
(meta_inf / "container.xml").write_text(container_xml, encoding="utf-8")
|
||||||
|
oebps = tmp_path / "OEBPS"
|
||||||
|
oebps.mkdir(parents=True, exist_ok=True)
|
||||||
|
(oebps / "content.opf").write_text(content_opf, encoding="utf-8")
|
||||||
|
(oebps / "chapter.xhtml").write_text(chapter_xhtml, encoding="utf-8")
|
||||||
|
(oebps / "nav.xhtml").write_text(nav_xhtml, encoding="utf-8")
|
||||||
|
|
||||||
|
# Per EPUB spec: mimetype must be the first entry and stored (no compression).
|
||||||
|
with zipfile.ZipFile(dest_path, "w") as zf:
|
||||||
|
zf.write(
|
||||||
|
tmp_path / "mimetype", "mimetype", compress_type=zipfile.ZIP_STORED
|
||||||
|
)
|
||||||
|
for source in (
|
||||||
|
meta_inf / "container.xml",
|
||||||
|
oebps / "content.opf",
|
||||||
|
oebps / "chapter.xhtml",
|
||||||
|
oebps / "nav.xhtml",
|
||||||
|
):
|
||||||
|
arcname = str(source.relative_to(tmp_path)).replace("\\", "/")
|
||||||
|
zf.write(source, arcname, compress_type=zipfile.ZIP_DEFLATED)
|
||||||
|
|
||||||
|
return dest_path
|
||||||
|
|
||||||
|
|
||||||
|
def iter_expected_codes() -> Iterable[str]:
|
||||||
|
for sample in DEBUG_TTS_SAMPLES:
|
||||||
|
yield sample.code
|
||||||
@@ -0,0 +1,239 @@
|
|||||||
|
"""Audio buffer operations for audiobook generation.
|
||||||
|
|
||||||
|
This module provides core audio buffer manipulation functions including:
|
||||||
|
- Silence generation
|
||||||
|
- Audio mixing
|
||||||
|
- Audio normalization
|
||||||
|
- Audio buffer resizing
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Optional
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
|
||||||
|
# Standard sample rate used throughout the application
|
||||||
|
SAMPLE_RATE = 24000
|
||||||
|
|
||||||
|
|
||||||
|
def create_silence(duration_seconds: float) -> np.ndarray:
|
||||||
|
"""Create a silence audio buffer.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
duration_seconds: Duration of silence in seconds.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Numpy array of float32 zeros with length = duration_seconds * SAMPLE_RATE.
|
||||||
|
Returns empty array if duration is <= 0.
|
||||||
|
"""
|
||||||
|
if duration_seconds <= 0:
|
||||||
|
return np.array([], dtype="float32")
|
||||||
|
|
||||||
|
samples = int(round(duration_seconds * SAMPLE_RATE))
|
||||||
|
if samples <= 0:
|
||||||
|
return np.array([], dtype="float32")
|
||||||
|
|
||||||
|
return np.zeros(samples, dtype="float32")
|
||||||
|
|
||||||
|
|
||||||
|
def mix_audio(
|
||||||
|
target: np.ndarray,
|
||||||
|
source: np.ndarray,
|
||||||
|
start_sample: int,
|
||||||
|
end_sample: Optional[int] = None,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Mix source audio into target buffer at specified position.
|
||||||
|
|
||||||
|
This performs additive mixing (target += source). The target buffer
|
||||||
|
is extended if necessary to accommodate the source audio.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
target: The target audio buffer to mix into.
|
||||||
|
source: The source audio buffer to mix.
|
||||||
|
start_sample: Starting sample index in target buffer.
|
||||||
|
end_sample: Optional end sample index. If None, calculated from source length.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
The target buffer (possibly extended). If target was extended, returns new array.
|
||||||
|
"""
|
||||||
|
if source.size == 0:
|
||||||
|
return target
|
||||||
|
|
||||||
|
if end_sample is None:
|
||||||
|
end_sample = start_sample + len(source)
|
||||||
|
|
||||||
|
# Extend target buffer if needed
|
||||||
|
if end_sample > len(target):
|
||||||
|
new_length = end_sample
|
||||||
|
new_target = np.concatenate([
|
||||||
|
target,
|
||||||
|
np.zeros(new_length - len(target), dtype="float32")
|
||||||
|
])
|
||||||
|
target = new_target
|
||||||
|
|
||||||
|
# Perform the mix (additive)
|
||||||
|
target[start_sample:end_sample] += source
|
||||||
|
return target
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_audio(
|
||||||
|
audio: np.ndarray,
|
||||||
|
target_peak: float = 1.0,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Normalize audio buffer to prevent clipping.
|
||||||
|
|
||||||
|
If the audio exceeds the target peak (default 1.0), it is scaled down
|
||||||
|
proportionally to prevent distortion.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
audio: Input audio buffer.
|
||||||
|
target_peak: Target maximum amplitude (default 1.0).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Normalized audio buffer (new array, original is not modified).
|
||||||
|
"""
|
||||||
|
if audio.size == 0:
|
||||||
|
return audio.copy()
|
||||||
|
|
||||||
|
max_amplitude = float(np.abs(audio).max())
|
||||||
|
|
||||||
|
if max_amplitude <= target_peak:
|
||||||
|
return audio.copy()
|
||||||
|
|
||||||
|
# Scale down to prevent clipping
|
||||||
|
scale_factor = target_peak / max_amplitude
|
||||||
|
return (audio * scale_factor).astype("float32")
|
||||||
|
|
||||||
|
|
||||||
|
def ensure_buffer_size(
|
||||||
|
buffer: np.ndarray,
|
||||||
|
min_samples: int,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Ensure audio buffer is at least min_samples long.
|
||||||
|
|
||||||
|
If buffer is shorter, it is extended with zeros.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
buffer: Input audio buffer.
|
||||||
|
min_samples: Minimum required length in samples.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Buffer of at least min_samples length (new array if extended).
|
||||||
|
"""
|
||||||
|
if len(buffer) >= min_samples:
|
||||||
|
return buffer
|
||||||
|
|
||||||
|
new_buffer = np.zeros(min_samples, dtype="float32")
|
||||||
|
new_buffer[:len(buffer)] = buffer
|
||||||
|
return new_buffer
|
||||||
|
|
||||||
|
|
||||||
|
def concatenate_audio(*buffers: np.ndarray) -> np.ndarray:
|
||||||
|
"""Concatenate multiple audio buffers.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
*buffers: Audio buffers to concatenate.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Single concatenated audio buffer.
|
||||||
|
"""
|
||||||
|
non_empty = [b for b in buffers if b.size > 0]
|
||||||
|
if not non_empty:
|
||||||
|
return np.array([], dtype="float32")
|
||||||
|
return np.concatenate(non_empty)
|
||||||
|
|
||||||
|
|
||||||
|
def audio_duration(audio: np.ndarray, sample_rate: int = SAMPLE_RATE) -> float:
|
||||||
|
"""Calculate duration of audio buffer in seconds.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
audio: Audio buffer.
|
||||||
|
sample_rate: Sample rate in Hz (default SAMPLE_RATE).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Duration in seconds.
|
||||||
|
"""
|
||||||
|
return len(audio) / sample_rate
|
||||||
|
|
||||||
|
|
||||||
|
def samples_for_duration(duration_seconds: float, sample_rate: int = SAMPLE_RATE) -> int:
|
||||||
|
"""Calculate number of samples for a given duration.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
duration_seconds: Duration in seconds.
|
||||||
|
sample_rate: Sample rate in Hz (default SAMPLE_RATE).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Number of samples (rounded to nearest integer), or 0 if duration is <= 0.
|
||||||
|
"""
|
||||||
|
if duration_seconds <= 0:
|
||||||
|
return 0
|
||||||
|
return int(round(duration_seconds * sample_rate))
|
||||||
|
|
||||||
|
|
||||||
|
def fit_audio_to_duration(
|
||||||
|
audio: np.ndarray,
|
||||||
|
target_duration: float,
|
||||||
|
sample_rate: int = SAMPLE_RATE,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Pad or trim audio to match target duration.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
audio: Input audio buffer.
|
||||||
|
target_duration: Desired duration in seconds.
|
||||||
|
sample_rate: Sample rate in Hz.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Audio buffer of exact length target_duration * sample_rate.
|
||||||
|
"""
|
||||||
|
target_samples = int(target_duration * sample_rate)
|
||||||
|
if len(audio) < target_samples:
|
||||||
|
padding = np.zeros(target_samples - len(audio), dtype="float32")
|
||||||
|
return np.concatenate([audio, padding])
|
||||||
|
return audio[:target_samples]
|
||||||
|
|
||||||
|
|
||||||
|
def ffmpeg_time_stretch(
|
||||||
|
audio: np.ndarray,
|
||||||
|
speed_factor: float,
|
||||||
|
sample_rate: int = SAMPLE_RATE,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Time-stretch audio using FFmpeg's atempo filter.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
audio: Input audio buffer (float32).
|
||||||
|
speed_factor: Speed multiplier (>1.0 = faster).
|
||||||
|
sample_rate: Sample rate in Hz.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Time-stretched audio buffer.
|
||||||
|
"""
|
||||||
|
import math
|
||||||
|
import subprocess
|
||||||
|
|
||||||
|
import static_ffmpeg
|
||||||
|
|
||||||
|
if speed_factor <= 1.0 or audio.size == 0:
|
||||||
|
return audio
|
||||||
|
|
||||||
|
static_ffmpeg.add_paths()
|
||||||
|
num_stages = max(1, int(math.ceil(math.log(speed_factor) / math.log(2.0))))
|
||||||
|
tempo = speed_factor ** (1.0 / num_stages)
|
||||||
|
filter_str = ",".join([f"atempo={tempo:.6f}"] * num_stages)
|
||||||
|
|
||||||
|
proc = subprocess.Popen(
|
||||||
|
[
|
||||||
|
"ffmpeg", "-y",
|
||||||
|
"-f", "f32le", "-ar", str(sample_rate), "-ac", "1",
|
||||||
|
"-i", "pipe:0",
|
||||||
|
"-filter:a", filter_str,
|
||||||
|
"-f", "f32le", "-ar", str(sample_rate), "-ac", "1",
|
||||||
|
"pipe:1",
|
||||||
|
],
|
||||||
|
stdin=subprocess.PIPE,
|
||||||
|
stdout=subprocess.PIPE,
|
||||||
|
stderr=subprocess.PIPE,
|
||||||
|
)
|
||||||
|
out, _ = proc.communicate(input=audio.tobytes())
|
||||||
|
return np.frombuffer(out, dtype="float32")
|
||||||
@@ -0,0 +1,118 @@
|
|||||||
|
"""Audio helper utilities.
|
||||||
|
|
||||||
|
Functions for building ffmpeg commands, converting audio formats,
|
||||||
|
and applying chapter metadata to MP4 files.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
|
||||||
|
|
||||||
|
SAMPLE_RATE = 24000
|
||||||
|
|
||||||
|
|
||||||
|
def build_ffmpeg_command(path: Path, fmt: str, metadata: Optional[Dict[str, str]] = None) -> list[str]:
|
||||||
|
from abogen.infrastructure.exporters import ExportService
|
||||||
|
|
||||||
|
base = [
|
||||||
|
"ffmpeg",
|
||||||
|
"-y",
|
||||||
|
"-f",
|
||||||
|
"f32le",
|
||||||
|
"-ar",
|
||||||
|
str(SAMPLE_RATE),
|
||||||
|
"-ac",
|
||||||
|
"1",
|
||||||
|
"-i",
|
||||||
|
"pipe:0",
|
||||||
|
]
|
||||||
|
if fmt == "mp3":
|
||||||
|
base += ["-c:a", "libmp3lame", "-qscale:a", "2"]
|
||||||
|
elif fmt == "opus":
|
||||||
|
base += ["-c:a", "libopus", "-b:a", "128000"]
|
||||||
|
elif fmt == "m4b":
|
||||||
|
base += ["-c:a", "aac", "-q:a", "2", "-movflags", "+faststart+use_metadata_tags"]
|
||||||
|
else:
|
||||||
|
base += ["-c:a", "copy"]
|
||||||
|
|
||||||
|
if metadata:
|
||||||
|
svc = ExportService()
|
||||||
|
base.extend(svc._metadata_to_ffmpeg_args(metadata))
|
||||||
|
base.append(str(path))
|
||||||
|
return base
|
||||||
|
|
||||||
|
|
||||||
|
def to_float32(audio_segment) -> np.ndarray:
|
||||||
|
if audio_segment is None:
|
||||||
|
return np.zeros(0, dtype="float32")
|
||||||
|
|
||||||
|
tensor = audio_segment
|
||||||
|
if hasattr(tensor, "detach"):
|
||||||
|
tensor = tensor.detach()
|
||||||
|
if hasattr(tensor, "cpu"):
|
||||||
|
try:
|
||||||
|
tensor = tensor.cpu()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
if hasattr(tensor, "numpy"):
|
||||||
|
return np.asarray(tensor.numpy(), dtype="float32").reshape(-1)
|
||||||
|
return np.asarray(tensor, dtype="float32").reshape(-1)
|
||||||
|
|
||||||
|
|
||||||
|
def apply_m4b_chapters_with_mutagen(
|
||||||
|
audio_path: Path,
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
) -> bool:
|
||||||
|
"""Apply chapter atoms to an MP4/M4B file using mutagen.
|
||||||
|
|
||||||
|
Returns True if chapters were written, False otherwise.
|
||||||
|
Raises ImportError if mutagen is not installed.
|
||||||
|
"""
|
||||||
|
if not chapters:
|
||||||
|
return False
|
||||||
|
|
||||||
|
from fractions import Fraction
|
||||||
|
from mutagen.mp4 import MP4, MP4Chapter # type: ignore[import]
|
||||||
|
|
||||||
|
mp4 = MP4(str(audio_path))
|
||||||
|
|
||||||
|
chapter_objects: List[MP4Chapter] = []
|
||||||
|
for index, entry in enumerate(sorted(chapters, key=lambda item: float(item.get("start") or 0.0))):
|
||||||
|
start_raw = entry.get("start")
|
||||||
|
if start_raw is None:
|
||||||
|
continue
|
||||||
|
try:
|
||||||
|
start_seconds = max(0.0, float(start_raw))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
continue
|
||||||
|
|
||||||
|
title_value = entry.get("title")
|
||||||
|
title_text = str(title_value) if title_value else f"Chapter {index + 1}"
|
||||||
|
|
||||||
|
start_fraction = Fraction(int(round(start_seconds * 1000)), 1000)
|
||||||
|
chapter_atom = MP4Chapter(start_fraction, title_text)
|
||||||
|
|
||||||
|
end_raw = entry.get("end")
|
||||||
|
if end_raw is not None:
|
||||||
|
try:
|
||||||
|
end_seconds = float(end_raw)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
end_seconds = None
|
||||||
|
if end_seconds is not None and end_seconds > start_seconds:
|
||||||
|
chapter_atom.end = Fraction(int(round(end_seconds * 1000)), 1000)
|
||||||
|
|
||||||
|
chapter_objects.append(chapter_atom)
|
||||||
|
|
||||||
|
if not chapter_objects:
|
||||||
|
return False
|
||||||
|
|
||||||
|
from typing import cast
|
||||||
|
|
||||||
|
mp4.chapters = cast(Any, chapter_objects)
|
||||||
|
mp4.save()
|
||||||
|
|
||||||
|
return True
|
||||||
@@ -0,0 +1,131 @@
|
|||||||
|
"""Audio sink abstraction for unified audio output.
|
||||||
|
|
||||||
|
Provides a context-manager-based abstraction for writing audio data
|
||||||
|
to various output formats (WAV, FLAC via soundfile; compressed via ffmpeg).
|
||||||
|
|
||||||
|
Usage:
|
||||||
|
with open_audio_sink(path, "wav") as sink:
|
||||||
|
sink.write(audio_data)
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import os
|
||||||
|
import subprocess
|
||||||
|
import sys
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Callable, Optional
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
|
||||||
|
from abogen.domain.audio_buffer import SAMPLE_RATE
|
||||||
|
from abogen.domain.audio_helpers import build_ffmpeg_command
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class AudioSink:
|
||||||
|
"""Represents an open audio output target."""
|
||||||
|
|
||||||
|
write: Callable[[np.ndarray], None]
|
||||||
|
close: Callable[[], None]
|
||||||
|
|
||||||
|
def __enter__(self) -> AudioSink:
|
||||||
|
return self
|
||||||
|
|
||||||
|
def __exit__(self, exc_type, exc_val, exc_tb) -> None:
|
||||||
|
self.close()
|
||||||
|
|
||||||
|
|
||||||
|
def _ensure_ffmpeg() -> None:
|
||||||
|
"""Ensure static ffmpeg binaries are on PATH."""
|
||||||
|
import static_ffmpeg # type: ignore
|
||||||
|
|
||||||
|
ffmpeg_cache_root = _get_ffmpeg_cache_root()
|
||||||
|
platform_cache = os.path.join(ffmpeg_cache_root, sys.platform)
|
||||||
|
os.makedirs(platform_cache, exist_ok=True)
|
||||||
|
try:
|
||||||
|
import static_ffmpeg.run as static_ffmpeg_run # type: ignore
|
||||||
|
|
||||||
|
static_ffmpeg_run.LOCK_FILE = os.path.join(ffmpeg_cache_root, "lock.file")
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
static_ffmpeg.add_paths(weak=True, download_dir=platform_cache)
|
||||||
|
|
||||||
|
|
||||||
|
def _get_ffmpeg_cache_root() -> str:
|
||||||
|
from abogen.utils import get_internal_cache_path
|
||||||
|
|
||||||
|
return get_internal_cache_path("ffmpeg")
|
||||||
|
|
||||||
|
|
||||||
|
def open_audio_sink(
|
||||||
|
path: Path,
|
||||||
|
fmt: str,
|
||||||
|
*,
|
||||||
|
metadata: Optional[dict[str, str]] = None,
|
||||||
|
cancel_check: Optional[Callable[[], bool]] = None,
|
||||||
|
extra_ffmpeg_args: Optional[list[str]] = None,
|
||||||
|
ffmpeg_cmd: Optional[list[str]] = None,
|
||||||
|
) -> AudioSink:
|
||||||
|
"""Open an audio output sink for writing raw float32 PCM samples.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
path: Output file path.
|
||||||
|
fmt: Output format ("wav", "flac", "mp3", "opus", "m4b").
|
||||||
|
metadata: Optional metadata dict (ignored when ffmpeg_cmd is provided).
|
||||||
|
cancel_check: Optional callable; if it returns True, writes are silently skipped.
|
||||||
|
extra_ffmpeg_args: Optional extra args inserted after ffmpeg header (ignored when ffmpeg_cmd is provided).
|
||||||
|
ffmpeg_cmd: Optional pre-built ffmpeg command list (for m4b with cover art etc.).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
AudioSink with write() and close() methods.
|
||||||
|
"""
|
||||||
|
fmt = fmt.lower()
|
||||||
|
|
||||||
|
if fmt in {"wav", "flac"}:
|
||||||
|
import soundfile as sf
|
||||||
|
|
||||||
|
soundfile_obj = sf.SoundFile(
|
||||||
|
path,
|
||||||
|
mode="w",
|
||||||
|
samplerate=SAMPLE_RATE,
|
||||||
|
channels=1,
|
||||||
|
format=fmt.upper(),
|
||||||
|
)
|
||||||
|
|
||||||
|
def _write_wav(data: np.ndarray) -> None:
|
||||||
|
if cancel_check and cancel_check():
|
||||||
|
return
|
||||||
|
soundfile_obj.write(data)
|
||||||
|
|
||||||
|
def _close_wav() -> None:
|
||||||
|
soundfile_obj.close()
|
||||||
|
|
||||||
|
return AudioSink(write=_write_wav, close=_close_wav)
|
||||||
|
|
||||||
|
# Compressed formats: pipe through ffmpeg
|
||||||
|
_ensure_ffmpeg()
|
||||||
|
|
||||||
|
if ffmpeg_cmd is not None:
|
||||||
|
cmd = list(ffmpeg_cmd)
|
||||||
|
else:
|
||||||
|
cmd = build_ffmpeg_command(path, fmt, metadata=metadata)
|
||||||
|
if extra_ffmpeg_args:
|
||||||
|
cmd[2:2] = extra_ffmpeg_args
|
||||||
|
|
||||||
|
process = subprocess.Popen(
|
||||||
|
cmd, stdin=subprocess.PIPE, stdout=subprocess.DEVNULL, stderr=subprocess.DEVNULL
|
||||||
|
)
|
||||||
|
|
||||||
|
def _write_compressed(data: np.ndarray) -> None:
|
||||||
|
if (cancel_check and cancel_check()) or process.stdin is None or process.stdin.closed:
|
||||||
|
return
|
||||||
|
process.stdin.write(data.tobytes())
|
||||||
|
|
||||||
|
def _close_compressed() -> None:
|
||||||
|
if process.stdin and not process.stdin.closed:
|
||||||
|
process.stdin.close()
|
||||||
|
process.wait()
|
||||||
|
|
||||||
|
return AudioSink(write=_write_compressed, close=_close_compressed)
|
||||||
@@ -0,0 +1,131 @@
|
|||||||
|
"""Heuristics for classifying chapters as content vs. supplements.
|
||||||
|
|
||||||
|
A 'supplement' is any non-story material that a listener would typically
|
||||||
|
skip: title page, copyright, table of contents, acknowledgements, etc.
|
||||||
|
The scoring functions return a float; higher ⇒ more likely to be a
|
||||||
|
supplement. ``should_preselect_chapter`` turns that score into a
|
||||||
|
boolean suitable for a web form default.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import Any, Dict, List, Tuple
|
||||||
|
|
||||||
|
# Compiled once at module load – these are immutable.
|
||||||
|
|
||||||
|
_SUPPLEMENT_TITLE_PATTERNS: List[Tuple[re.Pattern[str], float]] = [
|
||||||
|
(re.compile(r"\btitle\s+page\b"), 3.0),
|
||||||
|
(re.compile(r"\bcopyright\b"), 2.4),
|
||||||
|
(re.compile(r"\btable\s+of\s+contents\b"), 2.8),
|
||||||
|
(re.compile(r"\bcontents\b"), 2.0),
|
||||||
|
(re.compile(r"\backnowledg(e)?ments?\b"), 2.0),
|
||||||
|
(re.compile(r"\bdedication\b"), 2.0),
|
||||||
|
(re.compile(r"\babout\s+the\s+author(s)?\b"), 2.4),
|
||||||
|
(re.compile(r"\balso\s+by\b"), 2.0),
|
||||||
|
(re.compile(r"\bpraise\s+for\b"), 2.0),
|
||||||
|
(re.compile(r"\bcolophon\b"), 2.2),
|
||||||
|
(re.compile(r"\bpublication\s+data\b"), 2.2),
|
||||||
|
(re.compile(r"\btranscriber'?s?\s+note\b"), 2.2),
|
||||||
|
(re.compile(r"\bglossary\b"), 2.2),
|
||||||
|
(re.compile(r"\bindex\b"), 2.0),
|
||||||
|
(re.compile(r"\bbibliograph(y|ies)\b"), 2.0),
|
||||||
|
(re.compile(r"\breferences\b"), 1.8),
|
||||||
|
(re.compile(r"\bappendix\b"), 1.9),
|
||||||
|
]
|
||||||
|
|
||||||
|
_CONTENT_TITLE_PATTERNS: List[re.Pattern[str]] = [
|
||||||
|
re.compile(r"\bchapter\b"),
|
||||||
|
re.compile(r"\bbook\b"),
|
||||||
|
re.compile(r"\bpart\b"),
|
||||||
|
re.compile(r"\bsection\b"),
|
||||||
|
re.compile(r"\bscene\b"),
|
||||||
|
re.compile(r"\bprologue\b"),
|
||||||
|
re.compile(r"\bepilogue\b"),
|
||||||
|
re.compile(r"\bintroduction\b"),
|
||||||
|
re.compile(r"\bstory\b"),
|
||||||
|
]
|
||||||
|
|
||||||
|
_SUPPLEMENT_TEXT_KEYWORDS: List[Tuple[str, float]] = [
|
||||||
|
("copyright", 1.2),
|
||||||
|
("all rights reserved", 1.1),
|
||||||
|
("isbn", 0.9),
|
||||||
|
("library of congress", 1.0),
|
||||||
|
("table of contents", 1.0),
|
||||||
|
("dedicated to", 0.8),
|
||||||
|
("acknowledg", 0.8),
|
||||||
|
("printed in", 0.6),
|
||||||
|
("permission", 0.6),
|
||||||
|
("publisher", 0.5),
|
||||||
|
("praise for", 0.9),
|
||||||
|
("also by", 0.9),
|
||||||
|
("glossary", 0.8),
|
||||||
|
("index", 0.8),
|
||||||
|
("newsletter", 3.2),
|
||||||
|
("mailing list", 2.6),
|
||||||
|
("sign-up", 2.2),
|
||||||
|
]
|
||||||
|
|
||||||
|
|
||||||
|
def supplement_score(title: str, text: str, index: int) -> float:
|
||||||
|
"""Return a score indicating how likely *title*/*text* is a supplement.
|
||||||
|
|
||||||
|
Higher values ⇒ more likely to be non-story material (title page,
|
||||||
|
copyright, acknowledgements, etc.).
|
||||||
|
"""
|
||||||
|
normalized_title = (title or "").lower()
|
||||||
|
score = 0.0
|
||||||
|
|
||||||
|
for pattern, weight in _SUPPLEMENT_TITLE_PATTERNS:
|
||||||
|
if pattern.search(normalized_title):
|
||||||
|
score += weight
|
||||||
|
|
||||||
|
for pattern in _CONTENT_TITLE_PATTERNS:
|
||||||
|
if pattern.search(normalized_title):
|
||||||
|
score -= 2.0
|
||||||
|
|
||||||
|
stripped_text = (text or "").strip()
|
||||||
|
length = len(stripped_text)
|
||||||
|
if length <= 150:
|
||||||
|
score += 0.9
|
||||||
|
elif length <= 400:
|
||||||
|
score += 0.6
|
||||||
|
elif length <= 800:
|
||||||
|
score += 0.35
|
||||||
|
|
||||||
|
lowercase_text = stripped_text.lower()
|
||||||
|
for keyword, weight in _SUPPLEMENT_TEXT_KEYWORDS:
|
||||||
|
if keyword in lowercase_text:
|
||||||
|
score += weight
|
||||||
|
|
||||||
|
if index == 0 and score > 0:
|
||||||
|
score += 0.25
|
||||||
|
|
||||||
|
return score
|
||||||
|
|
||||||
|
|
||||||
|
def should_preselect_chapter(
|
||||||
|
title: str,
|
||||||
|
text: str,
|
||||||
|
index: int,
|
||||||
|
total_count: int,
|
||||||
|
) -> bool:
|
||||||
|
"""Return True if the chapter should be *enabled* by default in the form.
|
||||||
|
|
||||||
|
A single chapter is always preselected. For multi-chapter books, the
|
||||||
|
chapter is preselected when its supplement score is below 1.9.
|
||||||
|
"""
|
||||||
|
if total_count <= 1:
|
||||||
|
return True
|
||||||
|
score = supplement_score(title, text, index)
|
||||||
|
return score < 1.9
|
||||||
|
|
||||||
|
|
||||||
|
def ensure_at_least_one_chapter_enabled(chapters: List[Dict[str, Any]]) -> None:
|
||||||
|
"""Mutate *chapters* in-place so that at least one has ``enabled=True``."""
|
||||||
|
if not chapters:
|
||||||
|
return
|
||||||
|
if any(chapter.get("enabled") for chapter in chapters):
|
||||||
|
return
|
||||||
|
best_index = max(range(len(chapters)), key=lambda idx: chapters[idx].get("characters", 0))
|
||||||
|
chapters[best_index]["enabled"] = True
|
||||||
@@ -0,0 +1,92 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, List, Optional, Tuple
|
||||||
|
|
||||||
|
from abogen.text_extractor import ExtractedChapter
|
||||||
|
from abogen.domain.voice_utils import coerce_truthy
|
||||||
|
|
||||||
|
|
||||||
|
def apply_chapter_overrides(
|
||||||
|
extracted: List[ExtractedChapter],
|
||||||
|
overrides: List[Dict[str, Any]],
|
||||||
|
) -> Tuple[List[ExtractedChapter], Dict[str, str], List[str]]:
|
||||||
|
if not overrides:
|
||||||
|
return [], {}, []
|
||||||
|
|
||||||
|
selected: List[ExtractedChapter] = []
|
||||||
|
metadata_updates: Dict[str, str] = {}
|
||||||
|
diagnostics: List[str] = []
|
||||||
|
|
||||||
|
for position, payload in enumerate(overrides):
|
||||||
|
if not isinstance(payload, dict):
|
||||||
|
diagnostics.append(
|
||||||
|
f"Skipped chapter override at position {position + 1}: unsupported payload type {type(payload).__name__}."
|
||||||
|
)
|
||||||
|
continue
|
||||||
|
|
||||||
|
enabled = coerce_truthy(payload.get("enabled", True))
|
||||||
|
payload["enabled"] = enabled
|
||||||
|
if not enabled:
|
||||||
|
continue
|
||||||
|
|
||||||
|
metadata_payload = payload.get("metadata") or {}
|
||||||
|
if isinstance(metadata_payload, dict):
|
||||||
|
for key, value in metadata_payload.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
metadata_updates[str(key)] = str(value)
|
||||||
|
|
||||||
|
base: Optional[ExtractedChapter] = None
|
||||||
|
idx_candidate = payload.get("index")
|
||||||
|
idx_normalized: Optional[int] = None
|
||||||
|
if isinstance(idx_candidate, int):
|
||||||
|
idx_normalized = idx_candidate
|
||||||
|
elif isinstance(idx_candidate, str):
|
||||||
|
try:
|
||||||
|
idx_normalized = int(idx_candidate)
|
||||||
|
except ValueError:
|
||||||
|
idx_normalized = None
|
||||||
|
if idx_normalized is not None and 0 <= idx_normalized < len(extracted):
|
||||||
|
base = extracted[idx_normalized]
|
||||||
|
payload["index"] = idx_normalized
|
||||||
|
|
||||||
|
if base is None:
|
||||||
|
source_title = payload.get("source_title")
|
||||||
|
if isinstance(source_title, str):
|
||||||
|
base = next((chapter for chapter in extracted if chapter.title == source_title), None)
|
||||||
|
|
||||||
|
if base is None:
|
||||||
|
candidate_title = payload.get("title")
|
||||||
|
if isinstance(candidate_title, str):
|
||||||
|
base = next((chapter for chapter in extracted if chapter.title == candidate_title), None)
|
||||||
|
|
||||||
|
text_override = payload.get("text")
|
||||||
|
if text_override is not None:
|
||||||
|
text_value = str(text_override)
|
||||||
|
elif base is not None:
|
||||||
|
text_value = base.text
|
||||||
|
else:
|
||||||
|
diagnostics.append(
|
||||||
|
f"Skipped chapter override at position {position + 1}: no text provided and no matching source chapter found."
|
||||||
|
)
|
||||||
|
continue
|
||||||
|
|
||||||
|
title_override = payload.get("title")
|
||||||
|
if title_override is not None:
|
||||||
|
title_value = str(title_override)
|
||||||
|
elif base is not None:
|
||||||
|
title_value = base.title
|
||||||
|
else:
|
||||||
|
title_value = f"Chapter {position + 1}"
|
||||||
|
|
||||||
|
if base and not payload.get("source_title"):
|
||||||
|
payload["source_title"] = base.title
|
||||||
|
|
||||||
|
payload["title"] = title_value
|
||||||
|
payload["text"] = text_value
|
||||||
|
payload["characters"] = len(text_value)
|
||||||
|
payload.setdefault("order", payload.get("order", position))
|
||||||
|
|
||||||
|
selected.append(ExtractedChapter(title=title_value, text=text_value))
|
||||||
|
|
||||||
|
return selected, metadata_updates, diagnostics
|
||||||
@@ -0,0 +1,204 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import List, Tuple
|
||||||
|
|
||||||
|
|
||||||
|
_HEADING_SANITIZE_RE = re.compile(r"[^a-z0-9]+")
|
||||||
|
_HEADING_NUMBER_PREFIX_RE = re.compile(
|
||||||
|
r"^\s*(?P<number>(?:\d+|[ivxlcdm]+))(?P<suffix>(?:[\s.:;-].*)?)$",
|
||||||
|
re.IGNORECASE,
|
||||||
|
)
|
||||||
|
_ACRONYM_ALLOWLIST = {
|
||||||
|
"AI", "API", "CPU", "DIY", "GPU", "HTML", "HTTP", "HTTPS", "ID",
|
||||||
|
"JSON", "MP3", "MP4", "M4B", "NASA", "OCR", "PDF", "SQL", "TV",
|
||||||
|
"TTS", "UK", "UN", "UFO", "OK", "URL", "USA", "US", "VR",
|
||||||
|
}
|
||||||
|
_ROMAN_NUMERAL_CHARS = frozenset("IVXLCDM")
|
||||||
|
_CAPS_WORD_RE = re.compile(r"[A-Z][A-Z0-9'\u2019-]*")
|
||||||
|
|
||||||
|
|
||||||
|
def simplify_heading_text(text: str) -> str:
|
||||||
|
raw = str(text or "").strip().lower()
|
||||||
|
if not raw:
|
||||||
|
return ""
|
||||||
|
simplified = _HEADING_SANITIZE_RE.sub("", raw)
|
||||||
|
if simplified.startswith("chapter"):
|
||||||
|
simplified = simplified[7:]
|
||||||
|
return simplified
|
||||||
|
|
||||||
|
|
||||||
|
def headings_equivalent(left: str, right: str) -> bool:
|
||||||
|
simple_left = simplify_heading_text(left)
|
||||||
|
simple_right = simplify_heading_text(right)
|
||||||
|
if not simple_left or not simple_right:
|
||||||
|
return False
|
||||||
|
if simple_left == simple_right:
|
||||||
|
return True
|
||||||
|
if simple_right.startswith(simple_left):
|
||||||
|
return True
|
||||||
|
if simple_left.startswith(simple_right):
|
||||||
|
return True
|
||||||
|
if len(simple_left) > 5 and simple_left in simple_right:
|
||||||
|
return True
|
||||||
|
return False
|
||||||
|
|
||||||
|
|
||||||
|
def strip_duplicate_heading_line(text: str, heading: str) -> Tuple[str, bool]:
|
||||||
|
source_text = str(text or "")
|
||||||
|
if not source_text:
|
||||||
|
return source_text, False
|
||||||
|
normalized_heading = simplify_heading_text(heading)
|
||||||
|
if not normalized_heading:
|
||||||
|
return source_text, False
|
||||||
|
lines = source_text.splitlines()
|
||||||
|
new_lines: List[str] = []
|
||||||
|
removed = False
|
||||||
|
for line in lines:
|
||||||
|
stripped = line.strip()
|
||||||
|
if not removed and stripped:
|
||||||
|
if headings_equivalent(stripped, heading):
|
||||||
|
removed = True
|
||||||
|
continue
|
||||||
|
new_lines.append(line)
|
||||||
|
if not removed:
|
||||||
|
return source_text, False
|
||||||
|
while new_lines and not new_lines[0].strip():
|
||||||
|
new_lines.pop(0)
|
||||||
|
return "\n".join(new_lines), True
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_caps_word(word: str) -> str:
|
||||||
|
upper = word.upper()
|
||||||
|
letters = [char for char in upper if char.isalpha()]
|
||||||
|
if not letters:
|
||||||
|
return word
|
||||||
|
if upper in _ACRONYM_ALLOWLIST:
|
||||||
|
return word
|
||||||
|
if len(letters) <= 1:
|
||||||
|
return word
|
||||||
|
if all(char in _ROMAN_NUMERAL_CHARS for char in letters) and len(letters) <= 7:
|
||||||
|
return word
|
||||||
|
|
||||||
|
parts = re.split(r"(['\-\u2019])", word)
|
||||||
|
normalized_parts: List[str] = []
|
||||||
|
for part in parts:
|
||||||
|
if part in {"'", "-", "\u2019"}:
|
||||||
|
normalized_parts.append(part)
|
||||||
|
continue
|
||||||
|
if not part:
|
||||||
|
continue
|
||||||
|
normalized_parts.append(part[0].upper() + part[1:].lower())
|
||||||
|
return "".join(normalized_parts) or word
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_chapter_opening_caps(text: str) -> Tuple[str, bool]:
|
||||||
|
if not text:
|
||||||
|
return text, False
|
||||||
|
|
||||||
|
leading_len = len(text) - len(text.lstrip())
|
||||||
|
leading = text[:leading_len]
|
||||||
|
working = text[leading_len:]
|
||||||
|
if not working:
|
||||||
|
return text, False
|
||||||
|
|
||||||
|
builder: List[str] = []
|
||||||
|
pos = 0
|
||||||
|
changed = False
|
||||||
|
|
||||||
|
while pos < len(working):
|
||||||
|
char = working[pos]
|
||||||
|
if char in "\r\n":
|
||||||
|
builder.append(working[pos:])
|
||||||
|
pos = len(working)
|
||||||
|
break
|
||||||
|
if char.isspace():
|
||||||
|
builder.append(char)
|
||||||
|
pos += 1
|
||||||
|
continue
|
||||||
|
if char.islower():
|
||||||
|
builder.append(working[pos:])
|
||||||
|
pos = len(working)
|
||||||
|
break
|
||||||
|
if not char.isalpha():
|
||||||
|
builder.append(char)
|
||||||
|
pos += 1
|
||||||
|
continue
|
||||||
|
|
||||||
|
match = _CAPS_WORD_RE.match(working, pos)
|
||||||
|
if not match:
|
||||||
|
builder.append(char)
|
||||||
|
pos += 1
|
||||||
|
continue
|
||||||
|
|
||||||
|
word = match.group(0)
|
||||||
|
if any(ch.islower() for ch in word):
|
||||||
|
builder.append(working[pos:])
|
||||||
|
pos = len(working)
|
||||||
|
break
|
||||||
|
|
||||||
|
normalized = normalize_caps_word(word)
|
||||||
|
if normalized != word:
|
||||||
|
changed = True
|
||||||
|
builder.append(normalized)
|
||||||
|
pos = match.end()
|
||||||
|
|
||||||
|
if pos < len(working):
|
||||||
|
builder.append(working[pos:])
|
||||||
|
|
||||||
|
if not changed:
|
||||||
|
return text, False
|
||||||
|
|
||||||
|
return leading + "".join(builder), True
|
||||||
|
|
||||||
|
|
||||||
|
def format_spoken_chapter_title(title: str, index: int, apply_prefix: bool) -> str:
|
||||||
|
base = str(title or "").strip()
|
||||||
|
if not base:
|
||||||
|
return f"Chapter {index}" if apply_prefix else ""
|
||||||
|
if not apply_prefix:
|
||||||
|
return base
|
||||||
|
lowered = base.lower()
|
||||||
|
if lowered.startswith("chapter") and (len(lowered) == 7 or not lowered[7].isalpha()):
|
||||||
|
return base
|
||||||
|
match = _HEADING_NUMBER_PREFIX_RE.match(base)
|
||||||
|
if match:
|
||||||
|
number = match.group("number") or ""
|
||||||
|
suffix = match.group("suffix") or ""
|
||||||
|
cleaned_suffix = suffix.lstrip(" .,:;-_ \t\u2013\u2014\u00b7\u2022")
|
||||||
|
if cleaned_suffix:
|
||||||
|
return f"Chapter {number}. {cleaned_suffix}"
|
||||||
|
return f"Chapter {number}"
|
||||||
|
return base
|
||||||
|
|
||||||
|
|
||||||
|
def apply_chapter_text_transforms(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
heading_text: str,
|
||||||
|
raw_title: str,
|
||||||
|
strip_heading: bool,
|
||||||
|
normalize_caps: bool,
|
||||||
|
) -> Tuple[str, bool, bool]:
|
||||||
|
"""Strip duplicate heading and normalize opening caps.
|
||||||
|
|
||||||
|
Returns ``(text, heading_removed, caps_changed)``.
|
||||||
|
The caller is responsible for state updates (pending flags, logging,
|
||||||
|
dict mutation, ``continue``).
|
||||||
|
"""
|
||||||
|
heading_removed = False
|
||||||
|
caps_changed = False
|
||||||
|
|
||||||
|
if strip_heading and heading_text:
|
||||||
|
text, heading_removed = strip_duplicate_heading_line(text, heading_text)
|
||||||
|
if not heading_removed and raw_title:
|
||||||
|
match = _HEADING_NUMBER_PREFIX_RE.match(raw_title)
|
||||||
|
if match:
|
||||||
|
number = match.group("number")
|
||||||
|
if number:
|
||||||
|
text, heading_removed = strip_duplicate_heading_line(text, number)
|
||||||
|
|
||||||
|
if normalize_caps and text:
|
||||||
|
text, caps_changed = normalize_chapter_opening_caps(text)
|
||||||
|
|
||||||
|
return text, heading_removed, caps_changed
|
||||||
@@ -0,0 +1,76 @@
|
|||||||
|
"""Chunk processing utilities.
|
||||||
|
|
||||||
|
Functions for grouping chunks, recording override usage, and selecting
|
||||||
|
text for TTS synthesis.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from collections import defaultdict
|
||||||
|
from typing import Any, Dict, Iterable, Mapping
|
||||||
|
|
||||||
|
from abogen.domain.enums import Language
|
||||||
|
from abogen.pronunciation_store import increment_usage
|
||||||
|
|
||||||
|
|
||||||
|
def safe_int(value: Any, default: int = 0) -> int:
|
||||||
|
try:
|
||||||
|
return int(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def group_chunks_by_chapter(chunks: Iterable[Dict[str, Any]]) -> Dict[int, List[Dict[str, Any]]]:
|
||||||
|
grouped: Dict[int, List[Dict[str, Any]]] = defaultdict(list)
|
||||||
|
for entry in chunks or []:
|
||||||
|
if not isinstance(entry, dict):
|
||||||
|
continue
|
||||||
|
try:
|
||||||
|
chapter_index = int(entry.get("chapter_index", 0))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
chapter_index = 0
|
||||||
|
grouped[chapter_index].append(dict(entry))
|
||||||
|
|
||||||
|
for chapter_index, items in grouped.items():
|
||||||
|
items.sort(key=lambda payload: safe_int(payload.get("chunk_index")))
|
||||||
|
|
||||||
|
return grouped
|
||||||
|
|
||||||
|
|
||||||
|
def record_override_usage(
|
||||||
|
job: Any,
|
||||||
|
usage_counter: Mapping[str, int],
|
||||||
|
token_map: Mapping[str, str],
|
||||||
|
) -> None:
|
||||||
|
if not usage_counter:
|
||||||
|
return
|
||||||
|
|
||||||
|
language = getattr(job, "language", Language.EN_US) or Language.EN_US
|
||||||
|
for normalized, amount in usage_counter.items():
|
||||||
|
if amount <= 0:
|
||||||
|
continue
|
||||||
|
token_value = token_map.get(normalized, normalized)
|
||||||
|
try:
|
||||||
|
increment_usage(language=language, token=token_value, amount=int(amount))
|
||||||
|
except Exception: # pragma: no cover - defensive logging
|
||||||
|
job.add_log(f"Failed to record usage for override {token_value}", level="warning")
|
||||||
|
|
||||||
|
|
||||||
|
def chunk_text_for_tts(entry: Mapping[str, Any]) -> str:
|
||||||
|
"""Choose the best source text for synthesis.
|
||||||
|
|
||||||
|
We must prefer the raw chunk text (``text`` / ``original_text``) so
|
||||||
|
manual/pronunciation overrides can match against the original tokens
|
||||||
|
(e.g. censored words like ``Unfu*k``). ``normalized_text`` may have
|
||||||
|
already been run through ``normalize_for_pipeline``, which can remove
|
||||||
|
punctuation and prevent overrides from triggering.
|
||||||
|
"""
|
||||||
|
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
return ""
|
||||||
|
return str(
|
||||||
|
entry.get("text")
|
||||||
|
or entry.get("original_text")
|
||||||
|
or entry.get("normalized_text")
|
||||||
|
or ""
|
||||||
|
).strip()
|
||||||
@@ -0,0 +1,52 @@
|
|||||||
|
"""Domain config types — shared contracts for domain functions.
|
||||||
|
|
||||||
|
These dataclasses group parameters that domain functions receive.
|
||||||
|
Domain defines them, app layer fills them.
|
||||||
|
|
||||||
|
Why here (domain) and not application:
|
||||||
|
- build_tts_context() is in domain → needs PronunciationConfig
|
||||||
|
- make_subtitle_writer() is in infrastructure → needs SubtitleConfig
|
||||||
|
- embed_m4b_metadata() is in infrastructure → needs CoverConfig
|
||||||
|
- Domain should not depend on application layer (DIP)
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional
|
||||||
|
|
||||||
|
from abogen.domain.enums import SubtitleFormat, SubtitleMode
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class PronunciationConfig:
|
||||||
|
"""Pronunciation and normalization override settings.
|
||||||
|
|
||||||
|
Used by build_tts_context() to compile override rules.
|
||||||
|
"""
|
||||||
|
pronunciation_overrides: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
manual_overrides: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
heteronym_overrides: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
normalization_overrides: Optional[Dict[str, Any]] = None
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class SubtitleConfig:
|
||||||
|
"""Subtitle output settings.
|
||||||
|
|
||||||
|
Used by make_subtitle_writer() and process_and_write_subtitles().
|
||||||
|
"""
|
||||||
|
mode: SubtitleMode = SubtitleMode.DISABLED
|
||||||
|
format: SubtitleFormat = SubtitleFormat.SRT
|
||||||
|
max_words: int = 50
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class CoverConfig:
|
||||||
|
"""Cover image settings.
|
||||||
|
|
||||||
|
Used by embed_m4b_metadata() and build_epub3_package().
|
||||||
|
"""
|
||||||
|
path: Optional[Path] = None
|
||||||
|
mime: Optional[str] = None
|
||||||
@@ -0,0 +1,241 @@
|
|||||||
|
"""Shared TTS iteration loop used by both WebUI and PyQt conversion runners.
|
||||||
|
|
||||||
|
The core pattern is identical across both UIs:
|
||||||
|
|
||||||
|
for seg in tts_segments(text, backend, voice, speed, split_pattern, current_time):
|
||||||
|
check_cancel()
|
||||||
|
update_progress(seg)
|
||||||
|
write_audio(seg, sink)
|
||||||
|
accumulate_subtitles(seg)
|
||||||
|
|
||||||
|
After the loop, the caller processes accumulated subtitle tokens.
|
||||||
|
|
||||||
|
This module provides ``run_tts_segment_loop`` which encapsulates that
|
||||||
|
iteration, and ``synthesize_text`` which adds normalization on top —
|
||||||
|
the single entry point both UIs should call for text-to-speech.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import time
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from typing import Any, Callable, Optional, Protocol
|
||||||
|
|
||||||
|
from abogen.domain.audio_sink import AudioSink
|
||||||
|
from abogen.domain.conversion_pipeline import tts_segments
|
||||||
|
from abogen.domain.enums import Language, SubtitleMode
|
||||||
|
from abogen.domain.normalization import TTSContext
|
||||||
|
from abogen.domain.progress import calc_etr_str
|
||||||
|
from abogen.domain.subtitle_generation import process_subtitle_tokens
|
||||||
|
|
||||||
|
|
||||||
|
class CancelChecker(Protocol):
|
||||||
|
"""Returns True if conversion has been cancelled."""
|
||||||
|
def __call__(self) -> bool: ...
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SegmentStats:
|
||||||
|
"""Running statistics updated per TTS segment."""
|
||||||
|
processed_chars: int = 0
|
||||||
|
current_time: float = 0.0
|
||||||
|
etr_start_time: float = field(default_factory=time.time)
|
||||||
|
total_characters: int = 0
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SegmentInfo:
|
||||||
|
"""Read-only info about a TTS segment, passed to on_segment callback."""
|
||||||
|
graphemes: str
|
||||||
|
audio: Any
|
||||||
|
tokens: list
|
||||||
|
duration: float
|
||||||
|
chunk_start: float
|
||||||
|
|
||||||
|
|
||||||
|
def run_tts_segment_loop(
|
||||||
|
*,
|
||||||
|
text: str,
|
||||||
|
params: SynthParams,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float,
|
||||||
|
split_pattern: str,
|
||||||
|
total_steps: Optional[int] = None,
|
||||||
|
chapter_sink: Optional[AudioSink] = None,
|
||||||
|
preview_callback: Optional[Callable[[str], None]] = None,
|
||||||
|
on_segment: Optional[Callable[[SegmentInfo], None]] = None,
|
||||||
|
) -> tuple[int, list]:
|
||||||
|
"""Run the core TTS segment iteration loop.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Normalized text to synthesize.
|
||||||
|
params: Common synthesis parameters (stats, callbacks, sinks, etc.).
|
||||||
|
backend: TTS pipeline instance (Kokoro or Supertonic).
|
||||||
|
voice: Voice name/id for the backend.
|
||||||
|
speed: Speech speed multiplier.
|
||||||
|
split_pattern: Regex pattern used by the TTS engine for sentence splitting.
|
||||||
|
total_steps: Inference quality steps (Supertonic only, ignored by Kokoro).
|
||||||
|
preview_callback: Called with a short preview string per segment.
|
||||||
|
on_segment: Called with a SegmentInfo for each segment *before*
|
||||||
|
audio is written. Useful for callers that need per-segment
|
||||||
|
subtitle processing (e.g. PyQt dual-writer pattern).
|
||||||
|
When provided, the default subtitle accumulation is skipped.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (segment_count, accumulated_subtitle_tokens).
|
||||||
|
The caller is responsible for processing subtitle tokens via
|
||||||
|
``process_subtitle_tokens`` and writing entries to subtitle writers.
|
||||||
|
"""
|
||||||
|
local_segments = 0
|
||||||
|
accumulated_tokens: list[dict] = []
|
||||||
|
|
||||||
|
for seg in tts_segments(
|
||||||
|
text,
|
||||||
|
backend=backend,
|
||||||
|
voice=voice,
|
||||||
|
speed=speed,
|
||||||
|
split_pattern=split_pattern,
|
||||||
|
current_time=params.stats.current_time,
|
||||||
|
total_steps=total_steps,
|
||||||
|
):
|
||||||
|
if params.check_cancel():
|
||||||
|
break
|
||||||
|
|
||||||
|
local_segments += 1
|
||||||
|
params.stats.processed_chars += len(seg.graphemes)
|
||||||
|
|
||||||
|
# Progress
|
||||||
|
if params.stats.total_characters:
|
||||||
|
percent = min(int(params.stats.processed_chars / params.stats.total_characters * 100), 99)
|
||||||
|
else:
|
||||||
|
percent = 0 if params.stats.processed_chars == 0 else 99
|
||||||
|
|
||||||
|
etr_str = calc_etr_str(
|
||||||
|
time.time() - params.stats.etr_start_time,
|
||||||
|
params.stats.processed_chars,
|
||||||
|
params.stats.total_characters,
|
||||||
|
)
|
||||||
|
params.on_progress(percent, etr_str)
|
||||||
|
|
||||||
|
# Preview / log
|
||||||
|
if preview_callback:
|
||||||
|
preview_callback(seg.graphemes or "[silence]")
|
||||||
|
|
||||||
|
# Per-segment callback (for callers needing segment-level access)
|
||||||
|
if on_segment:
|
||||||
|
info = SegmentInfo(
|
||||||
|
graphemes=seg.graphemes,
|
||||||
|
audio=seg.audio,
|
||||||
|
tokens=list(seg.tokens) if seg.tokens else [],
|
||||||
|
duration=seg.duration,
|
||||||
|
chunk_start=getattr(seg, "chunk_start", params.stats.current_time),
|
||||||
|
)
|
||||||
|
on_segment(info)
|
||||||
|
|
||||||
|
# Write audio
|
||||||
|
if chapter_sink:
|
||||||
|
chapter_sink.write(seg.audio)
|
||||||
|
if params.audio_sink:
|
||||||
|
params.audio_sink.write(seg.audio)
|
||||||
|
|
||||||
|
# Accumulate subtitle tokens (default path; skipped if on_segment handles it)
|
||||||
|
if not on_segment and params.subtitle_mode != SubtitleMode.DISABLED and seg.tokens:
|
||||||
|
accumulated_tokens.extend(seg.tokens)
|
||||||
|
|
||||||
|
# Update timing
|
||||||
|
if params.audio_sink:
|
||||||
|
params.stats.current_time += seg.duration
|
||||||
|
|
||||||
|
return local_segments, accumulated_tokens
|
||||||
|
|
||||||
|
|
||||||
|
def process_and_write_subtitles(
|
||||||
|
accumulated_tokens: list[dict],
|
||||||
|
subtitle_writer: Any,
|
||||||
|
*,
|
||||||
|
subtitle: "SubtitleConfig | str",
|
||||||
|
max_subtitle_words: int | None = None,
|
||||||
|
language: Language,
|
||||||
|
use_spacy_segmentation: bool,
|
||||||
|
fallback_end_time: float,
|
||||||
|
) -> None:
|
||||||
|
"""Process accumulated subtitle tokens and write entries to a subtitle writer.
|
||||||
|
|
||||||
|
Accepts a SubtitleConfig object or a subtitle mode string
|
||||||
|
for backward compatibility.
|
||||||
|
"""
|
||||||
|
from abogen.domain.config_types import SubtitleConfig
|
||||||
|
|
||||||
|
if isinstance(subtitle, SubtitleConfig):
|
||||||
|
mode_str = subtitle.mode.value
|
||||||
|
words = subtitle.max_words
|
||||||
|
else:
|
||||||
|
mode_str = subtitle
|
||||||
|
words = max_subtitle_words or 50
|
||||||
|
|
||||||
|
if not accumulated_tokens or not subtitle_writer:
|
||||||
|
return
|
||||||
|
new_entries: list[tuple] = []
|
||||||
|
process_subtitle_tokens(
|
||||||
|
accumulated_tokens,
|
||||||
|
new_entries,
|
||||||
|
words,
|
||||||
|
mode_str,
|
||||||
|
language,
|
||||||
|
use_spacy_segmentation=use_spacy_segmentation,
|
||||||
|
fallback_end_time=fallback_end_time,
|
||||||
|
)
|
||||||
|
for start, end, text in new_entries:
|
||||||
|
subtitle_writer.write_entry(start=start, end=end, text=text)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class SynthParams:
|
||||||
|
"""Common parameters for synthesize_text calls.
|
||||||
|
|
||||||
|
Packed once by the executor to avoid repeating identical kwargs.
|
||||||
|
When adding new common params, change only this dataclass.
|
||||||
|
"""
|
||||||
|
tts_context: TTSContext
|
||||||
|
stats: SegmentStats
|
||||||
|
check_cancel: CancelChecker
|
||||||
|
on_progress: Callable[[int, str], None]
|
||||||
|
audio_sink: Optional[AudioSink] = None
|
||||||
|
subtitle_mode: str = "Disabled"
|
||||||
|
max_subtitle_words: int = 50
|
||||||
|
language: Language = Language.EN_US
|
||||||
|
use_spacy_segmentation: bool = False
|
||||||
|
|
||||||
|
|
||||||
|
def synthesize_text(
|
||||||
|
*,
|
||||||
|
text: str,
|
||||||
|
params: SynthParams,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float,
|
||||||
|
total_steps: Optional[int] = None,
|
||||||
|
chapter_sink: Optional[AudioSink] = None,
|
||||||
|
preview_callback: Optional[Callable[[str], None]] = None,
|
||||||
|
on_segment: Optional[Callable[[SegmentInfo], None]] = None,
|
||||||
|
split_pattern_override: Optional[str] = None,
|
||||||
|
) -> tuple[int, list]:
|
||||||
|
"""Normalize text and run TTS — the single entry point for both UIs.
|
||||||
|
|
||||||
|
Combines TTSContext.normalize() + run_tts_segment_loop() into one call.
|
||||||
|
UI-specific concerns (provider resolution, progress display) stay in the UI.
|
||||||
|
"""
|
||||||
|
normalized = params.tts_context.normalize(text)
|
||||||
|
return run_tts_segment_loop(
|
||||||
|
text=normalized,
|
||||||
|
params=params,
|
||||||
|
backend=backend,
|
||||||
|
voice=voice,
|
||||||
|
speed=speed,
|
||||||
|
total_steps=total_steps,
|
||||||
|
split_pattern=split_pattern_override or params.tts_context.split_pattern,
|
||||||
|
chapter_sink=chapter_sink,
|
||||||
|
preview_callback=preview_callback,
|
||||||
|
on_segment=on_segment,
|
||||||
|
)
|
||||||
@@ -0,0 +1,355 @@
|
|||||||
|
"""Shared TTS emission pipeline.
|
||||||
|
|
||||||
|
Provides the core TTS emission loop used by both WebUI and PyQt conversion runners.
|
||||||
|
The caller handles audio I/O, progress reporting, and subtitle writing.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
|
||||||
|
from abogen.domain.enums import Language, SubtitleMode
|
||||||
|
from typing import Any, Callable, Dict, Iterator, List, Optional, Tuple
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
|
||||||
|
from abogen.domain.audio_helpers import to_float32
|
||||||
|
from abogen.domain.normalization import prepare_text_for_tts
|
||||||
|
from abogen.domain.tokens import FakeToken
|
||||||
|
from abogen.domain.audio_buffer import SAMPLE_RATE
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
# Languages where spaCy is used for pre-TTS segmentation
|
||||||
|
# English ("a", "b") is excluded — spaCy only used for post-TTS subtitles
|
||||||
|
_SPACY_EXCLUDED_LANGS = {Language.EN_US, Language.EN_GB}
|
||||||
|
|
||||||
|
# CJK languages — different spacing pattern
|
||||||
|
_CJK_LANGS = {Language.ZH, Language.JA}
|
||||||
|
|
||||||
|
|
||||||
|
def spacy_pre_tts_segmentation(
|
||||||
|
text: str,
|
||||||
|
lang_code: Any,
|
||||||
|
subtitle_mode: Any,
|
||||||
|
*,
|
||||||
|
is_subtitle_input: bool = False,
|
||||||
|
use_spacy_segmentation: bool = True,
|
||||||
|
log_callback: Optional[Callable[[str], None]] = None,
|
||||||
|
) -> Tuple[List[str], str]:
|
||||||
|
"""Segment text using spaCy before TTS, with split_pattern override.
|
||||||
|
|
||||||
|
For non-English languages, spaCy sentence segmentation produces better
|
||||||
|
sentence boundaries than regex. This function:
|
||||||
|
1. Checks if spaCy should be used (toggle on, not disabled mode, not subtitle input)
|
||||||
|
2. For non-English: runs spaCy segmentation, computes split_pattern override
|
||||||
|
3. For English: returns single segment with default pattern (spaCy only for subtitles)
|
||||||
|
4. If spaCy fails: falls back to default pattern
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Text to segment.
|
||||||
|
lang_code: Language code (Language enum or string like "a", "de", "fr").
|
||||||
|
subtitle_mode: SubtitleMode enum or string.
|
||||||
|
is_subtitle_input: True if source is .srt/.ass/.vtt file.
|
||||||
|
use_spacy_segmentation: User toggle for spaCy segmentation.
|
||||||
|
log_callback: Optional logging function.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (text_segments, active_split_pattern).
|
||||||
|
text_segments is a list of sentences (always at least one element).
|
||||||
|
active_split_pattern is the regex to use for TTS backend splitting.
|
||||||
|
"""
|
||||||
|
from abogen.domain.split_pattern import PUNCTUATION_COMMAS, get_split_pattern
|
||||||
|
|
||||||
|
def _log(msg: str) -> None:
|
||||||
|
if log_callback:
|
||||||
|
log_callback(msg)
|
||||||
|
|
||||||
|
# Normalize language
|
||||||
|
lang_enum = _to_language_enum(lang_code)
|
||||||
|
|
||||||
|
# Default split pattern
|
||||||
|
default_split = get_split_pattern(lang_code, subtitle_mode)
|
||||||
|
|
||||||
|
# Check conditions
|
||||||
|
if not use_spacy_segmentation:
|
||||||
|
return [text], default_split
|
||||||
|
|
||||||
|
subtitle_mode_str = _to_subtitle_mode_str(subtitle_mode)
|
||||||
|
if subtitle_mode_str in ("Disabled", "Line"):
|
||||||
|
return [text], default_split
|
||||||
|
|
||||||
|
if is_subtitle_input:
|
||||||
|
return [text], default_split
|
||||||
|
|
||||||
|
# English: spaCy only for post-TTS subtitles, not pre-TTS
|
||||||
|
if lang_enum in _SPACY_EXCLUDED_LANGS:
|
||||||
|
return [text], default_split
|
||||||
|
|
||||||
|
# Non-English: run spaCy pre-TTS segmentation
|
||||||
|
from abogen.spacy_utils import segment_sentences
|
||||||
|
|
||||||
|
_log("Using spaCy for sentence segmentation (pre-TTS)...")
|
||||||
|
spacy_sentences = segment_sentences(text, lang_code, log_callback=log_callback)
|
||||||
|
|
||||||
|
if not spacy_sentences:
|
||||||
|
_log("spaCy: Fallback to default segmentation...")
|
||||||
|
return [text], default_split
|
||||||
|
|
||||||
|
_log(f"spaCy: Text segmented into {len(spacy_sentences)} sentences...")
|
||||||
|
|
||||||
|
# Compute split_pattern override based on subtitle mode
|
||||||
|
spacing_pattern = r"\s*" if lang_enum in _CJK_LANGS else r"\s+"
|
||||||
|
|
||||||
|
if subtitle_mode_str == "Sentence + Comma":
|
||||||
|
active_split = r"(?<=[{}]){}|\n+".format(PUNCTUATION_COMMAS, spacing_pattern)
|
||||||
|
else:
|
||||||
|
# Sentence mode: spaCy already split, only split on newlines
|
||||||
|
active_split = "\n"
|
||||||
|
|
||||||
|
return spacy_sentences, active_split
|
||||||
|
|
||||||
|
|
||||||
|
def _to_language_enum(lang_code: Any) -> Language:
|
||||||
|
"""Convert lang_code to Language enum (ISO code or Language enum)."""
|
||||||
|
try:
|
||||||
|
return Language.from_str(str(lang_code))
|
||||||
|
except ValueError:
|
||||||
|
return Language.EN_US
|
||||||
|
|
||||||
|
|
||||||
|
def _to_subtitle_mode_str(subtitle_mode: Any) -> str:
|
||||||
|
"""Convert subtitle_mode to string."""
|
||||||
|
if isinstance(subtitle_mode, SubtitleMode):
|
||||||
|
return subtitle_mode.value
|
||||||
|
return str(subtitle_mode)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SegmentResult:
|
||||||
|
"""One TTS segment emitted by the pipeline."""
|
||||||
|
graphemes: str
|
||||||
|
audio: np.ndarray
|
||||||
|
duration: float
|
||||||
|
chunk_start: float
|
||||||
|
tokens: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
|
||||||
|
|
||||||
|
def tts_segments(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float,
|
||||||
|
split_pattern: str,
|
||||||
|
current_time: float = 0.0,
|
||||||
|
total_steps: Optional[int] = None,
|
||||||
|
) -> Iterator[SegmentResult]:
|
||||||
|
"""Invoke TTS backend on (already normalized) text and yield SegmentResults.
|
||||||
|
|
||||||
|
Use this when you've already normalized the text yourself (e.g. after
|
||||||
|
spaCy sentence segmentation). For raw text, use emit_text_segments() instead.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Already-normalized text to synthesize.
|
||||||
|
backend: TTS pipeline callable.
|
||||||
|
voice: Resolved voice.
|
||||||
|
speed: TTS speed multiplier.
|
||||||
|
split_pattern: Regex pattern for sentence splitting.
|
||||||
|
current_time: Current position in the audio timeline (seconds).
|
||||||
|
total_steps: Inference quality steps (Supertonic only, ignored by Kokoro).
|
||||||
|
|
||||||
|
Yields:
|
||||||
|
SegmentResult for each non-empty TTS segment.
|
||||||
|
"""
|
||||||
|
kwargs: dict[str, Any] = dict(
|
||||||
|
voice=voice,
|
||||||
|
speed=speed,
|
||||||
|
split_pattern=split_pattern,
|
||||||
|
)
|
||||||
|
if total_steps is not None:
|
||||||
|
kwargs["total_steps"] = total_steps
|
||||||
|
|
||||||
|
segment_iter = backend(text, **kwargs)
|
||||||
|
|
||||||
|
chunk_start = current_time
|
||||||
|
|
||||||
|
for segment in segment_iter:
|
||||||
|
graphemes_raw = getattr(segment, "graphemes", "") or ""
|
||||||
|
graphemes = graphemes_raw.strip()
|
||||||
|
|
||||||
|
audio = to_float32(getattr(segment, "audio", None))
|
||||||
|
if audio.size == 0:
|
||||||
|
continue
|
||||||
|
|
||||||
|
duration = len(audio) / SAMPLE_RATE
|
||||||
|
|
||||||
|
tokens_list = getattr(segment, "tokens", [])
|
||||||
|
if not tokens_list and graphemes:
|
||||||
|
tokens_list = [FakeToken(graphemes, 0, duration)]
|
||||||
|
|
||||||
|
tokens = [
|
||||||
|
{
|
||||||
|
"start": chunk_start + (tok.start_ts or 0),
|
||||||
|
"end": chunk_start + (tok.end_ts or 0),
|
||||||
|
"text": tok.text,
|
||||||
|
"whitespace": tok.whitespace,
|
||||||
|
}
|
||||||
|
for tok in tokens_list
|
||||||
|
]
|
||||||
|
|
||||||
|
yield SegmentResult(
|
||||||
|
graphemes=graphemes,
|
||||||
|
audio=audio,
|
||||||
|
duration=duration,
|
||||||
|
chunk_start=chunk_start,
|
||||||
|
tokens=tokens,
|
||||||
|
)
|
||||||
|
|
||||||
|
chunk_start += duration
|
||||||
|
|
||||||
|
|
||||||
|
def emit_text_segments(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float,
|
||||||
|
split_pattern: str,
|
||||||
|
current_time: float = 0.0,
|
||||||
|
total_steps: Optional[int] = None,
|
||||||
|
# normalization
|
||||||
|
heteronym_rules: Any = None,
|
||||||
|
pronunciation_rules: Any = None,
|
||||||
|
normalization_overrides: Any = None,
|
||||||
|
usage_counter: Optional[Dict[str, int]] = None,
|
||||||
|
) -> Iterator[SegmentResult]:
|
||||||
|
"""Normalize text and yield SegmentResults from the TTS backend.
|
||||||
|
|
||||||
|
This is the innermost TTS emission loop shared by both UIs. It handles:
|
||||||
|
1. Text normalization (heteronym + pronunciation rules)
|
||||||
|
2. TTS backend invocation
|
||||||
|
3. Segment iteration with token extraction
|
||||||
|
|
||||||
|
The caller is responsible for:
|
||||||
|
- Writing audio to sinks
|
||||||
|
- Accumulating tokens for subtitle processing
|
||||||
|
- Progress tracking and cancellation
|
||||||
|
- Error handling
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Raw text to synthesize.
|
||||||
|
backend: TTS pipeline callable (kokoro or supertonic).
|
||||||
|
voice: Resolved voice for TTS.
|
||||||
|
speed: TTS speed multiplier.
|
||||||
|
split_pattern: Regex pattern for sentence splitting.
|
||||||
|
current_time: Current position in the audio timeline (seconds).
|
||||||
|
heteronym_rules: Compiled heteronym rules.
|
||||||
|
pronunciation_rules: Compiled pronunciation rules.
|
||||||
|
normalization_overrides: User normalization overrides.
|
||||||
|
usage_counter: Counter for normalization statistics.
|
||||||
|
|
||||||
|
Yields:
|
||||||
|
SegmentResult for each non-empty TTS segment.
|
||||||
|
"""
|
||||||
|
source_text = str(text or "")
|
||||||
|
normalized = prepare_text_for_tts(
|
||||||
|
source_text,
|
||||||
|
heteronym_rules=heteronym_rules,
|
||||||
|
pronunciation_rules=pronunciation_rules,
|
||||||
|
normalization_overrides=normalization_overrides,
|
||||||
|
usage_counter=usage_counter,
|
||||||
|
)
|
||||||
|
|
||||||
|
yield from tts_segments(
|
||||||
|
normalized,
|
||||||
|
backend=backend,
|
||||||
|
voice=voice,
|
||||||
|
speed=speed,
|
||||||
|
split_pattern=split_pattern,
|
||||||
|
current_time=current_time,
|
||||||
|
total_steps=total_steps,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def emit_text_to_sinks(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float,
|
||||||
|
split_pattern: str,
|
||||||
|
current_time: float = 0.0,
|
||||||
|
# sinks
|
||||||
|
audio_sink: Any = None,
|
||||||
|
chapter_sink: Any = None,
|
||||||
|
# subtitle
|
||||||
|
subtitle_writer: Any = None,
|
||||||
|
subtitle_mode: str = "Disabled",
|
||||||
|
subtitle_lang: Language = Language.EN_US,
|
||||||
|
max_subtitle_words: int = 50,
|
||||||
|
use_spacy_segmentation: bool = True,
|
||||||
|
# normalization
|
||||||
|
heteronym_rules: Any = None,
|
||||||
|
pronunciation_rules: Any = None,
|
||||||
|
normalization_overrides: Any = None,
|
||||||
|
usage_counter: Optional[Dict[str, int]] = None,
|
||||||
|
) -> tuple[int, float, List[Dict[str, Any]]]:
|
||||||
|
"""Emit TTS audio for text, writing to sinks and collecting subtitle tokens.
|
||||||
|
|
||||||
|
Convenience wrapper around emit_text_segments() that handles audio writing
|
||||||
|
and token accumulation. Returns stats for the caller to update progress.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (segments_emitted, new_current_time, accumulated_tokens).
|
||||||
|
"""
|
||||||
|
from abogen.domain.subtitle_generation import process_subtitle_tokens
|
||||||
|
|
||||||
|
segments_emitted = 0
|
||||||
|
accumulated_tokens: List[Dict[str, Any]] = []
|
||||||
|
|
||||||
|
for seg in emit_text_segments(
|
||||||
|
text,
|
||||||
|
backend=backend,
|
||||||
|
voice=voice,
|
||||||
|
speed=speed,
|
||||||
|
split_pattern=split_pattern,
|
||||||
|
current_time=current_time,
|
||||||
|
heteronym_rules=heteronym_rules,
|
||||||
|
pronunciation_rules=pronunciation_rules,
|
||||||
|
normalization_overrides=normalization_overrides,
|
||||||
|
usage_counter=usage_counter,
|
||||||
|
):
|
||||||
|
segments_emitted += 1
|
||||||
|
|
||||||
|
# Write audio
|
||||||
|
if chapter_sink:
|
||||||
|
chapter_sink.write(seg.audio)
|
||||||
|
if audio_sink:
|
||||||
|
audio_sink.write(seg.audio)
|
||||||
|
|
||||||
|
# Collect tokens
|
||||||
|
accumulated_tokens.extend(seg.tokens)
|
||||||
|
|
||||||
|
# Flush subtitle tokens
|
||||||
|
if subtitle_writer and accumulated_tokens:
|
||||||
|
_use_spacy = subtitle_mode not in (SubtitleMode.DISABLED, SubtitleMode.LINE)
|
||||||
|
new_entries: List[tuple] = []
|
||||||
|
process_subtitle_tokens(
|
||||||
|
accumulated_tokens,
|
||||||
|
new_entries,
|
||||||
|
max_subtitle_words,
|
||||||
|
subtitle_mode,
|
||||||
|
subtitle_lang,
|
||||||
|
use_spacy_segmentation=_use_spacy,
|
||||||
|
fallback_end_time=current_time + sum(t["end"] - t["start"] for t in accumulated_tokens if accumulated_tokens),
|
||||||
|
)
|
||||||
|
for start, end, text_entry in new_entries:
|
||||||
|
subtitle_writer.write_entry(start=start, end=end, text=text_entry)
|
||||||
|
|
||||||
|
new_time = current_time
|
||||||
|
if accumulated_tokens:
|
||||||
|
new_time = max(t["end"] for t in accumulated_tokens)
|
||||||
|
|
||||||
|
return segments_emitted, new_time, accumulated_tokens
|
||||||
@@ -0,0 +1,31 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import platform as _platform
|
||||||
|
|
||||||
|
|
||||||
|
def select_device() -> str:
|
||||||
|
"""Return the best available compute device (``"mps"``, ``"cuda"``, or ``"cpu"``).
|
||||||
|
|
||||||
|
Checks ``torch`` availability at runtime so this can be called from
|
||||||
|
any context without requiring torch at import time.
|
||||||
|
"""
|
||||||
|
try:
|
||||||
|
import torch # type: ignore[import-not-found]
|
||||||
|
except Exception:
|
||||||
|
return "cpu"
|
||||||
|
|
||||||
|
system = _platform.system()
|
||||||
|
if system == "Darwin" and _platform.processor() == "arm":
|
||||||
|
try:
|
||||||
|
if torch.backends.mps.is_available(): # type: ignore[union-attr]
|
||||||
|
return "mps"
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
return "cpu"
|
||||||
|
|
||||||
|
try:
|
||||||
|
if torch.cuda.is_available(): # type: ignore[union-attr]
|
||||||
|
return "cuda"
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
return "cpu"
|
||||||
@@ -0,0 +1,231 @@
|
|||||||
|
"""Domain enums — typed constants for values tied to business logic.
|
||||||
|
|
||||||
|
Using Enum instead of bare strings ensures:
|
||||||
|
- Invalid values are caught at construction time
|
||||||
|
- IDE autocomplete and type checking work
|
||||||
|
- Adding new values is explicit (must update Enum)
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from enum import Enum
|
||||||
|
from pathlib import Path
|
||||||
|
|
||||||
|
|
||||||
|
class SubtitleMode(str, Enum):
|
||||||
|
"""Subtitle generation mode."""
|
||||||
|
DISABLED = "Disabled"
|
||||||
|
LINE = "Line"
|
||||||
|
SENTENCE = "Sentence"
|
||||||
|
SENTENCE_COMMA = "Sentence + Comma"
|
||||||
|
SENTENCE_HIGHLIGHT = "Sentence + Highlighting"
|
||||||
|
|
||||||
|
@classmethod
|
||||||
|
def from_str(cls, value: str) -> SubtitleMode:
|
||||||
|
"""Parse from user input: case-insensitive, strips whitespace."""
|
||||||
|
normalized = value.strip()
|
||||||
|
for member in cls:
|
||||||
|
if member.value.lower() == normalized.lower():
|
||||||
|
return member
|
||||||
|
raise ValueError(f"Invalid SubtitleMode: {value!r}. Valid: {[m.value for m in cls]}")
|
||||||
|
|
||||||
|
|
||||||
|
class OutputFormat(str, Enum):
|
||||||
|
"""Audio output format."""
|
||||||
|
WAV = "wav"
|
||||||
|
MP3 = "mp3"
|
||||||
|
FLAC = "flac"
|
||||||
|
OPUS = "opus"
|
||||||
|
M4B = "m4b"
|
||||||
|
|
||||||
|
@property
|
||||||
|
def dot_ext(self) -> str:
|
||||||
|
"""File extension with dot: '.wav', '.mp3', etc."""
|
||||||
|
return f".{self.value}"
|
||||||
|
|
||||||
|
@property
|
||||||
|
def is_lossless(self) -> bool:
|
||||||
|
"""True for lossless formats."""
|
||||||
|
return self in (self.WAV, self.FLAC)
|
||||||
|
|
||||||
|
@classmethod
|
||||||
|
def from_str(cls, value: str) -> OutputFormat:
|
||||||
|
"""Parse from user input: strips dot prefix, case-insensitive."""
|
||||||
|
normalized = value.strip().lstrip(".").lower()
|
||||||
|
for member in cls:
|
||||||
|
if member.value == normalized:
|
||||||
|
return member
|
||||||
|
raise ValueError(f"Invalid OutputFormat: {value!r}. Valid: {[m.value for m in cls]}")
|
||||||
|
|
||||||
|
|
||||||
|
class SaveMode(str, Enum):
|
||||||
|
"""Where to save the output file."""
|
||||||
|
SAVE_NEXT_TO_INPUT = "save_next_to_input"
|
||||||
|
SAVE_TO_DESKTOP = "save_to_desktop"
|
||||||
|
CHOOSE_OUTPUT_FOLDER = "choose_output_folder"
|
||||||
|
DEFAULT_OUTPUT = "default_output"
|
||||||
|
CUSTOM_FOLDER = "custom_folder"
|
||||||
|
|
||||||
|
|
||||||
|
class SubtitleFormat(str, Enum):
|
||||||
|
"""Subtitle file format."""
|
||||||
|
SRT = "srt"
|
||||||
|
ASS = "ass"
|
||||||
|
VTT = "vtt"
|
||||||
|
|
||||||
|
@property
|
||||||
|
def dot_ext(self) -> str:
|
||||||
|
"""File extension with dot: '.srt', '.ass'."""
|
||||||
|
return f".{self.value}"
|
||||||
|
|
||||||
|
@classmethod
|
||||||
|
def from_str(cls, value: str) -> SubtitleFormat:
|
||||||
|
"""Parse from user input: strips dot prefix, case-insensitive."""
|
||||||
|
normalized = value.strip().lstrip(".").lower()
|
||||||
|
for member in cls:
|
||||||
|
if member.value == normalized:
|
||||||
|
return member
|
||||||
|
raise ValueError(f"Invalid SubtitleFormat: {value!r}. Valid: {[m.value for m in cls]}")
|
||||||
|
|
||||||
|
|
||||||
|
class InputFormat(str, Enum):
|
||||||
|
"""Input file format."""
|
||||||
|
EPUB = "epub"
|
||||||
|
PDF = "pdf"
|
||||||
|
TXT = "txt"
|
||||||
|
MD = "md"
|
||||||
|
SRT = "srt"
|
||||||
|
ASS = "ass"
|
||||||
|
VTT = "vtt"
|
||||||
|
|
||||||
|
@property
|
||||||
|
def is_book(self) -> bool:
|
||||||
|
"""True for book/document formats (epub, pdf, txt, md)."""
|
||||||
|
return self in (self.EPUB, self.PDF, self.TXT, self.MD)
|
||||||
|
|
||||||
|
@property
|
||||||
|
def is_subtitle(self) -> bool:
|
||||||
|
"""True for subtitle formats (srt, ass, vtt)."""
|
||||||
|
return self in (self.SRT, self.ASS, self.VTT)
|
||||||
|
|
||||||
|
@property
|
||||||
|
def dot_ext(self) -> str:
|
||||||
|
"""File extension with dot: '.epub', '.srt', etc."""
|
||||||
|
return f".{self.value}"
|
||||||
|
|
||||||
|
@classmethod
|
||||||
|
def from_path(cls, path: Path) -> InputFormat:
|
||||||
|
"""Detect format from file path extension."""
|
||||||
|
suffix = path.suffix.lower().lstrip(".")
|
||||||
|
if suffix == "markdown":
|
||||||
|
return cls.MD
|
||||||
|
try:
|
||||||
|
return cls(suffix)
|
||||||
|
except ValueError:
|
||||||
|
raise ValueError(f"Unsupported input format: {path.suffix!r}. Supported: {[m.value for m in cls]}")
|
||||||
|
|
||||||
|
|
||||||
|
class Language(str, Enum):
|
||||||
|
"""TTS language code (ISO 639-1 with region where needed).
|
||||||
|
|
||||||
|
Each engine maps these to its own internal language identifiers.
|
||||||
|
Engines report which languages they support via ``supported_languages()``.
|
||||||
|
"""
|
||||||
|
EN_US = "en-US"
|
||||||
|
EN_GB = "en-GB"
|
||||||
|
ES = "es"
|
||||||
|
FR = "fr"
|
||||||
|
HI = "hi"
|
||||||
|
IT = "it"
|
||||||
|
JA = "ja"
|
||||||
|
PT_BR = "pt-BR"
|
||||||
|
ZH = "zh"
|
||||||
|
AR = "ar"
|
||||||
|
BG = "bg"
|
||||||
|
CS = "cs"
|
||||||
|
DA = "da"
|
||||||
|
DE = "de"
|
||||||
|
EL = "el"
|
||||||
|
ET = "et"
|
||||||
|
FI = "fi"
|
||||||
|
HR = "hr"
|
||||||
|
HU = "hu"
|
||||||
|
ID = "id"
|
||||||
|
KO = "ko"
|
||||||
|
LT = "lt"
|
||||||
|
LV = "lv"
|
||||||
|
NL = "nl"
|
||||||
|
PL = "pl"
|
||||||
|
RO = "ro"
|
||||||
|
RU = "ru"
|
||||||
|
SK = "sk"
|
||||||
|
SL = "sl"
|
||||||
|
SV = "sv"
|
||||||
|
TR = "tr"
|
||||||
|
UK = "uk"
|
||||||
|
VI = "vi"
|
||||||
|
|
||||||
|
@property
|
||||||
|
def display_name(self) -> str:
|
||||||
|
"""Human-readable language name."""
|
||||||
|
_names = {
|
||||||
|
"en-US": "American English",
|
||||||
|
"en-GB": "British English",
|
||||||
|
"es": "Spanish",
|
||||||
|
"fr": "French",
|
||||||
|
"hi": "Hindi",
|
||||||
|
"it": "Italian",
|
||||||
|
"ja": "Japanese",
|
||||||
|
"pt-BR": "Brazilian Portuguese",
|
||||||
|
"zh": "Mandarin Chinese",
|
||||||
|
"ar": "Arabic",
|
||||||
|
"bg": "Bulgarian",
|
||||||
|
"cs": "Czech",
|
||||||
|
"da": "Danish",
|
||||||
|
"de": "German",
|
||||||
|
"el": "Greek",
|
||||||
|
"et": "Estonian",
|
||||||
|
"fi": "Finnish",
|
||||||
|
"hr": "Croatian",
|
||||||
|
"hu": "Hungarian",
|
||||||
|
"id": "Indonesian",
|
||||||
|
"ko": "Korean",
|
||||||
|
"lt": "Lithuanian",
|
||||||
|
"lv": "Latvian",
|
||||||
|
"nl": "Dutch",
|
||||||
|
"pl": "Polish",
|
||||||
|
"ro": "Romanian",
|
||||||
|
"ru": "Russian",
|
||||||
|
"sk": "Slovak",
|
||||||
|
"sl": "Slovenian",
|
||||||
|
"sv": "Swedish",
|
||||||
|
"tr": "Turkish",
|
||||||
|
"uk": "Ukrainian",
|
||||||
|
"vi": "Vietnamese",
|
||||||
|
}
|
||||||
|
return _names[self.value]
|
||||||
|
|
||||||
|
@property
|
||||||
|
def is_cjk(self) -> bool:
|
||||||
|
"""True for CJK languages (Chinese, Japanese, Korean)."""
|
||||||
|
return self in (self.ZH, self.JA, self.KO)
|
||||||
|
|
||||||
|
@property
|
||||||
|
def supports_subtitle_tokens(self) -> bool:
|
||||||
|
"""True if this language supports subtitle generation.
|
||||||
|
|
||||||
|
All languages are supported: languages without per-word timestamped
|
||||||
|
tokens fall back to segment-level fake tokens in the pipeline.
|
||||||
|
"""
|
||||||
|
return True
|
||||||
|
|
||||||
|
@classmethod
|
||||||
|
def from_str(cls, value: str) -> Language:
|
||||||
|
"""Parse from user input: ISO code, case-insensitive."""
|
||||||
|
if isinstance(value, Language):
|
||||||
|
return value
|
||||||
|
normalized = value.strip()
|
||||||
|
for member in cls:
|
||||||
|
if member.value.lower() == normalized.lower():
|
||||||
|
return member
|
||||||
|
raise ValueError(f"Invalid Language: {value!r}. Valid: {[m.value for m in cls]}")
|
||||||
@@ -0,0 +1,136 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Tuple
|
||||||
|
|
||||||
|
from abogen.text_extractor import ExtractedChapter
|
||||||
|
|
||||||
|
|
||||||
|
_SIGNIFICANT_LENGTH_THRESHOLDS: Dict[str, int] = {"epub": 1000, "markdown": 500}
|
||||||
|
_MIN_SHORT_CONTENT: Dict[str, int] = {"epub": 240, "markdown": 160}
|
||||||
|
_STRUCTURAL_KEYWORDS = (
|
||||||
|
"preface",
|
||||||
|
"prologue",
|
||||||
|
"introduction",
|
||||||
|
"foreword",
|
||||||
|
"epilogue",
|
||||||
|
"afterword",
|
||||||
|
"appendix",
|
||||||
|
"acknowledgment",
|
||||||
|
"acknowledgement",
|
||||||
|
)
|
||||||
|
_STRUCTURAL_MIN_LENGTH = 120
|
||||||
|
_MAX_SHORT_CHAPTERS = 2
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ChapterFilterResult:
|
||||||
|
kept: List[ExtractedChapter]
|
||||||
|
skipped: List[Tuple[str, int]]
|
||||||
|
|
||||||
|
|
||||||
|
def infer_file_type(path: Path) -> str:
|
||||||
|
suffix = path.suffix.lower()
|
||||||
|
if suffix == ".epub":
|
||||||
|
return "epub"
|
||||||
|
if suffix in {".md", ".markdown"}:
|
||||||
|
return "markdown"
|
||||||
|
if suffix == ".pdf":
|
||||||
|
return "pdf"
|
||||||
|
if suffix == ".txt":
|
||||||
|
return "text"
|
||||||
|
return suffix.lstrip(".") or "text"
|
||||||
|
|
||||||
|
|
||||||
|
def looks_structural(title: str) -> bool:
|
||||||
|
lowered = title.strip().lower()
|
||||||
|
if not lowered:
|
||||||
|
return False
|
||||||
|
return any(keyword in lowered for keyword in _STRUCTURAL_KEYWORDS)
|
||||||
|
|
||||||
|
|
||||||
|
def chapter_label(file_type: str) -> str:
|
||||||
|
return "chapters" if file_type.lower() in {"epub", "markdown"} else "pages"
|
||||||
|
|
||||||
|
|
||||||
|
def auto_select_relevant_chapters(
|
||||||
|
chapters: List[ExtractedChapter],
|
||||||
|
file_type: str,
|
||||||
|
) -> ChapterFilterResult:
|
||||||
|
if not chapters:
|
||||||
|
return ChapterFilterResult(kept=[], skipped=[])
|
||||||
|
|
||||||
|
normalized = file_type.lower()
|
||||||
|
threshold = _SIGNIFICANT_LENGTH_THRESHOLDS.get(normalized, 0)
|
||||||
|
min_short = _MIN_SHORT_CONTENT.get(normalized, 0)
|
||||||
|
|
||||||
|
kept: List[ExtractedChapter] = []
|
||||||
|
skipped: List[Tuple[str, int]] = []
|
||||||
|
short_kept = 0
|
||||||
|
|
||||||
|
for chapter in chapters:
|
||||||
|
stripped = chapter.text.strip()
|
||||||
|
length = len(stripped)
|
||||||
|
if length == 0:
|
||||||
|
skipped.append((chapter.title, length))
|
||||||
|
continue
|
||||||
|
|
||||||
|
keep = False
|
||||||
|
if threshold == 0:
|
||||||
|
keep = True
|
||||||
|
elif length >= threshold:
|
||||||
|
keep = True
|
||||||
|
elif not kept:
|
||||||
|
keep = True
|
||||||
|
elif min_short and length >= min_short and short_kept < _MAX_SHORT_CHAPTERS:
|
||||||
|
keep = True
|
||||||
|
short_kept += 1
|
||||||
|
elif looks_structural(chapter.title) and length >= _STRUCTURAL_MIN_LENGTH:
|
||||||
|
keep = True
|
||||||
|
|
||||||
|
if keep:
|
||||||
|
kept.append(chapter)
|
||||||
|
else:
|
||||||
|
skipped.append((chapter.title, length))
|
||||||
|
|
||||||
|
if kept:
|
||||||
|
return ChapterFilterResult(kept=kept, skipped=skipped)
|
||||||
|
|
||||||
|
longest_idx = None
|
||||||
|
longest_length = 0
|
||||||
|
for idx, chapter in enumerate(chapters):
|
||||||
|
stripped = chapter.text.strip()
|
||||||
|
if stripped and len(stripped) > longest_length:
|
||||||
|
longest_length = len(stripped)
|
||||||
|
longest_idx = idx
|
||||||
|
|
||||||
|
if longest_idx is not None:
|
||||||
|
longest = chapters[longest_idx]
|
||||||
|
fallback_skipped = [
|
||||||
|
(chapter.title, len(chapter.text.strip()))
|
||||||
|
for idx, chapter in enumerate(chapters)
|
||||||
|
if idx != longest_idx and chapter.text.strip()
|
||||||
|
]
|
||||||
|
return ChapterFilterResult(kept=[longest], skipped=fallback_skipped)
|
||||||
|
|
||||||
|
return ChapterFilterResult(kept=[], skipped=skipped)
|
||||||
|
|
||||||
|
|
||||||
|
def update_metadata_for_chapter_count(
|
||||||
|
metadata: Dict[str, Any], count: int, file_type: str
|
||||||
|
) -> None:
|
||||||
|
if not metadata or count <= 0:
|
||||||
|
return
|
||||||
|
|
||||||
|
label = "Chapters" if file_type.lower() in {"epub", "markdown"} else "Pages"
|
||||||
|
metadata["chapter_count"] = str(count)
|
||||||
|
|
||||||
|
pattern = re.compile(r"\(\d+\s+(Chapters?|Pages?)\)")
|
||||||
|
replacement = f"({count} {label})"
|
||||||
|
for key in ("album", "ALBUM"):
|
||||||
|
value = metadata.get(key)
|
||||||
|
if not isinstance(value, str):
|
||||||
|
continue
|
||||||
|
metadata[key] = pattern.sub(replacement, value)
|
||||||
@@ -0,0 +1,83 @@
|
|||||||
|
"""Intro/outro text building and voice resolution for audiobook conversion.
|
||||||
|
|
||||||
|
Both UIs (WebUI and Desktop) need to:
|
||||||
|
1. Build intro/outro text from book metadata
|
||||||
|
2. Resolve which voice to use for intro/outro synthesis
|
||||||
|
|
||||||
|
This module provides the shared domain logic. The actual TTS synthesis
|
||||||
|
and audio writing remain UI-specific.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Dict, Optional
|
||||||
|
|
||||||
|
from abogen.domain.title_builder import build_title_intro_text, build_outro_text
|
||||||
|
from abogen.domain.voice_resolution import resolve_fallback_voice_spec
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class IntroOutroSpec:
|
||||||
|
"""Resolved intro or outro specification ready for TTS synthesis."""
|
||||||
|
text: str
|
||||||
|
voice_spec: str
|
||||||
|
enabled: bool
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_intro(
|
||||||
|
metadata: Optional[Dict[str, Any]],
|
||||||
|
original_filename: str,
|
||||||
|
read_title_intro: bool,
|
||||||
|
base_voice_spec: str,
|
||||||
|
job_voice: str,
|
||||||
|
voice_cache_keys: list[str],
|
||||||
|
) -> IntroOutroSpec:
|
||||||
|
"""Resolve the intro specification from job settings and metadata.
|
||||||
|
|
||||||
|
Returns an IntroOutroSpec with text and voice_spec populated,
|
||||||
|
or enabled=False if intro is disabled or text cannot be built.
|
||||||
|
"""
|
||||||
|
if not read_title_intro:
|
||||||
|
return IntroOutroSpec(text="", voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
text = build_title_intro_text(metadata, original_filename)
|
||||||
|
if not text:
|
||||||
|
return IntroOutroSpec(text="", voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
voice_spec = resolve_fallback_voice_spec(
|
||||||
|
base_voice_spec, job_voice, voice_cache_keys
|
||||||
|
)
|
||||||
|
if not voice_spec:
|
||||||
|
return IntroOutroSpec(text=text, voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
return IntroOutroSpec(text=text, voice_spec=voice_spec, enabled=True)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_outro(
|
||||||
|
metadata: Optional[Dict[str, Any]],
|
||||||
|
original_filename: str,
|
||||||
|
read_closing_outro: bool,
|
||||||
|
base_voice_spec: str,
|
||||||
|
job_voice: str,
|
||||||
|
voice_cache_keys: list[str],
|
||||||
|
) -> IntroOutroSpec:
|
||||||
|
"""Resolve the outro specification from job settings and metadata.
|
||||||
|
|
||||||
|
Returns an IntroOutroSpec with text and voice_spec populated,
|
||||||
|
or enabled=False if outro is disabled or text cannot be built.
|
||||||
|
"""
|
||||||
|
if not read_closing_outro:
|
||||||
|
return IntroOutroSpec(text="", voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
text = build_outro_text(metadata, original_filename)
|
||||||
|
if not text:
|
||||||
|
return IntroOutroSpec(text="", voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
voice_spec = resolve_fallback_voice_spec(
|
||||||
|
base_voice_spec, job_voice, voice_cache_keys
|
||||||
|
)
|
||||||
|
if not voice_spec:
|
||||||
|
return IntroOutroSpec(text=text, voice_spec="", enabled=False)
|
||||||
|
|
||||||
|
return IntroOutroSpec(text=text, voice_spec=voice_spec, enabled=True)
|
||||||
@@ -0,0 +1,503 @@
|
|||||||
|
"""Metadata extraction and processing utilities.
|
||||||
|
|
||||||
|
This module provides functions for extracting metadata from text content,
|
||||||
|
formatting metadata tags for TTS embedding, and generating ffmpeg metadata arguments.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import datetime
|
||||||
|
import logging
|
||||||
|
import os
|
||||||
|
import re
|
||||||
|
import uuid
|
||||||
|
from typing import Any, Dict, List, Optional, Tuple
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
|
||||||
|
def extract_metadata_from_text(text: str) -> Dict[str, Optional[str]]:
|
||||||
|
"""Extract metadata tags from text content.
|
||||||
|
|
||||||
|
Looks for tags in format: <<METADATA_KEY:value>>
|
||||||
|
|
||||||
|
Supported tags:
|
||||||
|
- TITLE, ARTIST, ALBUM, YEAR
|
||||||
|
- ALBUM_ARTIST, COMPOSER, GENRE
|
||||||
|
- COVER_PATH
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Text content to search for metadata tags.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Dictionary with extracted metadata values (None if not found).
|
||||||
|
"""
|
||||||
|
metadata = {}
|
||||||
|
|
||||||
|
patterns = {
|
||||||
|
"title": r"<<METADATA_TITLE:([^>]*)>>",
|
||||||
|
"artist": r"<<METADATA_ARTIST:([^>]*)>>",
|
||||||
|
"album": r"<<METADATA_ALBUM:([^>]*)>>",
|
||||||
|
"year": r"<<METADATA_YEAR:([^>]*)>>",
|
||||||
|
"album_artist": r"<<METADATA_ALBUM_ARTIST:([^>]*)>>",
|
||||||
|
"composer": r"<<METADATA_COMPOSER:([^>]*)>>",
|
||||||
|
"genre": r"<<METADATA_GENRE:([^>]*)>>",
|
||||||
|
"cover_path": r"<<METADATA_COVER_PATH:([^>]*)>>",
|
||||||
|
}
|
||||||
|
|
||||||
|
for key, pattern in patterns.items():
|
||||||
|
match = re.search(pattern, text)
|
||||||
|
if match:
|
||||||
|
metadata[key] = match.group(1).strip()
|
||||||
|
else:
|
||||||
|
metadata[key] = None
|
||||||
|
|
||||||
|
return metadata
|
||||||
|
|
||||||
|
|
||||||
|
def get_filename_from_path(
|
||||||
|
file_path: str,
|
||||||
|
display_path: Optional[str] = None,
|
||||||
|
from_queue: bool = False,
|
||||||
|
) -> str:
|
||||||
|
"""Extract filename (without extension) from path.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
file_path: The file path to extract from.
|
||||||
|
display_path: Optional display path (used if from_queue is False).
|
||||||
|
from_queue: Whether the file is from queue.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Filename without extension.
|
||||||
|
"""
|
||||||
|
if from_queue:
|
||||||
|
base_path = file_path
|
||||||
|
else:
|
||||||
|
base_path = display_path if display_path else file_path
|
||||||
|
|
||||||
|
filename = os.path.splitext(os.path.basename(base_path))[0]
|
||||||
|
return filename
|
||||||
|
|
||||||
|
|
||||||
|
def build_ffmpeg_metadata_args(
|
||||||
|
metadata: Dict[str, Optional[str]],
|
||||||
|
filename: str,
|
||||||
|
) -> List[str]:
|
||||||
|
"""Build ffmpeg metadata arguments from metadata dictionary.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
metadata: Dictionary with metadata keys and values.
|
||||||
|
filename: Fallback filename for title/album if not specified.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
List of ffmpeg metadata arguments.
|
||||||
|
"""
|
||||||
|
args = []
|
||||||
|
|
||||||
|
# Default values
|
||||||
|
defaults = {
|
||||||
|
"title": filename,
|
||||||
|
"artist": "Unknown",
|
||||||
|
"album": filename,
|
||||||
|
"date": str(datetime.datetime.now().year),
|
||||||
|
"album_artist": "Unknown",
|
||||||
|
"composer": "Narrator",
|
||||||
|
"genre": "Audiobook",
|
||||||
|
}
|
||||||
|
|
||||||
|
# Map of metadata keys to ffmpeg metadata keys
|
||||||
|
key_mapping = {
|
||||||
|
"title": "title",
|
||||||
|
"artist": "artist",
|
||||||
|
"album": "album",
|
||||||
|
"year": "date", # year -> date for ffmpeg
|
||||||
|
"album_artist": "album_artist",
|
||||||
|
"composer": "composer",
|
||||||
|
"genre": "genre",
|
||||||
|
}
|
||||||
|
|
||||||
|
for metadata_key, ffmpeg_key in key_mapping.items():
|
||||||
|
value = metadata.get(metadata_key)
|
||||||
|
if value is None:
|
||||||
|
value = defaults.get(metadata_key, "")
|
||||||
|
if value:
|
||||||
|
args.extend(["-metadata", f"{ffmpeg_key}={value}"])
|
||||||
|
|
||||||
|
return args
|
||||||
|
|
||||||
|
|
||||||
|
def extract_metadata_and_build_args(
|
||||||
|
text: str,
|
||||||
|
filename: str,
|
||||||
|
display_path: Optional[str] = None,
|
||||||
|
from_queue: bool = False,
|
||||||
|
) -> Tuple[List[str], Optional[str]]:
|
||||||
|
"""Extract metadata from text and build ffmpeg arguments.
|
||||||
|
|
||||||
|
Convenience function that combines extract_metadata_from_text and
|
||||||
|
build_ffmpeg_metadata_args.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Text content to search for metadata tags.
|
||||||
|
filename: Fallback filename for title/album.
|
||||||
|
display_path: Optional display path.
|
||||||
|
from_queue: Whether the file is from queue.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (ffmpeg_metadata_args, cover_path).
|
||||||
|
"""
|
||||||
|
metadata = extract_metadata_from_text(text)
|
||||||
|
cover_path = metadata.get("cover_path")
|
||||||
|
|
||||||
|
# Get actual filename from path
|
||||||
|
actual_filename = get_filename_from_path(
|
||||||
|
file_path=filename,
|
||||||
|
display_path=display_path,
|
||||||
|
from_queue=from_queue,
|
||||||
|
)
|
||||||
|
|
||||||
|
args = build_ffmpeg_metadata_args(metadata, actual_filename)
|
||||||
|
return args, cover_path
|
||||||
|
|
||||||
|
|
||||||
|
def read_text_for_metadata(
|
||||||
|
file_path: str,
|
||||||
|
is_direct_text: bool,
|
||||||
|
direct_text: Optional[str] = None,
|
||||||
|
encoding: Optional[str] = None,
|
||||||
|
) -> str:
|
||||||
|
"""Read text content for metadata extraction.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
file_path: Path to file (or text if is_direct_text).
|
||||||
|
is_direct_text: Whether file_path contains direct text.
|
||||||
|
direct_text: Optional direct text (used if is_direct_text).
|
||||||
|
encoding: File encoding (detected if not provided).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Text content for metadata extraction.
|
||||||
|
"""
|
||||||
|
if is_direct_text:
|
||||||
|
return direct_text or file_path
|
||||||
|
|
||||||
|
# Read from file
|
||||||
|
actual_path = direct_text if direct_text else file_path
|
||||||
|
|
||||||
|
try:
|
||||||
|
if encoding is None:
|
||||||
|
from abogen.utils import detect_encoding
|
||||||
|
encoding = detect_encoding(actual_path)
|
||||||
|
|
||||||
|
with open(actual_path, "r", encoding=encoding, errors="replace") as f:
|
||||||
|
return f.read()
|
||||||
|
except Exception:
|
||||||
|
return ""
|
||||||
|
|
||||||
|
|
||||||
|
def extract_metadata_for_file(
|
||||||
|
file_path: str,
|
||||||
|
is_direct_text: bool = False,
|
||||||
|
) -> Dict[str, Optional[str]]:
|
||||||
|
"""Extract metadata dict from a file or direct text.
|
||||||
|
|
||||||
|
Convenience function combining read_text_for_metadata + extract_metadata_from_text.
|
||||||
|
Returns empty dict on any error.
|
||||||
|
"""
|
||||||
|
try:
|
||||||
|
text = read_text_for_metadata(
|
||||||
|
file_path=file_path,
|
||||||
|
is_direct_text=is_direct_text,
|
||||||
|
direct_text=file_path if is_direct_text else None,
|
||||||
|
)
|
||||||
|
if text:
|
||||||
|
return extract_metadata_from_text(text) or {}
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
return {}
|
||||||
|
|
||||||
|
|
||||||
|
def format_metadata_tags(
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
filename: str,
|
||||||
|
chapter_count: int,
|
||||||
|
file_type: str,
|
||||||
|
cover_bytes: Optional[bytes] = None,
|
||||||
|
cache_dir: Optional[str] = None,
|
||||||
|
) -> str:
|
||||||
|
"""Format metadata tags for insertion into TTS text.
|
||||||
|
|
||||||
|
Builds <<METADATA_KEY:value>> tags that are later parsed by
|
||||||
|
extract_metadata_from_text() and fed to ffmpeg.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
metadata: Dict with keys like 'title', 'authors' (list),
|
||||||
|
'publication_year', 'description', 'cover_image' (bytes).
|
||||||
|
filename: Fallback filename (without extension) for title/album.
|
||||||
|
chapter_count: Number of chapters/pages.
|
||||||
|
file_type: 'epub', 'pdf', or 'markdown'.
|
||||||
|
cover_bytes: Optional cover image bytes to save to cache.
|
||||||
|
cache_dir: Directory for cover cache (uses default if None).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Newline-joined string of <<METADATA_KEY:value>> tags.
|
||||||
|
"""
|
||||||
|
title = metadata.get("title") or filename
|
||||||
|
authors = metadata.get("authors") or ["Unknown"]
|
||||||
|
authors_text = ", ".join(authors) if isinstance(authors, list) else str(authors)
|
||||||
|
year = metadata.get("publication_year") or str(datetime.datetime.now().year)
|
||||||
|
|
||||||
|
chapter_label = "Chapters" if file_type in ("epub", "markdown") else "Pages"
|
||||||
|
chapter_text = f"{chapter_count} {chapter_label}"
|
||||||
|
|
||||||
|
tags = [
|
||||||
|
f"<<METADATA_TITLE:{title}>>",
|
||||||
|
f"<<METADATA_ARTIST:{authors_text}>>",
|
||||||
|
f"<<METADATA_ALBUM:{title} ({chapter_text})>>",
|
||||||
|
f"<<METADATA_YEAR:{year}>>",
|
||||||
|
f"<<METADATA_ALBUM_ARTIST:{authors_text}>>",
|
||||||
|
f"<<METADATA_COMPOSER:Narrator>>",
|
||||||
|
f"<<METADATA_GENRE:Audiobook>>",
|
||||||
|
]
|
||||||
|
|
||||||
|
cover_path = _save_cover_to_cache(cover_bytes, cache_dir)
|
||||||
|
if cover_path:
|
||||||
|
tags.append(f"<<METADATA_COVER_PATH:{cover_path}>>")
|
||||||
|
|
||||||
|
return "\n".join(tags)
|
||||||
|
|
||||||
|
|
||||||
|
def _save_cover_to_cache(
|
||||||
|
cover_bytes: Optional[bytes],
|
||||||
|
cache_dir: Optional[str] = None,
|
||||||
|
) -> Optional[str]:
|
||||||
|
"""Save cover image bytes to cache directory.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
cover_bytes: Raw image bytes (e.g. JPEG/PNG).
|
||||||
|
cache_dir: Directory to save to. If None, returns None.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Normalized path to saved cover file, or None on failure.
|
||||||
|
"""
|
||||||
|
if not cover_bytes:
|
||||||
|
return None
|
||||||
|
if cache_dir is None:
|
||||||
|
return None
|
||||||
|
|
||||||
|
try:
|
||||||
|
cover_path = os.path.join(cache_dir, f"cover_{uuid.uuid4()}.jpg")
|
||||||
|
cover_path = os.path.normpath(cover_path)
|
||||||
|
with open(cover_path, "wb") as f:
|
||||||
|
f.write(cover_bytes)
|
||||||
|
return cover_path
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Failed to save cover image: %s", e)
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def extract_book_metadata_epub(book: Any) -> Dict[str, Any]:
|
||||||
|
"""Extract metadata from an opened ebooklib EPUB book.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
book: An opened ebooklib EPUB book object.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Dict with keys: title, authors, description, publisher,
|
||||||
|
publication_year, cover_image (bytes or None).
|
||||||
|
"""
|
||||||
|
import ebooklib
|
||||||
|
|
||||||
|
metadata: Dict[str, Any] = {
|
||||||
|
"title": None,
|
||||||
|
"authors": [],
|
||||||
|
"description": None,
|
||||||
|
"cover_image": None,
|
||||||
|
"publisher": None,
|
||||||
|
"publication_year": None,
|
||||||
|
}
|
||||||
|
|
||||||
|
try:
|
||||||
|
title_items = book.get_metadata("DC", "title")
|
||||||
|
if title_items and len(title_items) > 0:
|
||||||
|
metadata["title"] = title_items[0][0]
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error extracting title metadata: %s", e)
|
||||||
|
|
||||||
|
try:
|
||||||
|
author_items = book.get_metadata("DC", "creator")
|
||||||
|
if author_items:
|
||||||
|
metadata["authors"] = [
|
||||||
|
author[0] for author in author_items if len(author) > 0
|
||||||
|
]
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error extracting author metadata: %s", e)
|
||||||
|
|
||||||
|
try:
|
||||||
|
desc_items = book.get_metadata("DC", "description")
|
||||||
|
if desc_items and len(desc_items) > 0:
|
||||||
|
metadata["description"] = desc_items[0][0]
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error extracting description metadata: %s", e)
|
||||||
|
|
||||||
|
try:
|
||||||
|
publisher_items = book.get_metadata("DC", "publisher")
|
||||||
|
if publisher_items and len(publisher_items) > 0:
|
||||||
|
metadata["publisher"] = publisher_items[0][0]
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error extracting publisher metadata: %s", e)
|
||||||
|
|
||||||
|
try:
|
||||||
|
date_items = book.get_metadata("DC", "date")
|
||||||
|
if date_items and len(date_items) > 0:
|
||||||
|
date_str = date_items[0][0]
|
||||||
|
year_match = re.search(r"\b(19|20)\d{2}\b", date_str)
|
||||||
|
if year_match:
|
||||||
|
metadata["publication_year"] = year_match.group(0)
|
||||||
|
else:
|
||||||
|
metadata["publication_year"] = date_str
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error extracting publication date metadata: %s", e)
|
||||||
|
|
||||||
|
for item in book.get_items_of_type(ebooklib.ITEM_COVER):
|
||||||
|
metadata["cover_image"] = item.get_content()
|
||||||
|
break
|
||||||
|
|
||||||
|
if not metadata["cover_image"]:
|
||||||
|
for item in book.get_items_of_type(ebooklib.ITEM_IMAGE):
|
||||||
|
if "cover" in item.get_name().lower():
|
||||||
|
metadata["cover_image"] = item.get_content()
|
||||||
|
break
|
||||||
|
|
||||||
|
return metadata
|
||||||
|
|
||||||
|
|
||||||
|
def extract_book_metadata_pdf(pdf_doc: Any) -> Dict[str, Any]:
|
||||||
|
"""Extract metadata from an opened PyMuPDF document.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
pdf_doc: An opened fitz.Document object.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Dict with keys: title, authors, description, publisher,
|
||||||
|
publication_year, cover_image (bytes or None).
|
||||||
|
"""
|
||||||
|
metadata: Dict[str, Any] = {
|
||||||
|
"title": None,
|
||||||
|
"authors": [],
|
||||||
|
"description": None,
|
||||||
|
"cover_image": None,
|
||||||
|
"publisher": None,
|
||||||
|
"publication_year": None,
|
||||||
|
}
|
||||||
|
|
||||||
|
pdf_info = pdf_doc.metadata
|
||||||
|
if pdf_info:
|
||||||
|
metadata["title"] = pdf_info.get("title", None)
|
||||||
|
author = pdf_info.get("author", None)
|
||||||
|
if author:
|
||||||
|
metadata["authors"] = [author]
|
||||||
|
metadata["description"] = pdf_info.get("subject", None)
|
||||||
|
keywords = pdf_info.get("keywords", None)
|
||||||
|
if keywords:
|
||||||
|
if metadata["description"]:
|
||||||
|
metadata["description"] += f"\n\nKeywords: {keywords}"
|
||||||
|
else:
|
||||||
|
metadata["description"] = f"Keywords: {keywords}"
|
||||||
|
metadata["publisher"] = pdf_info.get("creator", None)
|
||||||
|
|
||||||
|
if "creationDate" in pdf_info:
|
||||||
|
date_str = pdf_info["creationDate"]
|
||||||
|
year_match = re.search(r"D:(\d{4})", date_str)
|
||||||
|
if year_match:
|
||||||
|
metadata["publication_year"] = year_match.group(1)
|
||||||
|
elif "modDate" in pdf_info:
|
||||||
|
date_str = pdf_info["modDate"]
|
||||||
|
year_match = re.search(r"D:(\d{4})", date_str)
|
||||||
|
if year_match:
|
||||||
|
metadata["publication_year"] = year_match.group(1)
|
||||||
|
|
||||||
|
if len(pdf_doc) > 0:
|
||||||
|
try:
|
||||||
|
import fitz
|
||||||
|
pix = pdf_doc[0].get_pixmap(matrix=fitz.Matrix(2, 2))
|
||||||
|
metadata["cover_image"] = pix.tobytes("png")
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
return metadata
|
||||||
|
|
||||||
|
|
||||||
|
def extract_book_metadata_markdown(
|
||||||
|
markdown_text: str,
|
||||||
|
markdown_toc: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
"""Extract metadata from markdown frontmatter and first heading.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
markdown_text: Raw markdown text content.
|
||||||
|
markdown_toc: Optional table of contents list (each item has
|
||||||
|
'level' and 'name' keys).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Dict with keys: title, authors, description, publication_year.
|
||||||
|
cover_image is always None for markdown.
|
||||||
|
"""
|
||||||
|
metadata: Dict[str, Any] = {
|
||||||
|
"title": None,
|
||||||
|
"authors": [],
|
||||||
|
"description": None,
|
||||||
|
"cover_image": None,
|
||||||
|
"publisher": None,
|
||||||
|
"publication_year": None,
|
||||||
|
}
|
||||||
|
|
||||||
|
if not markdown_text:
|
||||||
|
return metadata
|
||||||
|
|
||||||
|
frontmatter_match = re.match(
|
||||||
|
r"^---\s*\n(.*?)\n---\s*\n", markdown_text, re.DOTALL
|
||||||
|
)
|
||||||
|
if frontmatter_match:
|
||||||
|
try:
|
||||||
|
frontmatter = frontmatter_match.group(1)
|
||||||
|
title_match = re.search(
|
||||||
|
r"^title:\s*(.+)$", frontmatter, re.MULTILINE | re.IGNORECASE
|
||||||
|
)
|
||||||
|
if title_match:
|
||||||
|
metadata["title"] = title_match.group(1).strip().strip("\"'")
|
||||||
|
|
||||||
|
author_match = re.search(
|
||||||
|
r"^author:\s*(.+)$", frontmatter, re.MULTILINE | re.IGNORECASE
|
||||||
|
)
|
||||||
|
if author_match:
|
||||||
|
metadata["authors"] = [
|
||||||
|
author_match.group(1).strip().strip("\"'")
|
||||||
|
]
|
||||||
|
|
||||||
|
desc_match = re.search(
|
||||||
|
r"^description:\s*(.+)$", frontmatter, re.MULTILINE | re.IGNORECASE
|
||||||
|
)
|
||||||
|
if desc_match:
|
||||||
|
metadata["description"] = (
|
||||||
|
desc_match.group(1).strip().strip("\"'")
|
||||||
|
)
|
||||||
|
|
||||||
|
date_match = re.search(
|
||||||
|
r"^date:\s*(.+)$", frontmatter, re.MULTILINE | re.IGNORECASE
|
||||||
|
)
|
||||||
|
if date_match:
|
||||||
|
date_str = date_match.group(1).strip().strip("\"'")
|
||||||
|
year_match = re.search(r"\b(19|20)\d{2}\b", date_str)
|
||||||
|
if year_match:
|
||||||
|
metadata["publication_year"] = year_match.group(0)
|
||||||
|
except Exception as e:
|
||||||
|
logger.warning("Error parsing markdown frontmatter: %s", e)
|
||||||
|
|
||||||
|
if not metadata["title"] and markdown_toc:
|
||||||
|
first_h1 = next(
|
||||||
|
(h for h in markdown_toc if h.get("level") == 1), None
|
||||||
|
)
|
||||||
|
if first_h1:
|
||||||
|
metadata["title"] = first_h1.get("name")
|
||||||
|
|
||||||
|
return metadata
|
||||||
@@ -0,0 +1,496 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import json
|
||||||
|
import math
|
||||||
|
import re
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Mapping, Optional, Tuple
|
||||||
|
|
||||||
|
|
||||||
|
_SERIES_NAME_KEYS = (
|
||||||
|
"series",
|
||||||
|
"series_name",
|
||||||
|
"series_title",
|
||||||
|
)
|
||||||
|
_SERIES_NUMBER_KEYS = (
|
||||||
|
"series_index",
|
||||||
|
"series_position",
|
||||||
|
"series_sequence",
|
||||||
|
"book_number",
|
||||||
|
"series_number",
|
||||||
|
)
|
||||||
|
_SERIES_NUMBER_RE = re.compile(r"\d+(?:\.\d+)?")
|
||||||
|
|
||||||
|
_SERIES_NAME_ALIASES = ("series", "series_name", "seriesname", "series_title", "seriestitle")
|
||||||
|
_SERIES_INDEX_ALIASES = ("series_index", "series_sequence", "series_position", "book_number")
|
||||||
|
_AUTHOR_ALIASES = ("author", "authors")
|
||||||
|
_DESCRIPTION_ALIASES = ("description", "summary")
|
||||||
|
_TAGS_ALIASES = ("tags", "keywords", "genre")
|
||||||
|
|
||||||
|
|
||||||
|
def expand_metadata_aliases(tags: Mapping[str, Any]) -> Dict[str, Any]:
|
||||||
|
"""Expand concept aliases so each concept has all canonical keys set.
|
||||||
|
|
||||||
|
One input concept fans out to multiple keys so that downstream consumers
|
||||||
|
can look up any variant and find the value.
|
||||||
|
|
||||||
|
Expanded concepts:
|
||||||
|
series -> series, series_name, seriesname, series_title, seriestitle
|
||||||
|
series_index -> series_index, series_sequence, series_position, book_number
|
||||||
|
author -> author, authors
|
||||||
|
description -> description, summary
|
||||||
|
tags -> tags, keywords, genre
|
||||||
|
"""
|
||||||
|
if not tags:
|
||||||
|
return {}
|
||||||
|
|
||||||
|
result: Dict[str, Any] = {}
|
||||||
|
for key, value in tags.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
text = str(value).strip() if not isinstance(value, (list, tuple, set)) else value
|
||||||
|
if not text:
|
||||||
|
continue
|
||||||
|
key_lower = str(key).strip().lower()
|
||||||
|
if not key_lower:
|
||||||
|
continue
|
||||||
|
|
||||||
|
if key_lower in _SERIES_NAME_ALIASES:
|
||||||
|
for alias in _SERIES_NAME_ALIASES:
|
||||||
|
result[alias] = text
|
||||||
|
elif key_lower in _SERIES_INDEX_ALIASES:
|
||||||
|
for alias in _SERIES_INDEX_ALIASES:
|
||||||
|
result[alias] = text
|
||||||
|
elif key_lower in _AUTHOR_ALIASES:
|
||||||
|
for alias in _AUTHOR_ALIASES:
|
||||||
|
result[alias] = text
|
||||||
|
elif key_lower in _DESCRIPTION_ALIASES:
|
||||||
|
for alias in _DESCRIPTION_ALIASES:
|
||||||
|
result[alias] = text
|
||||||
|
elif key_lower in _TAGS_ALIASES:
|
||||||
|
for alias in _TAGS_ALIASES:
|
||||||
|
result[alias] = text
|
||||||
|
else:
|
||||||
|
result[key_lower] = text
|
||||||
|
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_metadata_map(values: Optional[Mapping[str, Any]]) -> Dict[str, str]:
|
||||||
|
normalized: Dict[str, str] = {}
|
||||||
|
if not values:
|
||||||
|
return normalized
|
||||||
|
for key, value in values.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
text = str(value).strip()
|
||||||
|
if not text:
|
||||||
|
continue
|
||||||
|
normalized[str(key).casefold()] = text
|
||||||
|
return normalized
|
||||||
|
|
||||||
|
|
||||||
|
def format_author_sentence(raw: Optional[str]) -> str:
|
||||||
|
if raw is None:
|
||||||
|
return ""
|
||||||
|
normalized = str(raw).strip()
|
||||||
|
if not normalized:
|
||||||
|
return ""
|
||||||
|
lowered = normalized.casefold()
|
||||||
|
if lowered in {"unknown", "various"}:
|
||||||
|
return ""
|
||||||
|
|
||||||
|
working = normalized.replace("&", " and ")
|
||||||
|
segments = [segment.strip() for segment in working.split(",") if segment.strip()]
|
||||||
|
tokens: List[str] = []
|
||||||
|
|
||||||
|
if segments:
|
||||||
|
for segment in segments:
|
||||||
|
parts = [part.strip() for part in re.split(r"\band\b", segment, flags=re.IGNORECASE) if part.strip()]
|
||||||
|
if parts:
|
||||||
|
tokens.extend(parts)
|
||||||
|
else:
|
||||||
|
tokens.append(segment)
|
||||||
|
else:
|
||||||
|
parts = [part.strip() for part in re.split(r"\band\b", working, flags=re.IGNORECASE) if part.strip()]
|
||||||
|
tokens.extend(parts or [normalized])
|
||||||
|
|
||||||
|
cleaned = [token for token in tokens if token and token.casefold() not in {"unknown", "various"}]
|
||||||
|
if not cleaned:
|
||||||
|
return ""
|
||||||
|
if len(cleaned) == 1:
|
||||||
|
return f"By {cleaned[0]}"
|
||||||
|
if len(cleaned) == 2:
|
||||||
|
return f"By {cleaned[0]} and {cleaned[1]}"
|
||||||
|
return f"By {', '.join(cleaned[:-1])}, and {cleaned[-1]}"
|
||||||
|
|
||||||
|
|
||||||
|
def ensure_sentence(text: str) -> str:
|
||||||
|
cleaned = text.strip()
|
||||||
|
if not cleaned:
|
||||||
|
return ""
|
||||||
|
if cleaned[-1] in ".!?":
|
||||||
|
return cleaned
|
||||||
|
return f"{cleaned}."
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_series_number(value: Any) -> Optional[str]:
|
||||||
|
text = str(value or "").strip()
|
||||||
|
if not text:
|
||||||
|
return None
|
||||||
|
candidate = text.replace(",", ".")
|
||||||
|
if candidate.replace(".", "", 1).isdigit():
|
||||||
|
if "." in candidate:
|
||||||
|
normalized = candidate.rstrip("0").rstrip(".")
|
||||||
|
return normalized or "0"
|
||||||
|
try:
|
||||||
|
return str(int(candidate))
|
||||||
|
except ValueError:
|
||||||
|
pass
|
||||||
|
match = _SERIES_NUMBER_RE.search(candidate)
|
||||||
|
if not match:
|
||||||
|
return None
|
||||||
|
normalized = match.group(0)
|
||||||
|
if "." in normalized:
|
||||||
|
normalized = normalized.rstrip("0").rstrip(".")
|
||||||
|
return normalized or "0"
|
||||||
|
try:
|
||||||
|
return str(int(normalized))
|
||||||
|
except ValueError:
|
||||||
|
return normalized
|
||||||
|
|
||||||
|
|
||||||
|
def extract_series_metadata(values: Mapping[str, str]) -> Tuple[Optional[str], Optional[str]]:
|
||||||
|
series_name: Optional[str] = None
|
||||||
|
for key in _SERIES_NAME_KEYS:
|
||||||
|
raw = values.get(key)
|
||||||
|
if raw:
|
||||||
|
cleaned = str(raw).strip()
|
||||||
|
if cleaned:
|
||||||
|
series_name = cleaned
|
||||||
|
break
|
||||||
|
|
||||||
|
series_number: Optional[str] = None
|
||||||
|
for key in _SERIES_NUMBER_KEYS:
|
||||||
|
raw = values.get(key)
|
||||||
|
if raw is None:
|
||||||
|
continue
|
||||||
|
normalized = normalize_series_number(raw)
|
||||||
|
if normalized:
|
||||||
|
series_number = normalized
|
||||||
|
break
|
||||||
|
|
||||||
|
return series_name, series_number
|
||||||
|
|
||||||
|
|
||||||
|
def format_series_sentence(series_name: Optional[str], series_number: Optional[str]) -> str:
|
||||||
|
if not series_name or not series_number:
|
||||||
|
return ""
|
||||||
|
name = series_name.strip()
|
||||||
|
number = series_number.strip()
|
||||||
|
if not name or not number:
|
||||||
|
return ""
|
||||||
|
article = "the " if not name.lower().startswith("the ") else ""
|
||||||
|
phrase = f"Book {number} of {article}{name}"
|
||||||
|
return re.sub(r"\s+", " ", phrase).strip()
|
||||||
|
|
||||||
|
|
||||||
|
_PEOPLE_SPLIT_RE = re.compile(r"[;,/&]|\band\b", re.IGNORECASE)
|
||||||
|
_LIST_SPLIT_RE = re.compile(r"[;,\n]")
|
||||||
|
_SERIES_SEQUENCE_TAG_KEYS: Tuple[str, ...] = (
|
||||||
|
"series_index",
|
||||||
|
"series_position",
|
||||||
|
"series_sequence",
|
||||||
|
"series_number",
|
||||||
|
"seriesnumber",
|
||||||
|
"book_number",
|
||||||
|
"booknumber",
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_metadata_casefold(values: Optional[Mapping[str, Any]]) -> Dict[str, Any]:
|
||||||
|
normalized: Dict[str, Any] = {}
|
||||||
|
if not values:
|
||||||
|
return normalized
|
||||||
|
for key, value in values.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
key_text = str(key).strip().lower()
|
||||||
|
if not key_text:
|
||||||
|
continue
|
||||||
|
if isinstance(value, (list, tuple, set)):
|
||||||
|
normalized[key_text] = value
|
||||||
|
else:
|
||||||
|
text = str(value).strip()
|
||||||
|
if text:
|
||||||
|
normalized[key_text] = text
|
||||||
|
return normalized
|
||||||
|
|
||||||
|
|
||||||
|
def split_people_field(raw: Any) -> List[str]:
|
||||||
|
if raw is None:
|
||||||
|
return []
|
||||||
|
if isinstance(raw, (list, tuple, set)):
|
||||||
|
results: List[str] = []
|
||||||
|
for item in raw:
|
||||||
|
results.extend(split_people_field(item))
|
||||||
|
return results
|
||||||
|
text = str(raw or "").strip()
|
||||||
|
if not text:
|
||||||
|
return []
|
||||||
|
tokens = [_token.strip() for _token in _PEOPLE_SPLIT_RE.split(text) if _token.strip()]
|
||||||
|
seen: set[str] = set()
|
||||||
|
ordered: List[str] = []
|
||||||
|
for token in tokens:
|
||||||
|
key = token.casefold()
|
||||||
|
if key in seen:
|
||||||
|
continue
|
||||||
|
seen.add(key)
|
||||||
|
ordered.append(token)
|
||||||
|
return ordered
|
||||||
|
|
||||||
|
|
||||||
|
def split_simple_list(raw: Any) -> List[str]:
|
||||||
|
if raw is None:
|
||||||
|
return []
|
||||||
|
if isinstance(raw, (list, tuple, set)):
|
||||||
|
results: List[str] = []
|
||||||
|
for item in raw:
|
||||||
|
results.extend(split_simple_list(item))
|
||||||
|
return results
|
||||||
|
text = str(raw or "").strip()
|
||||||
|
if not text:
|
||||||
|
return []
|
||||||
|
tokens = [_token.strip() for _token in _LIST_SPLIT_RE.split(text) if _token.strip()]
|
||||||
|
seen: set[str] = set()
|
||||||
|
ordered: List[str] = []
|
||||||
|
for token in tokens:
|
||||||
|
key = token.casefold()
|
||||||
|
if key in seen:
|
||||||
|
continue
|
||||||
|
seen.add(key)
|
||||||
|
ordered.append(token)
|
||||||
|
return ordered
|
||||||
|
|
||||||
|
|
||||||
|
def first_nonempty(*values: Any) -> Optional[str]:
|
||||||
|
for value in values:
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
if isinstance(value, (list, tuple, set)):
|
||||||
|
items = list(value)
|
||||||
|
if not items:
|
||||||
|
continue
|
||||||
|
value = items[0]
|
||||||
|
text = str(value).strip()
|
||||||
|
if text:
|
||||||
|
return text
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def extract_year(raw: Optional[str]) -> Optional[int]:
|
||||||
|
if not raw:
|
||||||
|
return None
|
||||||
|
text = str(raw).strip()
|
||||||
|
if not text:
|
||||||
|
return None
|
||||||
|
match = re.search(r"(19|20)\d{2}", text)
|
||||||
|
if match:
|
||||||
|
try:
|
||||||
|
return int(match.group(0))
|
||||||
|
except ValueError:
|
||||||
|
return None
|
||||||
|
try:
|
||||||
|
parsed = int(text)
|
||||||
|
except ValueError:
|
||||||
|
return None
|
||||||
|
if 0 < parsed < 3000:
|
||||||
|
return parsed
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_series_sequence(raw: Any) -> Optional[str]:
|
||||||
|
if raw is None:
|
||||||
|
return None
|
||||||
|
if isinstance(raw, (int, float)):
|
||||||
|
if isinstance(raw, float) and (math.isnan(raw) or math.isinf(raw)):
|
||||||
|
return None
|
||||||
|
text = str(raw)
|
||||||
|
else:
|
||||||
|
text = str(raw).strip()
|
||||||
|
if not text:
|
||||||
|
return None
|
||||||
|
candidate = text.replace(",", ".")
|
||||||
|
match = _SERIES_NUMBER_RE.search(candidate)
|
||||||
|
if not match:
|
||||||
|
return None
|
||||||
|
normalized = match.group(0)
|
||||||
|
if "." in normalized:
|
||||||
|
normalized = normalized.rstrip("0").rstrip(".")
|
||||||
|
if not normalized:
|
||||||
|
normalized = "0"
|
||||||
|
return normalized
|
||||||
|
try:
|
||||||
|
return str(int(normalized))
|
||||||
|
except ValueError:
|
||||||
|
cleaned = normalized.lstrip("0")
|
||||||
|
return cleaned or "0"
|
||||||
|
|
||||||
|
|
||||||
|
def build_audiobookshelf_metadata(
|
||||||
|
tags: Mapping[str, Any],
|
||||||
|
*,
|
||||||
|
language: str = "",
|
||||||
|
filename: str = "",
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
normalized = normalize_metadata_casefold(tags)
|
||||||
|
title = first_nonempty(
|
||||||
|
normalized.get("title"),
|
||||||
|
normalized.get("book_title"),
|
||||||
|
normalized.get("name"),
|
||||||
|
normalized.get("album"),
|
||||||
|
filename,
|
||||||
|
)
|
||||||
|
authors = split_people_field(
|
||||||
|
normalized.get("authors")
|
||||||
|
or normalized.get("author")
|
||||||
|
or normalized.get("album_artist")
|
||||||
|
or normalized.get("artist")
|
||||||
|
)
|
||||||
|
narrators = split_people_field(normalized.get("narrators") or normalized.get("narrator"))
|
||||||
|
description = first_nonempty(
|
||||||
|
normalized.get("description"), normalized.get("summary"), normalized.get("comment")
|
||||||
|
)
|
||||||
|
genres = split_simple_list(normalized.get("genre"))
|
||||||
|
keywords = split_simple_list(normalized.get("tags") or normalized.get("keywords"))
|
||||||
|
lang = first_nonempty(normalized.get("language"), normalized.get("lang")) or language or ""
|
||||||
|
series_name = first_nonempty(
|
||||||
|
normalized.get("series"),
|
||||||
|
normalized.get("series_name"),
|
||||||
|
normalized.get("seriesname"),
|
||||||
|
normalized.get("series_title"),
|
||||||
|
normalized.get("seriestitle"),
|
||||||
|
)
|
||||||
|
|
||||||
|
series_sequence = None
|
||||||
|
for key in _SERIES_SEQUENCE_TAG_KEYS:
|
||||||
|
raw_value = normalized.get(key)
|
||||||
|
seq = normalize_series_sequence(raw_value)
|
||||||
|
if seq:
|
||||||
|
series_sequence = seq
|
||||||
|
break
|
||||||
|
if not series_name:
|
||||||
|
series_sequence = None
|
||||||
|
|
||||||
|
data: Dict[str, Any] = {
|
||||||
|
"title": title,
|
||||||
|
"subtitle": normalized.get("subtitle"),
|
||||||
|
"authors": authors,
|
||||||
|
"narrators": narrators,
|
||||||
|
"description": description,
|
||||||
|
"publisher": normalized.get("publisher"),
|
||||||
|
"genres": genres,
|
||||||
|
"tags": keywords,
|
||||||
|
"language": lang,
|
||||||
|
"publishedYear": extract_year(
|
||||||
|
normalized.get("published")
|
||||||
|
or normalized.get("publication_year")
|
||||||
|
or normalized.get("date")
|
||||||
|
or normalized.get("year")
|
||||||
|
),
|
||||||
|
"seriesName": series_name,
|
||||||
|
"seriesSequence": series_sequence,
|
||||||
|
"isbn": first_nonempty(normalized.get("isbn"), normalized.get("asin")),
|
||||||
|
}
|
||||||
|
published_date = first_nonempty(
|
||||||
|
normalized.get("published"), normalized.get("publication_date"), normalized.get("date")
|
||||||
|
)
|
||||||
|
if published_date:
|
||||||
|
data["publishedDate"] = published_date
|
||||||
|
|
||||||
|
rating_text = first_nonempty(normalized.get("rating"), normalized.get("my_rating"))
|
||||||
|
if rating_text:
|
||||||
|
try:
|
||||||
|
data["rating"] = float(str(rating_text).strip())
|
||||||
|
except ValueError:
|
||||||
|
pass
|
||||||
|
rating_max_text = first_nonempty(
|
||||||
|
normalized.get("rating_max"), normalized.get("rating_scale")
|
||||||
|
)
|
||||||
|
if rating_max_text:
|
||||||
|
try:
|
||||||
|
data["ratingMax"] = float(str(rating_max_text).strip())
|
||||||
|
except ValueError:
|
||||||
|
pass
|
||||||
|
|
||||||
|
cleaned: Dict[str, Any] = {}
|
||||||
|
for key, value in data.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
if isinstance(value, str) and not value.strip():
|
||||||
|
continue
|
||||||
|
if isinstance(value, (list, tuple)) and not value:
|
||||||
|
continue
|
||||||
|
cleaned[key] = value
|
||||||
|
return cleaned
|
||||||
|
|
||||||
|
|
||||||
|
def load_audiobookshelf_chapters(
|
||||||
|
metadata_path: Path,
|
||||||
|
) -> Optional[List[Dict[str, Any]]]:
|
||||||
|
if not metadata_path.exists():
|
||||||
|
return None
|
||||||
|
try:
|
||||||
|
payload = json.loads(metadata_path.read_text(encoding="utf-8"))
|
||||||
|
except (OSError, json.JSONDecodeError):
|
||||||
|
return None
|
||||||
|
chapters = payload.get("chapters")
|
||||||
|
if not isinstance(chapters, list):
|
||||||
|
return None
|
||||||
|
cleaned: List[Dict[str, Any]] = []
|
||||||
|
for entry in chapters:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
title = first_nonempty(entry.get("title"), entry.get("original_title"))
|
||||||
|
start = entry.get("start")
|
||||||
|
end = entry.get("end")
|
||||||
|
if title and start is not None and end is not None:
|
||||||
|
cleaned.append({"title": str(title), "start": start, "end": end})
|
||||||
|
return cleaned or None
|
||||||
|
|
||||||
|
|
||||||
|
def build_metadata_payload(
|
||||||
|
metadata: Optional[Dict[str, Any]] = None,
|
||||||
|
chapter_markers: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
chunk_markers: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
chunk_level: Optional[str] = None,
|
||||||
|
speaker_mode: Optional[str] = None,
|
||||||
|
speakers: Optional[Dict[str, Any]] = None,
|
||||||
|
generate_epub3: bool = False,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
"""Build the canonical metadata payload dict for persistence and downstream use.
|
||||||
|
|
||||||
|
This is the single source of truth for metadata assembly. Both PyQt and WebUI
|
||||||
|
runners should call this instead of building the dict manually.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
metadata: Normalized metadata tags dict.
|
||||||
|
chapter_markers: List of chapter marker dicts with title/start/end.
|
||||||
|
chunk_markers: List of chunk marker dicts.
|
||||||
|
chunk_level: Chunk granularity level (e.g. 'chapter', 'chunk').
|
||||||
|
speaker_mode: Speaker mode ('single', 'multi', etc.).
|
||||||
|
speakers: Speaker profile mapping.
|
||||||
|
generate_epub3: Whether EPUB3 generation is enabled.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Complete metadata payload dict.
|
||||||
|
"""
|
||||||
|
return {
|
||||||
|
"metadata": dict(metadata or {}),
|
||||||
|
"chapters": chapter_markers or [],
|
||||||
|
"chunks": chunk_markers or [],
|
||||||
|
"chunk_level": chunk_level,
|
||||||
|
"speaker_mode": speaker_mode,
|
||||||
|
"speakers": dict(speakers or {}),
|
||||||
|
"generate_epub3": generate_epub3,
|
||||||
|
}
|
||||||
@@ -0,0 +1,23 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Optional
|
||||||
|
|
||||||
|
|
||||||
|
def merge_metadata(
|
||||||
|
extracted: Optional[Dict[str, Any]],
|
||||||
|
overrides: Optional[Dict[str, Any]],
|
||||||
|
) -> Dict[str, str]:
|
||||||
|
merged: Dict[str, str] = {}
|
||||||
|
if extracted:
|
||||||
|
for key, value in extracted.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
merged[str(key)] = str(value)
|
||||||
|
if overrides:
|
||||||
|
for key, value in overrides.items():
|
||||||
|
key_str = str(key)
|
||||||
|
if value is None:
|
||||||
|
merged.pop(key_str, None)
|
||||||
|
else:
|
||||||
|
merged[key_str] = str(value)
|
||||||
|
return merged
|
||||||
@@ -0,0 +1,56 @@
|
|||||||
|
"""OPDS metadata normalization.
|
||||||
|
|
||||||
|
Normalizes metadata keys from various OPDS/Calibre sources into
|
||||||
|
a canonical set of overrides for the audiobook conversion pipeline.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Mapping
|
||||||
|
|
||||||
|
from abogen.domain.metadata_helpers import expand_metadata_aliases
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_opds_metadata(metadata_payload: Mapping[str, Any]) -> Dict[str, Any]:
|
||||||
|
"""Normalize OPDS/Calibre metadata into canonical override keys.
|
||||||
|
|
||||||
|
Takes a metadata payload with various key aliases (e.g. 'series'/'series_name',
|
||||||
|
'tags'/'keywords', 'authors'/'creator') and returns a dict with all
|
||||||
|
concept aliases expanded.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
metadata_payload: Raw metadata dict from OPDS/Calibre import.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Dict with all canonical metadata key aliases expanded.
|
||||||
|
"""
|
||||||
|
def _stringify(value: Any) -> str:
|
||||||
|
if value is None:
|
||||||
|
return ""
|
||||||
|
if isinstance(value, (list, tuple, set)):
|
||||||
|
parts = [str(item).strip() for item in value if item is not None]
|
||||||
|
return ", ".join(part for part in parts if part)
|
||||||
|
return str(value).strip()
|
||||||
|
|
||||||
|
# Map OPDS-specific keys to common concept keys before expansion
|
||||||
|
normalized_input: Dict[str, Any] = {}
|
||||||
|
for key, value in metadata_payload.items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
key_lower = str(key).strip().lower()
|
||||||
|
if not key_lower:
|
||||||
|
continue
|
||||||
|
text = _stringify(value)
|
||||||
|
if not text:
|
||||||
|
continue
|
||||||
|
|
||||||
|
# Map OPDS-specific author aliases
|
||||||
|
if key_lower in ("creator", "dc_creator"):
|
||||||
|
normalized_input["author"] = text
|
||||||
|
# Map OPDS-specific subtitle aliases
|
||||||
|
elif key_lower in ("sub_title", "calibre_subtitle"):
|
||||||
|
normalized_input["subtitle"] = text
|
||||||
|
else:
|
||||||
|
normalized_input[key_lower] = text
|
||||||
|
|
||||||
|
return expand_metadata_aliases(normalized_input)
|
||||||
@@ -0,0 +1,245 @@
|
|||||||
|
"""Text normalization convenience helpers.
|
||||||
|
|
||||||
|
Provides both the simple ``normalize_text_for_pipeline`` (apostrophe + LLM only)
|
||||||
|
and the comprehensive ``prepare_text_for_tts`` that chains all three normalization
|
||||||
|
stages used during conversion: heteronym rules → pronunciation rules → pipeline
|
||||||
|
normalization. The latter is the single entry point that both the Web UI and
|
||||||
|
PyQt Desktop GUI should use.
|
||||||
|
|
||||||
|
Also provides ``TTSContext`` — a dataclass bundling all pre-compiled normalization
|
||||||
|
resources so they can be created once and passed as a single object.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from typing import Any, Callable, Dict, List, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.domain.enums import Language
|
||||||
|
from abogen.kokoro_text_normalization import (
|
||||||
|
ApostropheConfig,
|
||||||
|
normalize_for_pipeline as _normalize_for_pipeline,
|
||||||
|
)
|
||||||
|
from abogen.normalization_settings import (
|
||||||
|
build_apostrophe_config,
|
||||||
|
get_runtime_settings,
|
||||||
|
apply_overrides as _apply_overrides,
|
||||||
|
)
|
||||||
|
|
||||||
|
_BASE_APOSTROPHE_CONFIG = ApostropheConfig()
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class TTSContext:
|
||||||
|
"""Bundles pre-compiled normalization resources for TTS processing.
|
||||||
|
|
||||||
|
Created once per conversion job and passed to ``prepare_text_for_tts``
|
||||||
|
instead of threading 5 separate parameters.
|
||||||
|
"""
|
||||||
|
|
||||||
|
split_pattern: str = r"(?<=[.!?\-])\s+"
|
||||||
|
pronunciation_rules: Optional[List[Dict[str, Any]]] = None
|
||||||
|
heteronym_rules: Optional[List[Dict[str, Any]]] = None
|
||||||
|
normalization_overrides: Optional[Mapping[str, Any]] = None
|
||||||
|
usage_counter: Dict[str, int] = field(default_factory=dict)
|
||||||
|
|
||||||
|
def normalize(self, text: str) -> str:
|
||||||
|
"""Shorthand: normalize text using this context's compiled rules."""
|
||||||
|
return prepare_text_for_tts(
|
||||||
|
text,
|
||||||
|
heteronym_rules=self.heteronym_rules,
|
||||||
|
pronunciation_rules=self.pronunciation_rules,
|
||||||
|
normalization_overrides=self.normalization_overrides,
|
||||||
|
usage_counter=self.usage_counter,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_text_for_pipeline(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
normalization_overrides: Optional[Mapping[str, Any]] = None,
|
||||||
|
) -> str:
|
||||||
|
"""Normalize text using runtime settings with optional overrides."""
|
||||||
|
runtime_settings = get_runtime_settings()
|
||||||
|
if normalization_overrides:
|
||||||
|
runtime_settings = _apply_overrides(runtime_settings, normalization_overrides)
|
||||||
|
apostrophe_config = build_apostrophe_config(settings=runtime_settings, base=_BASE_APOSTROPHE_CONFIG)
|
||||||
|
return _normalize_for_pipeline(text, config=apostrophe_config, settings=runtime_settings)
|
||||||
|
|
||||||
|
|
||||||
|
def prepare_text_for_tts(
|
||||||
|
text: str,
|
||||||
|
*,
|
||||||
|
heteronym_rules: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
pronunciation_rules: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
normalization_overrides: Optional[Mapping[str, Any]] = None,
|
||||||
|
usage_counter: Optional[Dict[str, int]] = None,
|
||||||
|
) -> str:
|
||||||
|
"""Apply the full text normalization pipeline before TTS synthesis.
|
||||||
|
|
||||||
|
Chains three stages in order:
|
||||||
|
1. Heteronym sentence rules (context-dependent pronunciation)
|
||||||
|
2. Pronunciation rules (token-level replacements)
|
||||||
|
3. Pipeline normalization (apostrophe handling, LLM normalization)
|
||||||
|
|
||||||
|
This is the **single entry point** that both the Web UI conversion runner
|
||||||
|
and the PyQt conversion thread should call before passing text to the TTS
|
||||||
|
backend.
|
||||||
|
|
||||||
|
Parameters
|
||||||
|
----------
|
||||||
|
text:
|
||||||
|
Raw text to normalize.
|
||||||
|
heteronym_rules:
|
||||||
|
Compiled heteronym rules from ``compile_heteronym_sentence_rules``.
|
||||||
|
pronunciation_rules:
|
||||||
|
Compiled pronunciation rules from ``compile_pronunciation_rules``.
|
||||||
|
normalization_overrides:
|
||||||
|
User-level overrides for normalization settings (apostrophe mode, etc.).
|
||||||
|
usage_counter:
|
||||||
|
Mutable dict that tracks how many times each pronunciation override was
|
||||||
|
applied. Passed through to ``apply_pronunciation_rules``.
|
||||||
|
|
||||||
|
Returns
|
||||||
|
-------
|
||||||
|
str
|
||||||
|
Fully normalized text ready for TTS.
|
||||||
|
"""
|
||||||
|
from abogen.domain.pronunciation import (
|
||||||
|
apply_heteronym_sentence_rules,
|
||||||
|
apply_pronunciation_rules,
|
||||||
|
)
|
||||||
|
|
||||||
|
result = str(text or "")
|
||||||
|
|
||||||
|
if heteronym_rules:
|
||||||
|
result = apply_heteronym_sentence_rules(result, heteronym_rules)
|
||||||
|
|
||||||
|
if pronunciation_rules:
|
||||||
|
result = apply_pronunciation_rules(result, pronunciation_rules, usage_counter)
|
||||||
|
|
||||||
|
runtime_settings = get_runtime_settings()
|
||||||
|
if normalization_overrides:
|
||||||
|
runtime_settings = _apply_overrides(runtime_settings, normalization_overrides)
|
||||||
|
apostrophe_config = build_apostrophe_config(settings=runtime_settings, base=_BASE_APOSTROPHE_CONFIG)
|
||||||
|
|
||||||
|
return _normalize_for_pipeline(result, config=apostrophe_config, settings=runtime_settings)
|
||||||
|
|
||||||
|
|
||||||
|
def build_tts_context(
|
||||||
|
*,
|
||||||
|
language: Language,
|
||||||
|
subtitle: "SubtitleConfig | str" = "Disabled",
|
||||||
|
pronunciation: Optional["PronunciationConfig"] = None,
|
||||||
|
speakers: Optional[Dict[str, Any]] = None,
|
||||||
|
usage_counter: Optional[Dict[str, int]] = None,
|
||||||
|
log_callback: Optional[Callable[[str, str], None]] = None,
|
||||||
|
) -> TTSContext:
|
||||||
|
"""Build a TTSContext from raw data. Single entry point for both UIs.
|
||||||
|
|
||||||
|
Loads normalization settings, applies overrides, validates configuration,
|
||||||
|
merges pronunciation overrides, and compiles all rules.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
language: Language enum value.
|
||||||
|
subtitle: SubtitleConfig object or subtitle mode string.
|
||||||
|
pronunciation: PronunciationConfig with override rules.
|
||||||
|
speakers: Speaker profile mapping.
|
||||||
|
usage_counter: Mutable dict for tracking override usage.
|
||||||
|
log_callback: Callable(level, message) for warnings.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
TTSContext ready for text normalization.
|
||||||
|
"""
|
||||||
|
from abogen.domain.config_types import PronunciationConfig, SubtitleConfig
|
||||||
|
from abogen.domain.enums import SubtitleMode
|
||||||
|
from abogen.domain.pronunciation import (
|
||||||
|
compile_heteronym_sentence_rules,
|
||||||
|
compile_pronunciation_rules,
|
||||||
|
merge_pronunciation_overrides,
|
||||||
|
)
|
||||||
|
from abogen.domain.split_pattern import get_split_pattern
|
||||||
|
|
||||||
|
def _log(msg: str, level: str = "warning") -> None:
|
||||||
|
if log_callback:
|
||||||
|
log_callback(level, msg)
|
||||||
|
|
||||||
|
# Resolve subtitle mode
|
||||||
|
if isinstance(subtitle, SubtitleConfig):
|
||||||
|
resolved_subtitle = subtitle.mode
|
||||||
|
else:
|
||||||
|
try:
|
||||||
|
resolved_subtitle = SubtitleMode.from_str(subtitle) if not isinstance(subtitle, SubtitleMode) else subtitle
|
||||||
|
except ValueError:
|
||||||
|
resolved_subtitle = SubtitleMode.DISABLED
|
||||||
|
|
||||||
|
# Resolve pronunciation config
|
||||||
|
if pronunciation is None:
|
||||||
|
pronunciation = PronunciationConfig()
|
||||||
|
|
||||||
|
# Get runtime normalization settings
|
||||||
|
runtime_settings = get_runtime_settings()
|
||||||
|
|
||||||
|
# Apply per-job normalization overrides
|
||||||
|
if pronunciation.normalization_overrides:
|
||||||
|
runtime_settings = _apply_overrides(runtime_settings, pronunciation.normalization_overrides)
|
||||||
|
|
||||||
|
# Build apostrophe config
|
||||||
|
apostrophe_config = build_apostrophe_config(settings=runtime_settings)
|
||||||
|
|
||||||
|
# Validate LLM apostrophe mode
|
||||||
|
apostrophe_mode = str(runtime_settings.get("normalization_apostrophe_mode", "spacy")).lower()
|
||||||
|
if apostrophe_mode == "llm":
|
||||||
|
from abogen.normalization_settings import build_llm_configuration
|
||||||
|
llm_config = build_llm_configuration(runtime_settings)
|
||||||
|
if not llm_config.is_configured():
|
||||||
|
raise RuntimeError(
|
||||||
|
"LLM-based apostrophe normalization is selected, but the LLM configuration is incomplete."
|
||||||
|
)
|
||||||
|
|
||||||
|
# Check for num2words availability
|
||||||
|
if apostrophe_config.convert_numbers:
|
||||||
|
try:
|
||||||
|
import num2words # noqa: F401
|
||||||
|
except ImportError:
|
||||||
|
_log(
|
||||||
|
"Number normalization is enabled but 'num2words' library is not available. "
|
||||||
|
"Numbers will NOT be converted to words."
|
||||||
|
)
|
||||||
|
|
||||||
|
# Compute split pattern
|
||||||
|
if not isinstance(language, Language):
|
||||||
|
raise TypeError(f"language must be Language enum, got {type(language).__name__}: {language!r}")
|
||||||
|
split_pattern = get_split_pattern(language, resolved_subtitle)
|
||||||
|
|
||||||
|
# Merge pronunciation overrides
|
||||||
|
source = {
|
||||||
|
"pronunciation_overrides": pronunciation.pronunciation_overrides,
|
||||||
|
"manual_overrides": pronunciation.manual_overrides,
|
||||||
|
"speakers": speakers or {},
|
||||||
|
"language": language,
|
||||||
|
}
|
||||||
|
merged_overrides = merge_pronunciation_overrides(source)
|
||||||
|
|
||||||
|
# Compile rules
|
||||||
|
pronunciation_rules = compile_pronunciation_rules(merged_overrides)
|
||||||
|
heteronym_rules = compile_heteronym_sentence_rules(pronunciation.heteronym_overrides)
|
||||||
|
|
||||||
|
if heteronym_rules:
|
||||||
|
_log(
|
||||||
|
f"Applying {len(heteronym_rules)} heteronym override(s) during conversion.",
|
||||||
|
level="debug",
|
||||||
|
)
|
||||||
|
if pronunciation_rules:
|
||||||
|
_log(
|
||||||
|
f"Applying {len(pronunciation_rules)} pronunciation override(s) during conversion.",
|
||||||
|
level="debug",
|
||||||
|
)
|
||||||
|
|
||||||
|
return TTSContext(
|
||||||
|
split_pattern=split_pattern,
|
||||||
|
pronunciation_rules=pronunciation_rules,
|
||||||
|
heteronym_rules=heteronym_rules,
|
||||||
|
normalization_overrides=pronunciation.normalization_overrides,
|
||||||
|
usage_counter=usage_counter if usage_counter is not None else {},
|
||||||
|
)
|
||||||
@@ -0,0 +1,226 @@
|
|||||||
|
"""Output path resolution utilities.
|
||||||
|
|
||||||
|
Pure functions for resolving output directories, building file paths,
|
||||||
|
and computing project folder layouts.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import os
|
||||||
|
import platform
|
||||||
|
import re
|
||||||
|
from datetime import datetime
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Callable, List, Optional, Tuple
|
||||||
|
|
||||||
|
from abogen.text_extractor import ExtractedChapter
|
||||||
|
|
||||||
|
|
||||||
|
_OUTPUT_SANITIZE_RE = re.compile(r"[^\w\-_.]+")
|
||||||
|
|
||||||
|
# OS-specific illegal characters for filenames
|
||||||
|
_WINDOWS_ILLEGAL_CHARS_RE = re.compile(r'[<>:"/\\|?*\x00-\x1f]')
|
||||||
|
_MACOS_ILLEGAL_CHARS_RE = re.compile(r"[:]")
|
||||||
|
_LINUX_ILLEGAL_CHARS_RE = re.compile(r"[/\x00]")
|
||||||
|
_CONTROL_CHARS_RE = re.compile(r"[\x00-\x1f]")
|
||||||
|
_UNIX_CONTROL_CHARS_RE = re.compile(r'[\x00-\x1f]')
|
||||||
|
_RESERVED_NAMES = frozenset(
|
||||||
|
{"CON", "PRN", "AUX", "NUL"}
|
||||||
|
| {f"COM{i}" for i in range(1, 10)}
|
||||||
|
| {f"LPT{i}" for i in range(1, 10)}
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def sanitize_name_for_os(name: str, is_folder: bool = True) -> str:
|
||||||
|
"""Sanitize a filename or folder name based on the operating system.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
name: The name to sanitize
|
||||||
|
is_folder: Whether this is a folder name (default: True)
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Sanitized name safe for the current OS
|
||||||
|
"""
|
||||||
|
if not name:
|
||||||
|
return "audiobook"
|
||||||
|
|
||||||
|
system = platform.system()
|
||||||
|
|
||||||
|
if system == "Windows":
|
||||||
|
sanitized = _WINDOWS_ILLEGAL_CHARS_RE.sub("_", name)
|
||||||
|
sanitized = _CONTROL_CHARS_RE.sub("_", sanitized)
|
||||||
|
sanitized = sanitized.rstrip(". ")
|
||||||
|
if sanitized.upper() in _RESERVED_NAMES or sanitized.upper().split(".")[0] in _RESERVED_NAMES:
|
||||||
|
sanitized = f"_{sanitized}"
|
||||||
|
elif system == "Darwin":
|
||||||
|
sanitized = _MACOS_ILLEGAL_CHARS_RE.sub("_", name)
|
||||||
|
sanitized = _CONTROL_CHARS_RE.sub("_", sanitized)
|
||||||
|
if is_folder and sanitized.startswith("."):
|
||||||
|
sanitized = "_" + sanitized[1:]
|
||||||
|
else:
|
||||||
|
sanitized = _LINUX_ILLEGAL_CHARS_RE.sub("_", name)
|
||||||
|
sanitized = _UNIX_CONTROL_CHARS_RE.sub("_", sanitized)
|
||||||
|
if is_folder and sanitized.startswith("."):
|
||||||
|
sanitized = "_" + sanitized[1:]
|
||||||
|
|
||||||
|
if not sanitized or sanitized.strip() == "":
|
||||||
|
sanitized = "audiobook"
|
||||||
|
|
||||||
|
if len(sanitized) > 255:
|
||||||
|
sanitized = sanitized[:255].rstrip(". ")
|
||||||
|
|
||||||
|
return sanitized
|
||||||
|
|
||||||
|
|
||||||
|
def slugify(title: str, index: int) -> str:
|
||||||
|
sanitized = re.sub(r"[^\w\-]+", "_", title.lower()).strip("_")
|
||||||
|
if not sanitized:
|
||||||
|
sanitized = f"chapter_{index:02d}"
|
||||||
|
return sanitized[:80]
|
||||||
|
|
||||||
|
|
||||||
|
def sanitize_filename_for_chapter(title: str, index: int, max_len: int = 80) -> str:
|
||||||
|
"""Sanitize a chapter name for use as a filename component.
|
||||||
|
|
||||||
|
Combines character sanitization, OS safety, and smart truncation
|
||||||
|
at word boundaries. Prepends zero-padded index prefix.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
title: Raw chapter title.
|
||||||
|
index: 1-based chapter number for prefix.
|
||||||
|
max_len: Maximum length of the sanitized portion (excluding prefix).
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Sanitized string like "01_the_beginning".
|
||||||
|
"""
|
||||||
|
# Remove non-word/non-space/non-hyphen chars, then collapse spaces/hyphens
|
||||||
|
sanitized = re.sub(r"[^\w\s\-]", "", title)
|
||||||
|
sanitized = re.sub(r"[\s\-]+", "_", sanitized).strip("_")
|
||||||
|
|
||||||
|
if not sanitized:
|
||||||
|
sanitized = f"chapter_{index:02d}"
|
||||||
|
|
||||||
|
# OS-specific sanitization
|
||||||
|
system = platform.system()
|
||||||
|
if system == "Windows":
|
||||||
|
sanitized = _WINDOWS_ILLEGAL_CHARS_RE.sub("_", sanitized)
|
||||||
|
sanitized = sanitized.rstrip(". ")
|
||||||
|
base = sanitized.split(".")[0].upper()
|
||||||
|
if base in _RESERVED_NAMES:
|
||||||
|
sanitized = f"_{sanitized}"
|
||||||
|
# Linux: only NUL is truly illegal, but control chars are problematic
|
||||||
|
sanitized = _UNIX_CONTROL_CHARS_RE.sub("_", sanitized)
|
||||||
|
|
||||||
|
# Smart truncation at word boundary
|
||||||
|
if len(sanitized) > max_len:
|
||||||
|
pos = sanitized[:max_len].rfind("_")
|
||||||
|
sanitized = sanitized[: pos if pos > 0 else max_len].rstrip("_")
|
||||||
|
|
||||||
|
return f"{index:02d}_{sanitized}"
|
||||||
|
|
||||||
|
|
||||||
|
def sanitize_output_stem(name: str, index: int = 0) -> str:
|
||||||
|
base = Path(name or "").stem
|
||||||
|
sanitized = _OUTPUT_SANITIZE_RE.sub("_", base).strip("_")
|
||||||
|
return sanitized or "output"
|
||||||
|
|
||||||
|
|
||||||
|
def output_timestamp_token() -> str:
|
||||||
|
return datetime.now().strftime("%Y%m%d-%H%M%S")
|
||||||
|
|
||||||
|
|
||||||
|
def build_output_path(directory: Path, original_name: str, extension: str) -> Path:
|
||||||
|
sanitized = sanitize_output_stem(original_name)
|
||||||
|
return directory / f"{sanitized}.{extension}"
|
||||||
|
|
||||||
|
|
||||||
|
def apply_newline_policy(chapters: List[ExtractedChapter], replace_single_newlines: bool) -> None:
|
||||||
|
if not replace_single_newlines:
|
||||||
|
return
|
||||||
|
newline_regex = re.compile(r"(?<!\n)\n(?!\n)")
|
||||||
|
for chapter in chapters:
|
||||||
|
chapter.text = newline_regex.sub(" ", chapter.text)
|
||||||
|
|
||||||
|
|
||||||
|
from abogen.domain.enums import SaveMode
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_output_directory(
|
||||||
|
*,
|
||||||
|
save_mode: str,
|
||||||
|
stored_path: Path,
|
||||||
|
output_folder: Optional[str],
|
||||||
|
desktop_dir: Optional[Path],
|
||||||
|
user_output_path: Optional[Path],
|
||||||
|
user_cache_outputs: Optional[Path],
|
||||||
|
) -> Path:
|
||||||
|
if save_mode in (SaveMode.SAVE_TO_DESKTOP, "Save to Desktop") and desktop_dir:
|
||||||
|
return desktop_dir
|
||||||
|
if save_mode in (SaveMode.SAVE_NEXT_TO_INPUT, "Save next to input file"):
|
||||||
|
return stored_path.parent
|
||||||
|
if save_mode in (SaveMode.CHOOSE_OUTPUT_FOLDER, "Choose output folder") and output_folder:
|
||||||
|
return Path(output_folder)
|
||||||
|
if save_mode in (SaveMode.DEFAULT_OUTPUT, "Use default save location") and user_output_path:
|
||||||
|
return user_output_path
|
||||||
|
return user_cache_outputs or Path(".")
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_project_layout(
|
||||||
|
*,
|
||||||
|
original_filename: str,
|
||||||
|
save_as_project: bool,
|
||||||
|
base_dir: Path,
|
||||||
|
timestamp_fn: Callable[[], str] = output_timestamp_token,
|
||||||
|
sanitize_fn: Callable[[str, int], str] = sanitize_output_stem,
|
||||||
|
) -> Tuple[Path, Path, Path, Optional[Path]]:
|
||||||
|
sanitized = sanitize_fn(original_filename, 0)
|
||||||
|
folder_name = f"{timestamp_fn()}_{sanitized}"
|
||||||
|
project_root = base_dir / folder_name
|
||||||
|
project_root.mkdir(parents=True, exist_ok=True)
|
||||||
|
|
||||||
|
if save_as_project:
|
||||||
|
audio_dir = project_root / "audio"
|
||||||
|
subtitle_dir = project_root / "subtitles"
|
||||||
|
metadata_dir = project_root / "metadata"
|
||||||
|
for directory in (audio_dir, subtitle_dir, metadata_dir):
|
||||||
|
directory.mkdir(parents=True, exist_ok=True)
|
||||||
|
return project_root, audio_dir, subtitle_dir, metadata_dir
|
||||||
|
|
||||||
|
return project_root, project_root, project_root, None
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_unique_path(
|
||||||
|
parent_dir: str,
|
||||||
|
base_name: str,
|
||||||
|
extension: str,
|
||||||
|
allowed_extensions: Optional[set] = None,
|
||||||
|
) -> str:
|
||||||
|
"""Find a unique file path by appending _2, _3, etc. on collision.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
parent_dir: Directory to check for collisions.
|
||||||
|
base_name: Base filename (without extension).
|
||||||
|
extension: File extension (without dot).
|
||||||
|
allowed_extensions: Set of extensions to check against.
|
||||||
|
If None, checks any existing file/dir with same name.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Full path without extension (e.g. "/path/to/name_2").
|
||||||
|
"""
|
||||||
|
sanitized = sanitize_name_for_os(base_name, is_folder=True)
|
||||||
|
counter = 1
|
||||||
|
while True:
|
||||||
|
suffix = f"_{counter}" if counter > 1 else ""
|
||||||
|
candidate = os.path.join(parent_dir, f"{sanitized}{suffix}")
|
||||||
|
if allowed_extensions is not None:
|
||||||
|
file_parts = (os.path.splitext(f) for f in os.listdir(parent_dir))
|
||||||
|
clash = any(
|
||||||
|
name == f"{sanitized}{suffix}"
|
||||||
|
and ext[1:].lower() in allowed_extensions
|
||||||
|
for name, ext in file_parts
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
clash = os.path.exists(candidate)
|
||||||
|
if not clash:
|
||||||
|
return candidate
|
||||||
|
counter += 1
|
||||||
@@ -0,0 +1,117 @@
|
|||||||
|
"""Pipeline creation, caching and lifecycle management.
|
||||||
|
|
||||||
|
Provides a unified interface for creating and managing TTS pipelines
|
||||||
|
across all UI layers (WebUI, PyQt, CLI).
|
||||||
|
|
||||||
|
Language handling: the engine owns the mapping between Language enum
|
||||||
|
and its internal format. Callers pass Language enum; the engine
|
||||||
|
converts internally. No engine-specific codes leak outside the engine.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict
|
||||||
|
|
||||||
|
from abogen.domain.device import select_device
|
||||||
|
from abogen.domain.enums import Language
|
||||||
|
from abogen.domain.voice_resolution import initialize_voice_cache
|
||||||
|
from abogen.tts_plugin.utils import create_pipeline, is_plugin_registered
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_device(use_gpu: bool) -> str:
|
||||||
|
"""Determine compute device from job and global config flags."""
|
||||||
|
from abogen.utils import load_config
|
||||||
|
|
||||||
|
cfg = load_config()
|
||||||
|
if use_gpu and cfg.get("use_gpu", True):
|
||||||
|
return select_device()
|
||||||
|
return "cpu"
|
||||||
|
|
||||||
|
|
||||||
|
def create_pipeline_for_job(
|
||||||
|
provider: str,
|
||||||
|
language: Language,
|
||||||
|
use_gpu: bool,
|
||||||
|
) -> Any:
|
||||||
|
"""Create a TTS pipeline with proper device selection.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
provider: TTS provider name ("kokoro" or "supertonic").
|
||||||
|
language: Language enum (app-layer type, not engine-specific).
|
||||||
|
use_gpu: Whether GPU acceleration is requested.
|
||||||
|
"""
|
||||||
|
provider = str(provider or "kokoro").strip().lower() or "kokoro"
|
||||||
|
if not is_plugin_registered(provider):
|
||||||
|
provider = "kokoro"
|
||||||
|
|
||||||
|
if provider == "supertonic":
|
||||||
|
return create_pipeline("supertonic", language=language)
|
||||||
|
|
||||||
|
device = resolve_device(use_gpu)
|
||||||
|
return create_pipeline("kokoro", language=language, device=device)
|
||||||
|
|
||||||
|
|
||||||
|
def dispose_pipelines(pipelines: Dict[str, Any]) -> None:
|
||||||
|
"""Dispose all pipelines in a dict and clear it."""
|
||||||
|
for p in pipelines.values():
|
||||||
|
try:
|
||||||
|
p.dispose()
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
pipelines.clear()
|
||||||
|
|
||||||
|
|
||||||
|
class PipelinePool:
|
||||||
|
"""Cache and manage TTS pipelines by provider.
|
||||||
|
|
||||||
|
Usage::
|
||||||
|
|
||||||
|
pool = PipelinePool()
|
||||||
|
backend = pool.get("kokoro", Language.EN_US, use_gpu=True)
|
||||||
|
# ... use backend ...
|
||||||
|
pool.dispose_all()
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(self) -> None:
|
||||||
|
self._pipelines: Dict[str, Any] = {}
|
||||||
|
self._voice_cache_initialized = False
|
||||||
|
|
||||||
|
def get(
|
||||||
|
self,
|
||||||
|
provider: str,
|
||||||
|
language: Language,
|
||||||
|
use_gpu: bool,
|
||||||
|
*,
|
||||||
|
request: Any = None,
|
||||||
|
events: Any = None,
|
||||||
|
) -> Any:
|
||||||
|
"""Get or create a cached pipeline for the given provider.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
provider: TTS provider name ("kokoro" or "supertonic").
|
||||||
|
language: Language enum (app-layer type).
|
||||||
|
use_gpu: Whether GPU acceleration is requested.
|
||||||
|
request: ConversionRequest for voice cache initialization.
|
||||||
|
events: ConversionEvents for logging during cache init.
|
||||||
|
"""
|
||||||
|
provider = str(provider or "kokoro").strip().lower() or "kokoro"
|
||||||
|
if not is_plugin_registered(provider):
|
||||||
|
provider = "kokoro"
|
||||||
|
|
||||||
|
existing = self._pipelines.get(provider)
|
||||||
|
if existing is not None:
|
||||||
|
return existing
|
||||||
|
|
||||||
|
pipeline = create_pipeline_for_job(provider, language, use_gpu)
|
||||||
|
self._pipelines[provider] = pipeline
|
||||||
|
|
||||||
|
if provider == "kokoro" and not self._voice_cache_initialized and request is not None:
|
||||||
|
initialize_voice_cache(request, events=events)
|
||||||
|
self._voice_cache_initialized = True
|
||||||
|
|
||||||
|
return pipeline
|
||||||
|
|
||||||
|
def dispose_all(self) -> None:
|
||||||
|
"""Dispose all cached pipelines."""
|
||||||
|
dispose_pipelines(self._pipelines)
|
||||||
|
self._voice_cache_initialized = False
|
||||||
@@ -0,0 +1,72 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
"""Progress and ETR (estimated time remaining) calculation.
|
||||||
|
|
||||||
|
Shared by Web UI and PyQt desktop GUI. Pure math, no UI dependencies.
|
||||||
|
"""
|
||||||
|
import time
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ProgressTracker:
|
||||||
|
"""Tracks character-based progress with ETR calculation.
|
||||||
|
|
||||||
|
Usage:
|
||||||
|
tracker = ProgressTracker(total_chars=50000)
|
||||||
|
# ... as processing occurs:
|
||||||
|
tracker.update(chars_done=5000)
|
||||||
|
print(tracker.etr_str) # "00:04:30"
|
||||||
|
print(tracker.percent) # 10
|
||||||
|
"""
|
||||||
|
total_chars: int
|
||||||
|
_start_time: float = field(default_factory=time.time, repr=False)
|
||||||
|
_chars_done: int = field(default=0, repr=False)
|
||||||
|
|
||||||
|
def update(self, chars_done: int) -> None:
|
||||||
|
self._chars_done = chars_done
|
||||||
|
|
||||||
|
@property
|
||||||
|
def percent(self) -> int:
|
||||||
|
if self.total_chars <= 0:
|
||||||
|
return 0
|
||||||
|
return min(int(self._chars_done / self.total_chars * 100), 99)
|
||||||
|
|
||||||
|
@property
|
||||||
|
def etr_str(self) -> str:
|
||||||
|
elapsed = time.time() - self._start_time
|
||||||
|
if self._chars_done <= 0 or elapsed <= 0.5:
|
||||||
|
return "Processing..."
|
||||||
|
avg_time_per_char = elapsed / self._chars_done
|
||||||
|
remaining = self.total_chars - self._chars_done
|
||||||
|
if remaining <= 0:
|
||||||
|
return "00:00:00"
|
||||||
|
secs = avg_time_per_char * remaining
|
||||||
|
h = int(secs // 3600)
|
||||||
|
m = int((secs % 3600) // 60)
|
||||||
|
s = int(secs % 60)
|
||||||
|
return f"{h:02d}:{m:02d}:{s:02d}"
|
||||||
|
|
||||||
|
|
||||||
|
def calc_etr_str(elapsed: float, done: int, total: int) -> str:
|
||||||
|
"""Standalone ETR string calculation (matches PyQt original logic).
|
||||||
|
|
||||||
|
Args:
|
||||||
|
elapsed: seconds since processing started
|
||||||
|
done: items/characters processed so far
|
||||||
|
total: total items/characters to process
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
ETR string like "01:23:45" or "Processing..."
|
||||||
|
"""
|
||||||
|
if done <= 0 or elapsed <= 0.5:
|
||||||
|
return "Processing..."
|
||||||
|
avg_time_per_item = elapsed / done
|
||||||
|
remaining = total - done
|
||||||
|
if remaining <= 0:
|
||||||
|
return "00:00:00"
|
||||||
|
secs = avg_time_per_item * remaining
|
||||||
|
h = int(secs // 3600)
|
||||||
|
m = int((secs % 3600) // 60)
|
||||||
|
s = int(secs % 60)
|
||||||
|
return f"{h:02d}:{m:02d}:{s:02d}"
|
||||||
@@ -0,0 +1,270 @@
|
|||||||
|
"""Pronunciation rule compilation and application.
|
||||||
|
|
||||||
|
Pure functions for compiling token-level and sentence-level pronunciation
|
||||||
|
overrides into regex patterns, applying them to text, and merging multiple
|
||||||
|
override sources with precedence rules.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.entity_analysis import normalize_token as normalize_entity_token
|
||||||
|
from abogen.entity_analysis import normalize_manual_override_token
|
||||||
|
|
||||||
|
|
||||||
|
def compile_pronunciation_rules(
|
||||||
|
overrides: Optional[Iterable[Mapping[str, Any]]],
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
if not overrides:
|
||||||
|
return []
|
||||||
|
|
||||||
|
candidates: List[Dict[str, Any]] = []
|
||||||
|
seen: set[str] = set()
|
||||||
|
|
||||||
|
for entry in overrides:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
pronunciation_value = str(entry.get("pronunciation") or "").strip()
|
||||||
|
if not pronunciation_value:
|
||||||
|
continue
|
||||||
|
|
||||||
|
token_values: List[str] = []
|
||||||
|
token_raw = entry.get("token")
|
||||||
|
if token_raw:
|
||||||
|
token_value = str(token_raw).strip()
|
||||||
|
if token_value:
|
||||||
|
token_values.append(token_value)
|
||||||
|
normalized_raw = entry.get("normalized")
|
||||||
|
if normalized_raw:
|
||||||
|
normalized_value = str(normalized_raw).strip()
|
||||||
|
if normalized_value:
|
||||||
|
token_values.append(normalized_value)
|
||||||
|
if token_raw and not token_values:
|
||||||
|
fallback = normalize_entity_token(str(token_raw))
|
||||||
|
if fallback:
|
||||||
|
token_values.append(fallback)
|
||||||
|
|
||||||
|
if not token_values:
|
||||||
|
continue
|
||||||
|
|
||||||
|
usage_normalized = str(entry.get("normalized") or "").strip()
|
||||||
|
if not usage_normalized and token_values:
|
||||||
|
usage_normalized = normalize_entity_token(token_values[0]) or token_values[0]
|
||||||
|
usage_token = str(entry.get("token") or token_values[0])
|
||||||
|
|
||||||
|
for token_value in token_values:
|
||||||
|
key = token_value.casefold()
|
||||||
|
if key in seen:
|
||||||
|
continue
|
||||||
|
seen.add(key)
|
||||||
|
candidates.append(
|
||||||
|
{
|
||||||
|
"token": token_value,
|
||||||
|
"normalized": usage_normalized,
|
||||||
|
"replacement": pronunciation_value,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
if not candidates:
|
||||||
|
return []
|
||||||
|
|
||||||
|
candidates.sort(key=lambda item: len(item["token"]), reverse=True)
|
||||||
|
compiled: List[Dict[str, Any]] = []
|
||||||
|
for candidate in candidates:
|
||||||
|
token_value = candidate["token"]
|
||||||
|
pronunciation_value = candidate["replacement"]
|
||||||
|
escaped = re.escape(token_value)
|
||||||
|
pattern = re.compile(rf"(?i)(?<!\w){escaped}(?P<possessive>'s|\u2019s|\u2019)?(?!\w)")
|
||||||
|
compiled.append(
|
||||||
|
{
|
||||||
|
"pattern": pattern,
|
||||||
|
"replacement": pronunciation_value,
|
||||||
|
"normalized": candidate.get("normalized") or token_value,
|
||||||
|
"token": candidate.get("token") or token_value,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
return compiled
|
||||||
|
|
||||||
|
|
||||||
|
def compile_heteronym_sentence_rules(
|
||||||
|
overrides: Optional[Iterable[Mapping[str, Any]]],
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
if not overrides:
|
||||||
|
return []
|
||||||
|
|
||||||
|
compiled: List[Dict[str, Any]] = []
|
||||||
|
seen: set[str] = set()
|
||||||
|
|
||||||
|
for entry in overrides:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
sentence = str(entry.get("sentence") or "").strip()
|
||||||
|
if not sentence:
|
||||||
|
continue
|
||||||
|
choice = str(entry.get("choice") or "").strip()
|
||||||
|
if not choice:
|
||||||
|
continue
|
||||||
|
|
||||||
|
replacement_sentence = ""
|
||||||
|
options = entry.get("options")
|
||||||
|
if isinstance(options, list):
|
||||||
|
for opt in options:
|
||||||
|
if not isinstance(opt, Mapping):
|
||||||
|
continue
|
||||||
|
if str(opt.get("key") or "").strip() == choice:
|
||||||
|
replacement_sentence = str(opt.get("replacement_sentence") or "").strip()
|
||||||
|
break
|
||||||
|
if not replacement_sentence:
|
||||||
|
continue
|
||||||
|
|
||||||
|
rule_key = f"{sentence}\n{choice}".casefold()
|
||||||
|
if rule_key in seen:
|
||||||
|
continue
|
||||||
|
seen.add(rule_key)
|
||||||
|
|
||||||
|
parts = [p for p in re.split(r"\s+", sentence) if p]
|
||||||
|
if not parts:
|
||||||
|
continue
|
||||||
|
pattern_text = r"\s+".join(re.escape(p) for p in parts)
|
||||||
|
pattern = re.compile(pattern_text)
|
||||||
|
compiled.append({"pattern": pattern, "replacement": replacement_sentence})
|
||||||
|
|
||||||
|
compiled.sort(key=lambda item: len(item["pattern"].pattern), reverse=True)
|
||||||
|
return compiled
|
||||||
|
|
||||||
|
|
||||||
|
def apply_heteronym_sentence_rules(text: str, rules: List[Dict[str, Any]]) -> str:
|
||||||
|
if not text or not rules:
|
||||||
|
return text
|
||||||
|
result = text
|
||||||
|
for rule in rules:
|
||||||
|
pattern = rule["pattern"]
|
||||||
|
replacement = rule["replacement"]
|
||||||
|
result = pattern.sub(replacement, result)
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
def apply_pronunciation_rules(
|
||||||
|
text: str,
|
||||||
|
rules: List[Dict[str, Any]],
|
||||||
|
usage_counter: Optional[Dict[str, int]] = None,
|
||||||
|
) -> str:
|
||||||
|
if not text or not rules:
|
||||||
|
return text
|
||||||
|
|
||||||
|
result = text
|
||||||
|
for rule in rules:
|
||||||
|
pattern = rule["pattern"]
|
||||||
|
pronunciation_value = rule["replacement"]
|
||||||
|
usage_key = str(rule.get("normalized") or "").strip()
|
||||||
|
|
||||||
|
def _replacement(match: re.Match[str]) -> str:
|
||||||
|
suffix = match.group("possessive") or ""
|
||||||
|
if usage_counter is not None and usage_key:
|
||||||
|
usage_counter[usage_key] = usage_counter.get(usage_key, 0) + 1
|
||||||
|
return pronunciation_value + suffix
|
||||||
|
|
||||||
|
result = pattern.sub(_replacement, result)
|
||||||
|
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
def merge_pronunciation_overrides(job: Any) -> List[Dict[str, Any]]:
|
||||||
|
"""Return pronunciation override entries, ensuring manual overrides are included.
|
||||||
|
|
||||||
|
Pending jobs keep both ``manual_overrides`` and ``pronunciation_overrides``, but the
|
||||||
|
latter can be stale if the UI didn't resync before enqueue. During conversion,
|
||||||
|
we must merge manual overrides so they always apply (before TTS).
|
||||||
|
|
||||||
|
Precedence: manual overrides win over existing entries for the same normalized key.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
job: Either a job-like object with attributes, or a dict with keys:
|
||||||
|
``pronunciation_overrides``, ``manual_overrides``, ``speakers``, ``language``.
|
||||||
|
"""
|
||||||
|
|
||||||
|
collected: Dict[str, Dict[str, Any]] = {}
|
||||||
|
|
||||||
|
def _get(key: str, default: Any = None) -> Any:
|
||||||
|
if isinstance(job, Mapping):
|
||||||
|
return job.get(key, default)
|
||||||
|
return getattr(job, key, default)
|
||||||
|
|
||||||
|
existing = _get("pronunciation_overrides")
|
||||||
|
if isinstance(existing, list):
|
||||||
|
for entry in existing:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
token_value = str(entry.get("token") or "").strip()
|
||||||
|
pronunciation_value = str(entry.get("pronunciation") or "").strip()
|
||||||
|
if not token_value or not pronunciation_value:
|
||||||
|
continue
|
||||||
|
normalized = str(entry.get("normalized") or "").strip() or normalize_entity_token(token_value)
|
||||||
|
if not normalized:
|
||||||
|
continue
|
||||||
|
collected[normalized] = {
|
||||||
|
"token": token_value,
|
||||||
|
"normalized": normalized,
|
||||||
|
"pronunciation": pronunciation_value,
|
||||||
|
"voice": str(entry.get("voice") or "").strip() or None,
|
||||||
|
"notes": str(entry.get("notes") or "").strip() or None,
|
||||||
|
"context": str(entry.get("context") or "").strip() or None,
|
||||||
|
"source": str(entry.get("source") or "pronunciation"),
|
||||||
|
"language": _get("language"),
|
||||||
|
}
|
||||||
|
|
||||||
|
speakers = _get("speakers")
|
||||||
|
if isinstance(speakers, dict):
|
||||||
|
for payload in speakers.values():
|
||||||
|
if not isinstance(payload, Mapping):
|
||||||
|
continue
|
||||||
|
token_value = str(payload.get("token") or "").strip()
|
||||||
|
pronunciation_value = str(payload.get("pronunciation") or "").strip()
|
||||||
|
if not token_value or not pronunciation_value:
|
||||||
|
continue
|
||||||
|
normalized = normalize_entity_token(token_value)
|
||||||
|
if not normalized:
|
||||||
|
continue
|
||||||
|
collected[normalized] = {
|
||||||
|
"token": token_value,
|
||||||
|
"normalized": normalized,
|
||||||
|
"pronunciation": pronunciation_value,
|
||||||
|
"voice": str(
|
||||||
|
payload.get("resolved_voice")
|
||||||
|
or payload.get("voice")
|
||||||
|
or _get("voice", "")
|
||||||
|
).strip()
|
||||||
|
or None,
|
||||||
|
"notes": None,
|
||||||
|
"context": None,
|
||||||
|
"source": "speaker",
|
||||||
|
"language": _get("language"),
|
||||||
|
}
|
||||||
|
|
||||||
|
manual = _get("manual_overrides")
|
||||||
|
if isinstance(manual, list):
|
||||||
|
for entry in manual:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
token_value = str(entry.get("token") or "").strip()
|
||||||
|
pronunciation_value = str(entry.get("pronunciation") or "").strip()
|
||||||
|
if not token_value or not pronunciation_value:
|
||||||
|
continue
|
||||||
|
normalized = str(entry.get("normalized") or "").strip() or normalize_manual_override_token(token_value)
|
||||||
|
if not normalized:
|
||||||
|
continue
|
||||||
|
collected[normalized] = {
|
||||||
|
"token": token_value,
|
||||||
|
"normalized": normalized,
|
||||||
|
"pronunciation": pronunciation_value,
|
||||||
|
"voice": str(entry.get("voice") or "").strip() or None,
|
||||||
|
"notes": str(entry.get("notes") or "").strip() or None,
|
||||||
|
"context": str(entry.get("context") or "").strip() or None,
|
||||||
|
"source": str(entry.get("source") or "manual"),
|
||||||
|
"language": _get("language"),
|
||||||
|
}
|
||||||
|
|
||||||
|
return list(collected.values())
|
||||||
@@ -0,0 +1,641 @@
|
|||||||
|
"""Shared settings core.
|
||||||
|
|
||||||
|
Defines the SETTINGS_REGISTRY — the single source of truth for all settings.
|
||||||
|
Every setting has a key, type, default, validation rules, and UI scope.
|
||||||
|
Both Web UI and Desktop GUI must reference this registry.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import os
|
||||||
|
import re
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Callable, Dict, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.constants import (
|
||||||
|
KOKORO_CODE_LABELS,
|
||||||
|
SUBTITLE_FORMATS,
|
||||||
|
SUPPORTED_SOUND_FORMATS,
|
||||||
|
)
|
||||||
|
from abogen.tts_plugin.utils import get_default_voice
|
||||||
|
from abogen.normalization_settings import (
|
||||||
|
DEFAULT_LLM_PROMPT,
|
||||||
|
environment_llm_defaults,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
# ── Schema ───────────────────────────────────────────────────────────
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class Setting:
|
||||||
|
"""Contract for a single setting.
|
||||||
|
|
||||||
|
Attributes:
|
||||||
|
key: Config dict key (e.g. "output_format").
|
||||||
|
type_: Python type (bool, int, float, str, list).
|
||||||
|
default: Default value or callable returning one.
|
||||||
|
min_value: Minimum for numeric types.
|
||||||
|
max_value: Maximum for numeric types.
|
||||||
|
valid_values: Allowed values for str types (None = any).
|
||||||
|
gui_only: True if only used by PyQt Desktop GUI.
|
||||||
|
web_only: True if only used by Web UI.
|
||||||
|
normalizer: Optional callable(value, default) -> normalized_value.
|
||||||
|
description: Human-readable explanation.
|
||||||
|
"""
|
||||||
|
key: str
|
||||||
|
type_: type
|
||||||
|
default: Any
|
||||||
|
min_value: float | None = None
|
||||||
|
max_value: float | None = None
|
||||||
|
valid_values: tuple[Any, ...] | None = None
|
||||||
|
gui_only: bool = False
|
||||||
|
web_only: bool = False
|
||||||
|
normalizer: Callable | None = None
|
||||||
|
description: str = ""
|
||||||
|
|
||||||
|
def coerce(self, value: Any, fallback: Any | None = None) -> Any:
|
||||||
|
"""Coerce value to the declared type, returning fallback on failure."""
|
||||||
|
fb = fallback if fallback is not None else self.default
|
||||||
|
if self.type_ is bool:
|
||||||
|
if isinstance(value, bool):
|
||||||
|
return value
|
||||||
|
if isinstance(value, str):
|
||||||
|
return value.lower() in {"true", "1", "yes", "on"}
|
||||||
|
if value is None:
|
||||||
|
return fb
|
||||||
|
return bool(value)
|
||||||
|
if self.type_ is int:
|
||||||
|
try:
|
||||||
|
v = int(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return fb
|
||||||
|
if self.min_value is not None:
|
||||||
|
v = max(int(self.min_value), v)
|
||||||
|
if self.max_value is not None:
|
||||||
|
v = min(int(self.max_value), v)
|
||||||
|
return v
|
||||||
|
if self.type_ is float:
|
||||||
|
try:
|
||||||
|
v = float(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return fb
|
||||||
|
if self.min_value is not None:
|
||||||
|
v = max(self.min_value, v)
|
||||||
|
if self.max_value is not None:
|
||||||
|
v = min(self.max_value, v)
|
||||||
|
return v
|
||||||
|
if self.type_ is str:
|
||||||
|
if isinstance(value, str):
|
||||||
|
v = value.strip()
|
||||||
|
if self.valid_values and v not in self.valid_values:
|
||||||
|
return fb
|
||||||
|
return v
|
||||||
|
return fb
|
||||||
|
if self.type_ is list:
|
||||||
|
if isinstance(value, (list, tuple, set)):
|
||||||
|
return list(value)
|
||||||
|
return fb
|
||||||
|
return value
|
||||||
|
|
||||||
|
|
||||||
|
# ── Normalizers (used by Setting.normalizer) ─────────────────────────
|
||||||
|
|
||||||
|
def _norm_save_mode(value: Any, default: str) -> str:
|
||||||
|
if isinstance(value, str):
|
||||||
|
if value in SAVE_MODE_LABELS:
|
||||||
|
return value
|
||||||
|
if value in LEGACY_SAVE_MODE_MAP:
|
||||||
|
return LEGACY_SAVE_MODE_MAP[value]
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _norm_voice_spec(value: Any, default: str) -> str:
|
||||||
|
if isinstance(value, str):
|
||||||
|
text = value.strip()
|
||||||
|
if not text:
|
||||||
|
return default
|
||||||
|
spec, profile_name = split_profile_spec(text)
|
||||||
|
if profile_name:
|
||||||
|
return f"speaker:{profile_name}"
|
||||||
|
return spec
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _norm_speaker_spec(value: Any, default: str) -> str:
|
||||||
|
if isinstance(value, str):
|
||||||
|
text = value.strip()
|
||||||
|
if not text:
|
||||||
|
return ""
|
||||||
|
spec, profile_name = split_profile_spec(text)
|
||||||
|
if profile_name:
|
||||||
|
return f"speaker:{profile_name}"
|
||||||
|
return spec
|
||||||
|
return ""
|
||||||
|
|
||||||
|
|
||||||
|
def _norm_language_list(value: Any, default: list) -> list:
|
||||||
|
if isinstance(value, (list, tuple, set)):
|
||||||
|
return [code for code in value if isinstance(code, str) and code in KOKORO_CODE_LABELS]
|
||||||
|
if isinstance(value, str):
|
||||||
|
parts = [item.strip().lower() for item in value.split(",") if item.strip()]
|
||||||
|
return [code for code in parts if code in KOKORO_CODE_LABELS]
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _norm_stripped_str(value: Any, default: str) -> str:
|
||||||
|
return str(value or "").strip()
|
||||||
|
|
||||||
|
|
||||||
|
def _norm_prompt(value: Any, default: str) -> str:
|
||||||
|
candidate = str(value or "").strip()
|
||||||
|
return candidate if candidate else default
|
||||||
|
|
||||||
|
|
||||||
|
# ── Registry ─────────────────────────────────────────────────────────
|
||||||
|
|
||||||
|
def _default_output_format() -> str:
|
||||||
|
return "wav"
|
||||||
|
|
||||||
|
|
||||||
|
def _default_save_mode() -> str:
|
||||||
|
return "default_output" if has_output_override() else "save_next_to_input"
|
||||||
|
|
||||||
|
|
||||||
|
def _default_llm(key: str) -> str:
|
||||||
|
return environment_llm_defaults().get(key, "")
|
||||||
|
|
||||||
|
|
||||||
|
SETTINGS_REGISTRY: list[Setting] = [
|
||||||
|
# ── Core output ──────────────────────────────────────────────
|
||||||
|
Setting("output_format", str, "wav",
|
||||||
|
valid_values=tuple(SUPPORTED_SOUND_FORMATS),
|
||||||
|
description="Audio output format"),
|
||||||
|
Setting("subtitle_format", str, "srt",
|
||||||
|
valid_values=tuple(item[0] for item in SUBTITLE_FORMATS),
|
||||||
|
description="Subtitle file format"),
|
||||||
|
Setting("save_mode", str, _default_save_mode,
|
||||||
|
normalizer=_norm_save_mode,
|
||||||
|
description="Where to save output files"),
|
||||||
|
Setting("separate_chapters_format", str, "wav",
|
||||||
|
valid_values=("wav", "flac", "mp3", "opus"),
|
||||||
|
description="Format for separately saved chapters"),
|
||||||
|
Setting("chunk_level", str, "paragraph",
|
||||||
|
valid_values=("paragraph", "sentence"),
|
||||||
|
description="Text chunking granularity"),
|
||||||
|
|
||||||
|
# ── Voice ────────────────────────────────────────────────────
|
||||||
|
Setting("default_speaker", str, "",
|
||||||
|
normalizer=_norm_speaker_spec,
|
||||||
|
description="Default speaker name"),
|
||||||
|
Setting("default_voice", str, lambda: get_default_voice("kokoro"),
|
||||||
|
normalizer=_norm_voice_spec,
|
||||||
|
description="Default TTS voice"),
|
||||||
|
Setting("speed", float, 1.0, min_value=0.5, max_value=3.0,
|
||||||
|
gui_only=True,
|
||||||
|
description="TTS speed multiplier"),
|
||||||
|
Setting("supertonic_total_steps", int, 5, min_value=2, max_value=15,
|
||||||
|
description="SuperTonic processing steps"),
|
||||||
|
Setting("supertonic_speed", float, 1.0, min_value=0.7, max_value=2.0,
|
||||||
|
description="SuperTonic speed"),
|
||||||
|
|
||||||
|
# ── Chapter handling ─────────────────────────────────────────
|
||||||
|
Setting("silence_between_chapters", float, 2.0, min_value=0.0,
|
||||||
|
description="Silence gap between chapters (seconds)"),
|
||||||
|
Setting("chapter_intro_delay", float, 0.5, min_value=0.0,
|
||||||
|
description="Delay after chapter heading (seconds)"),
|
||||||
|
Setting("read_title_intro", bool, False,
|
||||||
|
description="Read chapter title as intro"),
|
||||||
|
Setting("read_closing_outro", bool, True,
|
||||||
|
description="Read closing/outro text"),
|
||||||
|
Setting("normalize_chapter_opening_caps", bool, True,
|
||||||
|
description="Normalize chapter opening caps"),
|
||||||
|
Setting("auto_prefix_chapter_titles", bool, True,
|
||||||
|
description="Auto-prefix chapter titles"),
|
||||||
|
Setting("save_chapters_separately", bool, False,
|
||||||
|
description="Save each chapter as separate file"),
|
||||||
|
Setting("merge_chapters_at_end", bool, True,
|
||||||
|
description="Merge chapters into single file"),
|
||||||
|
Setting("save_as_project", bool, False,
|
||||||
|
description="Save as editable project"),
|
||||||
|
Setting("generate_epub3", bool, False,
|
||||||
|
description="Generate EPUB3 output"),
|
||||||
|
|
||||||
|
# ── GPU / performance ────────────────────────────────────────
|
||||||
|
Setting("use_gpu", bool, True,
|
||||||
|
description="Use GPU acceleration"),
|
||||||
|
|
||||||
|
# ── Text processing ──────────────────────────────────────────
|
||||||
|
Setting("replace_single_newlines", bool, False,
|
||||||
|
description="Replace single newlines with spaces"),
|
||||||
|
Setting("max_subtitle_words", int, 50, min_value=1, max_value=500,
|
||||||
|
description="Max words per subtitle"),
|
||||||
|
Setting("enable_entity_recognition", bool, True,
|
||||||
|
description="Enable entity recognition"),
|
||||||
|
|
||||||
|
# ── Speaker analysis ─────────────────────────────────────────
|
||||||
|
Setting("speaker_analysis_threshold", int, 3, min_value=1, max_value=25,
|
||||||
|
description="Speaker analysis threshold"),
|
||||||
|
Setting("speaker_pronunciation_sentence", str, "This is {{name}} speaking.",
|
||||||
|
description="Template for pronunciation samples"),
|
||||||
|
Setting("speaker_random_languages", list, [],
|
||||||
|
normalizer=_norm_language_list,
|
||||||
|
description="Languages for random speaker assignment"),
|
||||||
|
|
||||||
|
# ── LLM ──────────────────────────────────────────────────────
|
||||||
|
Setting("llm_base_url", str, lambda: _default_llm("llm_base_url"),
|
||||||
|
normalizer=_norm_stripped_str,
|
||||||
|
description="LLM API base URL"),
|
||||||
|
Setting("llm_api_key", str, lambda: _default_llm("llm_api_key"),
|
||||||
|
normalizer=_norm_stripped_str,
|
||||||
|
description="LLM API key"),
|
||||||
|
Setting("llm_model", str, lambda: _default_llm("llm_model"),
|
||||||
|
normalizer=_norm_stripped_str,
|
||||||
|
description="LLM model name"),
|
||||||
|
Setting("llm_timeout", float, lambda: _default_llm("llm_timeout") or 30.0,
|
||||||
|
min_value=1.0,
|
||||||
|
description="LLM request timeout"),
|
||||||
|
Setting("llm_prompt", str, lambda: _default_llm("llm_prompt") or DEFAULT_LLM_PROMPT,
|
||||||
|
normalizer=_norm_prompt,
|
||||||
|
description="LLM normalization prompt"),
|
||||||
|
Setting("llm_context_mode", str, lambda: _default_llm("llm_context_mode") or "sentence",
|
||||||
|
valid_values=("sentence",),
|
||||||
|
description="LLM context mode"),
|
||||||
|
|
||||||
|
# ── Normalization (booleans) ─────────────────────────────────
|
||||||
|
Setting("normalization_numbers", bool, True,
|
||||||
|
description="Convert grouped numbers to words"),
|
||||||
|
Setting("normalization_currency", bool, True,
|
||||||
|
description="Convert currency symbols"),
|
||||||
|
Setting("normalization_footnotes", bool, True,
|
||||||
|
description="Remove footnote indicators"),
|
||||||
|
Setting("normalization_titles", bool, True,
|
||||||
|
description="Expand titles and suffixes"),
|
||||||
|
Setting("normalization_terminal", bool, True,
|
||||||
|
description="Ensure terminal punctuation"),
|
||||||
|
Setting("normalization_phoneme_hints", bool, True,
|
||||||
|
description="Add phoneme hints for possessives"),
|
||||||
|
Setting("normalization_caps_quotes", bool, True,
|
||||||
|
description="Convert ALL CAPS in quotes"),
|
||||||
|
Setting("normalization_internet_slang", bool, False,
|
||||||
|
description="Expand internet slang"),
|
||||||
|
Setting("normalization_apostrophes_contractions", bool, True,
|
||||||
|
description="Expand contractions"),
|
||||||
|
Setting("normalization_apostrophes_plural_possessives", bool, True,
|
||||||
|
description="Collapse plural possessives"),
|
||||||
|
Setting("normalization_apostrophes_sibilant_possessives", bool, True,
|
||||||
|
description="Mark sibilant possessives"),
|
||||||
|
Setting("normalization_apostrophes_decades", bool, True,
|
||||||
|
description="Expand decades"),
|
||||||
|
Setting("normalization_apostrophes_leading_elisions", bool, True,
|
||||||
|
description="Expand leading elisions"),
|
||||||
|
Setting("normalization_contraction_aux_be", bool, True,
|
||||||
|
description="Expand auxiliary 'be'"),
|
||||||
|
Setting("normalization_contraction_aux_have", bool, True,
|
||||||
|
description="Expand auxiliary 'have'"),
|
||||||
|
Setting("normalization_contraction_modal_will", bool, True,
|
||||||
|
description="Expand modal 'will'"),
|
||||||
|
Setting("normalization_contraction_modal_would", bool, True,
|
||||||
|
description="Expand modal 'would'"),
|
||||||
|
Setting("normalization_contraction_negation_not", bool, True,
|
||||||
|
description="Expand negation 'not'"),
|
||||||
|
Setting("normalization_contraction_let_us", bool, True,
|
||||||
|
description="Expand 'let's'"),
|
||||||
|
|
||||||
|
# ── Normalization (strings) ──────────────────────────────────
|
||||||
|
Setting("normalization_apostrophe_mode", str, "spacy",
|
||||||
|
valid_values=("off", "spacy", "llm"),
|
||||||
|
description="Apostrophe handling mode"),
|
||||||
|
Setting("normalization_numbers_year_style", str, "american",
|
||||||
|
valid_values=("american", "off"),
|
||||||
|
description="Year style for number normalization"),
|
||||||
|
|
||||||
|
# ── PyQt GUI-only ────────────────────────────────────────────
|
||||||
|
Setting("theme", str, "system",
|
||||||
|
gui_only=True,
|
||||||
|
description="UI theme"),
|
||||||
|
Setting("check_updates", bool, True,
|
||||||
|
gui_only=True,
|
||||||
|
description="Check for updates on startup"),
|
||||||
|
Setting("subtitle_mode", str, "Sentence",
|
||||||
|
gui_only=True,
|
||||||
|
description="Subtitle display mode"),
|
||||||
|
Setting("selected_format", str, "wav",
|
||||||
|
gui_only=True,
|
||||||
|
description="Last selected audio format"),
|
||||||
|
Setting("selected_voice", str, "af_heart",
|
||||||
|
gui_only=True,
|
||||||
|
description="Last selected voice"),
|
||||||
|
Setting("selected_profile_name", str, None,
|
||||||
|
gui_only=True,
|
||||||
|
description="Last selected profile name"),
|
||||||
|
Setting("log_window_max_lines", int, 2000, min_value=100,
|
||||||
|
gui_only=True,
|
||||||
|
description="Max lines in log window"),
|
||||||
|
Setting("use_silent_gaps", bool, True,
|
||||||
|
gui_only=True,
|
||||||
|
description="Use silent gaps between chunks"),
|
||||||
|
Setting("subtitle_speed_method", str, "tts",
|
||||||
|
gui_only=True,
|
||||||
|
valid_values=("tts", "ffmpeg"),
|
||||||
|
description="Speed adjustment method for subtitles"),
|
||||||
|
Setting("use_spacy_segmentation", bool, True,
|
||||||
|
gui_only=True,
|
||||||
|
description="Use spaCy for sentence segmentation"),
|
||||||
|
Setting("word_substitutions_enabled", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Enable word substitutions"),
|
||||||
|
Setting("word_substitutions_list", str, "",
|
||||||
|
gui_only=True,
|
||||||
|
description="Word substitutions list"),
|
||||||
|
Setting("case_sensitive_substitutions", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Case-sensitive substitutions"),
|
||||||
|
Setting("replace_all_caps", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Replace ALL CAPS text"),
|
||||||
|
Setting("replace_numerals", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Replace numerals with words"),
|
||||||
|
Setting("fix_nonstandard_punctuation", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Fix nonstandard punctuation"),
|
||||||
|
Setting("queue_override_settings", bool, False,
|
||||||
|
gui_only=True,
|
||||||
|
description="Override settings per queue item"),
|
||||||
|
Setting("disable_kokoro_internet", bool, False,
|
||||||
|
description="Disable Kokoro internet access"),
|
||||||
|
]
|
||||||
|
|
||||||
|
|
||||||
|
# ── Registry helpers ─────────────────────────────────────────────────
|
||||||
|
|
||||||
|
_REGISTRY_BY_KEY: dict[str, Setting] = {s.key: s for s in SETTINGS_REGISTRY}
|
||||||
|
|
||||||
|
SETTING_KEYS: frozenset[str] = frozenset(_REGISTRY_BY_KEY.keys())
|
||||||
|
GUI_ONLY_KEYS: frozenset[str] = frozenset(s.key for s in SETTINGS_REGISTRY if s.gui_only)
|
||||||
|
WEB_ONLY_KEYS: frozenset[str] = frozenset(s.key for s in SETTINGS_REGISTRY if s.web_only)
|
||||||
|
SHARED_KEYS: frozenset[str] = SETTING_KEYS - GUI_ONLY_KEYS - WEB_ONLY_KEYS
|
||||||
|
|
||||||
|
BOOLEAN_SETTINGS: frozenset[str] = frozenset(s.key for s in SETTINGS_REGISTRY if s.type_ is bool)
|
||||||
|
FLOAT_SETTINGS: frozenset[str] = frozenset(s.key for s in SETTINGS_REGISTRY if s.type_ is float)
|
||||||
|
INT_SETTINGS: frozenset[str] = frozenset(s.key for s in SETTINGS_REGISTRY if s.type_ is int)
|
||||||
|
|
||||||
|
# Backward-compatible aliases (used by existing code)
|
||||||
|
_NORMALIZATION_BOOLEAN_KEYS: frozenset[str] = frozenset(
|
||||||
|
s.key for s in SETTINGS_REGISTRY
|
||||||
|
if s.type_ is bool and s.key.startswith("normalization_")
|
||||||
|
)
|
||||||
|
_NORMALIZATION_STRING_KEYS: frozenset[str] = frozenset(
|
||||||
|
s.key for s in SETTINGS_REGISTRY
|
||||||
|
if s.type_ is str and s.key.startswith("normalization_")
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def get_setting(key: str) -> Setting | None:
|
||||||
|
"""Look up a setting by key."""
|
||||||
|
return _REGISTRY_BY_KEY.get(key)
|
||||||
|
|
||||||
|
|
||||||
|
def has_output_override() -> bool:
|
||||||
|
return bool(os.environ.get("ABOGEN_OUTPUT_DIR") or os.environ.get("ABOGEN_OUTPUT_ROOT"))
|
||||||
|
|
||||||
|
|
||||||
|
# ── Defaults ─────────────────────────────────────────────────────────
|
||||||
|
|
||||||
|
def settings_defaults() -> Dict[str, Any]:
|
||||||
|
"""Default values for all shared settings (excludes gui_only)."""
|
||||||
|
result: Dict[str, Any] = {}
|
||||||
|
for s in SETTINGS_REGISTRY:
|
||||||
|
if s.gui_only:
|
||||||
|
continue
|
||||||
|
result[s.key] = s.default() if callable(s.default) else s.default
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
def all_settings_defaults() -> Dict[str, Any]:
|
||||||
|
"""Default values for ALL settings (including gui_only)."""
|
||||||
|
result: Dict[str, Any] = {}
|
||||||
|
for s in SETTINGS_REGISTRY:
|
||||||
|
result[s.key] = s.default() if callable(s.default) else s.default
|
||||||
|
return result
|
||||||
|
|
||||||
|
|
||||||
|
def load_settings() -> Dict[str, Any]:
|
||||||
|
"""Load and normalize settings from config file."""
|
||||||
|
from abogen.utils import load_config
|
||||||
|
defaults = settings_defaults()
|
||||||
|
cfg = load_config() or {}
|
||||||
|
settings: Dict[str, Any] = {}
|
||||||
|
for key, default in defaults.items():
|
||||||
|
raw_value = cfg.get(key, default)
|
||||||
|
settings[key] = normalize_setting_value(key, raw_value, defaults)
|
||||||
|
return settings
|
||||||
|
|
||||||
|
|
||||||
|
# ── Normalization (delegates to Setting.coerce) ──────────────────────
|
||||||
|
|
||||||
|
def normalize_setting_value(key: str, value: Any, defaults: Dict[str, Any]) -> Any:
|
||||||
|
"""Normalize a single setting value using the registry schema."""
|
||||||
|
setting = _REGISTRY_BY_KEY.get(key)
|
||||||
|
if setting is None:
|
||||||
|
return value if value is not None else defaults.get(key)
|
||||||
|
|
||||||
|
fallback = defaults.get(key, setting.default() if callable(setting.default) else setting.default)
|
||||||
|
|
||||||
|
if setting.normalizer is not None:
|
||||||
|
return setting.normalizer(value, fallback)
|
||||||
|
|
||||||
|
return setting.coerce(value, fallback)
|
||||||
|
|
||||||
|
|
||||||
|
def validate_setting(key: str, value: Any) -> tuple[bool, str]:
|
||||||
|
"""Validate a setting value against its schema. Returns (ok, error_message)."""
|
||||||
|
setting = _REGISTRY_BY_KEY.get(key)
|
||||||
|
if setting is None:
|
||||||
|
return False, f"Unknown setting: {key}"
|
||||||
|
if setting.type_ is str and setting.valid_values is not None:
|
||||||
|
v = str(value or "").strip()
|
||||||
|
if v and v not in setting.valid_values:
|
||||||
|
return False, f"Invalid value '{v}' for {key}. Allowed: {setting.valid_values}"
|
||||||
|
if setting.type_ is int:
|
||||||
|
try:
|
||||||
|
iv = int(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return False, f"Invalid integer value for {key}: {value!r}"
|
||||||
|
if setting.min_value is not None and iv < setting.min_value:
|
||||||
|
return False, f"{key} must be >= {setting.min_value}, got {iv}"
|
||||||
|
if setting.max_value is not None and iv > setting.max_value:
|
||||||
|
return False, f"{key} must be <= {setting.max_value}, got {iv}"
|
||||||
|
if setting.type_ is float:
|
||||||
|
try:
|
||||||
|
fv = float(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return False, f"Invalid float value for {key}: {value!r}"
|
||||||
|
if setting.min_value is not None and fv < setting.min_value:
|
||||||
|
return False, f"{key} must be >= {setting.min_value}, got {fv}"
|
||||||
|
if setting.max_value is not None and fv > setting.max_value:
|
||||||
|
return False, f"{key} must be <= {setting.max_value}, got {fv}"
|
||||||
|
return True, ""
|
||||||
|
|
||||||
|
|
||||||
|
# ── Constants (backward-compatible) ──────────────────────────────────
|
||||||
|
|
||||||
|
SAVE_MODE_LABELS = {
|
||||||
|
"save_next_to_input": "Save next to input file",
|
||||||
|
"save_to_desktop": "Save to Desktop",
|
||||||
|
"choose_output_folder": "Choose output folder",
|
||||||
|
"default_output": "Use default save location",
|
||||||
|
}
|
||||||
|
|
||||||
|
LEGACY_SAVE_MODE_MAP = {label: key for key, label in SAVE_MODE_LABELS.items()}
|
||||||
|
|
||||||
|
CHUNK_LEVEL_OPTIONS = [
|
||||||
|
{"value": "paragraph", "label": "Paragraphs"},
|
||||||
|
{"value": "sentence", "label": "Sentences"},
|
||||||
|
]
|
||||||
|
|
||||||
|
CHUNK_LEVEL_VALUES = frozenset(option["value"] for option in CHUNK_LEVEL_OPTIONS)
|
||||||
|
|
||||||
|
DEFAULT_ANALYSIS_THRESHOLD = 3
|
||||||
|
|
||||||
|
|
||||||
|
# ── Coercion helpers (backward-compatible, delegate to Setting.coerce) ──
|
||||||
|
|
||||||
|
def coerce_bool(value: Any, default: bool) -> bool:
|
||||||
|
return Setting("_", bool, default).coerce(value, default)
|
||||||
|
|
||||||
|
|
||||||
|
def coerce_float(value: Any, default: float) -> float:
|
||||||
|
return Setting("_", float, default).coerce(value, default)
|
||||||
|
|
||||||
|
|
||||||
|
def coerce_int(value: Any, default: int, *, minimum: int = 1, maximum: int = 200) -> int:
|
||||||
|
return Setting("_", int, default, min_value=minimum, max_value=maximum).coerce(value, default)
|
||||||
|
|
||||||
|
|
||||||
|
def split_profile_spec(value: Any) -> tuple[str, str | None]:
|
||||||
|
"""Split 'speaker:Name' or 'profile:Name' into (raw, name)."""
|
||||||
|
text = str(value or "").strip()
|
||||||
|
if not text:
|
||||||
|
return "", None
|
||||||
|
lowered = text.lower()
|
||||||
|
if lowered.startswith("profile:") or lowered.startswith("speaker:"):
|
||||||
|
_, _, remainder = text.partition(":")
|
||||||
|
name = remainder.strip()
|
||||||
|
return "", name or None
|
||||||
|
return text, None
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_save_mode(value: Any, default: str) -> str:
|
||||||
|
return _norm_save_mode(value, default)
|
||||||
|
|
||||||
|
|
||||||
|
# ── LLM helpers ──────────────────────────────────────────────────────
|
||||||
|
|
||||||
|
_PROMPT_TOKEN_RE = re.compile(r"{{\s*([a-zA-Z0-9_]+)\s*}}")
|
||||||
|
|
||||||
|
|
||||||
|
def llm_ready(settings: Mapping[str, Any]) -> bool:
|
||||||
|
base_url = str(settings.get("llm_base_url") or "").strip()
|
||||||
|
return bool(base_url)
|
||||||
|
|
||||||
|
|
||||||
|
def render_prompt_template(template: str, context: Mapping[str, str]) -> str:
|
||||||
|
if not template:
|
||||||
|
return ""
|
||||||
|
|
||||||
|
def _replace(match: re.Match[str]) -> str:
|
||||||
|
key = match.group(1)
|
||||||
|
return context.get(key, "")
|
||||||
|
|
||||||
|
return _PROMPT_TOKEN_RE.sub(_replace, template)
|
||||||
|
|
||||||
|
|
||||||
|
# ── Integration defaults ─────────────────────────────────────────────
|
||||||
|
|
||||||
|
def integration_defaults() -> Dict[str, Dict[str, Any]]:
|
||||||
|
"""Default values for integration settings."""
|
||||||
|
return {
|
||||||
|
"calibre_opds": {
|
||||||
|
"enabled": False,
|
||||||
|
"base_url": "",
|
||||||
|
"username": "",
|
||||||
|
"password": "",
|
||||||
|
"verify_ssl": True,
|
||||||
|
},
|
||||||
|
"audiobookshelf": {
|
||||||
|
"enabled": False,
|
||||||
|
"base_url": "",
|
||||||
|
"api_token": "",
|
||||||
|
"library_id": "",
|
||||||
|
"collection_id": "",
|
||||||
|
"folder_id": "",
|
||||||
|
"verify_ssl": True,
|
||||||
|
"send_cover": True,
|
||||||
|
"send_chapters": True,
|
||||||
|
"send_subtitles": False,
|
||||||
|
"auto_send": False,
|
||||||
|
"timeout": 30.0,
|
||||||
|
},
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def stored_integration_config(name: str) -> Dict[str, Any]:
|
||||||
|
"""Read raw integration config from config.json.
|
||||||
|
|
||||||
|
Reads ``config["integrations"][name]``.
|
||||||
|
"""
|
||||||
|
from abogen.utils import load_config
|
||||||
|
|
||||||
|
cfg = load_config() or {}
|
||||||
|
integrations = cfg.get("integrations")
|
||||||
|
if isinstance(integrations, Mapping):
|
||||||
|
entry = integrations.get(name)
|
||||||
|
if isinstance(entry, Mapping):
|
||||||
|
return dict(entry)
|
||||||
|
return {}
|
||||||
|
|
||||||
|
|
||||||
|
def load_audiobookshelf_config() -> Optional["AudiobookshelfConfig"]:
|
||||||
|
"""Read Audiobookshelf settings from config.json and build typed config.
|
||||||
|
|
||||||
|
Returns ``None`` when the integration is not configured or required
|
||||||
|
fields are missing.
|
||||||
|
"""
|
||||||
|
raw = stored_integration_config("audiobookshelf")
|
||||||
|
if not raw:
|
||||||
|
return None
|
||||||
|
return build_audiobookshelf_config(raw)
|
||||||
|
|
||||||
|
|
||||||
|
def build_audiobookshelf_config(
|
||||||
|
settings: Mapping[str, Any],
|
||||||
|
) -> Optional["AudiobookshelfConfig"]:
|
||||||
|
"""Build :class:`AudiobookshelfConfig` from a settings dict.
|
||||||
|
|
||||||
|
Returns ``None`` when required fields (base_url, api_token, library_id)
|
||||||
|
are missing.
|
||||||
|
"""
|
||||||
|
from abogen.integrations.audiobookshelf import AudiobookshelfConfig
|
||||||
|
|
||||||
|
base_url = str(settings.get("base_url") or "").strip()
|
||||||
|
api_token = str(settings.get("api_token") or "").strip()
|
||||||
|
library_id = str(settings.get("library_id") or "").strip()
|
||||||
|
if not (base_url and api_token and library_id):
|
||||||
|
return None
|
||||||
|
try:
|
||||||
|
timeout = float(settings.get("timeout", 3600.0))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
timeout = 3600.0
|
||||||
|
return AudiobookshelfConfig(
|
||||||
|
base_url=base_url,
|
||||||
|
api_token=api_token,
|
||||||
|
library_id=library_id,
|
||||||
|
collection_id=(str(settings.get("collection_id") or "").strip() or None),
|
||||||
|
folder_id=(str(settings.get("folder_id") or "").strip() or None),
|
||||||
|
verify_ssl=coerce_bool(settings.get("verify_ssl"), True),
|
||||||
|
send_cover=coerce_bool(settings.get("send_cover"), True),
|
||||||
|
send_chapters=coerce_bool(settings.get("send_chapters"), True),
|
||||||
|
send_subtitles=coerce_bool(settings.get("send_subtitles"), False),
|
||||||
|
timeout=timeout,
|
||||||
|
)
|
||||||
@@ -0,0 +1,381 @@
|
|||||||
|
"""Speaker metadata functions for building and applying speaker rosters.
|
||||||
|
|
||||||
|
This module contains the core logic for:
|
||||||
|
- Building narrator and speaker rosters from analysis results
|
||||||
|
- Matching speakers to configured presets
|
||||||
|
- Applying speaker config presets to rosters
|
||||||
|
- Preparing full speaker metadata for conversion
|
||||||
|
|
||||||
|
Moved from webui/routes/utils/voice.py to be available across all UIs.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional, Tuple, cast
|
||||||
|
|
||||||
|
from abogen.speaker_analysis import analyze_speakers
|
||||||
|
from abogen.speaker_configs import slugify_label
|
||||||
|
from abogen.domain.settings_core import load_settings
|
||||||
|
|
||||||
|
|
||||||
|
def build_narrator_roster(
|
||||||
|
voice: str,
|
||||||
|
voice_profile: Optional[str],
|
||||||
|
existing: Optional[Mapping[str, Any]] = None,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
roster: Dict[str, Any] = {
|
||||||
|
"narrator": {
|
||||||
|
"id": "narrator",
|
||||||
|
"label": "Narrator",
|
||||||
|
"voice": voice,
|
||||||
|
}
|
||||||
|
}
|
||||||
|
if voice_profile:
|
||||||
|
roster["narrator"]["voice_profile"] = voice_profile
|
||||||
|
existing_entry: Optional[Mapping[str, Any]] = None
|
||||||
|
if existing is not None:
|
||||||
|
existing_entry = existing.get("narrator") if isinstance(existing, Mapping) else None
|
||||||
|
if isinstance(existing_entry, Mapping):
|
||||||
|
roster_entry = roster["narrator"]
|
||||||
|
for key in ("label", "voice", "voice_profile", "voice_formula", "pronunciation"):
|
||||||
|
value = existing_entry.get(key)
|
||||||
|
if value is not None and value != "":
|
||||||
|
roster_entry[key] = value
|
||||||
|
return roster
|
||||||
|
|
||||||
|
|
||||||
|
def build_speaker_roster(
|
||||||
|
analysis: Dict[str, Any],
|
||||||
|
base_voice: str,
|
||||||
|
voice_profile: Optional[str],
|
||||||
|
existing: Optional[Mapping[str, Any]] = None,
|
||||||
|
order: Optional[Iterable[str]] = None,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
roster = build_narrator_roster(base_voice, voice_profile, existing)
|
||||||
|
existing_map: Dict[str, Any] = dict(existing) if isinstance(existing, Mapping) else {}
|
||||||
|
speakers = analysis.get("speakers", {}) if isinstance(analysis, dict) else {}
|
||||||
|
ordered_ids: Iterable[str]
|
||||||
|
if order is not None:
|
||||||
|
ordered_ids = [sid for sid in order if sid in speakers]
|
||||||
|
else:
|
||||||
|
ordered_ids = speakers.keys()
|
||||||
|
|
||||||
|
for speaker_id in ordered_ids:
|
||||||
|
payload = speakers.get(speaker_id, {})
|
||||||
|
if speaker_id == "narrator":
|
||||||
|
continue
|
||||||
|
if isinstance(payload, Mapping) and payload.get("suppressed"):
|
||||||
|
continue
|
||||||
|
previous = existing_map.get(speaker_id)
|
||||||
|
roster[speaker_id] = {
|
||||||
|
"id": speaker_id,
|
||||||
|
"label": payload.get("label") or speaker_id.replace("_", " ").title(),
|
||||||
|
"analysis_confidence": payload.get("confidence"),
|
||||||
|
"analysis_count": payload.get("count"),
|
||||||
|
"gender": payload.get("gender", "unknown"),
|
||||||
|
}
|
||||||
|
detected_gender = payload.get("detected_gender")
|
||||||
|
if detected_gender:
|
||||||
|
roster[speaker_id]["detected_gender"] = detected_gender
|
||||||
|
samples = payload.get("sample_quotes")
|
||||||
|
if isinstance(samples, list):
|
||||||
|
roster[speaker_id]["sample_quotes"] = samples
|
||||||
|
if isinstance(previous, Mapping):
|
||||||
|
for key in ("voice", "voice_profile", "voice_formula", "resolved_voice", "pronunciation"):
|
||||||
|
value = previous.get(key)
|
||||||
|
if value is not None and value != "":
|
||||||
|
roster[speaker_id][key] = value
|
||||||
|
if "sample_quotes" not in roster[speaker_id]:
|
||||||
|
prev_samples = previous.get("sample_quotes")
|
||||||
|
if isinstance(prev_samples, list):
|
||||||
|
roster[speaker_id]["sample_quotes"] = prev_samples
|
||||||
|
if "detected_gender" not in roster[speaker_id]:
|
||||||
|
prev_detected = previous.get("detected_gender")
|
||||||
|
if isinstance(prev_detected, str) and prev_detected:
|
||||||
|
roster[speaker_id]["detected_gender"] = prev_detected
|
||||||
|
return roster
|
||||||
|
|
||||||
|
|
||||||
|
def match_configured_speaker(
|
||||||
|
config_speakers: Mapping[str, Any],
|
||||||
|
roster_id: str,
|
||||||
|
roster_label: str,
|
||||||
|
) -> Optional[Mapping[str, Any]]:
|
||||||
|
if not config_speakers:
|
||||||
|
return None
|
||||||
|
entry = config_speakers.get(roster_id)
|
||||||
|
if entry:
|
||||||
|
return cast(Mapping[str, Any], entry)
|
||||||
|
slug = slugify_label(roster_label)
|
||||||
|
if slug != roster_id and slug in config_speakers:
|
||||||
|
return cast(Mapping[str, Any], config_speakers[slug])
|
||||||
|
lower_label = roster_label.strip().lower()
|
||||||
|
for record in config_speakers.values():
|
||||||
|
if not isinstance(record, Mapping):
|
||||||
|
continue
|
||||||
|
if str(record.get("label", "")).strip().lower() == lower_label:
|
||||||
|
return record
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def apply_speaker_config_to_roster(
|
||||||
|
roster: Mapping[str, Any],
|
||||||
|
config: Optional[Mapping[str, Any]],
|
||||||
|
*,
|
||||||
|
persist_changes: bool = False,
|
||||||
|
fallback_languages: Optional[Iterable[str]] = None,
|
||||||
|
) -> Tuple[Dict[str, Any], List[str], Optional[Dict[str, Any]]]:
|
||||||
|
if not isinstance(roster, Mapping):
|
||||||
|
effective_languages = [code for code in (fallback_languages or []) if isinstance(code, str) and code]
|
||||||
|
return {}, effective_languages, None
|
||||||
|
updated_roster: Dict[str, Any] = {key: dict(value) for key, value in roster.items() if isinstance(value, Mapping)}
|
||||||
|
if not config:
|
||||||
|
effective_languages = [code for code in (fallback_languages or []) if isinstance(code, str) and code]
|
||||||
|
return updated_roster, effective_languages, None
|
||||||
|
|
||||||
|
speakers_map = config.get("speakers")
|
||||||
|
if not isinstance(speakers_map, Mapping):
|
||||||
|
effective_languages = [code for code in (fallback_languages or []) if isinstance(code, str) and code]
|
||||||
|
return updated_roster, effective_languages, None
|
||||||
|
|
||||||
|
config_languages = config.get("languages")
|
||||||
|
if isinstance(config_languages, list):
|
||||||
|
allowed_languages = [code for code in config_languages if isinstance(code, str) and code]
|
||||||
|
else:
|
||||||
|
allowed_languages = []
|
||||||
|
if not allowed_languages and fallback_languages:
|
||||||
|
allowed_languages = [code for code in fallback_languages if isinstance(code, str) and code]
|
||||||
|
|
||||||
|
default_voice = config.get("default_voice") if isinstance(config.get("default_voice"), str) else ""
|
||||||
|
used_voices = {entry.get("resolved_voice") or entry.get("voice") for entry in updated_roster.values()} - {None}
|
||||||
|
narrator_voice = ""
|
||||||
|
narrator_entry = updated_roster.get("narrator") if isinstance(updated_roster, Mapping) else None
|
||||||
|
if isinstance(narrator_entry, Mapping):
|
||||||
|
narrator_voice = str(
|
||||||
|
narrator_entry.get("resolved_voice")
|
||||||
|
or narrator_entry.get("default_voice")
|
||||||
|
or ""
|
||||||
|
).strip()
|
||||||
|
if narrator_voice:
|
||||||
|
used_voices.add(narrator_voice)
|
||||||
|
|
||||||
|
config_changed = False
|
||||||
|
new_config_payload: Dict[str, Any] = {
|
||||||
|
"language": config.get("language", "a"),
|
||||||
|
"languages": allowed_languages,
|
||||||
|
"default_voice": default_voice,
|
||||||
|
"speakers": dict(speakers_map),
|
||||||
|
"version": config.get("version", 1),
|
||||||
|
"notes": config.get("notes", ""),
|
||||||
|
}
|
||||||
|
|
||||||
|
speakers_payload = new_config_payload["speakers"]
|
||||||
|
|
||||||
|
for speaker_id, roster_entry in updated_roster.items():
|
||||||
|
if speaker_id == "narrator":
|
||||||
|
continue
|
||||||
|
label = str(roster_entry.get("label") or speaker_id)
|
||||||
|
config_entry = match_configured_speaker(speakers_map, speaker_id, label)
|
||||||
|
if config_entry is None:
|
||||||
|
continue
|
||||||
|
voice_id = str(config_entry.get("voice") or "").strip()
|
||||||
|
voice_profile = str(config_entry.get("voice_profile") or "").strip()
|
||||||
|
voice_formula = str(config_entry.get("voice_formula") or "").strip()
|
||||||
|
resolved_voice = str(config_entry.get("resolved_voice") or "").strip()
|
||||||
|
languages = config_entry.get("languages") if isinstance(config_entry.get("languages"), list) else []
|
||||||
|
chosen_voice = resolved_voice or voice_formula or voice_id or roster_entry.get("voice")
|
||||||
|
usable_languages = languages or allowed_languages
|
||||||
|
|
||||||
|
if chosen_voice:
|
||||||
|
roster_entry["resolved_voice"] = chosen_voice
|
||||||
|
roster_entry["voice"] = chosen_voice if not voice_profile and not voice_formula else roster_entry.get("voice", chosen_voice)
|
||||||
|
if voice_profile:
|
||||||
|
roster_entry["voice_profile"] = voice_profile
|
||||||
|
if voice_formula:
|
||||||
|
roster_entry["voice_formula"] = voice_formula
|
||||||
|
roster_entry["resolved_voice"] = voice_formula
|
||||||
|
if not voice_formula and not voice_profile and resolved_voice:
|
||||||
|
roster_entry["resolved_voice"] = resolved_voice
|
||||||
|
roster_entry["config_languages"] = usable_languages or []
|
||||||
|
|
||||||
|
if chosen_voice:
|
||||||
|
used_voices.add(chosen_voice)
|
||||||
|
|
||||||
|
# persist updates back to config payload if required
|
||||||
|
if persist_changes:
|
||||||
|
slug = config_entry.get("id") or slugify_label(label)
|
||||||
|
speakers_payload[slug] = {
|
||||||
|
"id": slug,
|
||||||
|
"label": label,
|
||||||
|
"gender": config_entry.get("gender", "unknown"),
|
||||||
|
"voice": voice_id,
|
||||||
|
"voice_profile": voice_profile,
|
||||||
|
"voice_formula": voice_formula,
|
||||||
|
"resolved_voice": roster_entry.get("resolved_voice", resolved_voice or voice_id),
|
||||||
|
"languages": usable_languages,
|
||||||
|
}
|
||||||
|
|
||||||
|
new_config = new_config_payload if (persist_changes and config_changed) else None
|
||||||
|
return updated_roster, allowed_languages, new_config
|
||||||
|
|
||||||
|
|
||||||
|
def prepare_speaker_metadata(
|
||||||
|
*,
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
chunks: List[Dict[str, Any]],
|
||||||
|
analysis_chunks: Optional[List[Dict[str, Any]]] = None,
|
||||||
|
voice: str,
|
||||||
|
voice_profile: Optional[str],
|
||||||
|
threshold: int,
|
||||||
|
existing_roster: Optional[Mapping[str, Any]] = None,
|
||||||
|
run_analysis: bool = True,
|
||||||
|
speaker_config: Optional[Mapping[str, Any]] = None,
|
||||||
|
apply_config: bool = False,
|
||||||
|
persist_config: bool = False,
|
||||||
|
inject_recommended: Optional[Any] = None,
|
||||||
|
) -> tuple[List[Dict[str, Any]], Dict[str, Any], Dict[str, Any], List[str], Optional[Dict[str, Any]]]:
|
||||||
|
chunk_list = [dict(chunk) for chunk in chunks]
|
||||||
|
analysis_source = [dict(chunk) for chunk in (analysis_chunks or chunks)]
|
||||||
|
threshold_value = max(1, int(threshold))
|
||||||
|
analysis_enabled = run_analysis
|
||||||
|
settings_state = load_settings()
|
||||||
|
global_random_languages = [
|
||||||
|
code
|
||||||
|
for code in settings_state.get("speaker_random_languages", [])
|
||||||
|
if isinstance(code, str) and code
|
||||||
|
]
|
||||||
|
|
||||||
|
if not analysis_enabled:
|
||||||
|
for chunk in chunk_list:
|
||||||
|
chunk["speaker_id"] = "narrator"
|
||||||
|
chunk["speaker_label"] = "Narrator"
|
||||||
|
analysis_payload = {
|
||||||
|
"version": "1.0",
|
||||||
|
"narrator": "narrator",
|
||||||
|
"assignments": {str(chunk.get("id")): "narrator" for chunk in chunk_list},
|
||||||
|
"speakers": {
|
||||||
|
"narrator": {
|
||||||
|
"id": "narrator",
|
||||||
|
"label": "Narrator",
|
||||||
|
"count": len(chunk_list),
|
||||||
|
"confidence": "low",
|
||||||
|
"sample_quotes": [],
|
||||||
|
"suppressed": False,
|
||||||
|
}
|
||||||
|
},
|
||||||
|
"suppressed": [],
|
||||||
|
"stats": {
|
||||||
|
"total_chunks": len(chunk_list),
|
||||||
|
"explicit_chunks": 0,
|
||||||
|
"active_speakers": 0,
|
||||||
|
"unique_speakers": 1,
|
||||||
|
"suppressed": 0,
|
||||||
|
},
|
||||||
|
}
|
||||||
|
roster = build_narrator_roster(voice, voice_profile, existing_roster)
|
||||||
|
narrator_pron = roster["narrator"].get("pronunciation")
|
||||||
|
if narrator_pron:
|
||||||
|
analysis_payload["speakers"]["narrator"]["pronunciation"] = narrator_pron
|
||||||
|
return chunk_list, roster, analysis_payload, [], None
|
||||||
|
|
||||||
|
analysis_result = analyze_speakers(
|
||||||
|
chapters,
|
||||||
|
analysis_source,
|
||||||
|
threshold=threshold_value,
|
||||||
|
max_speakers=0,
|
||||||
|
)
|
||||||
|
analysis_payload = analysis_result.to_dict()
|
||||||
|
speakers_payload = analysis_payload.get("speakers", {})
|
||||||
|
ordered_ids = [
|
||||||
|
sid
|
||||||
|
for sid, meta in sorted(
|
||||||
|
(
|
||||||
|
(sid, meta)
|
||||||
|
for sid, meta in speakers_payload.items()
|
||||||
|
if sid != "narrator" and isinstance(meta, Mapping) and not meta.get("suppressed")
|
||||||
|
),
|
||||||
|
key=lambda item: item[1].get("count", 0),
|
||||||
|
reverse=True,
|
||||||
|
)
|
||||||
|
]
|
||||||
|
analysis_payload["ordered_speakers"] = ordered_ids
|
||||||
|
assignments = analysis_payload.get("assignments", {})
|
||||||
|
suppressed_ids = analysis_payload.get("suppressed", [])
|
||||||
|
suppressed_details: List[Dict[str, Any]] = []
|
||||||
|
speakers_payload = analysis_payload.get("speakers", {})
|
||||||
|
if isinstance(suppressed_ids, Iterable):
|
||||||
|
for suppressed_id in suppressed_ids:
|
||||||
|
speaker_meta = speakers_payload.get(suppressed_id) if isinstance(speakers_payload, dict) else None
|
||||||
|
if isinstance(speaker_meta, dict):
|
||||||
|
suppressed_details.append(
|
||||||
|
{
|
||||||
|
"id": suppressed_id,
|
||||||
|
"label": speaker_meta.get("label")
|
||||||
|
or str(suppressed_id).replace("_", " ").title(),
|
||||||
|
"pronunciation": speaker_meta.get("pronunciation"),
|
||||||
|
}
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
suppressed_details.append(
|
||||||
|
{
|
||||||
|
"id": suppressed_id,
|
||||||
|
"label": str(suppressed_id).replace("_", " ").title(),
|
||||||
|
"pronunciation": None,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
analysis_payload["suppressed_details"] = suppressed_details
|
||||||
|
roster = build_speaker_roster(
|
||||||
|
analysis_payload,
|
||||||
|
voice,
|
||||||
|
voice_profile,
|
||||||
|
existing=existing_roster,
|
||||||
|
order=analysis_payload.get("ordered_speakers"),
|
||||||
|
)
|
||||||
|
applied_languages: List[str] = []
|
||||||
|
updated_config: Optional[Dict[str, Any]] = None
|
||||||
|
if apply_config and speaker_config:
|
||||||
|
roster, applied_languages, updated_config = apply_speaker_config_to_roster(
|
||||||
|
roster,
|
||||||
|
speaker_config,
|
||||||
|
persist_changes=persist_config,
|
||||||
|
fallback_languages=global_random_languages,
|
||||||
|
)
|
||||||
|
speakers_payload = analysis_payload.get("speakers")
|
||||||
|
if isinstance(speakers_payload, dict):
|
||||||
|
for roster_id, roster_payload in roster.items():
|
||||||
|
speaker_meta = speakers_payload.get(roster_id)
|
||||||
|
if isinstance(speaker_meta, dict):
|
||||||
|
for key in ("voice", "voice_profile", "voice_formula", "resolved_voice"):
|
||||||
|
value = roster_payload.get(key)
|
||||||
|
if value:
|
||||||
|
speaker_meta[key] = value
|
||||||
|
effective_languages: List[str] = []
|
||||||
|
if applied_languages:
|
||||||
|
effective_languages = applied_languages
|
||||||
|
elif isinstance(analysis_payload.get("config_languages"), list):
|
||||||
|
effective_languages = [
|
||||||
|
code for code in analysis_payload.get("config_languages", []) if isinstance(code, str) and code
|
||||||
|
]
|
||||||
|
elif global_random_languages:
|
||||||
|
effective_languages = list(global_random_languages)
|
||||||
|
|
||||||
|
if effective_languages:
|
||||||
|
analysis_payload["config_languages"] = effective_languages
|
||||||
|
speakers_payload = analysis_payload.get("speakers")
|
||||||
|
if isinstance(speakers_payload, dict):
|
||||||
|
for roster_id, roster_payload in roster.items():
|
||||||
|
if roster_id in speakers_payload and isinstance(roster_payload, dict):
|
||||||
|
pronunciation_value = roster_payload.get("pronunciation")
|
||||||
|
if pronunciation_value:
|
||||||
|
speakers_payload[roster_id]["pronunciation"] = pronunciation_value
|
||||||
|
|
||||||
|
fallback_languages = effective_languages or []
|
||||||
|
if callable(inject_recommended):
|
||||||
|
inject_recommended(roster, fallback_languages=fallback_languages)
|
||||||
|
|
||||||
|
for chunk in chunk_list:
|
||||||
|
chunk_id = str(chunk.get("id"))
|
||||||
|
speaker_id = assignments.get(chunk_id, "narrator")
|
||||||
|
chunk["speaker_id"] = speaker_id
|
||||||
|
speaker_meta = roster.get(speaker_id)
|
||||||
|
chunk["speaker_label"] = speaker_meta.get("label") if isinstance(speaker_meta, dict) else speaker_id
|
||||||
|
|
||||||
|
return chunk_list, roster, analysis_payload, applied_languages, updated_config
|
||||||
@@ -0,0 +1,49 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
"""Unified split pattern logic extracted from 3 copies."""
|
||||||
|
|
||||||
|
from abogen.domain.enums import Language, SubtitleMode
|
||||||
|
|
||||||
|
# Canonical punctuation sets covering all supported scripts:
|
||||||
|
# ASCII (. ! ?), Arabic ؟, CJK (。!?), Devanagari ।
|
||||||
|
PUNCTUATION_SENTENCE = r".!?؟。!?।"
|
||||||
|
# Commas: ASCII , CJK fullwidth ,CJK ideographic 、
|
||||||
|
PUNCTUATION_SENTENCE_COMMA = r".!?,?。!?،,、।"
|
||||||
|
PUNCTUATION_COMMAS = ",,、"
|
||||||
|
|
||||||
|
|
||||||
|
def get_split_pattern(language: Language, subtitle_mode: str) -> str:
|
||||||
|
"""Get the appropriate split pattern based on language and subtitle mode.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
language: Language enum value, ISO code, or kokoro letter code.
|
||||||
|
subtitle_mode: Subtitle mode ("Sentence", "Sentence + Comma", "Line", etc.)
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Split pattern string
|
||||||
|
"""
|
||||||
|
try:
|
||||||
|
mode = SubtitleMode.from_str(subtitle_mode) if not isinstance(subtitle_mode, SubtitleMode) else subtitle_mode
|
||||||
|
except ValueError:
|
||||||
|
mode = SubtitleMode.DISABLED
|
||||||
|
|
||||||
|
# For English, always use newline splitting only
|
||||||
|
if language in (Language.EN_US, Language.EN_GB):
|
||||||
|
return "\n"
|
||||||
|
|
||||||
|
# Determine spacing pattern based on language
|
||||||
|
spacing = r"\s*" if language.is_cjk else r"\s+"
|
||||||
|
|
||||||
|
# For CJK languages, when subtitle mode is Disabled or Line, prefer
|
||||||
|
# punctuation-based splitting instead of plain newline splitting.
|
||||||
|
if mode in (SubtitleMode.DISABLED, SubtitleMode.LINE) and language.is_cjk:
|
||||||
|
return rf"(?<=[{PUNCTUATION_SENTENCE}]){spacing}|\n+"
|
||||||
|
|
||||||
|
if mode == SubtitleMode.LINE:
|
||||||
|
return "\n"
|
||||||
|
elif mode == SubtitleMode.SENTENCE:
|
||||||
|
return rf"(?<=[{PUNCTUATION_SENTENCE}]){spacing}|\n+"
|
||||||
|
elif mode == SubtitleMode.SENTENCE_COMMA:
|
||||||
|
return rf"(?<=[{PUNCTUATION_SENTENCE_COMMA}]){spacing}|\n+"
|
||||||
|
else:
|
||||||
|
return r"\n+"
|
||||||
@@ -0,0 +1,366 @@
|
|||||||
|
"""Subtitle generation utilities for audiobook generation.
|
||||||
|
|
||||||
|
This module provides functions for processing TTS tokens into subtitle entries
|
||||||
|
according to various subtitle modes (Line, Sentence, Sentence + Comma,
|
||||||
|
Sentence + Highlighting).
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import List, Optional, Tuple
|
||||||
|
|
||||||
|
from abogen.domain.enums import Language, SubtitleMode
|
||||||
|
from abogen.domain.split_pattern import PUNCTUATION_SENTENCE, PUNCTUATION_SENTENCE_COMMA
|
||||||
|
|
||||||
|
|
||||||
|
def process_subtitle_tokens(
|
||||||
|
tokens_with_timestamps: List[dict],
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
max_subtitle_words: int,
|
||||||
|
subtitle_mode: str,
|
||||||
|
language: Language,
|
||||||
|
use_spacy_segmentation: bool = False,
|
||||||
|
fallback_end_time: Optional[float] = None,
|
||||||
|
) -> None:
|
||||||
|
"""Process TTS tokens into subtitle entries according to the subtitle mode.
|
||||||
|
|
||||||
|
This function modifies subtitle_entries in-place by appending new entries.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
tokens_with_timestamps: List of token dictionaries with 'start', 'end', 'text',
|
||||||
|
and 'whitespace' keys.
|
||||||
|
subtitle_entries: List to append subtitle entries to (modified in-place).
|
||||||
|
Each entry is a tuple of (start_time, end_time, text).
|
||||||
|
max_subtitle_words: Maximum number of words per subtitle entry.
|
||||||
|
subtitle_mode: One of "Disabled", "Line", "Sentence", "Sentence + Comma",
|
||||||
|
"Sentence + Highlighting", or a string like "5" for word-count mode.
|
||||||
|
language: Language enum value for spaCy processing.
|
||||||
|
use_spacy_segmentation: Whether to use spaCy for sentence boundary detection.
|
||||||
|
fallback_end_time: Fallback end time for the last entry if none is available.
|
||||||
|
"""
|
||||||
|
if not tokens_with_timestamps:
|
||||||
|
return
|
||||||
|
|
||||||
|
processed_tokens = tokens_with_timestamps
|
||||||
|
|
||||||
|
# For English with spaCy enabled and sentence-based modes, use spaCy for sentence boundaries
|
||||||
|
# spaCy is disabled when subtitle mode is "Disabled" or "Line"
|
||||||
|
use_spacy_for_english = (
|
||||||
|
use_spacy_segmentation
|
||||||
|
and subtitle_mode not in [SubtitleMode.DISABLED, SubtitleMode.LINE]
|
||||||
|
and language in [Language.EN_US, Language.EN_GB]
|
||||||
|
and subtitle_mode in [SubtitleMode.SENTENCE, SubtitleMode.SENTENCE_COMMA]
|
||||||
|
)
|
||||||
|
|
||||||
|
if subtitle_mode == SubtitleMode.SENTENCE_HIGHLIGHT:
|
||||||
|
_process_karaoke_highlighting(
|
||||||
|
processed_tokens, subtitle_entries, max_subtitle_words, fallback_end_time
|
||||||
|
)
|
||||||
|
elif subtitle_mode in [SubtitleMode.SENTENCE, SubtitleMode.SENTENCE_COMMA, SubtitleMode.LINE]:
|
||||||
|
if use_spacy_for_english and subtitle_mode != SubtitleMode.LINE:
|
||||||
|
_process_spacy_sentences(
|
||||||
|
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||||
|
subtitle_mode, language, fallback_end_time
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
_process_regex_sentences(
|
||||||
|
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||||
|
subtitle_mode, fallback_end_time
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
# Word count-based grouping (e.g., "5" for 5-word groups)
|
||||||
|
_process_word_count(
|
||||||
|
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||||
|
subtitle_mode, fallback_end_time
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _process_karaoke_highlighting(
|
||||||
|
tokens: List[dict],
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
max_subtitle_words: int,
|
||||||
|
fallback_end_time: Optional[float],
|
||||||
|
) -> None:
|
||||||
|
"""Process tokens for Sentence + Highlighting mode (karaoke effect)."""
|
||||||
|
separator = rf"[{PUNCTUATION_SENTENCE}]"
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
|
||||||
|
for token in tokens:
|
||||||
|
current_sentence.append(token)
|
||||||
|
word_count += 1
|
||||||
|
|
||||||
|
# Split sentences based on separator or word count
|
||||||
|
if (
|
||||||
|
re.search(separator, token["text"]) and token.get("whitespace") == " "
|
||||||
|
) or word_count >= max_subtitle_words:
|
||||||
|
if current_sentence:
|
||||||
|
# Create karaoke subtitle entry for this sentence
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
|
||||||
|
# Generate karaoke text with timing
|
||||||
|
karaoke_text = ""
|
||||||
|
for t in current_sentence:
|
||||||
|
# Calculate duration in centiseconds
|
||||||
|
duration = (
|
||||||
|
t["end"] - t["start"]
|
||||||
|
if t.get("end") is not None and t.get("start") is not None
|
||||||
|
else 0.5
|
||||||
|
)
|
||||||
|
duration_cs = int(duration * 100)
|
||||||
|
# Add karaoke effect
|
||||||
|
karaoke_text += f"{{\\kf{duration_cs}}}{t['text']}{t.get('whitespace', '') or ''}"
|
||||||
|
|
||||||
|
subtitle_entries.append(
|
||||||
|
(start_time, end_time, karaoke_text.strip())
|
||||||
|
)
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
|
||||||
|
# Add any remaining tokens as a sentence
|
||||||
|
if current_sentence:
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
|
||||||
|
# Generate karaoke text for remaining tokens
|
||||||
|
karaoke_text = ""
|
||||||
|
for t in current_sentence:
|
||||||
|
duration = t["end"] - t["start"] if t.get("end") and t.get("start") else 0.5
|
||||||
|
duration_cs = int(duration * 100)
|
||||||
|
karaoke_text += f"{{\\kf{duration_cs}}}{t['text']}{t.get('whitespace', '') or ''}"
|
||||||
|
subtitle_entries.append((start_time, end_time, karaoke_text.strip()))
|
||||||
|
|
||||||
|
# Fallback for last entry
|
||||||
|
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||||
|
|
||||||
|
|
||||||
|
def _process_spacy_sentences(
|
||||||
|
tokens: List[dict],
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
max_subtitle_words: int,
|
||||||
|
subtitle_mode: str,
|
||||||
|
language: Language,
|
||||||
|
fallback_end_time: Optional[float],
|
||||||
|
) -> None:
|
||||||
|
"""Process tokens using spaCy for sentence boundary detection."""
|
||||||
|
try:
|
||||||
|
from abogen.spacy_utils import get_spacy_model
|
||||||
|
except ImportError:
|
||||||
|
# Fall back to regex if spaCy is not available
|
||||||
|
_process_regex_sentences(
|
||||||
|
tokens, subtitle_entries, max_subtitle_words,
|
||||||
|
subtitle_mode, fallback_end_time
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
|
nlp = get_spacy_model(language)
|
||||||
|
if not nlp:
|
||||||
|
_process_regex_sentences(
|
||||||
|
tokens, subtitle_entries, max_subtitle_words,
|
||||||
|
subtitle_mode, fallback_end_time
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
|
# Build full text and track character positions to token indices
|
||||||
|
full_text = ""
|
||||||
|
for token in tokens:
|
||||||
|
text_part = token["text"] + (token.get("whitespace") or "")
|
||||||
|
full_text += text_part
|
||||||
|
|
||||||
|
# Get sentence boundaries from spaCy
|
||||||
|
doc = nlp(full_text)
|
||||||
|
sentence_boundaries = [sent.end_char for sent in doc.sents]
|
||||||
|
|
||||||
|
# For "Sentence + Comma" mode, also split on commas
|
||||||
|
if subtitle_mode == SubtitleMode.SENTENCE_COMMA:
|
||||||
|
comma_positions = [
|
||||||
|
i + 1 for i, c in enumerate(full_text) if c == ","
|
||||||
|
]
|
||||||
|
sentence_boundaries = sorted(
|
||||||
|
set(sentence_boundaries + comma_positions)
|
||||||
|
)
|
||||||
|
|
||||||
|
# Group tokens by sentence boundaries
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
current_char_pos = 0
|
||||||
|
boundary_idx = 0
|
||||||
|
|
||||||
|
for token in tokens:
|
||||||
|
current_sentence.append(token)
|
||||||
|
word_count += 1
|
||||||
|
text_len = len(token["text"]) + len(token.get("whitespace") or "")
|
||||||
|
current_char_pos += text_len
|
||||||
|
|
||||||
|
# Check if we've hit a sentence boundary or max words
|
||||||
|
at_boundary = (
|
||||||
|
boundary_idx < len(sentence_boundaries)
|
||||||
|
and current_char_pos >= sentence_boundaries[boundary_idx]
|
||||||
|
)
|
||||||
|
if at_boundary or word_count >= max_subtitle_words:
|
||||||
|
if current_sentence:
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
sentence_text = "".join(
|
||||||
|
t["text"] + (t.get("whitespace") or "")
|
||||||
|
for t in current_sentence
|
||||||
|
)
|
||||||
|
subtitle_entries.append(
|
||||||
|
(start_time, end_time, sentence_text.strip())
|
||||||
|
)
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
if at_boundary:
|
||||||
|
boundary_idx += 1
|
||||||
|
|
||||||
|
# Add remaining tokens
|
||||||
|
if current_sentence:
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
sentence_text = "".join(
|
||||||
|
t["text"] + (t.get("whitespace") or "")
|
||||||
|
for t in current_sentence
|
||||||
|
)
|
||||||
|
subtitle_entries.append(
|
||||||
|
(start_time, end_time, sentence_text.strip())
|
||||||
|
)
|
||||||
|
|
||||||
|
# Fallback for last entry
|
||||||
|
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||||
|
|
||||||
|
|
||||||
|
def _process_regex_sentences(
|
||||||
|
tokens: List[dict],
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
max_subtitle_words: int,
|
||||||
|
subtitle_mode: str,
|
||||||
|
fallback_end_time: Optional[float],
|
||||||
|
) -> None:
|
||||||
|
"""Process tokens using regex for sentence boundary detection."""
|
||||||
|
# Define separator pattern based on mode
|
||||||
|
if subtitle_mode == SubtitleMode.LINE:
|
||||||
|
separator = r"\n"
|
||||||
|
elif subtitle_mode == SubtitleMode.SENTENCE:
|
||||||
|
separator = rf"[{PUNCTUATION_SENTENCE}]"
|
||||||
|
else: # Sentence + Comma
|
||||||
|
separator = rf"[{PUNCTUATION_SENTENCE_COMMA}]"
|
||||||
|
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
|
||||||
|
for token in tokens:
|
||||||
|
current_sentence.append(token)
|
||||||
|
word_count += 1
|
||||||
|
|
||||||
|
# Split sentences based on separator or word count
|
||||||
|
if (
|
||||||
|
re.search(separator, token["text"]) and token.get("whitespace") == " "
|
||||||
|
) or word_count >= max_subtitle_words:
|
||||||
|
if current_sentence:
|
||||||
|
# Create subtitle entry for this sentence
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
|
||||||
|
# Simplified text joining logic
|
||||||
|
sentence_text = ""
|
||||||
|
for t in current_sentence:
|
||||||
|
sentence_text += t["text"] + (t.get("whitespace") or "")
|
||||||
|
|
||||||
|
subtitle_entries.append(
|
||||||
|
(start_time, end_time, sentence_text.strip())
|
||||||
|
)
|
||||||
|
current_sentence = []
|
||||||
|
word_count = 0
|
||||||
|
|
||||||
|
# Add any remaining tokens as a sentence (split multi-sentence FakeToken)
|
||||||
|
if current_sentence:
|
||||||
|
start_time = current_sentence[0]["start"]
|
||||||
|
end_time = current_sentence[-1]["end"]
|
||||||
|
|
||||||
|
sentence_text = ""
|
||||||
|
for t in current_sentence:
|
||||||
|
sentence_text += t["text"] + (t.get("whitespace") or "")
|
||||||
|
sentence_text = sentence_text.strip()
|
||||||
|
|
||||||
|
if len(current_sentence) == 1:
|
||||||
|
parts = re.split(rf"(?<={separator})\s+", sentence_text)
|
||||||
|
if len(parts) > 1:
|
||||||
|
d = end_time - start_time
|
||||||
|
for i, p in enumerate(parts):
|
||||||
|
e = end_time if i == len(parts) - 1 else start_time + d * len(p) / len(sentence_text)
|
||||||
|
subtitle_entries.append((start_time, e, p.strip()))
|
||||||
|
start_time = e
|
||||||
|
current_sentence = []
|
||||||
|
|
||||||
|
if current_sentence:
|
||||||
|
subtitle_entries.append((start_time, end_time, sentence_text))
|
||||||
|
|
||||||
|
# Fallback for last entry
|
||||||
|
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||||
|
|
||||||
|
|
||||||
|
def _process_word_count(
|
||||||
|
tokens: List[dict],
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
max_subtitle_words: int,
|
||||||
|
subtitle_mode: str,
|
||||||
|
fallback_end_time: Optional[float],
|
||||||
|
) -> None:
|
||||||
|
"""Process tokens by counting spaces (word count mode)."""
|
||||||
|
try:
|
||||||
|
word_count = int(subtitle_mode.split()[0])
|
||||||
|
word_count = min(word_count, max_subtitle_words)
|
||||||
|
except (ValueError, IndexError):
|
||||||
|
word_count = 1
|
||||||
|
|
||||||
|
current_group = []
|
||||||
|
space_count = 0
|
||||||
|
|
||||||
|
for token in tokens:
|
||||||
|
current_group.append(token)
|
||||||
|
|
||||||
|
# Count spaces after tokens (in the whitespace field)
|
||||||
|
if token.get("whitespace", "") == " ":
|
||||||
|
space_count += 1
|
||||||
|
|
||||||
|
# Split after counting N spaces
|
||||||
|
if space_count >= word_count:
|
||||||
|
text = "".join(
|
||||||
|
t["text"] + (t.get("whitespace") or "")
|
||||||
|
for t in current_group
|
||||||
|
)
|
||||||
|
subtitle_entries.append(
|
||||||
|
(
|
||||||
|
current_group[0]["start"],
|
||||||
|
current_group[-1]["end"],
|
||||||
|
text.strip(),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
current_group = []
|
||||||
|
space_count = 0
|
||||||
|
|
||||||
|
# Add any remaining tokens
|
||||||
|
if current_group:
|
||||||
|
text = "".join(
|
||||||
|
t["text"] + (t.get("whitespace") or "") for t in current_group
|
||||||
|
)
|
||||||
|
subtitle_entries.append(
|
||||||
|
(current_group[0]["start"], current_group[-1]["end"], text.strip())
|
||||||
|
)
|
||||||
|
|
||||||
|
# Fallback for last entry
|
||||||
|
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||||
|
|
||||||
|
|
||||||
|
def _apply_fallback_end_time(
|
||||||
|
subtitle_entries: List[Tuple[float, float, str]],
|
||||||
|
fallback_end_time: Optional[float],
|
||||||
|
) -> None:
|
||||||
|
"""Apply fallback end time to the last entry if needed."""
|
||||||
|
if subtitle_entries and fallback_end_time is not None:
|
||||||
|
last_entry = subtitle_entries[-1]
|
||||||
|
start, end, text = last_entry
|
||||||
|
if end is None or end <= start or end <= 0:
|
||||||
|
subtitle_entries[-1] = (start, fallback_end_time, text)
|
||||||
@@ -0,0 +1,278 @@
|
|||||||
|
"""Subtitle-to-audio processing pipeline.
|
||||||
|
|
||||||
|
Converts subtitle files (SRT/ASS/VTT/timestamp text) into audio by
|
||||||
|
generating TTS for each entry and mixing into a buffer.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import logging
|
||||||
|
import time
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Callable, List, Optional, Tuple
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
|
||||||
|
from abogen.domain.audio_buffer import (
|
||||||
|
fit_audio_to_duration,
|
||||||
|
ffmpeg_time_stretch,
|
||||||
|
mix_audio,
|
||||||
|
normalize_audio,
|
||||||
|
SAMPLE_RATE,
|
||||||
|
)
|
||||||
|
from abogen.domain.audio_helpers import to_float32
|
||||||
|
from abogen.domain.progress import calc_etr_str
|
||||||
|
from abogen.subtitle_utils import (
|
||||||
|
parse_ass_file,
|
||||||
|
parse_srt_file,
|
||||||
|
parse_vtt_file,
|
||||||
|
parse_timestamp_text_file,
|
||||||
|
)
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SubtitleEntry:
|
||||||
|
"""A single subtitle entry with timing."""
|
||||||
|
start: float
|
||||||
|
end: Optional[float]
|
||||||
|
text: str
|
||||||
|
|
||||||
|
|
||||||
|
def parse_subtitle_file(
|
||||||
|
file_path: str,
|
||||||
|
is_timestamp_text: bool = False,
|
||||||
|
) -> List[Tuple[float, Optional[float], str]]:
|
||||||
|
"""Parse a subtitle file into (start, end, text) tuples.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
file_path: Path to subtitle file.
|
||||||
|
is_timestamp_text: Whether to treat as timestamp text file.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
List of (start_time, end_time, text) tuples.
|
||||||
|
"""
|
||||||
|
if is_timestamp_text:
|
||||||
|
return parse_timestamp_text_file(file_path)
|
||||||
|
|
||||||
|
import os
|
||||||
|
ext = os.path.splitext(file_path)[1].lower()
|
||||||
|
if ext == ".srt":
|
||||||
|
return parse_srt_file(file_path)
|
||||||
|
elif ext == ".vtt":
|
||||||
|
return parse_vtt_file(file_path)
|
||||||
|
else:
|
||||||
|
return parse_ass_file(file_path)
|
||||||
|
|
||||||
|
|
||||||
|
def format_time_range(
|
||||||
|
start: float,
|
||||||
|
end: Optional[float],
|
||||||
|
is_auto_end: bool = False,
|
||||||
|
) -> str:
|
||||||
|
"""Format a time range for display in logs.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
start: Start time in seconds.
|
||||||
|
end: End time in seconds, or None.
|
||||||
|
is_auto_end: Whether end time is auto-detected.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Formatted string like "00:01:23,456 - 00:01:25,789" or "00:01:23 - AUTO".
|
||||||
|
"""
|
||||||
|
def _fmt(seconds: float) -> str:
|
||||||
|
h = int(seconds // 3600)
|
||||||
|
m = int(seconds % 3600 // 60)
|
||||||
|
s = int(seconds % 60)
|
||||||
|
ms = int((seconds - int(seconds)) * 1000)
|
||||||
|
result = f"{h:02d}:{m:02d}:{s:02d}"
|
||||||
|
if ms > 0:
|
||||||
|
result += f",{ms:03d}"
|
||||||
|
return result
|
||||||
|
|
||||||
|
if is_auto_end or end is None:
|
||||||
|
return f"{_fmt(start)} - AUTO"
|
||||||
|
return f"{_fmt(start)} - {_fmt(end)}"
|
||||||
|
|
||||||
|
|
||||||
|
def speed_up_audio(
|
||||||
|
audio: np.ndarray,
|
||||||
|
speed_factor: float,
|
||||||
|
method: str = "tts",
|
||||||
|
*,
|
||||||
|
backend: Any = None,
|
||||||
|
text: str = "",
|
||||||
|
voice: Any = None,
|
||||||
|
base_speed: float = 1.0,
|
||||||
|
sample_rate: int = SAMPLE_RATE,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Speed up audio to fit a time window.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
audio: Input audio buffer.
|
||||||
|
speed_factor: Required speed multiplier.
|
||||||
|
method: "ffmpeg" for time-stretch, "tts" for regeneration.
|
||||||
|
backend: TTS backend (required if method="tts").
|
||||||
|
text: Text to regenerate (required if method="tts").
|
||||||
|
voice: Voice to use for regeneration.
|
||||||
|
base_speed: Base speed for TTS.
|
||||||
|
sample_rate: Sample rate.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Speed-adjusted audio buffer.
|
||||||
|
"""
|
||||||
|
if speed_factor <= 1.0:
|
||||||
|
return audio
|
||||||
|
|
||||||
|
if method == "ffmpeg":
|
||||||
|
logger.info("FFmpeg time-stretch: %.2fx", speed_factor)
|
||||||
|
return ffmpeg_time_stretch(audio, speed_factor, sample_rate)
|
||||||
|
|
||||||
|
# TTS regeneration
|
||||||
|
if backend is None:
|
||||||
|
return audio
|
||||||
|
new_speed = base_speed * speed_factor
|
||||||
|
logger.info("Regenerating at %.2fx speed", new_speed)
|
||||||
|
results = [
|
||||||
|
r for r in backend(text, voice=voice, speed=new_speed, split_pattern=None)
|
||||||
|
]
|
||||||
|
chunks = [r.audio for r in results]
|
||||||
|
if not chunks:
|
||||||
|
return audio
|
||||||
|
return np.concatenate([to_float32(c) for c in chunks])
|
||||||
|
|
||||||
|
|
||||||
|
def process_subtitle_entries(
|
||||||
|
subtitles: List[Tuple[float, Optional[float], str]],
|
||||||
|
*,
|
||||||
|
backend: Any,
|
||||||
|
voice: Any,
|
||||||
|
speed: float = 1.0,
|
||||||
|
cancel_check: Callable[[], bool] = lambda: False,
|
||||||
|
log_callback: Optional[Callable[[str], None]] = None,
|
||||||
|
progress_callback: Optional[Callable[[int, str], None]] = None,
|
||||||
|
replace_newlines: bool = True,
|
||||||
|
use_gaps: bool = False,
|
||||||
|
is_timestamp_text: bool = False,
|
||||||
|
subtitle_speed_method: str = "tts",
|
||||||
|
sample_rate: int = SAMPLE_RATE,
|
||||||
|
) -> np.ndarray:
|
||||||
|
"""Process subtitle entries: generate TTS for each and mix into buffer.
|
||||||
|
|
||||||
|
This is the core domain logic for subtitle-to-audio conversion.
|
||||||
|
UI-specific concerns (signals, widgets) are handled via callbacks.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
subtitles: List of (start, end, text) tuples.
|
||||||
|
backend: TTS pipeline callable.
|
||||||
|
voice: Resolved voice for TTS.
|
||||||
|
speed: TTS speed.
|
||||||
|
cancel_check: Returns True if processing should stop.
|
||||||
|
log_callback: Called with log messages.
|
||||||
|
progress_callback: Called with (percent, etr_string).
|
||||||
|
replace_newlines: Replace \\n with spaces in text.
|
||||||
|
use_gaps: Whether to use silent gaps between subtitles.
|
||||||
|
is_timestamp_text: Whether input is timestamp text.
|
||||||
|
subtitle_speed_method: "ffmpeg" or "tts" for speed adjustment.
|
||||||
|
sample_rate: Audio sample rate.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Mixed audio buffer (float32).
|
||||||
|
"""
|
||||||
|
if not subtitles:
|
||||||
|
return np.array([], dtype="float32")
|
||||||
|
|
||||||
|
max_end = max((end for _, end, _ in subtitles if end is not None), default=0)
|
||||||
|
buffer_samples = int(max_end * sample_rate) + sample_rate
|
||||||
|
audio_buffer = np.zeros(buffer_samples, dtype="float32")
|
||||||
|
etr_start = time.time()
|
||||||
|
total = len(subtitles)
|
||||||
|
|
||||||
|
for idx, (start_time, end_time, text) in enumerate(subtitles, 1):
|
||||||
|
if cancel_check():
|
||||||
|
break
|
||||||
|
|
||||||
|
processed_text = text.replace("\n", " ") if replace_newlines else text
|
||||||
|
next_start = (
|
||||||
|
subtitles[idx][0]
|
||||||
|
if (use_gaps and idx < total)
|
||||||
|
else float("inf")
|
||||||
|
)
|
||||||
|
subtitle_duration = None if end_time is None else end_time - start_time
|
||||||
|
|
||||||
|
is_auto_end = is_timestamp_text or (use_gaps and idx == total) or end_time is None
|
||||||
|
if log_callback:
|
||||||
|
log_callback(
|
||||||
|
f"\n[{idx}/{total}] {format_time_range(start_time, end_time, is_auto_end)}: {processed_text}"
|
||||||
|
)
|
||||||
|
|
||||||
|
# Generate TTS
|
||||||
|
results = [
|
||||||
|
r for r in backend(
|
||||||
|
processed_text, voice=voice, speed=speed, split_pattern=None
|
||||||
|
)
|
||||||
|
if not cancel_check()
|
||||||
|
]
|
||||||
|
if cancel_check():
|
||||||
|
break
|
||||||
|
|
||||||
|
audio_chunks = [r.audio for r in results]
|
||||||
|
full_audio = (
|
||||||
|
np.concatenate([to_float32(a) for a in audio_chunks])
|
||||||
|
if audio_chunks
|
||||||
|
else np.zeros(int((subtitle_duration or 0) * sample_rate), dtype="float32")
|
||||||
|
)
|
||||||
|
audio_duration = len(full_audio) / sample_rate
|
||||||
|
|
||||||
|
# Timing adjustment
|
||||||
|
if is_timestamp_text:
|
||||||
|
end_time = start_time + audio_duration
|
||||||
|
subtitle_duration = audio_duration
|
||||||
|
elif use_gaps:
|
||||||
|
end_time = min(start_time + audio_duration, next_start)
|
||||||
|
subtitle_duration = end_time - start_time
|
||||||
|
elif subtitle_duration is None:
|
||||||
|
subtitle_duration = audio_duration
|
||||||
|
end_time = start_time + audio_duration
|
||||||
|
|
||||||
|
# Speed up if needed
|
||||||
|
speedup_threshold = next_start - start_time if use_gaps else subtitle_duration
|
||||||
|
if audio_duration > speedup_threshold and speedup_threshold > 0:
|
||||||
|
speed_factor = audio_duration / speedup_threshold
|
||||||
|
full_audio = speed_up_audio(
|
||||||
|
full_audio, speed_factor,
|
||||||
|
method=subtitle_speed_method,
|
||||||
|
backend=backend, text=processed_text,
|
||||||
|
voice=voice, base_speed=speed,
|
||||||
|
sample_rate=sample_rate,
|
||||||
|
)
|
||||||
|
audio_duration = len(full_audio) / sample_rate
|
||||||
|
|
||||||
|
# Adjust duration after speed change
|
||||||
|
if use_gaps:
|
||||||
|
end_time = min(start_time + audio_duration, next_start)
|
||||||
|
subtitle_duration = end_time - start_time
|
||||||
|
elif subtitle_duration is None:
|
||||||
|
subtitle_duration = audio_duration
|
||||||
|
end_time = start_time + audio_duration
|
||||||
|
|
||||||
|
# Pad or trim to subtitle duration
|
||||||
|
full_audio = fit_audio_to_duration(full_audio, subtitle_duration, sample_rate)
|
||||||
|
|
||||||
|
# Mix into buffer
|
||||||
|
start_sample = int(start_time * sample_rate)
|
||||||
|
audio_buffer = mix_audio(audio_buffer, full_audio, start_sample)
|
||||||
|
|
||||||
|
# Progress
|
||||||
|
if progress_callback:
|
||||||
|
percent = min(int(idx / total * 100), 99)
|
||||||
|
etr = calc_etr_str(time.time() - etr_start, idx, total)
|
||||||
|
progress_callback(percent, etr)
|
||||||
|
|
||||||
|
# Normalize if needed
|
||||||
|
if np.abs(audio_buffer).max() > 1.0:
|
||||||
|
logger.info("Normalizing audio (peak: %.2f)", np.abs(audio_buffer).max())
|
||||||
|
audio_buffer = normalize_audio(audio_buffer)
|
||||||
|
|
||||||
|
return audio_buffer
|
||||||
@@ -0,0 +1,59 @@
|
|||||||
|
"""Chapter parsing from raw text.
|
||||||
|
|
||||||
|
Provides a unified function for splitting text by chapter markers,
|
||||||
|
used by both WebUI and PyQt conversion runners.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import List, Tuple
|
||||||
|
|
||||||
|
from abogen.subtitle_utils import clean_text
|
||||||
|
|
||||||
|
|
||||||
|
_CHAPTER_MARKER_RE = re.compile(r"<<CHAPTER_MARKER:(.*?)>>", re.IGNORECASE)
|
||||||
|
|
||||||
|
|
||||||
|
def parse_chapters_from_text(
|
||||||
|
text: str,
|
||||||
|
default_title: str = "text",
|
||||||
|
clean: bool = True,
|
||||||
|
) -> List[Tuple[str, str]]:
|
||||||
|
"""Split raw text into chapters using chapter marker patterns.
|
||||||
|
|
||||||
|
Preserves content before the first marker as "Introduction" if present.
|
||||||
|
Optionally applies clean_text() to each chapter segment.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Raw text possibly containing <<CHAPTER_MARKER:Title>> markers.
|
||||||
|
default_title: Fallback title when no markers are found.
|
||||||
|
clean: Whether to apply clean_text() to each segment.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
List of (title, text) tuples.
|
||||||
|
"""
|
||||||
|
matches = list(_CHAPTER_MARKER_RE.finditer(text))
|
||||||
|
if not matches:
|
||||||
|
cleaned = clean_text(text) if clean else text
|
||||||
|
return [(default_title, cleaned)]
|
||||||
|
|
||||||
|
chapters: List[Tuple[str, str]] = []
|
||||||
|
|
||||||
|
# Preserve content before first marker as "Introduction"
|
||||||
|
first_start = matches[0].start()
|
||||||
|
if first_start > 0:
|
||||||
|
intro_text = text[:first_start].strip()
|
||||||
|
if intro_text:
|
||||||
|
chapters.append(("Introduction", clean_text(intro_text) if clean else intro_text))
|
||||||
|
|
||||||
|
for idx, match in enumerate(matches):
|
||||||
|
start = match.end()
|
||||||
|
end = matches[idx + 1].start() if idx + 1 < len(matches) else len(text)
|
||||||
|
chapter_name = match.group(1).strip() or default_title
|
||||||
|
chapter_text = text[start:end].strip()
|
||||||
|
if clean:
|
||||||
|
chapter_text = clean_text(chapter_text)
|
||||||
|
chapters.append((chapter_name, chapter_text))
|
||||||
|
|
||||||
|
return chapters
|
||||||
@@ -0,0 +1,22 @@
|
|||||||
|
"""Text utility functions for the domain layer."""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
|
||||||
|
# Pre-compiled patterns for calculate_text_length
|
||||||
|
_METADATA_TAG_PATTERN = re.compile(r"<<METADATA_[^:]+:[^>]*>>")
|
||||||
|
_CHAPTER_MARKER_PATTERN = re.compile(r"<<CHAPTER_MARKER:[^>]*>>")
|
||||||
|
_VOICE_MARKER_PATTERN = re.compile(r"<<VOICE:[^>]*>>")
|
||||||
|
|
||||||
|
|
||||||
|
def calculate_text_length(text: str) -> int:
|
||||||
|
"""Calculate character count, ignoring internal markers and newlines.
|
||||||
|
|
||||||
|
Strips chapter markers, voice markers, and metadata tags before counting.
|
||||||
|
"""
|
||||||
|
text = _CHAPTER_MARKER_PATTERN.sub("", text)
|
||||||
|
text = _VOICE_MARKER_PATTERN.sub("", text)
|
||||||
|
text = _METADATA_TAG_PATTERN.sub("", text)
|
||||||
|
text = text.replace("\n", "").strip()
|
||||||
|
return len(text)
|
||||||
@@ -0,0 +1,97 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, List, Mapping, Optional
|
||||||
|
|
||||||
|
from .metadata_helpers import (
|
||||||
|
ensure_sentence,
|
||||||
|
extract_series_metadata,
|
||||||
|
format_author_sentence,
|
||||||
|
format_series_sentence,
|
||||||
|
normalize_metadata_map,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def build_title_intro_text(
|
||||||
|
metadata: Optional[Mapping[str, Any]],
|
||||||
|
fallback_basename: str,
|
||||||
|
) -> str:
|
||||||
|
"""Build the title introduction text from metadata."""
|
||||||
|
normalized = normalize_metadata_map(metadata)
|
||||||
|
fallback_title = Path(fallback_basename).stem if fallback_basename else ""
|
||||||
|
title = (
|
||||||
|
normalized.get("title")
|
||||||
|
or normalized.get("book_title")
|
||||||
|
or normalized.get("album")
|
||||||
|
or fallback_title
|
||||||
|
)
|
||||||
|
if not title:
|
||||||
|
title = fallback_title
|
||||||
|
subtitle = normalized.get("subtitle") or normalized.get("sub_title")
|
||||||
|
if subtitle and title and subtitle.casefold() == title.casefold():
|
||||||
|
subtitle = ""
|
||||||
|
|
||||||
|
author_value = ""
|
||||||
|
for candidate in ("artist", "album_artist", "author", "authors", "writer", "composer"):
|
||||||
|
value = normalized.get(candidate)
|
||||||
|
if value:
|
||||||
|
author_value = value
|
||||||
|
break
|
||||||
|
|
||||||
|
series_name, series_number = extract_series_metadata(normalized)
|
||||||
|
series_sentence = format_series_sentence(series_name, series_number)
|
||||||
|
|
||||||
|
sentences: List[str] = []
|
||||||
|
if series_sentence:
|
||||||
|
sentences.append(ensure_sentence(series_sentence))
|
||||||
|
if title:
|
||||||
|
sentences.append(ensure_sentence(title))
|
||||||
|
if subtitle:
|
||||||
|
sentences.append(ensure_sentence(subtitle))
|
||||||
|
author_sentence = format_author_sentence(author_value)
|
||||||
|
if author_sentence:
|
||||||
|
sentences.append(ensure_sentence(author_sentence))
|
||||||
|
return " ".join(sentences).strip()
|
||||||
|
|
||||||
|
|
||||||
|
def build_outro_text(
|
||||||
|
metadata: Optional[Mapping[str, Any]],
|
||||||
|
fallback_basename: str,
|
||||||
|
) -> str:
|
||||||
|
"""Build the outro/closing text from metadata."""
|
||||||
|
normalized = normalize_metadata_map(metadata)
|
||||||
|
fallback_title = Path(fallback_basename).stem if fallback_basename else ""
|
||||||
|
title = (
|
||||||
|
normalized.get("title")
|
||||||
|
or normalized.get("book_title")
|
||||||
|
or normalized.get("album")
|
||||||
|
or fallback_title
|
||||||
|
)
|
||||||
|
author_value = ""
|
||||||
|
for candidate in ("authors", "author", "album_artist", "artist", "writer", "composer"):
|
||||||
|
value = normalized.get(candidate)
|
||||||
|
if value:
|
||||||
|
author_value = value
|
||||||
|
break
|
||||||
|
author_sentence = format_author_sentence(author_value)
|
||||||
|
authors_fragment = (
|
||||||
|
author_sentence[3:].strip() if author_sentence.lower().startswith("by ") else author_sentence.strip()
|
||||||
|
)
|
||||||
|
|
||||||
|
if title and authors_fragment:
|
||||||
|
closing_line = f"The end of {title} from {authors_fragment}"
|
||||||
|
elif title:
|
||||||
|
closing_line = f"The end of {title}"
|
||||||
|
elif authors_fragment:
|
||||||
|
closing_line = f"The end from {authors_fragment}"
|
||||||
|
else:
|
||||||
|
closing_line = "The end"
|
||||||
|
|
||||||
|
series_name, series_number = extract_series_metadata(normalized)
|
||||||
|
series_sentence = format_series_sentence(series_name, series_number)
|
||||||
|
|
||||||
|
sentences: List[str] = [ensure_sentence(closing_line)]
|
||||||
|
if series_sentence:
|
||||||
|
sentences.append(ensure_sentence(series_sentence))
|
||||||
|
|
||||||
|
return " ".join(sentence for sentence in sentences if sentence).strip()
|
||||||
@@ -0,0 +1,13 @@
|
|||||||
|
"""Shared token stubs for TTS processing."""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
|
||||||
|
class FakeToken:
|
||||||
|
"""Minimal token stub for languages without per-word token support."""
|
||||||
|
|
||||||
|
def __init__(self, text: str, start: float, end: float):
|
||||||
|
self.text = text
|
||||||
|
self.start_ts = start
|
||||||
|
self.end_ts = end
|
||||||
|
self.whitespace = ""
|
||||||
@@ -0,0 +1,112 @@
|
|||||||
|
"""Voice catalog — shared voice metadata for all UIs.
|
||||||
|
|
||||||
|
Builds a unified catalog of available voices with metadata (language,
|
||||||
|
gender, display name). Used by both WebUI and PyQt for voice selection UIs.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.constants import LANGUAGE_DESCRIPTIONS
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
|
|
||||||
|
|
||||||
|
def build_voice_catalog() -> List[Dict[str, str]]:
|
||||||
|
"""Build voice catalog with metadata for all available voices.
|
||||||
|
|
||||||
|
Returns a list of dicts, each containing:
|
||||||
|
- id: voice ID (e.g. "af_heart")
|
||||||
|
- language: language code (e.g. "a", "e")
|
||||||
|
- language_label: human-readable language name
|
||||||
|
- gender: "Female", "Male", or "Unknown"
|
||||||
|
- gender_code: "f", "m", or ""
|
||||||
|
- display_name: human-readable voice name
|
||||||
|
"""
|
||||||
|
from plugins.kokoro.engine import language_for_voice_id
|
||||||
|
|
||||||
|
catalog: List[Dict[str, str]] = []
|
||||||
|
gender_map = {"f": "Female", "m": "Male"}
|
||||||
|
for voice_id in get_voices("kokoro"):
|
||||||
|
prefix, _, rest = voice_id.partition("_")
|
||||||
|
gender_code = prefix[1] if len(prefix) > 1 else ""
|
||||||
|
lang = language_for_voice_id(voice_id)
|
||||||
|
catalog.append(
|
||||||
|
{
|
||||||
|
"id": voice_id,
|
||||||
|
"language": lang.value,
|
||||||
|
"language_label": LANGUAGE_DESCRIPTIONS.get(lang, lang.value.upper()),
|
||||||
|
"gender": gender_map.get(gender_code, "Unknown"),
|
||||||
|
"gender_code": gender_code,
|
||||||
|
"display_name": rest.replace("_", " ").title() if rest else voice_id,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
return catalog
|
||||||
|
|
||||||
|
|
||||||
|
def filter_voice_catalog(
|
||||||
|
catalog: Iterable[Mapping[str, Any]],
|
||||||
|
*,
|
||||||
|
gender: str,
|
||||||
|
allowed_languages: Optional[Iterable[str]] = None,
|
||||||
|
) -> List[str]:
|
||||||
|
"""Filter voice catalog by gender and language.
|
||||||
|
|
||||||
|
Returns voice IDs that match the criteria. Falls back to broader
|
||||||
|
matches if no exact matches are found.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
catalog: Voice catalog entries (from build_voice_catalog).
|
||||||
|
gender: Gender filter ("male", "female", or "unknown").
|
||||||
|
allowed_languages: Optional list of allowed language codes.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
List of matching voice IDs.
|
||||||
|
"""
|
||||||
|
allowed_set = {code.lower() for code in (allowed_languages or []) if isinstance(code, str) and code}
|
||||||
|
gender_normalized = (gender or "unknown").lower()
|
||||||
|
gender_code = ""
|
||||||
|
if gender_normalized == "male":
|
||||||
|
gender_code = "m"
|
||||||
|
elif gender_normalized == "female":
|
||||||
|
gender_code = "f"
|
||||||
|
|
||||||
|
matches: List[str] = []
|
||||||
|
seen: set[str] = set()
|
||||||
|
|
||||||
|
def _consider(entry: Mapping[str, Any]) -> None:
|
||||||
|
voice_id = entry.get("id")
|
||||||
|
if not isinstance(voice_id, str) or not voice_id:
|
||||||
|
return
|
||||||
|
if voice_id in seen:
|
||||||
|
return
|
||||||
|
seen.add(voice_id)
|
||||||
|
matches.append(voice_id)
|
||||||
|
|
||||||
|
primary: List[Mapping[str, Any]] = []
|
||||||
|
fallback: List[Mapping[str, Any]] = []
|
||||||
|
for entry in catalog:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
voice_lang = str(entry.get("language", "")).lower()
|
||||||
|
voice_gender_code = str(entry.get("gender_code", "")).lower()
|
||||||
|
if allowed_set and voice_lang not in allowed_set:
|
||||||
|
continue
|
||||||
|
if gender_code and voice_gender_code != gender_code:
|
||||||
|
fallback.append(entry)
|
||||||
|
continue
|
||||||
|
primary.append(entry)
|
||||||
|
|
||||||
|
for entry in primary:
|
||||||
|
_consider(entry)
|
||||||
|
|
||||||
|
if not matches:
|
||||||
|
for entry in fallback:
|
||||||
|
_consider(entry)
|
||||||
|
|
||||||
|
if not matches:
|
||||||
|
for entry in catalog:
|
||||||
|
if isinstance(entry, Mapping):
|
||||||
|
_consider(entry)
|
||||||
|
|
||||||
|
return matches
|
||||||
@@ -0,0 +1,128 @@
|
|||||||
|
"""Voice loading and caching utilities.
|
||||||
|
|
||||||
|
This module provides unified voice loading with caching support for both
|
||||||
|
PyQt and WebUI interfaces.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Optional
|
||||||
|
|
||||||
|
from abogen.voice_formulas import get_new_voice
|
||||||
|
|
||||||
|
|
||||||
|
class VoiceCache:
|
||||||
|
"""Thread-safe voice cache for loaded voice tensors."""
|
||||||
|
|
||||||
|
def __init__(self):
|
||||||
|
self._cache: Dict[str, Any] = {}
|
||||||
|
|
||||||
|
def get(self, voice_spec: str) -> Optional[Any]:
|
||||||
|
"""Get cached voice by spec."""
|
||||||
|
return self._cache.get(voice_spec)
|
||||||
|
|
||||||
|
def set(self, voice_spec: str, voice: Any) -> None:
|
||||||
|
"""Cache a loaded voice."""
|
||||||
|
self._cache[voice_spec] = voice
|
||||||
|
|
||||||
|
def contains(self, voice_spec: str) -> bool:
|
||||||
|
"""Check if voice is in cache."""
|
||||||
|
return voice_spec in self._cache
|
||||||
|
|
||||||
|
def clear(self) -> None:
|
||||||
|
"""Clear all cached voices."""
|
||||||
|
self._cache.clear()
|
||||||
|
|
||||||
|
def keys(self):
|
||||||
|
"""Return cached voice specs."""
|
||||||
|
return self._cache.keys()
|
||||||
|
|
||||||
|
def __contains__(self, voice_spec: str) -> bool:
|
||||||
|
return self.contains(voice_spec)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_voice(
|
||||||
|
voice_spec: str,
|
||||||
|
pipeline: Any,
|
||||||
|
use_gpu: bool,
|
||||||
|
cache: Optional[VoiceCache] = None,
|
||||||
|
) -> Any:
|
||||||
|
"""Resolve voice spec to actual voice tensor or name.
|
||||||
|
|
||||||
|
If voice_spec contains '*' (formula), loads the voice using get_new_voice.
|
||||||
|
Otherwise, returns the voice_spec as-is (it's a voice name).
|
||||||
|
|
||||||
|
Uses optional cache to avoid reloading same voice multiple times.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
voice_spec: Voice specification (name or formula string with '*').
|
||||||
|
pipeline: TTS pipeline instance for loading formula voices.
|
||||||
|
use_gpu: Whether to use GPU for voice loading.
|
||||||
|
cache: Optional VoiceCache instance for caching loaded voices.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Loaded voice tensor (for formulas) or voice name string.
|
||||||
|
"""
|
||||||
|
# Check cache first
|
||||||
|
if cache and cache.contains(voice_spec):
|
||||||
|
return cache.get(voice_spec)
|
||||||
|
|
||||||
|
# Load voice
|
||||||
|
if "*" in voice_spec:
|
||||||
|
if pipeline is None or not hasattr(pipeline, "load_single_voice"):
|
||||||
|
return voice_spec
|
||||||
|
loaded_voice = get_new_voice(pipeline, voice_spec, use_gpu)
|
||||||
|
else:
|
||||||
|
loaded_voice = voice_spec
|
||||||
|
|
||||||
|
# Cache it
|
||||||
|
if cache:
|
||||||
|
cache.set(voice_spec, loaded_voice)
|
||||||
|
|
||||||
|
return loaded_voice
|
||||||
|
|
||||||
|
|
||||||
|
def load_voice_cached(
|
||||||
|
voice_name: str,
|
||||||
|
pipeline: Any,
|
||||||
|
use_gpu: bool,
|
||||||
|
cache: Any = None,
|
||||||
|
) -> Any:
|
||||||
|
"""Load voice with caching (compatibility wrapper for PyQt).
|
||||||
|
|
||||||
|
This function maintains backward compatibility with the PyQt interface
|
||||||
|
while using the unified voice loading logic.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
voice_name: Voice name or formula string.
|
||||||
|
pipeline: TTS pipeline instance.
|
||||||
|
use_gpu: Whether to use GPU.
|
||||||
|
cache: Optional VoiceCache or dict to use as cache.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Loaded voice tensor or voice name string.
|
||||||
|
"""
|
||||||
|
# Check cache (supports both VoiceCache and plain dict)
|
||||||
|
if cache is not None:
|
||||||
|
if isinstance(cache, VoiceCache):
|
||||||
|
if cache.contains(voice_name):
|
||||||
|
return cache.get(voice_name)
|
||||||
|
elif voice_name in cache:
|
||||||
|
return cache[voice_name]
|
||||||
|
|
||||||
|
# Load voice
|
||||||
|
if "*" in voice_name:
|
||||||
|
if pipeline is None or not hasattr(pipeline, "load_single_voice"):
|
||||||
|
return voice_name
|
||||||
|
loaded_voice = get_new_voice(pipeline, voice_name, use_gpu)
|
||||||
|
else:
|
||||||
|
loaded_voice = voice_name
|
||||||
|
|
||||||
|
# Cache it
|
||||||
|
if cache is not None:
|
||||||
|
if isinstance(cache, VoiceCache):
|
||||||
|
cache.set(voice_name, loaded_voice)
|
||||||
|
else:
|
||||||
|
cache[voice_name] = loaded_voice
|
||||||
|
|
||||||
|
return loaded_voice
|
||||||
@@ -0,0 +1,117 @@
|
|||||||
|
"""Voice marker parsing and text splitting.
|
||||||
|
|
||||||
|
Handles <<VOICE:name>> markers in text, splitting text into voice-specific
|
||||||
|
segments. This is domain logic about text segmentation by voice, not subtitle
|
||||||
|
processing.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import re
|
||||||
|
from typing import List, Tuple
|
||||||
|
|
||||||
|
_VOICE_MARKER_PATTERN = re.compile(r"<<VOICE:[^>]*>>")
|
||||||
|
_VOICE_MARKER_SEARCH_PATTERN = re.compile(r"<<VOICE:(.*?)>>")
|
||||||
|
|
||||||
|
|
||||||
|
def validate_voice_name(voice_name: str) -> Tuple[bool, str | None]:
|
||||||
|
"""Validate voice name against available voices (case-insensitive).
|
||||||
|
|
||||||
|
Handles both single voices and formulas like 'af_heart*0.5 + am_echo*0.5'.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (is_valid, invalid_voice_name):
|
||||||
|
- is_valid: True if all voices in the name/formula are valid
|
||||||
|
- invalid_voice_name: The first invalid voice found, or None if all valid
|
||||||
|
"""
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
|
|
||||||
|
voice_lookup_lower = {v.lower() for v in get_voices("kokoro")}
|
||||||
|
voice_name = voice_name.strip()
|
||||||
|
|
||||||
|
if "*" in voice_name:
|
||||||
|
voices = voice_name.split("+")
|
||||||
|
for term in voices:
|
||||||
|
if "*" in term:
|
||||||
|
base_voice = term.split("*")[0].strip()
|
||||||
|
if base_voice.lower() not in voice_lookup_lower:
|
||||||
|
return False, base_voice
|
||||||
|
return True, None
|
||||||
|
else:
|
||||||
|
if voice_name.lower() not in voice_lookup_lower:
|
||||||
|
return False, voice_name
|
||||||
|
return True, None
|
||||||
|
|
||||||
|
|
||||||
|
def split_text_by_voice_markers(
|
||||||
|
text: str, default_voice: str
|
||||||
|
) -> Tuple[List[Tuple[str, str]], str, int, int]:
|
||||||
|
"""Split text by voice markers, returning list of (voice, text) tuples.
|
||||||
|
|
||||||
|
Returns the last voice used so it can persist across chapters.
|
||||||
|
Voice names are normalized to lowercase to match canonical voice names.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
text: Text potentially containing <<VOICE:name>> markers
|
||||||
|
default_voice: Voice to use if no markers found or before first marker
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (segments_list, last_voice_used, valid_count, invalid_count):
|
||||||
|
- segments_list: List of (voice_name, segment_text) tuples
|
||||||
|
- last_voice_used: The voice that should continue into next chapter
|
||||||
|
- valid_count: Number of valid voice markers processed
|
||||||
|
- invalid_count: Number of invalid voice markers skipped
|
||||||
|
"""
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
|
|
||||||
|
voice_splits = list(_VOICE_MARKER_SEARCH_PATTERN.finditer(text))
|
||||||
|
|
||||||
|
if not voice_splits:
|
||||||
|
return [(default_voice, text)], default_voice, 0, 0
|
||||||
|
|
||||||
|
segments: List[Tuple[str, str]] = []
|
||||||
|
current_voice = default_voice
|
||||||
|
valid_markers = 0
|
||||||
|
invalid_markers = 0
|
||||||
|
|
||||||
|
first_start = voice_splits[0].start()
|
||||||
|
if first_start > 0:
|
||||||
|
intro_text = text[:first_start].strip()
|
||||||
|
if intro_text:
|
||||||
|
segments.append((current_voice, intro_text))
|
||||||
|
|
||||||
|
for idx, match in enumerate(voice_splits):
|
||||||
|
voice_name = match.group(1).strip()
|
||||||
|
start = match.end()
|
||||||
|
end = voice_splits[idx + 1].start() if idx + 1 < len(voice_splits) else len(text)
|
||||||
|
segment_text = text[start:end].strip()
|
||||||
|
|
||||||
|
is_valid, invalid_voice = validate_voice_name(voice_name)
|
||||||
|
if is_valid:
|
||||||
|
if "*" in voice_name:
|
||||||
|
normalized_parts = []
|
||||||
|
for part in voice_name.split("+"):
|
||||||
|
part = part.strip()
|
||||||
|
if "*" in part:
|
||||||
|
voice_part, weight = part.split("*", 1)
|
||||||
|
voice_part_lower = voice_part.strip().lower()
|
||||||
|
canonical_voice = next(
|
||||||
|
(v for v in get_voices("kokoro") if v.lower() == voice_part_lower),
|
||||||
|
voice_part.strip()
|
||||||
|
)
|
||||||
|
normalized_parts.append(f"{canonical_voice}*{weight.strip()}")
|
||||||
|
current_voice = " + ".join(normalized_parts)
|
||||||
|
else:
|
||||||
|
voice_name_lower = voice_name.lower()
|
||||||
|
current_voice = next(
|
||||||
|
(v for v in get_voices("kokoro") if v.lower() == voice_name_lower),
|
||||||
|
voice_name
|
||||||
|
)
|
||||||
|
valid_markers += 1
|
||||||
|
else:
|
||||||
|
invalid_markers += 1
|
||||||
|
|
||||||
|
if segment_text:
|
||||||
|
segments.append((current_voice, segment_text))
|
||||||
|
|
||||||
|
return segments, current_voice, valid_markers, invalid_markers
|
||||||
@@ -0,0 +1,355 @@
|
|||||||
|
"""Voice resolution helpers.
|
||||||
|
|
||||||
|
Functions for resolving voice specifications, collecting required voice IDs,
|
||||||
|
and determining the voice to use for chapters and chunks.
|
||||||
|
|
||||||
|
All functions accept ConversionRequest (the app-layer contract) instead of
|
||||||
|
UI-specific objects. This keeps the domain layer UI-agnostic.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Mapping, Optional, Set, Tuple
|
||||||
|
|
||||||
|
from abogen.tts_plugin.utils import get_voices, get_default_voice
|
||||||
|
from abogen.voice_formulas import extract_voice_ids, pairs_to_formula
|
||||||
|
from abogen.voice_cache import ensure_voice_assets
|
||||||
|
|
||||||
|
|
||||||
|
def spec_to_voice_ids(spec: Any) -> Set[str]:
|
||||||
|
text = str(spec or "").strip()
|
||||||
|
if not text:
|
||||||
|
return set()
|
||||||
|
if text == "__custom_mix":
|
||||||
|
return set()
|
||||||
|
if "*" in text:
|
||||||
|
try:
|
||||||
|
return set(extract_voice_ids(text))
|
||||||
|
except ValueError:
|
||||||
|
return set()
|
||||||
|
if text in get_voices("kokoro"):
|
||||||
|
return {text}
|
||||||
|
return set()
|
||||||
|
|
||||||
|
|
||||||
|
def _get_chapter_overrides(request: Any) -> list:
|
||||||
|
"""Extract chapter overrides from ConversionRequest."""
|
||||||
|
cc = getattr(request, "chapter_chunk", None)
|
||||||
|
if cc is not None:
|
||||||
|
return getattr(cc, "chapter_overrides", []) or []
|
||||||
|
return []
|
||||||
|
|
||||||
|
|
||||||
|
def _get_chunks(request: Any) -> list:
|
||||||
|
"""Extract chunks from ConversionRequest."""
|
||||||
|
cc = getattr(request, "chapter_chunk", None)
|
||||||
|
if cc is not None:
|
||||||
|
return getattr(cc, "chunks", []) or []
|
||||||
|
return []
|
||||||
|
|
||||||
|
|
||||||
|
def job_voice_fallback(request: Any) -> str:
|
||||||
|
base = str(getattr(request, "voice", "") or "").strip()
|
||||||
|
if base and base != "__custom_mix":
|
||||||
|
return base
|
||||||
|
|
||||||
|
speakers = getattr(request, "speakers", None)
|
||||||
|
if isinstance(speakers, dict):
|
||||||
|
narrator = speakers.get("narrator")
|
||||||
|
if isinstance(narrator, dict):
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
value = narrator.get(key)
|
||||||
|
candidate = str(value or "").strip()
|
||||||
|
if candidate and candidate != "__custom_mix":
|
||||||
|
return candidate
|
||||||
|
for payload in speakers.values() or []:
|
||||||
|
if not isinstance(payload, dict):
|
||||||
|
continue
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
value = payload.get(key)
|
||||||
|
candidate = str(value or "").strip()
|
||||||
|
if candidate and candidate != "__custom_mix":
|
||||||
|
return candidate
|
||||||
|
|
||||||
|
for chapter in _get_chapter_overrides(request):
|
||||||
|
if not isinstance(chapter, dict):
|
||||||
|
continue
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
candidate = str(chapter.get(key) or "").strip()
|
||||||
|
if candidate and candidate != "__custom_mix":
|
||||||
|
return candidate
|
||||||
|
|
||||||
|
return ""
|
||||||
|
|
||||||
|
|
||||||
|
def collect_required_voice_ids(request: Any) -> Set[str]:
|
||||||
|
voices: Set[str] = set()
|
||||||
|
voices.update(spec_to_voice_ids(request.voice))
|
||||||
|
voices.update(spec_to_voice_ids(job_voice_fallback(request)))
|
||||||
|
|
||||||
|
for chapter in _get_chapter_overrides(request):
|
||||||
|
if not isinstance(chapter, dict):
|
||||||
|
continue
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
voices.update(spec_to_voice_ids(chapter.get(key)))
|
||||||
|
|
||||||
|
for chunk in _get_chunks(request):
|
||||||
|
if not isinstance(chunk, dict):
|
||||||
|
continue
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
voices.update(spec_to_voice_ids(chunk.get(key)))
|
||||||
|
|
||||||
|
speakers = getattr(request, "speakers", {})
|
||||||
|
if isinstance(speakers, dict):
|
||||||
|
for payload in speakers.values() or []:
|
||||||
|
if not isinstance(payload, dict):
|
||||||
|
continue
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
voices.update(spec_to_voice_ids(payload.get(key)))
|
||||||
|
|
||||||
|
voices.update(get_voices("kokoro"))
|
||||||
|
return voices
|
||||||
|
|
||||||
|
|
||||||
|
def initialize_voice_cache(request: Any, events: Any = None) -> None:
|
||||||
|
"""Initialize voice cache by downloading required voice assets.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
request: ConversionRequest with voice/chapter/chunk/speaker info.
|
||||||
|
events: ConversionEvents for logging (optional, for backward compat).
|
||||||
|
"""
|
||||||
|
log = (lambda msg, level="info": events.log(msg, level=level)) if events else (lambda msg, level="info": None)
|
||||||
|
|
||||||
|
try:
|
||||||
|
targets = collect_required_voice_ids(request)
|
||||||
|
downloaded, errors = ensure_voice_assets(
|
||||||
|
targets,
|
||||||
|
on_progress=lambda message: log(message, level="debug"),
|
||||||
|
)
|
||||||
|
except RuntimeError as exc:
|
||||||
|
log(f"Voice cache unavailable: {exc}", level="warning")
|
||||||
|
return
|
||||||
|
|
||||||
|
if downloaded:
|
||||||
|
log(
|
||||||
|
f"Cached {len(downloaded)} voice asset{'s' if len(downloaded) != 1 else ''} locally.",
|
||||||
|
level="info",
|
||||||
|
)
|
||||||
|
|
||||||
|
for voice_id, error in errors.items():
|
||||||
|
log(f"Failed to cache voice '{voice_id}': {error}", level="warning")
|
||||||
|
|
||||||
|
|
||||||
|
def chapter_voice_spec(request: Any, override: Optional[Dict[str, Any]]) -> str:
|
||||||
|
if not override:
|
||||||
|
return job_voice_fallback(request)
|
||||||
|
|
||||||
|
resolved = str(override.get("resolved_voice", "")).strip()
|
||||||
|
if resolved:
|
||||||
|
return resolved
|
||||||
|
|
||||||
|
formula = str(override.get("voice_formula", "")).strip()
|
||||||
|
if formula:
|
||||||
|
return formula
|
||||||
|
|
||||||
|
voice = str(override.get("voice", "")).strip()
|
||||||
|
if voice:
|
||||||
|
return voice
|
||||||
|
|
||||||
|
return job_voice_fallback(request)
|
||||||
|
|
||||||
|
|
||||||
|
def chunk_voice_spec(request: Any, chunk: Dict[str, Any], fallback: str) -> str:
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
value = chunk.get(key)
|
||||||
|
if value:
|
||||||
|
return str(value)
|
||||||
|
|
||||||
|
speaker_id = chunk.get("speaker_id")
|
||||||
|
speakers = getattr(request, "speakers", None)
|
||||||
|
if isinstance(speakers, dict) and speaker_id in speakers:
|
||||||
|
speaker_entry = speakers.get(speaker_id) or {}
|
||||||
|
if isinstance(speaker_entry, dict):
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
value = speaker_entry.get(key)
|
||||||
|
if value:
|
||||||
|
return str(value)
|
||||||
|
profile_formula = speaker_entry.get("voice_formula")
|
||||||
|
if profile_formula:
|
||||||
|
return str(profile_formula)
|
||||||
|
|
||||||
|
profile_name = chunk.get("voice_profile")
|
||||||
|
if profile_name:
|
||||||
|
if isinstance(speakers, dict):
|
||||||
|
speaker_entry = speakers.get(profile_name)
|
||||||
|
if isinstance(speaker_entry, dict):
|
||||||
|
for key in ("resolved_voice", "voice_formula", "voice"):
|
||||||
|
value = speaker_entry.get(key)
|
||||||
|
if value:
|
||||||
|
return str(value)
|
||||||
|
|
||||||
|
if fallback:
|
||||||
|
return fallback
|
||||||
|
return job_voice_fallback(request)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_fallback_voice_spec(
|
||||||
|
base_spec: str,
|
||||||
|
job_voice: str,
|
||||||
|
voice_cache_keys: list[str],
|
||||||
|
provider: str = "kokoro",
|
||||||
|
) -> str:
|
||||||
|
"""Resolve the voice spec for intro/outro with a priority fallback chain.
|
||||||
|
|
||||||
|
Priority: base_spec → job_voice → first voice_cache key → default voice.
|
||||||
|
``"__custom_mix"`` is treated as empty (it is not a usable voice spec).
|
||||||
|
"""
|
||||||
|
spec = base_spec or job_voice
|
||||||
|
if spec == "__custom_mix":
|
||||||
|
spec = job_voice or ""
|
||||||
|
if not spec:
|
||||||
|
for key in voice_cache_keys:
|
||||||
|
if key and key != "__custom_mix":
|
||||||
|
spec = key.split(":", 1)[-1]
|
||||||
|
break
|
||||||
|
if not spec:
|
||||||
|
spec = get_default_voice(provider)
|
||||||
|
return spec
|
||||||
|
|
||||||
|
|
||||||
|
# ---------------------------------------------------------------------------
|
||||||
|
# Voice choice resolution (shared by all UIs)
|
||||||
|
# ---------------------------------------------------------------------------
|
||||||
|
|
||||||
|
|
||||||
|
def formula_from_profile(entry: Dict[str, Any]) -> Optional[str]:
|
||||||
|
"""Convert a voice profile entry to a voice formula string.
|
||||||
|
|
||||||
|
Handles both Kokoro (voices list) and SuperTonic (single voice) profiles.
|
||||||
|
Returns None if the entry has no usable voice data.
|
||||||
|
"""
|
||||||
|
if not isinstance(entry, dict):
|
||||||
|
return None
|
||||||
|
voices = entry.get("voices") or []
|
||||||
|
if not voices:
|
||||||
|
return None
|
||||||
|
return pairs_to_formula(voices)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_profile_voice(
|
||||||
|
profile_name: Optional[str],
|
||||||
|
*,
|
||||||
|
profiles: Optional[Mapping[str, Any]] = None,
|
||||||
|
) -> Tuple[str, Optional[str]]:
|
||||||
|
"""Resolve a profile name to (formula, language).
|
||||||
|
|
||||||
|
Args:
|
||||||
|
profile_name: Name of the profile to resolve.
|
||||||
|
profiles: Pre-loaded profiles dict. If None, loads from disk.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
(formula_string, language_code) or ("", None) if not found.
|
||||||
|
"""
|
||||||
|
if not profile_name:
|
||||||
|
return "", None
|
||||||
|
source = profiles if isinstance(profiles, Mapping) else None
|
||||||
|
if source is None:
|
||||||
|
from abogen.voice_profiles import load_profiles
|
||||||
|
source = load_profiles()
|
||||||
|
entry = source.get(profile_name) if isinstance(source, Mapping) else None
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
return "", None
|
||||||
|
formula = formula_from_profile(dict(entry)) or ""
|
||||||
|
language = entry.get("language") if isinstance(entry.get("language"), str) else None
|
||||||
|
if isinstance(language, str):
|
||||||
|
language = language.strip().lower() or None
|
||||||
|
return formula, language
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_voice_setting(
|
||||||
|
value: Any,
|
||||||
|
*,
|
||||||
|
profiles: Optional[Mapping[str, Any]] = None,
|
||||||
|
) -> Tuple[str, Optional[str], Optional[str]]:
|
||||||
|
"""Resolve a raw voice setting value into (spec, profile_name, language).
|
||||||
|
|
||||||
|
Parses 'profile:name' or 'speaker:name' prefixes and resolves
|
||||||
|
the profile to a formula string.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
value: Raw voice value from user input (e.g. "af_heart", "profile:MyMix").
|
||||||
|
profiles: Pre-loaded profiles dict. If None, loads from disk.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
(resolved_spec, profile_name, language) — profile_name and language
|
||||||
|
are None when the input is a plain voice spec.
|
||||||
|
"""
|
||||||
|
from abogen.domain.settings_core import split_profile_spec
|
||||||
|
|
||||||
|
base_spec, profile_name = split_profile_spec(value)
|
||||||
|
if profile_name:
|
||||||
|
formula, language = resolve_profile_voice(profile_name, profiles=profiles)
|
||||||
|
return formula or "", profile_name, language
|
||||||
|
return base_spec, None, None
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_voice_choice(
|
||||||
|
language: str,
|
||||||
|
base_voice: str,
|
||||||
|
profile_name: str,
|
||||||
|
custom_formula: str,
|
||||||
|
profiles: Dict[str, Any],
|
||||||
|
) -> Tuple[str, str, Optional[str]]:
|
||||||
|
"""Resolve a user's voice selection into (resolved_voice, resolved_language, selected_profile).
|
||||||
|
|
||||||
|
Handles three input modes:
|
||||||
|
1. Profile selection → resolves to formula (Kokoro) or speaker reference (SuperTonic)
|
||||||
|
2. Custom formula → used directly
|
||||||
|
3. Plain voice spec → passed through
|
||||||
|
|
||||||
|
Args:
|
||||||
|
language: Current language code (e.g. "a", "e").
|
||||||
|
base_voice: Base voice spec (voice ID or formula).
|
||||||
|
profile_name: Selected profile name (empty string if none).
|
||||||
|
custom_formula: Custom formula string (empty string if none).
|
||||||
|
profiles: Dict of all available profiles.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
(resolved_voice, resolved_language, selected_profile)
|
||||||
|
"""
|
||||||
|
from abogen.voice_profiles import normalize_profile_entry
|
||||||
|
|
||||||
|
resolved_voice = base_voice
|
||||||
|
resolved_language = language
|
||||||
|
selected_profile = None
|
||||||
|
|
||||||
|
if profile_name:
|
||||||
|
entry_raw = profiles.get(profile_name)
|
||||||
|
entry = normalize_profile_entry(entry_raw)
|
||||||
|
provider = str((entry or {}).get("provider") or "").strip().lower()
|
||||||
|
|
||||||
|
# Provider-aware behavior:
|
||||||
|
# - Kokoro profiles typically represent mixes (formula strings).
|
||||||
|
# - SuperTonic profiles represent a discrete voice id + settings.
|
||||||
|
# In that case, we return a speaker reference so downstream can
|
||||||
|
# resolve provider per-speaker and allow mixed-provider casting.
|
||||||
|
if provider == "supertonic":
|
||||||
|
resolved_voice = f"speaker:{profile_name}"
|
||||||
|
selected_profile = profile_name
|
||||||
|
profile_language = (entry or {}).get("language")
|
||||||
|
if profile_language:
|
||||||
|
resolved_language = str(profile_language)
|
||||||
|
else:
|
||||||
|
formula = formula_from_profile(entry or {}) if entry else None
|
||||||
|
if formula:
|
||||||
|
resolved_voice = formula
|
||||||
|
selected_profile = profile_name
|
||||||
|
profile_language = (entry or {}).get("language")
|
||||||
|
if profile_language:
|
||||||
|
resolved_language = profile_language
|
||||||
|
|
||||||
|
if custom_formula:
|
||||||
|
resolved_voice = custom_formula
|
||||||
|
selected_profile = None
|
||||||
|
|
||||||
|
return resolved_voice, resolved_language, selected_profile
|
||||||
@@ -0,0 +1,129 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from typing import Any, Dict, Mapping, Optional, Tuple
|
||||||
|
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
|
|
||||||
|
|
||||||
|
def infer_provider_from_spec(value: Any, fallback: str = "kokoro") -> str:
|
||||||
|
"""Infer TTS provider from voice specification."""
|
||||||
|
raw = str(value or "").strip()
|
||||||
|
if not raw:
|
||||||
|
return fallback
|
||||||
|
if raw.upper() == raw and raw.replace("_", "").isalnum():
|
||||||
|
return "supertonic"
|
||||||
|
if raw == "__custom_mix" or "*" in raw or "+" in raw:
|
||||||
|
return "kokoro"
|
||||||
|
if raw in get_voices("kokoro"):
|
||||||
|
return "kokoro"
|
||||||
|
return fallback
|
||||||
|
|
||||||
|
|
||||||
|
def supertonic_voice_from_spec(spec: Any, fallback: str) -> str:
|
||||||
|
"""Normalize a voice specification for Supertonic.
|
||||||
|
|
||||||
|
This function only performs Supertonic-specific normalization (uppercase conversion
|
||||||
|
and fallback handling). Backend resolution is handled by the registry.
|
||||||
|
"""
|
||||||
|
raw = str(spec or "").strip()
|
||||||
|
fallback_raw = str(fallback or "").strip()
|
||||||
|
|
||||||
|
# Normalize to uppercase for Supertonic voice IDs
|
||||||
|
upper = raw.upper() if raw else ""
|
||||||
|
|
||||||
|
# If empty or contains formula characters, use fallback
|
||||||
|
if not upper or "*" in upper or "+" in upper:
|
||||||
|
upper = fallback_raw.upper() if fallback_raw else ""
|
||||||
|
|
||||||
|
# If still empty, use default Supertonic voice
|
||||||
|
if not upper or "*" in upper or "+" in upper:
|
||||||
|
upper = "M1"
|
||||||
|
|
||||||
|
return upper
|
||||||
|
|
||||||
|
|
||||||
|
def split_speaker_reference(value: Any) -> Tuple[Optional[str], str]:
|
||||||
|
"""Parse speaker/profile reference from string.
|
||||||
|
|
||||||
|
Expected format: "speaker:name" or "profile:name"
|
||||||
|
Returns (name, original) or (None, original) if not a valid reference.
|
||||||
|
"""
|
||||||
|
raw = str(value or "").strip()
|
||||||
|
if not raw or ":" not in raw:
|
||||||
|
return None, raw
|
||||||
|
prefix, remainder = raw.split(":", 1)
|
||||||
|
prefix = prefix.strip().lower()
|
||||||
|
if prefix not in {"speaker", "profile"}:
|
||||||
|
return None, raw
|
||||||
|
name = remainder.strip()
|
||||||
|
return (name or None), raw
|
||||||
|
|
||||||
|
|
||||||
|
def formula_from_kokoro_entry(entry: Mapping[str, Any]) -> str:
|
||||||
|
"""Build voice formula string from kokoro entry."""
|
||||||
|
voices = entry.get("voices") or []
|
||||||
|
if not voices:
|
||||||
|
return ""
|
||||||
|
total = 0.0
|
||||||
|
parts: list[tuple[str, float]] = []
|
||||||
|
for item in voices:
|
||||||
|
if not isinstance(item, (list, tuple)) or len(item) < 2:
|
||||||
|
continue
|
||||||
|
name = str(item[0] or "").strip()
|
||||||
|
try:
|
||||||
|
weight = float(item[1])
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
continue
|
||||||
|
if name and weight > 0:
|
||||||
|
parts.append((name, weight))
|
||||||
|
total += weight
|
||||||
|
|
||||||
|
if not parts:
|
||||||
|
return ""
|
||||||
|
|
||||||
|
normalized = [(name, weight / total) for name, weight in parts]
|
||||||
|
return " + ".join(f"{name}*{weight:.6f}" for name, weight in normalized)
|
||||||
|
|
||||||
|
|
||||||
|
def coerce_truthy(value: Any, default: bool = True) -> bool:
|
||||||
|
"""Coerce a value to boolean with default."""
|
||||||
|
if isinstance(value, bool):
|
||||||
|
return value
|
||||||
|
if isinstance(value, str):
|
||||||
|
return value.lower() not in {"false", "0", "no", "off", ""}
|
||||||
|
if value is None:
|
||||||
|
return default
|
||||||
|
return bool(value)
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_voice_target(
|
||||||
|
raw_spec: str,
|
||||||
|
normalized_profiles: Dict[str, Dict[str, Any]],
|
||||||
|
*,
|
||||||
|
job_voice: str = "M1",
|
||||||
|
job_tts_provider: str = "kokoro",
|
||||||
|
job_supertonic_total_steps: int = 5,
|
||||||
|
job_speed: float = 1.0,
|
||||||
|
) -> Tuple[str, str, Optional[float], Optional[int]]:
|
||||||
|
"""Resolve a raw voice spec into (provider, voice_spec, speed_override, steps_override).
|
||||||
|
|
||||||
|
Pure function — all dependencies are passed as parameters.
|
||||||
|
"""
|
||||||
|
spec = str(raw_spec or "").strip()
|
||||||
|
speaker_name, _ = split_speaker_reference(spec)
|
||||||
|
if speaker_name and speaker_name in normalized_profiles:
|
||||||
|
entry = normalized_profiles[speaker_name]
|
||||||
|
provider = str(entry.get("provider") or "kokoro").strip().lower() or "kokoro"
|
||||||
|
if provider == "supertonic":
|
||||||
|
voice = str(entry.get("voice") or job_voice or "M1").strip() or "M1"
|
||||||
|
steps = int(entry.get("total_steps") or job_supertonic_total_steps or 5)
|
||||||
|
speed = float(entry.get("speed") or job_speed or 1.0)
|
||||||
|
return "supertonic", supertonic_voice_from_spec(voice, job_voice), speed, steps
|
||||||
|
formula = formula_from_kokoro_entry(entry)
|
||||||
|
return "kokoro", formula or spec, None, None
|
||||||
|
|
||||||
|
fallback_provider = str(job_tts_provider or "kokoro").strip().lower() or "kokoro"
|
||||||
|
inferred = infer_provider_from_spec(spec, fallback=fallback_provider)
|
||||||
|
if inferred == "supertonic":
|
||||||
|
return "supertonic", supertonic_voice_from_spec(spec, job_voice), None, None
|
||||||
|
return "kokoro", spec, None, None
|
||||||
@@ -0,0 +1,501 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import hashlib
|
||||||
|
import os
|
||||||
|
import re
|
||||||
|
import threading
|
||||||
|
import time
|
||||||
|
from collections import Counter
|
||||||
|
from dataclasses import dataclass, field
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional, Tuple
|
||||||
|
|
||||||
|
_Language = Any # type: ignore[misc,assignment]
|
||||||
|
Doc = Any # type: ignore[misc,assignment]
|
||||||
|
Span = Any # type: ignore[misc,assignment]
|
||||||
|
|
||||||
|
_SPACY: Any = None
|
||||||
|
_SPACY_LOADED = False
|
||||||
|
|
||||||
|
|
||||||
|
def _get_spacy() -> Any:
|
||||||
|
"""Import spaCy lazily (it pulls in torch/thinc, ~2s at startup)."""
|
||||||
|
global _SPACY, _SPACY_LOADED
|
||||||
|
if not _SPACY_LOADED:
|
||||||
|
_SPACY_LOADED = True
|
||||||
|
try: # pragma: no cover - fallback when spaCy not available during tests
|
||||||
|
import spacy # type: ignore[import-not-found]
|
||||||
|
except Exception: # pragma: no cover - spaCy optional during runtime bootstrap
|
||||||
|
spacy = None
|
||||||
|
_SPACY = spacy
|
||||||
|
return _SPACY
|
||||||
|
|
||||||
|
|
||||||
|
_TITLE_PREFIXES = (
|
||||||
|
"mr",
|
||||||
|
"mrs",
|
||||||
|
"ms",
|
||||||
|
"miss",
|
||||||
|
"dr",
|
||||||
|
"prof",
|
||||||
|
"sir",
|
||||||
|
"madam",
|
||||||
|
"lady",
|
||||||
|
"lord",
|
||||||
|
"capt",
|
||||||
|
"captain",
|
||||||
|
"col",
|
||||||
|
"colonel",
|
||||||
|
"maj",
|
||||||
|
"major",
|
||||||
|
"sgt",
|
||||||
|
"sergeant",
|
||||||
|
"rev",
|
||||||
|
"father",
|
||||||
|
"mother",
|
||||||
|
"brother",
|
||||||
|
"sister",
|
||||||
|
)
|
||||||
|
|
||||||
|
_STOP_LABELS = {
|
||||||
|
"the",
|
||||||
|
"that",
|
||||||
|
"this",
|
||||||
|
"those",
|
||||||
|
"these",
|
||||||
|
"there",
|
||||||
|
"here",
|
||||||
|
"then",
|
||||||
|
"and",
|
||||||
|
"but",
|
||||||
|
"or",
|
||||||
|
"nor",
|
||||||
|
"so",
|
||||||
|
"yet",
|
||||||
|
"dr",
|
||||||
|
"mr",
|
||||||
|
"mrs",
|
||||||
|
"ms",
|
||||||
|
"miss",
|
||||||
|
"sir",
|
||||||
|
"madam",
|
||||||
|
"lady",
|
||||||
|
"lord",
|
||||||
|
}
|
||||||
|
|
||||||
|
_EXCLUDED_NER_LABELS = {
|
||||||
|
"CARDINAL",
|
||||||
|
"DATE",
|
||||||
|
"ORDINAL",
|
||||||
|
"PERCENT",
|
||||||
|
"TIME",
|
||||||
|
"LAW",
|
||||||
|
"MONEY",
|
||||||
|
"QUANTITY",
|
||||||
|
}
|
||||||
|
|
||||||
|
_TITLE_PATTERN = re.compile(
|
||||||
|
r"^(?:" + "|".join(re.escape(prefix) for prefix in _TITLE_PREFIXES) + r")\.?\s+",
|
||||||
|
re.IGNORECASE,
|
||||||
|
)
|
||||||
|
_POSSESSIVE_PATTERN = re.compile(r"(?:'s|’s|\u2019s)$", re.IGNORECASE)
|
||||||
|
_NON_WORD_PATTERN = re.compile(r"[^\w\s'-]+")
|
||||||
|
_MULTI_SPACE_PATTERN = re.compile(r"\s+")
|
||||||
|
_SUFFIX_PATTERN = re.compile(
|
||||||
|
r",?\s+(?:jr|sr|ii|iii|iv|v|vi|md|phd|esq|esquire|dds|dvm)\.?$",
|
||||||
|
re.IGNORECASE,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(slots=True)
|
||||||
|
class EntityRecord:
|
||||||
|
key: Tuple[str, str]
|
||||||
|
label: str
|
||||||
|
kind: str
|
||||||
|
category: str
|
||||||
|
count: int = 0
|
||||||
|
samples: List[Dict[str, Any]] = field(default_factory=list)
|
||||||
|
chapter_indices: set[int] = field(default_factory=set)
|
||||||
|
forms: Counter = field(default_factory=Counter)
|
||||||
|
first_position: Optional[Tuple[int, int]] = None
|
||||||
|
|
||||||
|
def register(
|
||||||
|
self, *, chapter_index: int, position: int, text: str, sentence: Optional[str]
|
||||||
|
) -> None:
|
||||||
|
self.count += 1
|
||||||
|
self.chapter_indices.add(chapter_index)
|
||||||
|
self.forms[text] += 1
|
||||||
|
if self.first_position is None:
|
||||||
|
self.first_position = (chapter_index, position)
|
||||||
|
if sentence and len(self.samples) < 5:
|
||||||
|
payload = {
|
||||||
|
"excerpt": sentence.strip(),
|
||||||
|
"chapter_index": chapter_index,
|
||||||
|
}
|
||||||
|
if payload not in self.samples:
|
||||||
|
self.samples.append(payload)
|
||||||
|
|
||||||
|
def as_dict(self, ordinal: int) -> Dict[str, Any]:
|
||||||
|
chapter_indices = sorted(self.chapter_indices)
|
||||||
|
first_chapter = chapter_indices[0] if chapter_indices else None
|
||||||
|
return {
|
||||||
|
"id": f"{self.category}_{ordinal}",
|
||||||
|
"label": self.label,
|
||||||
|
"normalized": self.key[1],
|
||||||
|
"category": self.category,
|
||||||
|
"kind": self.kind,
|
||||||
|
"count": self.count,
|
||||||
|
"samples": list(self.samples),
|
||||||
|
"chapter_indices": chapter_indices,
|
||||||
|
"first_chapter": first_chapter,
|
||||||
|
"forms": self.forms.most_common(6),
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(slots=True)
|
||||||
|
class EntityExtractionResult:
|
||||||
|
summary: Dict[str, Any]
|
||||||
|
cache_key: str
|
||||||
|
elapsed: float
|
||||||
|
errors: List[str]
|
||||||
|
|
||||||
|
|
||||||
|
class EntityModelError(RuntimeError):
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
_MODEL_CACHE: Dict[str, Any] = {}
|
||||||
|
_MODEL_LOCK = threading.RLock()
|
||||||
|
|
||||||
|
|
||||||
|
def _resolve_model_name(language: str) -> str:
|
||||||
|
override = os.environ.get("ABOGEN_SPACY_MODEL")
|
||||||
|
if override:
|
||||||
|
return override.strip()
|
||||||
|
lowered = language.strip().lower()
|
||||||
|
if lowered.startswith("en"):
|
||||||
|
return "en_core_web_sm"
|
||||||
|
return "en_core_web_sm"
|
||||||
|
|
||||||
|
|
||||||
|
def _load_model(language: str) -> Any:
|
||||||
|
spacy = _get_spacy()
|
||||||
|
if spacy is None:
|
||||||
|
raise EntityModelError(
|
||||||
|
"spaCy is not available. Install spaCy to enable entity extraction."
|
||||||
|
)
|
||||||
|
|
||||||
|
model_name = _resolve_model_name(language)
|
||||||
|
cache_key = model_name.lower()
|
||||||
|
with _MODEL_LOCK:
|
||||||
|
if cache_key in _MODEL_CACHE:
|
||||||
|
return _MODEL_CACHE[cache_key]
|
||||||
|
try:
|
||||||
|
nlp = spacy.load(model_name) # type: ignore[arg-type]
|
||||||
|
except OSError as exc: # pragma: no cover - external dependency failure
|
||||||
|
raise EntityModelError(
|
||||||
|
f"spaCy model '{model_name}' is not installed. Download it with "
|
||||||
|
"`python -m spacy download en_core_web_sm`."
|
||||||
|
) from exc
|
||||||
|
nlp.max_length = max(nlp.max_length, 2_000_000)
|
||||||
|
_MODEL_CACHE[cache_key] = nlp
|
||||||
|
return nlp
|
||||||
|
|
||||||
|
|
||||||
|
def _normalize_label(text: str) -> str:
|
||||||
|
if not text:
|
||||||
|
return ""
|
||||||
|
stripped = text.strip().strip("\"'`“”’")
|
||||||
|
if not stripped:
|
||||||
|
return ""
|
||||||
|
stripped = _TITLE_PATTERN.sub("", stripped)
|
||||||
|
stripped = _SUFFIX_PATTERN.sub("", stripped)
|
||||||
|
stripped = _POSSESSIVE_PATTERN.sub("", stripped)
|
||||||
|
stripped = _NON_WORD_PATTERN.sub(" ", stripped)
|
||||||
|
stripped = _MULTI_SPACE_PATTERN.sub(" ", stripped)
|
||||||
|
stripped = stripped.strip()
|
||||||
|
if not stripped or stripped.lower() in _STOP_LABELS:
|
||||||
|
return ""
|
||||||
|
parts = stripped.split()
|
||||||
|
if not parts:
|
||||||
|
return ""
|
||||||
|
if len(parts) == 1 and len(parts[0]) <= 1:
|
||||||
|
return ""
|
||||||
|
# Normalise casing: preserve uppercase abbreviations, otherwise title case.
|
||||||
|
normalized_parts = []
|
||||||
|
for index, part in enumerate(parts):
|
||||||
|
if part.isupper():
|
||||||
|
normalized_parts.append(part)
|
||||||
|
elif part[:1].isupper():
|
||||||
|
normalized_parts.append(part[:1].upper() + part[1:])
|
||||||
|
elif index == 0:
|
||||||
|
normalized_parts.append(part[:1].upper() + part[1:])
|
||||||
|
else:
|
||||||
|
normalized_parts.append(part)
|
||||||
|
normalized = " ".join(normalized_parts).strip()
|
||||||
|
if normalized.lower() in _STOP_LABELS:
|
||||||
|
return ""
|
||||||
|
return normalized
|
||||||
|
|
||||||
|
|
||||||
|
def _token_key(value: str) -> str:
|
||||||
|
return _MULTI_SPACE_PATTERN.sub(" ", value.lower().strip()).strip()
|
||||||
|
|
||||||
|
|
||||||
|
def _iter_named_entities(doc: Any) -> Iterable[Any]: # type: ignore[override]
|
||||||
|
for ent in getattr(doc, "ents", ()):
|
||||||
|
if ent.label_ == "":
|
||||||
|
continue
|
||||||
|
yield ent
|
||||||
|
|
||||||
|
|
||||||
|
def _extract_propn_tokens(doc: Any) -> Iterable[Any]: # type: ignore[override]
|
||||||
|
seen: set[Tuple[int, int]] = set()
|
||||||
|
for ent in getattr(doc, "ents", ()): # guard multi-token spans
|
||||||
|
seen.add((ent.start, ent.end))
|
||||||
|
for token in doc:
|
||||||
|
if token.pos_ != "PROPN":
|
||||||
|
continue
|
||||||
|
span_key = (token.i, token.i + 1)
|
||||||
|
if span_key in seen:
|
||||||
|
continue
|
||||||
|
if token.is_stop:
|
||||||
|
continue
|
||||||
|
text = token.text.strip()
|
||||||
|
if not text:
|
||||||
|
continue
|
||||||
|
if token.ent_type_:
|
||||||
|
continue
|
||||||
|
yield doc[token.i : token.i + 1]
|
||||||
|
|
||||||
|
|
||||||
|
def _empty_result(
|
||||||
|
cache_key: str, error: Optional[str] = None
|
||||||
|
) -> EntityExtractionResult:
|
||||||
|
payload = {
|
||||||
|
"people": [],
|
||||||
|
"entities": [],
|
||||||
|
"index": {"tokens": []},
|
||||||
|
"stats": {
|
||||||
|
"tokens": 0,
|
||||||
|
"chapters": 0,
|
||||||
|
"processed": False,
|
||||||
|
},
|
||||||
|
"model": None,
|
||||||
|
}
|
||||||
|
errors = [error] if error else []
|
||||||
|
return EntityExtractionResult(
|
||||||
|
summary=payload, cache_key=cache_key, elapsed=0.0, errors=errors
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def extract_entities(
|
||||||
|
chapters: Iterable[Mapping[str, Any]],
|
||||||
|
*,
|
||||||
|
language: str = "en",
|
||||||
|
) -> EntityExtractionResult:
|
||||||
|
start = time.perf_counter()
|
||||||
|
normalized_language = language or "en"
|
||||||
|
combined_hasher = hashlib.sha1()
|
||||||
|
chapter_texts: List[Tuple[int, str]] = []
|
||||||
|
for idx, chapter in enumerate(chapters):
|
||||||
|
text = chapter.get("text") if isinstance(chapter, Mapping) else None
|
||||||
|
text_value = str(text or "")
|
||||||
|
original_index = idx
|
||||||
|
if isinstance(chapter, Mapping):
|
||||||
|
try:
|
||||||
|
original_index = int(chapter.get("index", idx))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
original_index = idx
|
||||||
|
chapter_texts.append((original_index, text_value))
|
||||||
|
if text_value:
|
||||||
|
combined_hasher.update(text_value.encode("utf-8", "ignore"))
|
||||||
|
combined_hasher.update(str(original_index).encode("utf-8", "ignore"))
|
||||||
|
cache_key = combined_hasher.hexdigest()
|
||||||
|
|
||||||
|
if not chapter_texts:
|
||||||
|
return _empty_result(cache_key)
|
||||||
|
|
||||||
|
try:
|
||||||
|
nlp = _load_model(normalized_language)
|
||||||
|
except EntityModelError as exc:
|
||||||
|
return _empty_result(cache_key, str(exc))
|
||||||
|
|
||||||
|
records: Dict[Tuple[str, str], EntityRecord] = {}
|
||||||
|
tokens_for_index: Dict[str, Dict[str, Any]] = {}
|
||||||
|
processed_tokens = 0
|
||||||
|
|
||||||
|
for chapter_index, text in chapter_texts:
|
||||||
|
trimmed = text.strip()
|
||||||
|
if not trimmed:
|
||||||
|
continue
|
||||||
|
if len(trimmed) + 1024 > nlp.max_length:
|
||||||
|
nlp.max_length = len(trimmed) + 1024
|
||||||
|
doc = nlp(trimmed)
|
||||||
|
|
||||||
|
def _register_span(span: Any, category_hint: Optional[str] = None) -> None:
|
||||||
|
nonlocal processed_tokens
|
||||||
|
if category_hint is None and span.label_ in _EXCLUDED_NER_LABELS:
|
||||||
|
return
|
||||||
|
cleaned = _normalize_label(span.text)
|
||||||
|
if not cleaned:
|
||||||
|
return
|
||||||
|
key = _token_key(cleaned)
|
||||||
|
if not key:
|
||||||
|
return
|
||||||
|
category = category_hint or (
|
||||||
|
"people" if span.label_ == "PERSON" else "entities"
|
||||||
|
)
|
||||||
|
record_key = (category, key)
|
||||||
|
record = records.get(record_key)
|
||||||
|
if record is None:
|
||||||
|
record = EntityRecord(
|
||||||
|
key=record_key,
|
||||||
|
label=cleaned,
|
||||||
|
kind=span.label_
|
||||||
|
or ("PROPN" if category == "entities" else "PERSON"),
|
||||||
|
category=category,
|
||||||
|
)
|
||||||
|
records[record_key] = record
|
||||||
|
sentence = (
|
||||||
|
span.sent.text
|
||||||
|
if hasattr(span, "sent") and span.sent is not None
|
||||||
|
else None
|
||||||
|
)
|
||||||
|
record.register(
|
||||||
|
chapter_index=chapter_index,
|
||||||
|
position=span.start,
|
||||||
|
text=span.text,
|
||||||
|
sentence=sentence,
|
||||||
|
)
|
||||||
|
processed_tokens += 1
|
||||||
|
index_entry = tokens_for_index.get(key)
|
||||||
|
if index_entry is None:
|
||||||
|
index_entry = {
|
||||||
|
"token": record.label,
|
||||||
|
"normalized": key,
|
||||||
|
"category": category,
|
||||||
|
"count": 0,
|
||||||
|
"samples": [],
|
||||||
|
}
|
||||||
|
tokens_for_index[key] = index_entry
|
||||||
|
index_entry["count"] += 1
|
||||||
|
if sentence and len(index_entry["samples"]) < 3:
|
||||||
|
if sentence not in index_entry["samples"]:
|
||||||
|
index_entry["samples"].append(sentence)
|
||||||
|
|
||||||
|
for ent in _iter_named_entities(doc):
|
||||||
|
_register_span(ent)
|
||||||
|
|
||||||
|
for span in _extract_propn_tokens(doc):
|
||||||
|
_register_span(span, category_hint="entities")
|
||||||
|
|
||||||
|
elapsed = time.perf_counter() - start
|
||||||
|
|
||||||
|
people_records = [
|
||||||
|
record for record in records.values() if record.category == "people"
|
||||||
|
]
|
||||||
|
people_keys = {record.key[1] for record in people_records}
|
||||||
|
entity_records = [
|
||||||
|
record
|
||||||
|
for record in records.values()
|
||||||
|
if record.category == "entities"
|
||||||
|
and record.key[1] not in people_keys
|
||||||
|
and record.kind != "PERSON"
|
||||||
|
]
|
||||||
|
|
||||||
|
people_records.sort(key=lambda rec: (-rec.count, rec.label))
|
||||||
|
entity_records.sort(key=lambda rec: (-rec.count, rec.label))
|
||||||
|
|
||||||
|
people_payload = [
|
||||||
|
record.as_dict(index + 1) for index, record in enumerate(people_records)
|
||||||
|
]
|
||||||
|
entity_payload = [
|
||||||
|
record.as_dict(index + 1) for index, record in enumerate(entity_records)
|
||||||
|
]
|
||||||
|
|
||||||
|
index_payload = sorted(
|
||||||
|
tokens_for_index.values(), key=lambda item: (-item["count"], item["token"])
|
||||||
|
)
|
||||||
|
|
||||||
|
summary = {
|
||||||
|
"people": people_payload,
|
||||||
|
"entities": entity_payload,
|
||||||
|
"index": {"tokens": index_payload},
|
||||||
|
"stats": {
|
||||||
|
"tokens": processed_tokens,
|
||||||
|
"chapters": len(chapter_texts),
|
||||||
|
"processed": True,
|
||||||
|
"people": len(people_payload),
|
||||||
|
"entities": len(entity_payload),
|
||||||
|
},
|
||||||
|
"model": {
|
||||||
|
"name": getattr(nlp, "meta", {}).get("name", "unknown"),
|
||||||
|
"version": getattr(nlp, "meta", {}).get("version", "unknown"),
|
||||||
|
"lang": getattr(nlp, "meta", {}).get("lang", normalized_language),
|
||||||
|
},
|
||||||
|
}
|
||||||
|
|
||||||
|
return EntityExtractionResult(
|
||||||
|
summary=summary, cache_key=cache_key, elapsed=elapsed, errors=[]
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def search_tokens(
|
||||||
|
index: Mapping[str, Any], query: str, *, limit: int = 15
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
tokens = index.get("tokens") if isinstance(index, Mapping) else None
|
||||||
|
if not isinstance(tokens, list) or not query:
|
||||||
|
return []
|
||||||
|
normalized = query.strip().lower()
|
||||||
|
if not normalized:
|
||||||
|
return tokens[:limit]
|
||||||
|
results: List[Dict[str, Any]] = []
|
||||||
|
for entry in tokens:
|
||||||
|
token_label = str(entry.get("token", ""))
|
||||||
|
normalized_label = token_label.lower()
|
||||||
|
if normalized in normalized_label or normalized in str(
|
||||||
|
entry.get("normalized", "")
|
||||||
|
):
|
||||||
|
results.append(entry)
|
||||||
|
if len(results) >= limit:
|
||||||
|
break
|
||||||
|
return results
|
||||||
|
|
||||||
|
|
||||||
|
def merge_override(
|
||||||
|
summary: Mapping[str, Any], overrides: Mapping[str, Mapping[str, Any]]
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
if not isinstance(summary, Mapping):
|
||||||
|
return {"people": [], "entities": []}
|
||||||
|
merged_summary: Dict[str, Any] = dict(summary)
|
||||||
|
for key in ("people", "entities"):
|
||||||
|
items = summary.get(key)
|
||||||
|
if not isinstance(items, list):
|
||||||
|
continue
|
||||||
|
merged_items: List[Dict[str, Any]] = []
|
||||||
|
for entry in items:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
normalized = _token_key(
|
||||||
|
str(entry.get("normalized") or entry.get("label") or "")
|
||||||
|
)
|
||||||
|
merged = dict(entry)
|
||||||
|
if normalized and normalized in overrides:
|
||||||
|
merged_override = dict(overrides[normalized])
|
||||||
|
merged["override"] = merged_override
|
||||||
|
merged_items.append(merged)
|
||||||
|
merged_summary[key] = merged_items
|
||||||
|
return merged_summary
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_token(token: str) -> str:
|
||||||
|
return _token_key(_normalize_label(token))
|
||||||
|
|
||||||
|
|
||||||
|
def normalize_manual_override_token(token: str) -> str:
|
||||||
|
if not token:
|
||||||
|
return ""
|
||||||
|
stripped = token.strip().strip("\"'`“”’")
|
||||||
|
if not stripped:
|
||||||
|
return ""
|
||||||
|
return _MULTI_SPACE_PATTERN.sub(" ", stripped.lower()).strip()
|
||||||
@@ -0,0 +1,3 @@
|
|||||||
|
from .exporter import EPUB3PackageBuilder, build_epub3_package
|
||||||
|
|
||||||
|
__all__ = ["EPUB3PackageBuilder", "build_epub3_package"]
|
||||||
@@ -0,0 +1,912 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import html
|
||||||
|
import re
|
||||||
|
import shutil
|
||||||
|
import uuid
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from datetime import datetime, timezone
|
||||||
|
from pathlib import Path
|
||||||
|
from tempfile import TemporaryDirectory
|
||||||
|
from typing import Any, Dict, Iterable, List, Optional, Pattern, Sequence, Tuple
|
||||||
|
import zipfile
|
||||||
|
|
||||||
|
from abogen.text_extractor import ExtractedChapter, ExtractionResult
|
||||||
|
from abogen.domain.metadata_helpers import normalize_metadata_map
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(slots=True)
|
||||||
|
class ChunkOverlay:
|
||||||
|
id: str
|
||||||
|
text: str
|
||||||
|
original_text: Optional[str]
|
||||||
|
start: Optional[float]
|
||||||
|
end: Optional[float]
|
||||||
|
speaker_id: str
|
||||||
|
voice: Optional[Dict[str, str]]
|
||||||
|
level: Optional[str] = None
|
||||||
|
group_id: Optional[str] = None
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(slots=True)
|
||||||
|
class ChapterDocument:
|
||||||
|
index: int # zero-based
|
||||||
|
title: str
|
||||||
|
xhtml_name: str
|
||||||
|
smil_name: str
|
||||||
|
chunks: List[ChunkOverlay]
|
||||||
|
start: Optional[float]
|
||||||
|
end: Optional[float]
|
||||||
|
|
||||||
|
|
||||||
|
class EPUB3PackageBuilder:
|
||||||
|
"""Constructs an EPUB 3 package with media overlays."""
|
||||||
|
|
||||||
|
def __init__(
|
||||||
|
self,
|
||||||
|
*,
|
||||||
|
output_path: Path,
|
||||||
|
book_id: str,
|
||||||
|
extraction: ExtractionResult,
|
||||||
|
metadata_tags: Dict[str, Any],
|
||||||
|
chapter_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunk_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunks: Iterable[Dict[str, Any]],
|
||||||
|
audio_path: Path,
|
||||||
|
speaker_mode: str = "single",
|
||||||
|
cover_image_path: Optional[Path] = None,
|
||||||
|
cover_image_mime: Optional[str] = None,
|
||||||
|
) -> None:
|
||||||
|
self.output_path = output_path
|
||||||
|
self.book_id = book_id or str(uuid.uuid4())
|
||||||
|
self.extraction = extraction
|
||||||
|
self.metadata_tags = normalize_metadata_map(metadata_tags)
|
||||||
|
self.chapter_markers = list(chapter_markers or [])
|
||||||
|
self.chunk_markers = list(chunk_markers or [])
|
||||||
|
self.chunks = list(chunks or [])
|
||||||
|
self.audio_path = audio_path
|
||||||
|
self.speaker_mode = speaker_mode or "single"
|
||||||
|
self.cover_image_path = cover_image_path if cover_image_path and cover_image_path.exists() else None
|
||||||
|
self.cover_image_mime = cover_image_mime
|
||||||
|
|
||||||
|
self._combined_metadata = _combine_metadata(extraction.metadata, self.metadata_tags)
|
||||||
|
self._title = self._combined_metadata.get("title") or self._fallback_title()
|
||||||
|
self._authors = _split_authors(self._combined_metadata)
|
||||||
|
self._language = self._determine_language()
|
||||||
|
self._publisher = self._combined_metadata.get("publisher") or ""
|
||||||
|
self._description = self._combined_metadata.get("comment")
|
||||||
|
self._duration = _calculate_total_duration(self.chunk_markers, self.chapter_markers)
|
||||||
|
self._modified = _utc_now_iso()
|
||||||
|
|
||||||
|
def build(self) -> Path:
|
||||||
|
if not self.audio_path or not self.audio_path.exists():
|
||||||
|
raise FileNotFoundError(f"Audio asset missing: {self.audio_path}")
|
||||||
|
|
||||||
|
chapter_documents = self._build_chapter_documents()
|
||||||
|
|
||||||
|
with TemporaryDirectory() as tmp_dir:
|
||||||
|
root = Path(tmp_dir)
|
||||||
|
oebps = root / "OEBPS"
|
||||||
|
text_dir = oebps / "text"
|
||||||
|
smil_dir = oebps / "smil"
|
||||||
|
audio_dir = oebps / "audio"
|
||||||
|
image_dir = oebps / "images"
|
||||||
|
stylesheet_dir = oebps / "styles"
|
||||||
|
|
||||||
|
for directory in (oebps, text_dir, smil_dir, audio_dir, stylesheet_dir):
|
||||||
|
directory.mkdir(parents=True, exist_ok=True)
|
||||||
|
if self.cover_image_path:
|
||||||
|
image_dir.mkdir(parents=True, exist_ok=True)
|
||||||
|
|
||||||
|
_write_mimetype(root)
|
||||||
|
_write_container_xml(root)
|
||||||
|
|
||||||
|
audio_filename = self.audio_path.name
|
||||||
|
embedded_audio = audio_dir / audio_filename
|
||||||
|
shutil.copy2(self.audio_path, embedded_audio)
|
||||||
|
|
||||||
|
if self.cover_image_path:
|
||||||
|
shutil.copy2(self.cover_image_path, image_dir / self.cover_image_path.name)
|
||||||
|
|
||||||
|
stylesheet_path = stylesheet_dir / "style.css"
|
||||||
|
stylesheet_path.write_text(_DEFAULT_STYLESHEET, encoding="utf-8")
|
||||||
|
|
||||||
|
for chapter in chapter_documents:
|
||||||
|
chapter_path = text_dir / chapter.xhtml_name
|
||||||
|
chapter_path.write_text(
|
||||||
|
self._render_chapter_xhtml(chapter),
|
||||||
|
encoding="utf-8",
|
||||||
|
)
|
||||||
|
smil_path = smil_dir / chapter.smil_name
|
||||||
|
smil_path.write_text(
|
||||||
|
self._render_chapter_smil(chapter, f"audio/{audio_filename}"),
|
||||||
|
encoding="utf-8",
|
||||||
|
)
|
||||||
|
|
||||||
|
nav_path = oebps / "nav.xhtml"
|
||||||
|
nav_path.write_text(self._render_nav(chapter_documents), encoding="utf-8")
|
||||||
|
|
||||||
|
opf_path = oebps / "content.opf"
|
||||||
|
opf_path.write_text(
|
||||||
|
self._render_opf(
|
||||||
|
chapter_documents,
|
||||||
|
audio_filename,
|
||||||
|
has_cover=self.cover_image_path is not None,
|
||||||
|
stylesheet_path=stylesheet_path.relative_to(oebps),
|
||||||
|
),
|
||||||
|
encoding="utf-8",
|
||||||
|
)
|
||||||
|
|
||||||
|
self.output_path.parent.mkdir(parents=True, exist_ok=True)
|
||||||
|
with zipfile.ZipFile(self.output_path, "w", compression=zipfile.ZIP_DEFLATED) as archive:
|
||||||
|
# Ensure mimetype is the first entry and stored without compression
|
||||||
|
mimetype_path = root / "mimetype"
|
||||||
|
info = zipfile.ZipInfo("mimetype")
|
||||||
|
info.compress_type = zipfile.ZIP_STORED
|
||||||
|
archive.writestr(info, mimetype_path.read_bytes())
|
||||||
|
|
||||||
|
for file_path in sorted(root.rglob("*")):
|
||||||
|
if file_path == mimetype_path or file_path.is_dir():
|
||||||
|
continue
|
||||||
|
archive.write(file_path, file_path.relative_to(root))
|
||||||
|
|
||||||
|
return self.output_path
|
||||||
|
|
||||||
|
# ------------------------------------------------------------------
|
||||||
|
def _build_chapter_documents(self) -> List[ChapterDocument]:
|
||||||
|
chunk_lookup = _build_chunk_lookup(self.chunks)
|
||||||
|
markers_by_chapter = _group_markers_by_chapter(self.chunk_markers)
|
||||||
|
chapter_meta = {int(entry.get("index", idx + 1)) - 1: dict(entry) for idx, entry in enumerate(self.chapter_markers)}
|
||||||
|
|
||||||
|
documents: List[ChapterDocument] = []
|
||||||
|
for chapter_index, chapter in enumerate(self.extraction.chapters):
|
||||||
|
markers = markers_by_chapter.get(chapter_index, [])
|
||||||
|
if not markers and chunk_lookup.by_chapter.get(chapter_index):
|
||||||
|
markers = [
|
||||||
|
{
|
||||||
|
"id": item.get("id"),
|
||||||
|
"chapter_index": chapter_index,
|
||||||
|
"chunk_index": item.get("chunk_index"),
|
||||||
|
"start": None,
|
||||||
|
"end": None,
|
||||||
|
"speaker_id": item.get("speaker_id", "narrator"),
|
||||||
|
"voice": item.get("voice"),
|
||||||
|
}
|
||||||
|
for item in chunk_lookup.by_chapter.get(chapter_index, [])
|
||||||
|
]
|
||||||
|
|
||||||
|
if not markers:
|
||||||
|
markers = [
|
||||||
|
{
|
||||||
|
"id": f"chap{chapter_index:04d}_auto0000",
|
||||||
|
"chapter_index": chapter_index,
|
||||||
|
"chunk_index": 0,
|
||||||
|
"start": chapter_meta.get(chapter_index, {}).get("start"),
|
||||||
|
"end": chapter_meta.get(chapter_index, {}).get("end"),
|
||||||
|
"speaker_id": "narrator",
|
||||||
|
"voice": None,
|
||||||
|
}
|
||||||
|
]
|
||||||
|
|
||||||
|
overlays = self._build_overlays_for_chapter(
|
||||||
|
chapter_index,
|
||||||
|
markers,
|
||||||
|
chunk_lookup,
|
||||||
|
)
|
||||||
|
|
||||||
|
xhtml_name = f"chapter_{chapter_index + 1:04d}.xhtml"
|
||||||
|
smil_name = f"chapter_{chapter_index + 1:04d}.smil"
|
||||||
|
|
||||||
|
chapter_start = chapter_meta.get(chapter_index, {}).get("start")
|
||||||
|
chapter_end = chapter_meta.get(chapter_index, {}).get("end")
|
||||||
|
|
||||||
|
documents.append(
|
||||||
|
ChapterDocument(
|
||||||
|
index=chapter_index,
|
||||||
|
title=chapter.title or f"Chapter {chapter_index + 1}",
|
||||||
|
xhtml_name=xhtml_name,
|
||||||
|
smil_name=smil_name,
|
||||||
|
chunks=overlays,
|
||||||
|
start=chapter_start,
|
||||||
|
end=chapter_end,
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
return documents
|
||||||
|
|
||||||
|
def _build_overlays_for_chapter(
|
||||||
|
self,
|
||||||
|
chapter_index: int,
|
||||||
|
markers: Sequence[Dict[str, Any]],
|
||||||
|
chunk_lookup: "ChunkLookup",
|
||||||
|
) -> List[ChunkOverlay]:
|
||||||
|
overlays: List[ChunkOverlay] = []
|
||||||
|
used_ids: set[str] = set()
|
||||||
|
|
||||||
|
chapter_chunks = list(chunk_lookup.by_chapter.get(chapter_index, []))
|
||||||
|
chapter_chunks.sort(key=lambda entry: _safe_int(entry.get("chunk_index")))
|
||||||
|
|
||||||
|
for position, marker in enumerate(markers):
|
||||||
|
chunk_id = marker.get("id")
|
||||||
|
chunk_entry = None
|
||||||
|
if chunk_id and chunk_id in chunk_lookup.by_id:
|
||||||
|
chunk_entry = chunk_lookup.by_id[chunk_id]
|
||||||
|
else:
|
||||||
|
candidate_index = _safe_int(marker.get("chunk_index"))
|
||||||
|
chunk_entry = _find_chunk_by_index(chapter_chunks, candidate_index)
|
||||||
|
if chunk_entry is None and chapter_chunks and position < len(chapter_chunks):
|
||||||
|
chunk_entry = chapter_chunks[position]
|
||||||
|
|
||||||
|
level = None
|
||||||
|
if chunk_entry is None:
|
||||||
|
text = self.extraction.chapters[chapter_index].text
|
||||||
|
speaker_id = str(marker.get("speaker_id") or "narrator")
|
||||||
|
voice = marker.get("voice")
|
||||||
|
else:
|
||||||
|
display_text = chunk_entry.get("display_text")
|
||||||
|
text = str(chunk_entry.get("text") or "")
|
||||||
|
speaker_id = str(chunk_entry.get("speaker_id") or marker.get("speaker_id") or "narrator")
|
||||||
|
voice = chunk_entry.get("voice") or chunk_entry.get("resolved_voice") or marker.get("voice")
|
||||||
|
level = chunk_entry.get("level") or None
|
||||||
|
if chunk_entry is None:
|
||||||
|
level = None
|
||||||
|
|
||||||
|
normalized_id = _normalize_chunk_id(chunk_id) if chunk_id else None
|
||||||
|
if not normalized_id:
|
||||||
|
normalized_id = f"chap{chapter_index:04d}_chunk{position:04d}"
|
||||||
|
while normalized_id in used_ids:
|
||||||
|
normalized_id = f"{normalized_id}_dup"
|
||||||
|
used_ids.add(normalized_id)
|
||||||
|
|
||||||
|
raw_group_key = chunk_entry.get("id") if chunk_entry else chunk_id
|
||||||
|
group_id = _derive_group_id(raw_group_key, level)
|
||||||
|
normalized_group_id = _normalize_chunk_id(group_id) if group_id else None
|
||||||
|
|
||||||
|
original_text = None
|
||||||
|
if chunk_entry is not None:
|
||||||
|
original_text = chunk_entry.get("original_text") or chunk_entry.get("display_text")
|
||||||
|
|
||||||
|
overlays.append(
|
||||||
|
ChunkOverlay(
|
||||||
|
id=normalized_id,
|
||||||
|
text=text or self.extraction.chapters[chapter_index].text,
|
||||||
|
original_text=str(original_text) if original_text is not None else None,
|
||||||
|
start=_safe_float(marker.get("start")),
|
||||||
|
end=_safe_float(marker.get("end")),
|
||||||
|
speaker_id=speaker_id,
|
||||||
|
voice=voice if isinstance(voice, dict) else None,
|
||||||
|
level=str(level) if level else None,
|
||||||
|
group_id=normalized_group_id,
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
chapter_text = ""
|
||||||
|
if 0 <= chapter_index < len(self.extraction.chapters):
|
||||||
|
chapter_entry = self.extraction.chapters[chapter_index]
|
||||||
|
chapter_text = getattr(chapter_entry, "text", "") or ""
|
||||||
|
|
||||||
|
_restore_original_chunk_text(chapter_text, overlays)
|
||||||
|
|
||||||
|
return overlays
|
||||||
|
|
||||||
|
def _render_chapter_xhtml(self, chapter: ChapterDocument) -> str:
|
||||||
|
language = html.escape(self._language or "en")
|
||||||
|
title = html.escape(chapter.title)
|
||||||
|
grouped_chunks = _group_chunks_for_render(chapter.chunks)
|
||||||
|
chunk_html = "\n".join(
|
||||||
|
_render_chunk_group_html(group_id, items) for group_id, items in grouped_chunks
|
||||||
|
)
|
||||||
|
if not chunk_html:
|
||||||
|
chunk_html = "<p></p>"
|
||||||
|
original_block = ""
|
||||||
|
if chapter.chunks:
|
||||||
|
original_text = "".join((chunk.original_text if chunk.original_text is not None else (chunk.text or "")) for chunk in chapter.chunks)
|
||||||
|
if original_text:
|
||||||
|
safe_original = html.escape(original_text)
|
||||||
|
original_block = (
|
||||||
|
" <pre class=\"chapter-original\" hidden=\"hidden\" aria-hidden=\"true\">\n"
|
||||||
|
f"{safe_original}\n"
|
||||||
|
" </pre>"
|
||||||
|
)
|
||||||
|
|
||||||
|
return (
|
||||||
|
"<?xml version=\"1.0\" encoding=\"utf-8\"?>\n"
|
||||||
|
"<html xmlns=\"http://www.w3.org/1999/xhtml\" xmlns:epub=\"http://www.idpf.org/2007/ops\" xml:lang=\"{lang}\" lang=\"{lang}\">\n"
|
||||||
|
" <head>\n"
|
||||||
|
" <title>{title}</title>\n"
|
||||||
|
" <meta charset=\"utf-8\"/>\n"
|
||||||
|
" <link rel=\"stylesheet\" type=\"text/css\" href=\"styles/style.css\"/>\n"
|
||||||
|
" </head>\n"
|
||||||
|
" <body>\n"
|
||||||
|
" <section epub:type=\"chapter\" id=\"chapter-{index:04d}\">\n"
|
||||||
|
" <h1>{title}</h1>\n"
|
||||||
|
" {chunks}\n"
|
||||||
|
"{original_block}"
|
||||||
|
" </section>\n"
|
||||||
|
" </body>\n"
|
||||||
|
"</html>\n"
|
||||||
|
).format(
|
||||||
|
lang=language,
|
||||||
|
title=title,
|
||||||
|
index=chapter.index + 1,
|
||||||
|
chunks=chunk_html,
|
||||||
|
original_block=("" if not original_block else f"{original_block}\n"),
|
||||||
|
)
|
||||||
|
|
||||||
|
def _render_chapter_smil(self, chapter: ChapterDocument, audio_href: str) -> str:
|
||||||
|
par_lines = []
|
||||||
|
for chunk in chapter.chunks:
|
||||||
|
par_lines.append(
|
||||||
|
" <par id=\"par-{chunk_id}\">\n"
|
||||||
|
" <text src=\"text/{xhtml}#{chunk_id}\"/>\n"
|
||||||
|
" <audio src=\"{audio}\" clipBegin=\"{start}\" clipEnd=\"{end}\"/>\n"
|
||||||
|
" </par>".format(
|
||||||
|
chunk_id=html.escape(chunk.id),
|
||||||
|
xhtml=html.escape(chapter.xhtml_name),
|
||||||
|
audio=html.escape(audio_href),
|
||||||
|
start=_format_smil_time(chunk.start),
|
||||||
|
end=_format_smil_time(chunk.end),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
return (
|
||||||
|
"<?xml version=\"1.0\" encoding=\"utf-8\"?>\n"
|
||||||
|
"<smil xmlns=\"http://www.w3.org/2001/SMIL20/Language\" xmlns:epub=\"http://www.idpf.org/2007/ops\">\n"
|
||||||
|
" <head>\n"
|
||||||
|
" <meta name=\"dc:title\" content=\"{title}\"/>\n"
|
||||||
|
" <meta name=\"dtb:uid\" content=\"{book_id}\"/>\n"
|
||||||
|
" <meta name=\"dtb:generator\" content=\"Abogen\"/>\n"
|
||||||
|
" </head>\n"
|
||||||
|
" <body>\n"
|
||||||
|
" <seq id=\"seq-{index:04d}\" epub:textref=\"text/{xhtml}\">\n"
|
||||||
|
"{pars}\n"
|
||||||
|
" </seq>\n"
|
||||||
|
" </body>\n"
|
||||||
|
"</smil>\n"
|
||||||
|
).format(
|
||||||
|
title=html.escape(chapter.title),
|
||||||
|
book_id=html.escape(self.book_id),
|
||||||
|
index=chapter.index + 1,
|
||||||
|
xhtml=html.escape(chapter.xhtml_name),
|
||||||
|
pars="\n".join(par_lines) if par_lines else " <par/>",
|
||||||
|
)
|
||||||
|
|
||||||
|
def _render_nav(self, chapters: Sequence[ChapterDocument]) -> str:
|
||||||
|
items = []
|
||||||
|
for chapter in chapters:
|
||||||
|
href = f"text/{chapter.xhtml_name}"
|
||||||
|
items.append(
|
||||||
|
" <li><a href=\"{href}\">{title}</a></li>".format(
|
||||||
|
href=html.escape(href),
|
||||||
|
title=html.escape(chapter.title),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
return (
|
||||||
|
"<?xml version=\"1.0\" encoding=\"utf-8\"?>\n"
|
||||||
|
"<html xmlns=\"http://www.w3.org/1999/xhtml\" xmlns:epub=\"http://www.idpf.org/2007/ops\" xml:lang=\"{lang}\">\n"
|
||||||
|
" <head>\n"
|
||||||
|
" <title>Navigation</title>\n"
|
||||||
|
" <meta charset=\"utf-8\"/>\n"
|
||||||
|
" </head>\n"
|
||||||
|
" <body>\n"
|
||||||
|
" <nav epub:type=\"toc\" id=\"toc\">\n"
|
||||||
|
" <h1>{title}</h1>\n"
|
||||||
|
" <ol>\n"
|
||||||
|
"{items}\n"
|
||||||
|
" </ol>\n"
|
||||||
|
" </nav>\n"
|
||||||
|
" </body>\n"
|
||||||
|
"</html>\n"
|
||||||
|
).format(
|
||||||
|
lang=html.escape(self._language or "en"),
|
||||||
|
title=html.escape(self._title),
|
||||||
|
items="\n".join(items) if items else " <li><a href=\"text/chapter_0001.xhtml\">Chapter 1</a></li>",
|
||||||
|
)
|
||||||
|
|
||||||
|
def _render_opf(
|
||||||
|
self,
|
||||||
|
chapters: Sequence[ChapterDocument],
|
||||||
|
audio_filename: str,
|
||||||
|
*,
|
||||||
|
has_cover: bool,
|
||||||
|
stylesheet_path: Path,
|
||||||
|
) -> str:
|
||||||
|
manifest_items = []
|
||||||
|
spine_refs = []
|
||||||
|
for chapter in chapters:
|
||||||
|
item_id = f"chap{chapter.index + 1:04d}"
|
||||||
|
overlay_id = f"mo-{chapter.index + 1:04d}"
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"{item_id}\" href=\"text/{href}\" media-type=\"application/xhtml+xml\" media-overlay=\"{overlay_id}\"/>".format(
|
||||||
|
item_id=item_id,
|
||||||
|
href=html.escape(chapter.xhtml_name),
|
||||||
|
overlay_id=overlay_id,
|
||||||
|
)
|
||||||
|
)
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"{overlay_id}\" href=\"smil/{smil}\" media-type=\"application/smil+xml\"/>".format(
|
||||||
|
overlay_id=overlay_id,
|
||||||
|
smil=html.escape(chapter.smil_name),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
spine_refs.append(f" <itemref idref=\"{item_id}\"/>")
|
||||||
|
|
||||||
|
audio_item_id = "primary-audio"
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"{item_id}\" href=\"audio/{href}\" media-type=\"{mime}\"/>".format(
|
||||||
|
item_id=audio_item_id,
|
||||||
|
href=html.escape(audio_filename),
|
||||||
|
mime=_detect_audio_mime(audio_filename),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"nav\" href=\"nav.xhtml\" media-type=\"application/xhtml+xml\" properties=\"nav\"/>"
|
||||||
|
)
|
||||||
|
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"style\" href=\"{href}\" media-type=\"text/css\"/>".format(
|
||||||
|
href=html.escape(str(stylesheet_path).replace("\\", "/")),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
if has_cover and self.cover_image_path:
|
||||||
|
cover_id = "cover-image"
|
||||||
|
manifest_items.append(
|
||||||
|
" <item id=\"{item_id}\" href=\"images/{href}\" media-type=\"{mime}\" properties=\"cover-image\"/>".format(
|
||||||
|
item_id=cover_id,
|
||||||
|
href=html.escape(self.cover_image_path.name),
|
||||||
|
mime=self.cover_image_mime or _detect_image_mime(self.cover_image_path.suffix),
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
metadata_elements = _render_metadata_xml(
|
||||||
|
self._title,
|
||||||
|
self._authors,
|
||||||
|
self._language,
|
||||||
|
self.book_id,
|
||||||
|
duration=self._duration,
|
||||||
|
publisher=self._publisher,
|
||||||
|
description=self._description,
|
||||||
|
speaker_mode=self.speaker_mode,
|
||||||
|
modified=self._modified,
|
||||||
|
)
|
||||||
|
|
||||||
|
return (
|
||||||
|
"<?xml version=\"1.0\" encoding=\"utf-8\"?>\n"
|
||||||
|
"<package xmlns=\"http://www.idpf.org/2007/opf\" version=\"3.0\" unique-identifier=\"book-id\">\n"
|
||||||
|
" <metadata xmlns:dc=\"http://purl.org/dc/elements/1.1/\" xmlns:opf=\"http://www.idpf.org/2007/opf\" xmlns:media=\"http://www.idpf.org/epub/vocab/mediaoverlays/#\" xmlns:abogen=\"https://abogen.app/ns#\" xmlns:dcterms=\"http://purl.org/dc/terms/\">\n"
|
||||||
|
"{metadata}\n"
|
||||||
|
" </metadata>\n"
|
||||||
|
" <manifest>\n"
|
||||||
|
"{manifest}\n"
|
||||||
|
" </manifest>\n"
|
||||||
|
" <spine>\n"
|
||||||
|
"{spine}\n"
|
||||||
|
" </spine>\n"
|
||||||
|
"</package>\n"
|
||||||
|
).format(
|
||||||
|
metadata="\n".join(metadata_elements),
|
||||||
|
manifest="\n".join(manifest_items),
|
||||||
|
spine="\n".join(spine_refs) if spine_refs else " <itemref idref=\"chap0001\"/>",
|
||||||
|
)
|
||||||
|
|
||||||
|
def _fallback_title(self) -> str:
|
||||||
|
if self.extraction.chapters:
|
||||||
|
first_title = self.extraction.chapters[0].title
|
||||||
|
if first_title:
|
||||||
|
return first_title
|
||||||
|
return "Generated Audiobook"
|
||||||
|
|
||||||
|
def _determine_language(self) -> str:
|
||||||
|
language = self._combined_metadata.get("language")
|
||||||
|
if language:
|
||||||
|
return language
|
||||||
|
return "en"
|
||||||
|
|
||||||
|
|
||||||
|
def build_epub3_package(
|
||||||
|
*,
|
||||||
|
output_path: Path,
|
||||||
|
book_id: str,
|
||||||
|
extraction: ExtractionResult,
|
||||||
|
metadata_tags: Dict[str, Any],
|
||||||
|
chapter_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunk_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunks: Iterable[Dict[str, Any]],
|
||||||
|
audio_path: Path,
|
||||||
|
speaker_mode: str = "single",
|
||||||
|
cover: "CoverConfig | None" = None,
|
||||||
|
cover_image_path: Optional[Path] = None,
|
||||||
|
cover_image_mime: Optional[str] = None,
|
||||||
|
) -> Path:
|
||||||
|
from abogen.domain.config_types import CoverConfig
|
||||||
|
if isinstance(cover, CoverConfig):
|
||||||
|
cover_image_path = cover.path
|
||||||
|
cover_image_mime = cover.mime
|
||||||
|
builder = EPUB3PackageBuilder(
|
||||||
|
output_path=output_path,
|
||||||
|
book_id=book_id,
|
||||||
|
extraction=extraction,
|
||||||
|
metadata_tags=metadata_tags,
|
||||||
|
chapter_markers=chapter_markers,
|
||||||
|
chunk_markers=chunk_markers,
|
||||||
|
chunks=chunks,
|
||||||
|
audio_path=audio_path,
|
||||||
|
speaker_mode=speaker_mode,
|
||||||
|
cover_image_path=cover_image_path,
|
||||||
|
cover_image_mime=cover_image_mime,
|
||||||
|
)
|
||||||
|
return builder.build()
|
||||||
|
|
||||||
|
|
||||||
|
# ---------------------------------------------------------------------------
|
||||||
|
# Helpers
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ChunkLookup:
|
||||||
|
by_id: Dict[str, Dict[str, Any]]
|
||||||
|
by_chapter: Dict[int, List[Dict[str, Any]]]
|
||||||
|
|
||||||
|
|
||||||
|
def _combine_metadata(*sources: Dict[str, Any]) -> Dict[str, str]:
|
||||||
|
combined: Dict[str, str] = {}
|
||||||
|
for source in sources:
|
||||||
|
for key, value in (source or {}).items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
combined[str(key).lower()] = str(value)
|
||||||
|
return combined
|
||||||
|
|
||||||
|
|
||||||
|
def _split_authors(metadata: Dict[str, str]) -> List[str]:
|
||||||
|
candidates = []
|
||||||
|
for key in ("artist", "author", "authors", "album_artist", "creator"):
|
||||||
|
value = metadata.get(key)
|
||||||
|
if value:
|
||||||
|
candidates.extend(part.strip() for part in value.replace(";", ",").split(","))
|
||||||
|
return [author for author in candidates if author]
|
||||||
|
|
||||||
|
|
||||||
|
def _calculate_total_duration(
|
||||||
|
chunk_markers: Sequence[Dict[str, Any]],
|
||||||
|
chapter_markers: Sequence[Dict[str, Any]],
|
||||||
|
) -> Optional[float]:
|
||||||
|
candidates: List[float] = []
|
||||||
|
for marker in chunk_markers or []:
|
||||||
|
end_value = _safe_float(marker.get("end"))
|
||||||
|
if end_value is not None:
|
||||||
|
candidates.append(end_value)
|
||||||
|
for marker in chapter_markers or []:
|
||||||
|
end_value = _safe_float(marker.get("end"))
|
||||||
|
if end_value is not None:
|
||||||
|
candidates.append(end_value)
|
||||||
|
if not candidates:
|
||||||
|
return None
|
||||||
|
return max(candidates)
|
||||||
|
|
||||||
|
|
||||||
|
def _write_mimetype(root: Path) -> None:
|
||||||
|
(root / "mimetype").write_text("application/epub+zip", encoding="utf-8")
|
||||||
|
|
||||||
|
|
||||||
|
def _write_container_xml(root: Path) -> None:
|
||||||
|
meta_inf = root / "META-INF"
|
||||||
|
meta_inf.mkdir(parents=True, exist_ok=True)
|
||||||
|
container = meta_inf / "container.xml"
|
||||||
|
container.write_text(
|
||||||
|
(
|
||||||
|
"<?xml version=\"1.0\" encoding=\"UTF-8\"?>\n"
|
||||||
|
"<container version=\"1.0\" xmlns=\"urn:oasis:names:tc:opendocument:xmlns:container\">\n"
|
||||||
|
" <rootfiles>\n"
|
||||||
|
" <rootfile full-path=\"OEBPS/content.opf\" media-type=\"application/oebps-package+xml\"/>\n"
|
||||||
|
" </rootfiles>\n"
|
||||||
|
"</container>\n"
|
||||||
|
),
|
||||||
|
encoding="utf-8",
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _build_chunk_lookup(chunks: Iterable[Dict[str, Any]]) -> ChunkLookup:
|
||||||
|
by_id: Dict[str, Dict[str, Any]] = {}
|
||||||
|
by_chapter: Dict[int, List[Dict[str, Any]]] = {}
|
||||||
|
for entry in chunks or []:
|
||||||
|
if not isinstance(entry, dict):
|
||||||
|
continue
|
||||||
|
chunk_id = entry.get("id")
|
||||||
|
if chunk_id:
|
||||||
|
by_id[str(chunk_id)] = dict(entry)
|
||||||
|
chapter_index = _safe_int(entry.get("chapter_index"))
|
||||||
|
by_chapter.setdefault(chapter_index, []).append(dict(entry))
|
||||||
|
return ChunkLookup(by_id=by_id, by_chapter=by_chapter)
|
||||||
|
|
||||||
|
|
||||||
|
def _group_markers_by_chapter(markers: Iterable[Dict[str, Any]]) -> Dict[int, List[Dict[str, Any]]]:
|
||||||
|
grouped: Dict[int, List[Dict[str, Any]]] = {}
|
||||||
|
for entry in markers or []:
|
||||||
|
if not isinstance(entry, dict):
|
||||||
|
continue
|
||||||
|
chapter_index = _safe_int(entry.get("chapter_index"))
|
||||||
|
grouped.setdefault(chapter_index, []).append(dict(entry))
|
||||||
|
for chapter_index, items in grouped.items():
|
||||||
|
items.sort(key=lambda payload: (_safe_int(payload.get("chunk_index")), _safe_float(payload.get("start")) or 0.0))
|
||||||
|
return grouped
|
||||||
|
|
||||||
|
|
||||||
|
def _find_chunk_by_index(
|
||||||
|
chapter_chunks: Sequence[Dict[str, Any]],
|
||||||
|
chunk_index: Optional[int],
|
||||||
|
) -> Optional[Dict[str, Any]]:
|
||||||
|
if chunk_index is None:
|
||||||
|
return None
|
||||||
|
for entry in chapter_chunks:
|
||||||
|
if _safe_int(entry.get("chunk_index")) == chunk_index:
|
||||||
|
return entry
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def _normalize_chunk_id(chunk_id: Optional[Any]) -> Optional[str]:
|
||||||
|
if chunk_id is None:
|
||||||
|
return None
|
||||||
|
text = str(chunk_id).strip()
|
||||||
|
if not text:
|
||||||
|
return None
|
||||||
|
safe = "".join(ch if ch.isalnum() or ch in {"_", "-"} else "_" for ch in text)
|
||||||
|
return safe[:120]
|
||||||
|
|
||||||
|
|
||||||
|
def _derive_group_id(chunk_id: Optional[Any], level: Optional[Any]) -> Optional[str]:
|
||||||
|
if chunk_id is None:
|
||||||
|
return None
|
||||||
|
text = str(chunk_id).strip()
|
||||||
|
if not text:
|
||||||
|
return None
|
||||||
|
if str(level or "").lower() == "sentence":
|
||||||
|
match = re.match(r"(.+?)_s\d+(?:_.*)?$", text)
|
||||||
|
if match:
|
||||||
|
return match.group(1)
|
||||||
|
return text
|
||||||
|
|
||||||
|
|
||||||
|
def _group_chunks_for_render(chunks: Sequence[ChunkOverlay]) -> List[Tuple[Optional[str], List[ChunkOverlay]]]:
|
||||||
|
groups: List[Tuple[Optional[str], List[ChunkOverlay]]] = []
|
||||||
|
current_key: Optional[str] = None
|
||||||
|
current_items: List[ChunkOverlay] = []
|
||||||
|
|
||||||
|
for chunk in chunks:
|
||||||
|
key = chunk.group_id or chunk.id
|
||||||
|
if current_items and key != current_key:
|
||||||
|
groups.append((current_key, current_items))
|
||||||
|
current_items = []
|
||||||
|
if not current_items:
|
||||||
|
current_key = key
|
||||||
|
current_items.append(chunk)
|
||||||
|
|
||||||
|
if current_items:
|
||||||
|
groups.append((current_key, current_items))
|
||||||
|
|
||||||
|
return groups
|
||||||
|
|
||||||
|
|
||||||
|
def _render_chunk_inline(chunk: ChunkOverlay) -> str:
|
||||||
|
escaped_id = html.escape(chunk.id)
|
||||||
|
speaker_attr = f" data-speaker=\"{html.escape(chunk.speaker_id)}\"" if chunk.speaker_id else ""
|
||||||
|
voice_str = None
|
||||||
|
if chunk.voice and isinstance(chunk.voice, dict):
|
||||||
|
name = chunk.voice.get("voice", "")
|
||||||
|
provider = chunk.voice.get("provider", "")
|
||||||
|
voice_str = f"{name}@{provider}" if name and provider else name or None
|
||||||
|
voice_attr = f" data-voice=\"{html.escape(voice_str)}\"" if voice_str else ""
|
||||||
|
level_attr = f" data-level=\"{html.escape(chunk.level)}\"" if chunk.level else ""
|
||||||
|
raw_text = chunk.text or ""
|
||||||
|
escaped_text = html.escape(raw_text)
|
||||||
|
if not escaped_text:
|
||||||
|
escaped_text = " "
|
||||||
|
return (
|
||||||
|
f"<span class=\"chunk\" id=\"{escaped_id}\"{speaker_attr}{voice_attr}{level_attr}>"
|
||||||
|
f"{escaped_text}"
|
||||||
|
"</span>"
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _render_chunk_group_html(group_id: Optional[str], chunks: Sequence[ChunkOverlay]) -> str:
|
||||||
|
if not chunks:
|
||||||
|
return ""
|
||||||
|
group_attr = f" data-group=\"{html.escape(group_id)}\"" if group_id else ""
|
||||||
|
inline_html = "".join(_render_chunk_inline(chunk) for chunk in chunks)
|
||||||
|
if not inline_html:
|
||||||
|
inline_html = " "
|
||||||
|
return f" <p class=\"chunk-group\"{group_attr}>{inline_html}</p>"
|
||||||
|
|
||||||
|
|
||||||
|
def _format_smil_time(value: Optional[float]) -> str:
|
||||||
|
if value is None or value < 0:
|
||||||
|
value = 0.0
|
||||||
|
total_ms = int(round(value * 1000))
|
||||||
|
hours, remainder = divmod(total_ms, 3600_000)
|
||||||
|
minutes, remainder = divmod(remainder, 60_000)
|
||||||
|
seconds, milliseconds = divmod(remainder, 1000)
|
||||||
|
return f"{hours:02d}:{minutes:02d}:{seconds:02d}.{milliseconds:03d}"
|
||||||
|
|
||||||
|
|
||||||
|
def _safe_int(value: Any, default: int = 0) -> int:
|
||||||
|
try:
|
||||||
|
return int(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _safe_float(value: Any) -> Optional[float]:
|
||||||
|
if value is None:
|
||||||
|
return None
|
||||||
|
try:
|
||||||
|
return float(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
def _restore_original_chunk_text(chapter_text: str, overlays: List[ChunkOverlay]) -> None:
|
||||||
|
if not chapter_text or not overlays:
|
||||||
|
return
|
||||||
|
|
||||||
|
cursor = 0
|
||||||
|
for chunk in overlays:
|
||||||
|
if chunk.original_text is not None:
|
||||||
|
prepared = _prepare_display_text(chunk.original_text)
|
||||||
|
chunk.text = prepared
|
||||||
|
continue
|
||||||
|
candidate = chunk.text or ""
|
||||||
|
if not candidate:
|
||||||
|
continue
|
||||||
|
match = _search_original_span(chapter_text, candidate, cursor)
|
||||||
|
if match is None and cursor:
|
||||||
|
match = _search_original_span(chapter_text, candidate, 0)
|
||||||
|
if match is None:
|
||||||
|
if chunk.original_text is None:
|
||||||
|
chunk.original_text = chunk.text
|
||||||
|
chunk.text = _prepare_display_text(chunk.text or "")
|
||||||
|
continue
|
||||||
|
start, end = match
|
||||||
|
segment = chapter_text[start:end]
|
||||||
|
chunk.original_text = segment
|
||||||
|
chunk.text = _prepare_display_text(segment)
|
||||||
|
cursor = end
|
||||||
|
|
||||||
|
|
||||||
|
def _prepare_display_text(value: str) -> str:
|
||||||
|
if not value:
|
||||||
|
return ""
|
||||||
|
cleaned = re.sub(r"(?:[ \t]*\r?\n)+\Z", "", value)
|
||||||
|
return cleaned if cleaned else ""
|
||||||
|
|
||||||
|
|
||||||
|
def _search_original_span(source: str, normalized: str, start: int) -> Optional[Tuple[int, int]]:
|
||||||
|
if not normalized:
|
||||||
|
return None
|
||||||
|
pattern = _build_chunk_pattern(normalized)
|
||||||
|
match = pattern.search(source, start)
|
||||||
|
if not match:
|
||||||
|
return None
|
||||||
|
return match.start(1), match.end(1)
|
||||||
|
|
||||||
|
|
||||||
|
_CHUNK_REGEX_CACHE: Dict[str, Pattern[str]] = {}
|
||||||
|
|
||||||
|
|
||||||
|
def _build_chunk_pattern(text: str) -> Pattern[str]:
|
||||||
|
cached = _CHUNK_REGEX_CACHE.get(text)
|
||||||
|
if cached is not None:
|
||||||
|
return cached
|
||||||
|
escaped = re.escape(text)
|
||||||
|
escaped = escaped.replace(r"\ ", r"\s+")
|
||||||
|
pattern = re.compile(r"(\s*" + escaped + r"\s*)", re.DOTALL)
|
||||||
|
_CHUNK_REGEX_CACHE[text] = pattern
|
||||||
|
return pattern
|
||||||
|
|
||||||
|
|
||||||
|
def _render_metadata_xml(
|
||||||
|
title: str,
|
||||||
|
authors: Sequence[str],
|
||||||
|
language: str,
|
||||||
|
book_id: str,
|
||||||
|
*,
|
||||||
|
duration: Optional[float],
|
||||||
|
publisher: Optional[str],
|
||||||
|
description: Optional[str],
|
||||||
|
speaker_mode: Optional[str],
|
||||||
|
modified: Optional[str],
|
||||||
|
) -> List[str]:
|
||||||
|
elements = [
|
||||||
|
f" <dc:identifier id=\"book-id\">{html.escape(book_id)}</dc:identifier>",
|
||||||
|
f" <dc:title>{html.escape(title)}</dc:title>",
|
||||||
|
f" <dc:language>{html.escape(language or 'en')}</dc:language>",
|
||||||
|
]
|
||||||
|
|
||||||
|
for author in authors or ["Unknown"]:
|
||||||
|
elements.append(f" <dc:creator>{html.escape(author)}</dc:creator>")
|
||||||
|
|
||||||
|
if publisher:
|
||||||
|
elements.append(f" <dc:publisher>{html.escape(publisher)}</dc:publisher>")
|
||||||
|
|
||||||
|
if description:
|
||||||
|
elements.append(f" <dc:description>{html.escape(description)}</dc:description>")
|
||||||
|
|
||||||
|
if duration is not None:
|
||||||
|
elements.append(f" <meta property=\"media:duration\">{_format_iso_duration(duration)}</meta>")
|
||||||
|
|
||||||
|
if speaker_mode:
|
||||||
|
elements.append(
|
||||||
|
" <meta property=\"abogen:speakerMode\">{}</meta>".format(
|
||||||
|
html.escape(str(speaker_mode))
|
||||||
|
)
|
||||||
|
)
|
||||||
|
|
||||||
|
if modified:
|
||||||
|
elements.append(f" <meta property=\"dcterms:modified\">{html.escape(modified)}</meta>")
|
||||||
|
return elements
|
||||||
|
|
||||||
|
|
||||||
|
def _format_iso_duration(value: float) -> str:
|
||||||
|
total_seconds = int(value)
|
||||||
|
remainder = value - total_seconds
|
||||||
|
hours, remainder_seconds = divmod(total_seconds, 3600)
|
||||||
|
minutes, seconds = divmod(remainder_seconds, 60)
|
||||||
|
seconds_with_fraction = seconds + remainder
|
||||||
|
if seconds_with_fraction.is_integer():
|
||||||
|
seconds_text = f"{int(seconds_with_fraction)}"
|
||||||
|
else:
|
||||||
|
seconds_text = f"{seconds_with_fraction:.3f}".rstrip("0").rstrip(".")
|
||||||
|
return f"PT{hours}H{minutes}M{seconds_text}S"
|
||||||
|
|
||||||
|
|
||||||
|
def _detect_audio_mime(audio_filename: str) -> str:
|
||||||
|
suffix = Path(audio_filename).suffix.lower()
|
||||||
|
return {
|
||||||
|
".mp3": "audio/mpeg",
|
||||||
|
".m4a": "audio/mp4",
|
||||||
|
".m4b": "audio/mp4",
|
||||||
|
".aac": "audio/aac",
|
||||||
|
".wav": "audio/wav",
|
||||||
|
".flac": "audio/flac",
|
||||||
|
".ogg": "audio/ogg",
|
||||||
|
".opus": "audio/ogg",
|
||||||
|
}.get(suffix, "audio/mpeg")
|
||||||
|
|
||||||
|
|
||||||
|
def _detect_image_mime(suffix: str) -> str:
|
||||||
|
normalized = suffix.lower()
|
||||||
|
return {
|
||||||
|
".jpg": "image/jpeg",
|
||||||
|
".jpeg": "image/jpeg",
|
||||||
|
".png": "image/png",
|
||||||
|
".gif": "image/gif",
|
||||||
|
".webp": "image/webp",
|
||||||
|
}.get(normalized, "image/jpeg")
|
||||||
|
|
||||||
|
|
||||||
|
def _utc_now_iso() -> str:
|
||||||
|
return datetime.now(timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
|
||||||
|
|
||||||
|
|
||||||
|
_DEFAULT_STYLESHEET = """
|
||||||
|
body {
|
||||||
|
font-family: 'Georgia', serif;
|
||||||
|
line-height: 1.6;
|
||||||
|
margin: 1.5em;
|
||||||
|
}
|
||||||
|
|
||||||
|
h1 {
|
||||||
|
font-size: 1.5em;
|
||||||
|
margin-bottom: 0.5em;
|
||||||
|
}
|
||||||
|
|
||||||
|
.chunk-group {
|
||||||
|
margin: 0.5em 0;
|
||||||
|
}
|
||||||
|
|
||||||
|
.chunk-group .chunk {
|
||||||
|
white-space: pre-wrap;
|
||||||
|
}
|
||||||
|
"""
|
||||||
+6
-3937
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,316 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import hashlib
|
||||||
|
import re
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional, Sequence, Tuple
|
||||||
|
|
||||||
|
_SPACY: Any = None
|
||||||
|
_SPACY_LOADED = False
|
||||||
|
|
||||||
|
|
||||||
|
def _get_spacy() -> Any:
|
||||||
|
"""Import spaCy lazily (it pulls in torch/thinc, ~2s at startup)."""
|
||||||
|
global _SPACY, _SPACY_LOADED
|
||||||
|
if not _SPACY_LOADED:
|
||||||
|
_SPACY_LOADED = True
|
||||||
|
try: # pragma: no cover - optional dependency
|
||||||
|
import spacy # type: ignore
|
||||||
|
except Exception: # pragma: no cover - spaCy may be unavailable in minimal environments
|
||||||
|
spacy = None
|
||||||
|
_SPACY = spacy
|
||||||
|
return _SPACY
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class HeteronymVariant:
|
||||||
|
key: str
|
||||||
|
label: str
|
||||||
|
replacement_token: str
|
||||||
|
example_sentence: str
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class HeteronymSpec:
|
||||||
|
token: str
|
||||||
|
variants: Tuple[HeteronymVariant, HeteronymVariant]
|
||||||
|
|
||||||
|
def default_choice_for_token(self, spacy_token: Any) -> str:
|
||||||
|
"""Return the most likely variant key for this token."""
|
||||||
|
pos = (getattr(spacy_token, "pos_", "") or "").upper()
|
||||||
|
tag = (getattr(spacy_token, "tag_", "") or "").upper()
|
||||||
|
|
||||||
|
token_lower = self.token.casefold()
|
||||||
|
if token_lower == "wind":
|
||||||
|
# VERB => /waɪnd/, NOUN => /wɪnd/
|
||||||
|
return "verb" if pos == "VERB" else "noun"
|
||||||
|
if token_lower == "read":
|
||||||
|
# VBD/VBN => /rɛd/
|
||||||
|
return "past" if tag in {"VBD", "VBN"} else "present"
|
||||||
|
if token_lower == "tear":
|
||||||
|
return "verb" if pos == "VERB" else "noun"
|
||||||
|
if token_lower == "close":
|
||||||
|
return "verb" if pos == "VERB" else "adj"
|
||||||
|
if token_lower == "lead":
|
||||||
|
# Default to verb unless POS suggests noun.
|
||||||
|
return "metal" if pos == "NOUN" else "verb"
|
||||||
|
return self.variants[0].key
|
||||||
|
|
||||||
|
|
||||||
|
# Minimal, high-confidence starter set.
|
||||||
|
# NOTE: These replacements intentionally prioritize speech output.
|
||||||
|
# Some replacements may not be appropriate for subtitles/text exports.
|
||||||
|
_HETERONYM_SPECS: Dict[str, HeteronymSpec] = {
|
||||||
|
"wind": HeteronymSpec(
|
||||||
|
token="wind",
|
||||||
|
variants=(
|
||||||
|
HeteronymVariant(
|
||||||
|
key="noun",
|
||||||
|
label="Noun (the wind)",
|
||||||
|
replacement_token="wind",
|
||||||
|
example_sentence="Listen to the wind.",
|
||||||
|
),
|
||||||
|
HeteronymVariant(
|
||||||
|
key="verb",
|
||||||
|
label="Verb (to wind)",
|
||||||
|
replacement_token="wynd",
|
||||||
|
example_sentence="I need to wind the watch.",
|
||||||
|
),
|
||||||
|
),
|
||||||
|
),
|
||||||
|
"read": HeteronymSpec(
|
||||||
|
token="read",
|
||||||
|
variants=(
|
||||||
|
HeteronymVariant(
|
||||||
|
key="present",
|
||||||
|
label="Present (I read every day)",
|
||||||
|
replacement_token="read",
|
||||||
|
example_sentence="I read every day.",
|
||||||
|
),
|
||||||
|
HeteronymVariant(
|
||||||
|
key="past",
|
||||||
|
label="Past (I read it yesterday)",
|
||||||
|
replacement_token="red",
|
||||||
|
example_sentence="I read it yesterday.",
|
||||||
|
),
|
||||||
|
),
|
||||||
|
),
|
||||||
|
"tear": HeteronymSpec(
|
||||||
|
token="tear",
|
||||||
|
variants=(
|
||||||
|
HeteronymVariant(
|
||||||
|
key="noun",
|
||||||
|
label="Noun (a tear /crying/)",
|
||||||
|
replacement_token="tier",
|
||||||
|
example_sentence="A tear rolled down her cheek.",
|
||||||
|
),
|
||||||
|
HeteronymVariant(
|
||||||
|
key="verb",
|
||||||
|
label="Verb (to tear /rip/)",
|
||||||
|
replacement_token="tear",
|
||||||
|
example_sentence="Please don't tear the page.",
|
||||||
|
),
|
||||||
|
),
|
||||||
|
),
|
||||||
|
"close": HeteronymSpec(
|
||||||
|
token="close",
|
||||||
|
variants=(
|
||||||
|
HeteronymVariant(
|
||||||
|
key="adj",
|
||||||
|
label="Adjective (close /near/)",
|
||||||
|
replacement_token="close",
|
||||||
|
example_sentence="We are close to the station.",
|
||||||
|
),
|
||||||
|
HeteronymVariant(
|
||||||
|
key="verb",
|
||||||
|
label="Verb (close /klohz/)",
|
||||||
|
replacement_token="cloze",
|
||||||
|
example_sentence="Please close the door.",
|
||||||
|
),
|
||||||
|
),
|
||||||
|
),
|
||||||
|
"lead": HeteronymSpec(
|
||||||
|
token="lead",
|
||||||
|
variants=(
|
||||||
|
HeteronymVariant(
|
||||||
|
key="verb",
|
||||||
|
label="Verb (to lead)",
|
||||||
|
replacement_token="lead",
|
||||||
|
example_sentence="They will lead the way.",
|
||||||
|
),
|
||||||
|
HeteronymVariant(
|
||||||
|
key="metal",
|
||||||
|
label="Noun (lead /metal/)",
|
||||||
|
replacement_token="led",
|
||||||
|
example_sentence="The pipe was made of lead.",
|
||||||
|
),
|
||||||
|
),
|
||||||
|
),
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def _hash_id(*parts: str) -> str:
|
||||||
|
digest = hashlib.sha1("\n".join(parts).encode("utf-8")).hexdigest()
|
||||||
|
return digest[:12]
|
||||||
|
|
||||||
|
|
||||||
|
_WORD_BOUNDARY_CACHE: Dict[str, re.Pattern[str]] = {}
|
||||||
|
|
||||||
|
|
||||||
|
def _word_boundary_pattern(token: str) -> re.Pattern[str]:
|
||||||
|
key = token.casefold()
|
||||||
|
cached = _WORD_BOUNDARY_CACHE.get(key)
|
||||||
|
if cached is not None:
|
||||||
|
return cached
|
||||||
|
escaped = re.escape(token)
|
||||||
|
pattern = re.compile(
|
||||||
|
rf"(?i)(?<!\w){escaped}(?P<possessive>'s|\u2019s|\u2019)?(?!\w)"
|
||||||
|
)
|
||||||
|
_WORD_BOUNDARY_CACHE[key] = pattern
|
||||||
|
return pattern
|
||||||
|
|
||||||
|
|
||||||
|
def _preserve_case(replacement: str, original: str) -> str:
|
||||||
|
if not replacement:
|
||||||
|
return replacement
|
||||||
|
if original.isupper():
|
||||||
|
return replacement.upper()
|
||||||
|
if original[:1].isupper():
|
||||||
|
return replacement[:1].upper() + replacement[1:]
|
||||||
|
return replacement
|
||||||
|
|
||||||
|
|
||||||
|
def _build_replacement_sentence(
|
||||||
|
sentence: str, token: str, replacement_token: str
|
||||||
|
) -> str:
|
||||||
|
pattern = _word_boundary_pattern(token)
|
||||||
|
|
||||||
|
def _repl(match: re.Match[str]) -> str:
|
||||||
|
matched = match.group(0) or ""
|
||||||
|
suffix = match.group("possessive") or ""
|
||||||
|
base = matched[: len(matched) - len(suffix)] if suffix else matched
|
||||||
|
return _preserve_case(replacement_token, base) + suffix
|
||||||
|
|
||||||
|
return pattern.sub(_repl, sentence)
|
||||||
|
|
||||||
|
|
||||||
|
def _load_spacy(language: str) -> Any:
|
||||||
|
spacy = _get_spacy()
|
||||||
|
if spacy is None:
|
||||||
|
return None
|
||||||
|
|
||||||
|
# English only for now.
|
||||||
|
# Use installed small model; keep it simple.
|
||||||
|
lang = (language or "en").lower()
|
||||||
|
if lang.startswith("en"):
|
||||||
|
try:
|
||||||
|
return spacy.load("en_core_web_sm")
|
||||||
|
except Exception:
|
||||||
|
return spacy.blank("en")
|
||||||
|
return spacy.blank("xx")
|
||||||
|
|
||||||
|
|
||||||
|
def extract_heteronym_overrides(
|
||||||
|
chapters: Sequence[Mapping[str, Any]],
|
||||||
|
*,
|
||||||
|
language: str,
|
||||||
|
existing: Optional[Iterable[Mapping[str, Any]]] = None,
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
"""Extract distinct heteronym-containing sentences from chapters.
|
||||||
|
|
||||||
|
Returns entries shaped for persistence + UI.
|
||||||
|
|
||||||
|
Each entry contains:
|
||||||
|
- id
|
||||||
|
- token
|
||||||
|
- sentence
|
||||||
|
- options: [{key,label,replacement_token,replacement_sentence,example_sentence}]
|
||||||
|
- default_choice
|
||||||
|
- choice
|
||||||
|
"""
|
||||||
|
|
||||||
|
lang = (language or "en").lower()
|
||||||
|
if not lang.startswith("en"):
|
||||||
|
return []
|
||||||
|
|
||||||
|
if _get_spacy() is None:
|
||||||
|
return []
|
||||||
|
|
||||||
|
nlp = _load_spacy(lang)
|
||||||
|
if nlp is None:
|
||||||
|
return []
|
||||||
|
|
||||||
|
previous_choices: Dict[str, str] = {}
|
||||||
|
if existing:
|
||||||
|
for item in existing:
|
||||||
|
if not isinstance(item, Mapping):
|
||||||
|
continue
|
||||||
|
entry_id = str(item.get("id") or "").strip()
|
||||||
|
choice = str(item.get("choice") or "").strip()
|
||||||
|
if entry_id and choice:
|
||||||
|
previous_choices[entry_id] = choice
|
||||||
|
|
||||||
|
results: List[Dict[str, Any]] = []
|
||||||
|
seen: set[tuple[str, str]] = set()
|
||||||
|
|
||||||
|
for chapter in chapters:
|
||||||
|
if not isinstance(chapter, Mapping):
|
||||||
|
continue
|
||||||
|
text = str(chapter.get("text") or "")
|
||||||
|
if not text.strip():
|
||||||
|
continue
|
||||||
|
|
||||||
|
doc = nlp(text)
|
||||||
|
for sent in getattr(doc, "sents", []):
|
||||||
|
sentence = str(getattr(sent, "text", "") or "").strip()
|
||||||
|
if not sentence:
|
||||||
|
continue
|
||||||
|
|
||||||
|
for token in sent:
|
||||||
|
token_text = str(getattr(token, "text", "") or "")
|
||||||
|
if not token_text:
|
||||||
|
continue
|
||||||
|
token_key = token_text.casefold()
|
||||||
|
spec = _HETERONYM_SPECS.get(token_key)
|
||||||
|
if not spec:
|
||||||
|
continue
|
||||||
|
|
||||||
|
dedupe_key = (token_key, sentence)
|
||||||
|
if dedupe_key in seen:
|
||||||
|
continue
|
||||||
|
seen.add(dedupe_key)
|
||||||
|
|
||||||
|
entry_id = _hash_id(token_key, sentence)
|
||||||
|
default_choice = spec.default_choice_for_token(token)
|
||||||
|
choice = previous_choices.get(entry_id, default_choice)
|
||||||
|
|
||||||
|
options: List[Dict[str, Any]] = []
|
||||||
|
for variant in spec.variants:
|
||||||
|
replacement_sentence = _build_replacement_sentence(
|
||||||
|
sentence,
|
||||||
|
token=spec.token,
|
||||||
|
replacement_token=variant.replacement_token,
|
||||||
|
)
|
||||||
|
options.append(
|
||||||
|
{
|
||||||
|
"key": variant.key,
|
||||||
|
"label": variant.label,
|
||||||
|
"replacement_token": variant.replacement_token,
|
||||||
|
"replacement_sentence": replacement_sentence,
|
||||||
|
"example_sentence": variant.example_sentence,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
results.append(
|
||||||
|
{
|
||||||
|
"id": entry_id,
|
||||||
|
"token": token_text,
|
||||||
|
"token_lower": token_key,
|
||||||
|
"sentence": sentence,
|
||||||
|
"options": options,
|
||||||
|
"default_choice": default_choice,
|
||||||
|
"choice": choice,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
|
||||||
|
return results
|
||||||
@@ -19,7 +19,7 @@ def tracked_hf_hub_download(*args, **kwargs):
|
|||||||
try:
|
try:
|
||||||
local_kwargs = dict(kwargs)
|
local_kwargs = dict(kwargs)
|
||||||
local_kwargs["local_files_only"] = True
|
local_kwargs["local_files_only"] = True
|
||||||
hf_hub_download(*args, **local_kwargs)
|
return hf_hub_download(*args, **local_kwargs)
|
||||||
except Exception:
|
except Exception:
|
||||||
repo_id = kwargs.get("repo_id", "<unknown repo>")
|
repo_id = kwargs.get("repo_id", "<unknown repo>")
|
||||||
filename = kwargs.get("filename", "<unknown file>")
|
filename = kwargs.get("filename", "<unknown file>")
|
||||||
|
|||||||
@@ -0,0 +1,324 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import json
|
||||||
|
import logging
|
||||||
|
import tempfile
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, List, Optional, Mapping, Sequence
|
||||||
|
|
||||||
|
import static_ffmpeg
|
||||||
|
|
||||||
|
from abogen.domain.metadata_helpers import (
|
||||||
|
split_people_field,
|
||||||
|
split_simple_list,
|
||||||
|
first_nonempty,
|
||||||
|
extract_year,
|
||||||
|
normalize_series_sequence,
|
||||||
|
_SERIES_SEQUENCE_TAG_KEYS,
|
||||||
|
)
|
||||||
|
from abogen.epub3.exporter import build_epub3_package
|
||||||
|
from abogen.utils import create_process
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class ExportConfig:
|
||||||
|
"""Configuration for export operations."""
|
||||||
|
ffmpeg_path: str = "ffmpeg"
|
||||||
|
verify_ssl: bool = True
|
||||||
|
|
||||||
|
|
||||||
|
class ExportService:
|
||||||
|
"""Unified service for audiobook exports (M4B, FFMETADATA, EPUB3, Audiobookshelf)."""
|
||||||
|
|
||||||
|
def __init__(self, config: Optional[ExportConfig] = None):
|
||||||
|
self.config = config or ExportConfig()
|
||||||
|
static_ffmpeg.add_paths()
|
||||||
|
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
# FFMETADATA
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
|
||||||
|
def render_ffmetadata(
|
||||||
|
self,
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
) -> str:
|
||||||
|
"""Render FFMETADATA content."""
|
||||||
|
lines = [";FFMETADATA1"]
|
||||||
|
|
||||||
|
for key, value in (metadata or {}).items():
|
||||||
|
if value is None:
|
||||||
|
continue
|
||||||
|
key_str = str(key).strip()
|
||||||
|
if not key_str:
|
||||||
|
continue
|
||||||
|
lines.append(f"{key_str}={self._escape_ffmetadata_value(value)}")
|
||||||
|
|
||||||
|
for chapter in chapters or []:
|
||||||
|
start = chapter.get("start")
|
||||||
|
end = chapter.get("end")
|
||||||
|
if start is None or end is None:
|
||||||
|
continue
|
||||||
|
try:
|
||||||
|
start_ms = max(0, int(round(float(start) * 1000)))
|
||||||
|
end_ms = int(round(float(end) * 1000))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
continue
|
||||||
|
if end_ms <= start_ms:
|
||||||
|
end_ms = start_ms + 1
|
||||||
|
lines.append("[CHAPTER]")
|
||||||
|
lines.append("TIMEBASE=1/1000")
|
||||||
|
lines.append(f"START={start_ms}")
|
||||||
|
lines.append(f"END={end_ms}")
|
||||||
|
title = chapter.get("title")
|
||||||
|
if title:
|
||||||
|
lines.append(f"title={self._escape_ffmetadata_value(title)}")
|
||||||
|
voices = chapter.get("voices")
|
||||||
|
if voices and isinstance(voices, list):
|
||||||
|
voice_str = ", ".join(
|
||||||
|
f"{v.get('voice', '')}@{v.get('provider', '')}"
|
||||||
|
for v in voices if v.get("voice")
|
||||||
|
)
|
||||||
|
if voice_str:
|
||||||
|
lines.append(f"voice={self._escape_ffmetadata_value(voice_str)}")
|
||||||
|
|
||||||
|
return "\n".join(lines) + "\n"
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _escape_ffmetadata_value(value: Any) -> str:
|
||||||
|
escaped = str(value).replace("\\", "\\\\").replace("\n", "\\n")
|
||||||
|
escaped = escaped.replace("=", "\\=").replace(";", "\\;").replace("#", "\\#")
|
||||||
|
return escaped
|
||||||
|
|
||||||
|
def write_ffmetadata_file(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
) -> Optional[Path]:
|
||||||
|
"""Write FFMETADATA file to temp location."""
|
||||||
|
content = self.render_ffmetadata(metadata, chapters)
|
||||||
|
if content.strip() == ";FFMETADATA1":
|
||||||
|
return None
|
||||||
|
|
||||||
|
directory = audio_path.parent if audio_path.parent.exists() else Path(tempfile.gettempdir())
|
||||||
|
with tempfile.NamedTemporaryFile(
|
||||||
|
mode="w",
|
||||||
|
encoding="utf-8",
|
||||||
|
suffix=".ffmeta",
|
||||||
|
delete=False,
|
||||||
|
dir=str(directory),
|
||||||
|
) as handle:
|
||||||
|
handle.write(content)
|
||||||
|
return Path(handle.name)
|
||||||
|
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
# M4B Export
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
|
||||||
|
def embed_m4b_metadata(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
cover: "CoverConfig | None" = None,
|
||||||
|
cover_path: Optional[Path] = None,
|
||||||
|
cover_mime: Optional[str] = None,
|
||||||
|
log_callback: Optional[callable] = None,
|
||||||
|
) -> None:
|
||||||
|
"""Embed metadata and chapters into M4B file using FFmpeg + Mutagen."""
|
||||||
|
from abogen.domain.config_types import CoverConfig
|
||||||
|
if isinstance(cover, CoverConfig):
|
||||||
|
cover_path = cover.path
|
||||||
|
cover_mime = cover.mime
|
||||||
|
ffmetadata_path = self.write_ffmetadata_file(audio_path, metadata, chapters)
|
||||||
|
|
||||||
|
metadata_args = self._metadata_to_ffmpeg_args(metadata)
|
||||||
|
|
||||||
|
cmd = ["ffmpeg", "-y", "-i", str(audio_path)]
|
||||||
|
|
||||||
|
if ffmetadata_path:
|
||||||
|
cmd.extend(["-f", "ffmetadata", "-i", str(ffmetadata_path)])
|
||||||
|
|
||||||
|
if cover_path and cover_path.exists():
|
||||||
|
cmd.extend(["-i", str(cover_path)])
|
||||||
|
cmd.extend(["-map", "0:a"])
|
||||||
|
cmd.extend(["-map", "1:v:0", "-c:v:0", "mjpeg", "-disposition:v:0", "attached_pic"])
|
||||||
|
if cover_mime:
|
||||||
|
cmd.extend(["-metadata:s:v:0", f"mimetype={cover_mime}"])
|
||||||
|
cmd.extend(["-metadata:s:v:0", "title=Cover Art"])
|
||||||
|
else:
|
||||||
|
cmd.extend(["-map", "0:a"])
|
||||||
|
|
||||||
|
cmd.extend(["-c:a", "copy"])
|
||||||
|
|
||||||
|
if ffmetadata_path:
|
||||||
|
cmd.extend(["-map_metadata", "1", "-map_chapters", "1"])
|
||||||
|
else:
|
||||||
|
cmd.extend(["-map_metadata", "0"])
|
||||||
|
|
||||||
|
if metadata_args:
|
||||||
|
cmd.extend(metadata_args)
|
||||||
|
|
||||||
|
cmd.extend(["-movflags", "+faststart+use_metadata_tags"])
|
||||||
|
|
||||||
|
temp_output = audio_path.with_suffix(audio_path.suffix + ".tmp")
|
||||||
|
if audio_path.suffix.lower() in {".m4b", ".mp4", ".m4a"}:
|
||||||
|
cmd.extend(["-f", "mp4"])
|
||||||
|
cmd.append(str(temp_output))
|
||||||
|
|
||||||
|
if log_callback:
|
||||||
|
log_callback("Embedding metadata into M4B output")
|
||||||
|
|
||||||
|
process = create_process(cmd, text=True)
|
||||||
|
return_code = process.wait()
|
||||||
|
|
||||||
|
if ffmetadata_path and ffmetadata_path.exists():
|
||||||
|
try:
|
||||||
|
ffmetadata_path.unlink()
|
||||||
|
except OSError:
|
||||||
|
pass
|
||||||
|
|
||||||
|
if return_code != 0:
|
||||||
|
if temp_output.exists():
|
||||||
|
temp_output.unlink(missing_ok=True)
|
||||||
|
raise RuntimeError(f"ffmpeg failed to embed metadata (exit code {return_code})")
|
||||||
|
|
||||||
|
temp_output.replace(audio_path)
|
||||||
|
|
||||||
|
if log_callback:
|
||||||
|
log_callback("Embedded metadata and chapters into M4B output", "info")
|
||||||
|
|
||||||
|
# Apply chapters via Mutagen for better compatibility
|
||||||
|
self._apply_m4b_chapters_mutagen(audio_path, chapters, log_callback)
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _metadata_to_ffmpeg_args(metadata: Dict[str, Any]) -> List[str]:
|
||||||
|
args = []
|
||||||
|
for key, value in (metadata or {}).items():
|
||||||
|
if value in (None, ""):
|
||||||
|
continue
|
||||||
|
key_str = str(key).strip()
|
||||||
|
if not key_str:
|
||||||
|
continue
|
||||||
|
normalized_key = key_str.lower()
|
||||||
|
if normalized_key == "year":
|
||||||
|
ffmpeg_key = "date"
|
||||||
|
else:
|
||||||
|
ffmpeg_key = key_str
|
||||||
|
args.extend(["-metadata", f"{ffmpeg_key}={value}"])
|
||||||
|
return args
|
||||||
|
|
||||||
|
def _apply_m4b_chapters_mutagen(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
chapters: List[Dict[str, Any]],
|
||||||
|
log_callback: Optional[callable] = None,
|
||||||
|
) -> bool:
|
||||||
|
"""Apply chapter atoms using Mutagen."""
|
||||||
|
if not chapters:
|
||||||
|
return False
|
||||||
|
|
||||||
|
try:
|
||||||
|
from fractions import Fraction
|
||||||
|
from mutagen.mp4 import MP4, MP4Chapter
|
||||||
|
except ImportError:
|
||||||
|
if log_callback:
|
||||||
|
log_callback("Unable to write MP4 chapter atoms because mutagen is not installed.", "warning")
|
||||||
|
return False
|
||||||
|
|
||||||
|
try:
|
||||||
|
mp4 = MP4(str(audio_path))
|
||||||
|
except Exception as exc:
|
||||||
|
if log_callback:
|
||||||
|
log_callback(f"Failed to open m4b for chapter embedding: {exc}", "warning")
|
||||||
|
return False
|
||||||
|
|
||||||
|
chapter_objects = []
|
||||||
|
for index, entry in enumerate(sorted(chapters, key=lambda item: float(item.get("start") or 0.0))):
|
||||||
|
start_raw = entry.get("start")
|
||||||
|
if start_raw is None:
|
||||||
|
continue
|
||||||
|
try:
|
||||||
|
start_seconds = max(0.0, float(start_raw))
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
continue
|
||||||
|
|
||||||
|
title_value = entry.get("title")
|
||||||
|
title_text = str(title_value) if title_value else f"Chapter {index + 1}"
|
||||||
|
|
||||||
|
start_fraction = Fraction(int(round(start_seconds * 1000)), 1000)
|
||||||
|
chapter_atom = MP4Chapter(start_fraction, title_text)
|
||||||
|
|
||||||
|
end_raw = entry.get("end")
|
||||||
|
if end_raw is not None:
|
||||||
|
try:
|
||||||
|
end_seconds = float(end_raw)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
end_seconds = None
|
||||||
|
if end_seconds is not None and end_seconds > start_seconds:
|
||||||
|
chapter_atom.end = Fraction(int(round(end_seconds * 1000)), 1000)
|
||||||
|
|
||||||
|
chapter_objects.append(chapter_atom)
|
||||||
|
|
||||||
|
if not chapter_objects:
|
||||||
|
return False
|
||||||
|
|
||||||
|
try:
|
||||||
|
mp4.chapters = chapter_objects
|
||||||
|
mp4.save()
|
||||||
|
except Exception as exc:
|
||||||
|
if log_callback:
|
||||||
|
log_callback(f"Failed to persist MP4 chapter atoms: {exc}", "warning")
|
||||||
|
return False
|
||||||
|
|
||||||
|
if log_callback:
|
||||||
|
log_callback(f"Applied {len(chapter_objects)} chapter markers via mutagen", "info")
|
||||||
|
return True
|
||||||
|
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
# EPUB3 Export
|
||||||
|
# ----------------------------------------------------------------------
|
||||||
|
|
||||||
|
def export_epub3(
|
||||||
|
self,
|
||||||
|
output_path: Path,
|
||||||
|
book_id: str,
|
||||||
|
extraction: Any, # ExtractionResult
|
||||||
|
metadata_tags: Dict[str, Any],
|
||||||
|
chapter_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunk_markers: Sequence[Dict[str, Any]],
|
||||||
|
chunks: Iterable[Dict[str, Any]],
|
||||||
|
audio_path: Path,
|
||||||
|
speaker_mode: str = "single",
|
||||||
|
cover_path: Optional[Path] = None,
|
||||||
|
cover_mime: Optional[str] = None,
|
||||||
|
) -> Path:
|
||||||
|
"""Export EPUB3 with media overlays."""
|
||||||
|
return build_epub3_package(
|
||||||
|
output_path=output_path,
|
||||||
|
book_id=book_id,
|
||||||
|
extraction=extraction,
|
||||||
|
metadata_tags=metadata_tags,
|
||||||
|
chapter_markers=chapter_markers,
|
||||||
|
chunk_markers=chunk_markers,
|
||||||
|
chunks=chunks,
|
||||||
|
audio_path=audio_path,
|
||||||
|
speaker_mode=speaker_mode,
|
||||||
|
cover_image_path=cover_path,
|
||||||
|
cover_image_mime=cover_mime,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
if value is None:
|
||||||
|
return default
|
||||||
|
return bool(value)
|
||||||
|
|
||||||
|
|
||||||
|
__all__ = [
|
||||||
|
"ExportConfig",
|
||||||
|
"ExportService",
|
||||||
|
]
|
||||||
@@ -0,0 +1,374 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
from abc import ABC, abstractmethod
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from enum import Enum
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import List, Optional, TextIO
|
||||||
|
|
||||||
|
from abogen.domain.enums import SubtitleFormat, SubtitleMode
|
||||||
|
from abogen.subtitle_utils import clean_subtitle_text
|
||||||
|
|
||||||
|
|
||||||
|
class SubtitleAlignment(Enum):
|
||||||
|
LEFT = "left"
|
||||||
|
CENTER = "center"
|
||||||
|
NARROW = "narrow"
|
||||||
|
CENTER_NARROW = "center_narrow"
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class SubtitleConfig:
|
||||||
|
"""Configuration for subtitle writer."""
|
||||||
|
format: SubtitleFormat
|
||||||
|
mode: SubtitleMode
|
||||||
|
alignment: SubtitleAlignment = SubtitleAlignment.LEFT
|
||||||
|
max_words: int = 50
|
||||||
|
highlight_color: str = "&H00FFFF00" # ASS highlight color
|
||||||
|
|
||||||
|
|
||||||
|
class SubtitleWriter(ABC):
|
||||||
|
"""Abstract base class for subtitle writers."""
|
||||||
|
|
||||||
|
def __init__(self, path: Path, config: SubtitleConfig):
|
||||||
|
self.path = path
|
||||||
|
self.config = config
|
||||||
|
self._file: Optional[TextIO] = None
|
||||||
|
self._index = 0
|
||||||
|
self._opened = False
|
||||||
|
|
||||||
|
def open(self) -> None:
|
||||||
|
"""Open the subtitle file and write header."""
|
||||||
|
if self._opened:
|
||||||
|
return
|
||||||
|
self._file = open(self.path, "w", encoding="utf-8", errors="replace")
|
||||||
|
self._write_header()
|
||||||
|
self._opened = True
|
||||||
|
|
||||||
|
@abstractmethod
|
||||||
|
def _write_header(self) -> None:
|
||||||
|
pass
|
||||||
|
|
||||||
|
def write_entry(
|
||||||
|
self,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
text: str,
|
||||||
|
voice: Optional[str] = None,
|
||||||
|
) -> None:
|
||||||
|
"""Write a subtitle entry."""
|
||||||
|
if not self._opened:
|
||||||
|
self.open()
|
||||||
|
|
||||||
|
text = clean_subtitle_text(text)
|
||||||
|
if not text:
|
||||||
|
return
|
||||||
|
|
||||||
|
self._index += 1
|
||||||
|
self._write_entry(self._index, start, end, text, voice)
|
||||||
|
|
||||||
|
@abstractmethod
|
||||||
|
def _write_entry(
|
||||||
|
self,
|
||||||
|
index: int,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
text: str,
|
||||||
|
voice: Optional[str],
|
||||||
|
) -> None:
|
||||||
|
pass
|
||||||
|
|
||||||
|
def close(self) -> None:
|
||||||
|
"""Close the subtitle file."""
|
||||||
|
if self._file:
|
||||||
|
self._file.close()
|
||||||
|
self._file = None
|
||||||
|
self._opened = False
|
||||||
|
|
||||||
|
def __enter__(self) -> "SubtitleWriter":
|
||||||
|
self.open()
|
||||||
|
return self
|
||||||
|
|
||||||
|
def __exit__(self, exc_type, exc_val, exc_tb) -> None:
|
||||||
|
self.close()
|
||||||
|
|
||||||
|
|
||||||
|
class SrtWriter(SubtitleWriter):
|
||||||
|
"""SRT subtitle writer."""
|
||||||
|
|
||||||
|
def _write_header(self) -> None:
|
||||||
|
pass # SRT has no header
|
||||||
|
|
||||||
|
def _write_entry(
|
||||||
|
self,
|
||||||
|
index: int,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
text: str,
|
||||||
|
voice: Optional[str],
|
||||||
|
) -> None:
|
||||||
|
start_str = self._format_time(start)
|
||||||
|
end_str = self._format_time(end)
|
||||||
|
|
||||||
|
if voice:
|
||||||
|
text = f"[{voice}] {text}"
|
||||||
|
|
||||||
|
self._file.write(f"{index}\n")
|
||||||
|
self._file.write(f"{start_str} --> {end_str}\n")
|
||||||
|
self._file.write(f"{text}\n\n")
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _format_time(seconds: float) -> str:
|
||||||
|
hours = int(seconds // 3600)
|
||||||
|
minutes = int((seconds % 3600) // 60)
|
||||||
|
secs = int(seconds % 60)
|
||||||
|
millis = int((seconds - int(seconds)) * 1000)
|
||||||
|
return f"{hours:02d}:{minutes:02d}:{secs:02d},{millis:03d}"
|
||||||
|
|
||||||
|
|
||||||
|
class VttWriter(SubtitleWriter):
|
||||||
|
"""WebVTT subtitle writer."""
|
||||||
|
|
||||||
|
def _write_header(self) -> None:
|
||||||
|
self._file.write("WEBVTT\n\n")
|
||||||
|
|
||||||
|
def _write_entry(
|
||||||
|
self,
|
||||||
|
index: int,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
text: str,
|
||||||
|
voice: Optional[str],
|
||||||
|
) -> None:
|
||||||
|
start_str = self._format_time(start)
|
||||||
|
end_str = self._format_time(end)
|
||||||
|
|
||||||
|
if voice:
|
||||||
|
text = f"[{voice}] {text}"
|
||||||
|
|
||||||
|
self._file.write(f"{index}\n")
|
||||||
|
self._file.write(f"{start_str} --> {end_str}\n")
|
||||||
|
self._file.write(f"{text}\n\n")
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _format_time(seconds: float) -> str:
|
||||||
|
hours = int(seconds // 3600)
|
||||||
|
minutes = int((seconds % 3600) // 60)
|
||||||
|
secs = seconds % 60
|
||||||
|
return f"{hours:02d}:{minutes:02d}:{secs:06.3f}".replace(".", ".")
|
||||||
|
|
||||||
|
|
||||||
|
class AssWriter(SubtitleWriter):
|
||||||
|
"""ASS subtitle writer with karaoke highlighting support."""
|
||||||
|
|
||||||
|
def __init__(self, path: Path, config: SubtitleConfig):
|
||||||
|
super().__init__(path, config)
|
||||||
|
self._is_centered = config.alignment in (SubtitleAlignment.CENTER, SubtitleAlignment.CENTER_NARROW)
|
||||||
|
self._is_narrow = config.alignment in (SubtitleAlignment.NARROW, SubtitleAlignment.CENTER_NARROW)
|
||||||
|
|
||||||
|
def _write_header(self) -> None:
|
||||||
|
margin = "90" if self._is_narrow else "10"
|
||||||
|
alignment = "5" if self._is_centered else "2"
|
||||||
|
|
||||||
|
self._file.write("[Script Info]\n")
|
||||||
|
self._file.write("Title: Generated by Abogen\n")
|
||||||
|
self._file.write("ScriptType: v4.00+\n\n")
|
||||||
|
|
||||||
|
# Styles
|
||||||
|
self._file.write("[V4+ Styles]\n")
|
||||||
|
self._file.write(
|
||||||
|
"Format: Name, Fontname, Fontsize, PrimaryColour, SecondaryColour, "
|
||||||
|
"OutlineColour, BackColour, Bold, Italic, Underline, StrikeOut, "
|
||||||
|
"ScaleX, ScaleY, Spacing, Angle, BorderStyle, Outline, Shadow, "
|
||||||
|
"Alignment, MarginL, MarginR, MarginV, Encoding\n"
|
||||||
|
)
|
||||||
|
|
||||||
|
if self.config.mode == SubtitleMode.SENTENCE_HIGHLIGHT:
|
||||||
|
# Karaoke style with highlighting
|
||||||
|
self._file.write(
|
||||||
|
f"Style: Default,Arial,24,&H00FFFFFF,&H00808080,&H00000000,&H00404040,"
|
||||||
|
f"0,0,0,0,100,100,0,0,3,2,0,{alignment},{margin},{margin},10,1\n"
|
||||||
|
)
|
||||||
|
self._file.write(
|
||||||
|
f"Style: Highlight,Arial,24,&H0000FFFF,&H00808080,&H00000000,&H00404040,"
|
||||||
|
f"0,0,0,0,100,100,0,0,3,2,0,{alignment},{margin},{margin},10,1\n\n"
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
self._file.write(
|
||||||
|
f"Style: Default,Arial,24,&H00FFFFFF,&H00808080,&H00000000,&H00404040,"
|
||||||
|
f"0,0,0,0,100,100,0,0,3,2,0,{alignment},{margin},{margin},10,1\n\n"
|
||||||
|
)
|
||||||
|
|
||||||
|
self._file.write("[Events]\n")
|
||||||
|
self._file.write(
|
||||||
|
"Format: Layer, Start, End, Style, Name, MarginL, MarginR, MarginV, Effect, Text\n"
|
||||||
|
)
|
||||||
|
|
||||||
|
def _write_entry(
|
||||||
|
self,
|
||||||
|
index: int,
|
||||||
|
start: float,
|
||||||
|
end: float,
|
||||||
|
text: str,
|
||||||
|
voice: Optional[str],
|
||||||
|
) -> None:
|
||||||
|
start_str = self._format_time(start)
|
||||||
|
end_str = self._format_time(end)
|
||||||
|
|
||||||
|
if voice:
|
||||||
|
text = f"[{voice}] {text}"
|
||||||
|
|
||||||
|
style = "Default"
|
||||||
|
if self.config.mode == SubtitleMode.SENTENCE_HIGHLIGHT:
|
||||||
|
# Add karaoke tags for highlighting
|
||||||
|
text = self._add_karaoke_tags(text)
|
||||||
|
style = "Highlight"
|
||||||
|
|
||||||
|
alignment_tag = r"{\an5}" if self._is_centered else ""
|
||||||
|
self._file.write(
|
||||||
|
f"Dialogue: 0,{start_str},{end_str},{style},,0,0,0,,{alignment_tag}{text}\n"
|
||||||
|
)
|
||||||
|
|
||||||
|
def _add_karaoke_tags(self, text: str) -> str:
|
||||||
|
"""Add karaoke highlighting tags to text."""
|
||||||
|
# Simple word-level karaoke timing
|
||||||
|
words = text.split()
|
||||||
|
if not words:
|
||||||
|
return text
|
||||||
|
|
||||||
|
# This is a simplified version - real karaoke needs per-word timing
|
||||||
|
# For now, just return the text with the highlight color
|
||||||
|
return r"{\k100}" + r"{\k100}".join(words) + r"{\k0}"
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _format_time(seconds: float) -> str:
|
||||||
|
hours = int(seconds // 3600)
|
||||||
|
minutes = int((seconds % 3600) // 60)
|
||||||
|
secs = seconds % 60
|
||||||
|
return f"{hours}:{minutes:02d}:{secs:05.2f}"
|
||||||
|
|
||||||
|
|
||||||
|
def create_subtitle_writer(
|
||||||
|
path: Path,
|
||||||
|
format: str,
|
||||||
|
mode: str,
|
||||||
|
alignment: str = "left",
|
||||||
|
max_words: int = 50,
|
||||||
|
) -> SubtitleWriter:
|
||||||
|
"""Factory function to create subtitle writer."""
|
||||||
|
fmt = SubtitleFormat(format.lower())
|
||||||
|
mode = SubtitleMode(mode)
|
||||||
|
align = SubtitleAlignment(alignment.lower())
|
||||||
|
|
||||||
|
config = SubtitleConfig(
|
||||||
|
format=fmt,
|
||||||
|
mode=mode,
|
||||||
|
alignment=align,
|
||||||
|
max_words=max_words,
|
||||||
|
)
|
||||||
|
|
||||||
|
if fmt == SubtitleFormat.SRT:
|
||||||
|
return SrtWriter(path, config)
|
||||||
|
elif fmt == SubtitleFormat.VTT:
|
||||||
|
return VttWriter(path, config)
|
||||||
|
elif fmt == SubtitleFormat.ASS:
|
||||||
|
return AssWriter(path, config)
|
||||||
|
else:
|
||||||
|
raise ValueError(f"Unsupported subtitle format: {format}")
|
||||||
|
|
||||||
|
|
||||||
|
def resolve_subtitle_format(
|
||||||
|
subtitle: "SubtitleConfig | str | None",
|
||||||
|
subtitle_mode: str | None = None,
|
||||||
|
) -> tuple[str, str]:
|
||||||
|
"""Resolve a subtitle config to (file_extension, alignment).
|
||||||
|
|
||||||
|
Accepts a SubtitleConfig object or individual format/mode strings
|
||||||
|
for backward compatibility.
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
Tuple of (file_extension, alignment) suitable for
|
||||||
|
:func:`create_subtitle_writer`.
|
||||||
|
"""
|
||||||
|
from abogen.domain.config_types import SubtitleConfig
|
||||||
|
|
||||||
|
if isinstance(subtitle, SubtitleConfig):
|
||||||
|
fmt = subtitle.format.value.lower()
|
||||||
|
mode_str = subtitle.mode.value
|
||||||
|
else:
|
||||||
|
fmt = (subtitle or "srt").lower()
|
||||||
|
mode_str = subtitle_mode or "Disabled"
|
||||||
|
|
||||||
|
if mode_str == "Sentence + Highlighting" and fmt == "srt":
|
||||||
|
fmt = "ass"
|
||||||
|
|
||||||
|
if "ass" in fmt:
|
||||||
|
extension = "ass"
|
||||||
|
if "centered_narrow" in fmt:
|
||||||
|
alignment = "center_narrow"
|
||||||
|
elif "centered" in fmt:
|
||||||
|
alignment = "center"
|
||||||
|
elif "narrow" in fmt:
|
||||||
|
alignment = "narrow"
|
||||||
|
else:
|
||||||
|
alignment = "left"
|
||||||
|
else:
|
||||||
|
extension = fmt if fmt in ("srt", "vtt") else "srt"
|
||||||
|
alignment = "left"
|
||||||
|
|
||||||
|
return extension, alignment
|
||||||
|
|
||||||
|
|
||||||
|
def make_subtitle_writer(
|
||||||
|
audio_path: Path,
|
||||||
|
subtitle: "SubtitleConfig | str | None",
|
||||||
|
subtitle_mode: str | None = None,
|
||||||
|
max_words: int | None = None,
|
||||||
|
) -> SubtitleWriter | None:
|
||||||
|
"""Convenience: resolve format and create a writer, or return None if disabled.
|
||||||
|
|
||||||
|
Accepts a SubtitleConfig object or individual format/mode strings
|
||||||
|
for backward compatibility.
|
||||||
|
|
||||||
|
Returns ``None`` when subtitle mode is ``"Disabled"`` or the
|
||||||
|
format is unsupported.
|
||||||
|
"""
|
||||||
|
from abogen.domain.config_types import SubtitleConfig
|
||||||
|
|
||||||
|
if isinstance(subtitle, SubtitleConfig):
|
||||||
|
mode_str = subtitle.mode.value
|
||||||
|
if mode_str == "Disabled":
|
||||||
|
return None
|
||||||
|
words = subtitle.max_words
|
||||||
|
else:
|
||||||
|
mode_str = subtitle_mode or subtitle or "Disabled"
|
||||||
|
if mode_str == "Disabled":
|
||||||
|
return None
|
||||||
|
words = max_words or 50
|
||||||
|
|
||||||
|
extension, alignment = resolve_subtitle_format(subtitle, subtitle_mode)
|
||||||
|
try:
|
||||||
|
return create_subtitle_writer(
|
||||||
|
audio_path.with_suffix(f".{extension}"),
|
||||||
|
extension,
|
||||||
|
mode_str,
|
||||||
|
alignment=alignment,
|
||||||
|
max_words=words,
|
||||||
|
)
|
||||||
|
except (ValueError, KeyError):
|
||||||
|
return None
|
||||||
|
|
||||||
|
|
||||||
|
__all__ = [
|
||||||
|
"SubtitleFormat",
|
||||||
|
"SubtitleMode",
|
||||||
|
"SubtitleAlignment",
|
||||||
|
"SubtitleConfig",
|
||||||
|
"SubtitleWriter",
|
||||||
|
"SrtWriter",
|
||||||
|
"VttWriter",
|
||||||
|
"AssWriter",
|
||||||
|
"create_subtitle_writer",
|
||||||
|
"resolve_subtitle_format",
|
||||||
|
"make_subtitle_writer",
|
||||||
|
]
|
||||||
@@ -0,0 +1 @@
|
|||||||
|
"""Integration clients for external services."""
|
||||||
@@ -0,0 +1,647 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import json
|
||||||
|
import logging
|
||||||
|
import mimetypes
|
||||||
|
from contextlib import ExitStack
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional, Sequence, Tuple
|
||||||
|
|
||||||
|
import httpx
|
||||||
|
|
||||||
|
from abogen.domain.metadata_helpers import normalize_series_sequence
|
||||||
|
|
||||||
|
logger = logging.getLogger(__name__)
|
||||||
|
|
||||||
|
|
||||||
|
class AudiobookshelfUploadError(RuntimeError):
|
||||||
|
"""Raised when an upload to Audiobookshelf fails."""
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class AudiobookshelfConfig:
|
||||||
|
base_url: str
|
||||||
|
api_token: str
|
||||||
|
library_id: Optional[str] = None
|
||||||
|
collection_id: Optional[str] = None
|
||||||
|
folder_id: Optional[str] = None
|
||||||
|
verify_ssl: bool = True
|
||||||
|
send_cover: bool = True
|
||||||
|
send_chapters: bool = True
|
||||||
|
send_subtitles: bool = True
|
||||||
|
timeout: float = 3600.0
|
||||||
|
|
||||||
|
def normalized_base_url(self) -> str:
|
||||||
|
base = (self.base_url or "").strip()
|
||||||
|
if not base:
|
||||||
|
raise ValueError("Audiobookshelf base URL is required")
|
||||||
|
normalized = base.rstrip("/")
|
||||||
|
# The web UI historically suggested including '/api' in the base URL; trim
|
||||||
|
# it here so we can safely append `/api/...` endpoints below.
|
||||||
|
if normalized.lower().endswith("/api"):
|
||||||
|
normalized = normalized[:-4]
|
||||||
|
return normalized or base
|
||||||
|
|
||||||
|
|
||||||
|
class AudiobookshelfClient:
|
||||||
|
"""Client for the legacy Audiobookshelf multipart upload endpoint."""
|
||||||
|
|
||||||
|
def __init__(self, config: AudiobookshelfConfig) -> None:
|
||||||
|
if not config.api_token:
|
||||||
|
raise ValueError("Audiobookshelf API token is required")
|
||||||
|
# library_id is now optional for discovery
|
||||||
|
self._config = config
|
||||||
|
normalized = config.normalized_base_url() or ""
|
||||||
|
self._base_url = normalized.rstrip("/") or normalized
|
||||||
|
self._client_base_url = f"{self._base_url}/"
|
||||||
|
self._folder_cache: Optional[Tuple[str, str, str]] = None
|
||||||
|
|
||||||
|
def get_libraries(self) -> List[Dict[str, Any]]:
|
||||||
|
"""Fetch all libraries from the Audiobookshelf server."""
|
||||||
|
route = self._api_path("libraries")
|
||||||
|
try:
|
||||||
|
with self._open_client() as client:
|
||||||
|
response = client.get(route)
|
||||||
|
response.raise_for_status()
|
||||||
|
data = response.json()
|
||||||
|
# data['libraries'] is a list of library objects
|
||||||
|
return data.get("libraries", [])
|
||||||
|
except httpx.HTTPError as exc:
|
||||||
|
raise AudiobookshelfUploadError(f"Failed to fetch libraries: {exc}") from exc
|
||||||
|
|
||||||
|
def _api_path(self, suffix: str = "") -> str:
|
||||||
|
"""Join the API prefix with the provided suffix without losing proxies."""
|
||||||
|
clean_suffix = suffix.lstrip("/")
|
||||||
|
return f"api/{clean_suffix}" if clean_suffix else "api"
|
||||||
|
|
||||||
|
def upload_audiobook(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
*,
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
cover_path: Optional[Path] = None,
|
||||||
|
chapters: Optional[Iterable[Dict[str, Any]]] = None,
|
||||||
|
subtitles: Optional[Iterable[Path]] = None,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
if not audio_path.exists():
|
||||||
|
raise AudiobookshelfUploadError(f"Audio path does not exist: {audio_path}")
|
||||||
|
|
||||||
|
form_fields = self._build_upload_fields(audio_path, metadata, chapters)
|
||||||
|
file_entries = self._build_file_entries(audio_path, cover_path, subtitles)
|
||||||
|
|
||||||
|
route = self._api_path("upload")
|
||||||
|
try:
|
||||||
|
with self._open_client() as client, ExitStack() as stack:
|
||||||
|
files_payload = self._open_file_handles(file_entries, stack)
|
||||||
|
response = client.post(route, data=form_fields, files=files_payload)
|
||||||
|
response.raise_for_status()
|
||||||
|
except httpx.HTTPStatusError as exc:
|
||||||
|
status = exc.response.status_code
|
||||||
|
detail = (exc.response.text or "").strip()
|
||||||
|
if detail:
|
||||||
|
detail = detail[:200]
|
||||||
|
message = f"Audiobookshelf upload failed with status {status}: {detail}"
|
||||||
|
else:
|
||||||
|
message = f"Audiobookshelf upload failed with status {status}"
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
message
|
||||||
|
) from exc
|
||||||
|
except httpx.HTTPError as exc:
|
||||||
|
raise AudiobookshelfUploadError(f"Audiobookshelf upload failed: {exc}") from exc
|
||||||
|
|
||||||
|
return {}
|
||||||
|
|
||||||
|
def _open_client(self) -> httpx.Client:
|
||||||
|
headers = {
|
||||||
|
"Authorization": f"Bearer {self._config.api_token}",
|
||||||
|
"Accept": "application/json",
|
||||||
|
}
|
||||||
|
return httpx.Client(
|
||||||
|
base_url=self._client_base_url,
|
||||||
|
headers=headers,
|
||||||
|
timeout=self._config.timeout,
|
||||||
|
verify=self._config.verify_ssl,
|
||||||
|
)
|
||||||
|
|
||||||
|
def _build_upload_fields(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
metadata: Dict[str, Any],
|
||||||
|
chapters: Optional[Iterable[Dict[str, Any]]],
|
||||||
|
) -> Dict[str, str]:
|
||||||
|
folder_id, _, _ = self._ensure_folder()
|
||||||
|
title = self._extract_title(metadata, audio_path)
|
||||||
|
author = self._extract_author(metadata)
|
||||||
|
series = self._extract_series(metadata)
|
||||||
|
series_sequence = self._extract_series_sequence(metadata)
|
||||||
|
|
||||||
|
fields: Dict[str, str] = {
|
||||||
|
"library": self._config.library_id,
|
||||||
|
"folder": folder_id,
|
||||||
|
"title": title,
|
||||||
|
}
|
||||||
|
if author:
|
||||||
|
fields["author"] = author
|
||||||
|
if series:
|
||||||
|
fields["series"] = series
|
||||||
|
if series_sequence:
|
||||||
|
fields["seriesSequence"] = series_sequence
|
||||||
|
if self._config.collection_id:
|
||||||
|
fields["collectionId"] = self._config.collection_id
|
||||||
|
|
||||||
|
metadata_payload: Dict[str, Any] = metadata or {}
|
||||||
|
if chapters and self._config.send_chapters:
|
||||||
|
metadata_payload = dict(metadata_payload)
|
||||||
|
metadata_payload["chapters"] = list(chapters)
|
||||||
|
|
||||||
|
if metadata_payload:
|
||||||
|
# Ensure authors is a list of strings in the JSON payload if it exists
|
||||||
|
if "authors" in metadata_payload:
|
||||||
|
authors_val = metadata_payload["authors"]
|
||||||
|
if isinstance(authors_val, str):
|
||||||
|
metadata_payload["authors"] = [a.strip() for a in authors_val.split(",") if a.strip()]
|
||||||
|
elif isinstance(authors_val, list):
|
||||||
|
metadata_payload["authors"] = [str(a).strip() for a in authors_val if str(a).strip()]
|
||||||
|
|
||||||
|
try:
|
||||||
|
fields["metadata"] = json.dumps(metadata_payload, ensure_ascii=False)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
logger.debug("Failed to serialize Audiobookshelf metadata payload")
|
||||||
|
|
||||||
|
return fields
|
||||||
|
|
||||||
|
def _build_file_entries(
|
||||||
|
self,
|
||||||
|
audio_path: Path,
|
||||||
|
cover_path: Optional[Path],
|
||||||
|
subtitles: Optional[Iterable[Path]],
|
||||||
|
) -> List[Tuple[str, Path]]:
|
||||||
|
entries: List[Tuple[str, Path]] = [("file0", audio_path)]
|
||||||
|
index = 1
|
||||||
|
|
||||||
|
if cover_path and self._config.send_cover and cover_path.exists():
|
||||||
|
entries.append((f"file{index}", cover_path))
|
||||||
|
index += 1
|
||||||
|
|
||||||
|
if subtitles and self._config.send_subtitles:
|
||||||
|
for subtitle in subtitles:
|
||||||
|
if subtitle.exists():
|
||||||
|
entries.append((f"file{index}", subtitle))
|
||||||
|
index += 1
|
||||||
|
|
||||||
|
return entries
|
||||||
|
|
||||||
|
def _open_file_handles(
|
||||||
|
self,
|
||||||
|
entries: Sequence[Tuple[str, Path]],
|
||||||
|
stack: ExitStack,
|
||||||
|
) -> List[Tuple[str, Tuple[str, Any, str]]]:
|
||||||
|
files: List[Tuple[str, Tuple[str, Any, str]]] = []
|
||||||
|
for field_name, path in entries:
|
||||||
|
mime_type, _ = mimetypes.guess_type(path.name)
|
||||||
|
mime_type = mime_type or "application/octet-stream"
|
||||||
|
handle = stack.enter_context(path.open("rb"))
|
||||||
|
files.append((field_name, (path.name, handle, mime_type)))
|
||||||
|
return files
|
||||||
|
|
||||||
|
def find_existing_items(
|
||||||
|
self,
|
||||||
|
title: str,
|
||||||
|
*,
|
||||||
|
folder_id: Optional[str] = None,
|
||||||
|
) -> List[Mapping[str, Any]]:
|
||||||
|
normalized_title = self._normalize_title_value(title)
|
||||||
|
if not normalized_title:
|
||||||
|
return []
|
||||||
|
|
||||||
|
folder_hint = folder_id or self._config.folder_id
|
||||||
|
target_folders = set()
|
||||||
|
if folder_hint:
|
||||||
|
folder_token = str(folder_hint).strip().lower()
|
||||||
|
if folder_token:
|
||||||
|
target_folders.add(folder_token)
|
||||||
|
|
||||||
|
requests = self._candidate_search_requests(title, folder_hint)
|
||||||
|
if not requests:
|
||||||
|
return []
|
||||||
|
|
||||||
|
matches: List[Mapping[str, Any]] = []
|
||||||
|
|
||||||
|
try:
|
||||||
|
with self._open_client() as client:
|
||||||
|
for route, params in requests:
|
||||||
|
try:
|
||||||
|
response = client.get(route, params=params)
|
||||||
|
except httpx.HTTPError as exc:
|
||||||
|
logger.debug("Audiobookshelf lookup failed for %s: %s", route, exc)
|
||||||
|
continue
|
||||||
|
|
||||||
|
if response.status_code == 404:
|
||||||
|
continue
|
||||||
|
|
||||||
|
try:
|
||||||
|
response.raise_for_status()
|
||||||
|
except httpx.HTTPStatusError as exc:
|
||||||
|
status = exc.response.status_code
|
||||||
|
if status in {401, 403}:
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
"Audiobookshelf authentication failed while checking for existing items."
|
||||||
|
) from exc
|
||||||
|
logger.debug("Audiobookshelf lookup error %s for %s", status, route)
|
||||||
|
continue
|
||||||
|
|
||||||
|
try:
|
||||||
|
payload = response.json()
|
||||||
|
except ValueError:
|
||||||
|
continue
|
||||||
|
|
||||||
|
candidates = self._extract_candidate_items(payload)
|
||||||
|
for item in candidates:
|
||||||
|
item_title = self._normalize_item_title(item)
|
||||||
|
if not item_title or item_title != normalized_title:
|
||||||
|
continue
|
||||||
|
if target_folders:
|
||||||
|
item_folder = self._normalize_folder_id(item)
|
||||||
|
if item_folder and item_folder not in target_folders:
|
||||||
|
continue
|
||||||
|
matches.append(item)
|
||||||
|
if matches:
|
||||||
|
break
|
||||||
|
except AudiobookshelfUploadError:
|
||||||
|
raise
|
||||||
|
except Exception:
|
||||||
|
logger.debug(
|
||||||
|
"Unexpected error while checking Audiobookshelf for existing items",
|
||||||
|
exc_info=True,
|
||||||
|
)
|
||||||
|
|
||||||
|
return matches
|
||||||
|
|
||||||
|
def delete_items(self, items: Iterable[Mapping[str, Any] | str]) -> None:
|
||||||
|
to_delete: List[str] = []
|
||||||
|
for entry in items:
|
||||||
|
if isinstance(entry, Mapping):
|
||||||
|
item_id = self._extract_item_id(entry)
|
||||||
|
else:
|
||||||
|
item_id = str(entry).strip()
|
||||||
|
if item_id:
|
||||||
|
to_delete.append(item_id)
|
||||||
|
|
||||||
|
if not to_delete:
|
||||||
|
return
|
||||||
|
|
||||||
|
with self._open_client() as client:
|
||||||
|
for item_id in to_delete:
|
||||||
|
self._delete_single_item(client, item_id)
|
||||||
|
|
||||||
|
def _candidate_search_requests(
|
||||||
|
self,
|
||||||
|
title: str,
|
||||||
|
folder_id: Optional[str],
|
||||||
|
) -> List[Tuple[str, Dict[str, Any]]]:
|
||||||
|
query = (title or "").strip()
|
||||||
|
if not query:
|
||||||
|
return []
|
||||||
|
|
||||||
|
library_id = self._config.library_id
|
||||||
|
folder_token = (folder_id or self._config.folder_id or "").strip()
|
||||||
|
|
||||||
|
requests: List[Tuple[str, Dict[str, Any]]] = []
|
||||||
|
seen_routes: set[str] = set()
|
||||||
|
|
||||||
|
def _append(route: str, params: Dict[str, Any]) -> None:
|
||||||
|
if route in seen_routes:
|
||||||
|
return
|
||||||
|
seen_routes.add(route)
|
||||||
|
requests.append((route, params))
|
||||||
|
|
||||||
|
if folder_token:
|
||||||
|
_append(
|
||||||
|
self._api_path(f"folders/{folder_token}/items"),
|
||||||
|
{"library": library_id, "search": query},
|
||||||
|
)
|
||||||
|
|
||||||
|
_append(self._api_path(f"libraries/{library_id}/items"), {"search": query})
|
||||||
|
_append(self._api_path("items"), {"library": library_id, "search": query})
|
||||||
|
_append(
|
||||||
|
self._api_path("search"),
|
||||||
|
{"query": query, "library": library_id, "media": "audiobook"},
|
||||||
|
)
|
||||||
|
|
||||||
|
return requests
|
||||||
|
|
||||||
|
def _delete_single_item(self, client: httpx.Client, item_id: str) -> None:
|
||||||
|
routes = [
|
||||||
|
self._api_path(f"items/{item_id}"),
|
||||||
|
self._api_path(f"libraries/{self._config.library_id}/items/{item_id}"),
|
||||||
|
]
|
||||||
|
|
||||||
|
for route in routes:
|
||||||
|
try:
|
||||||
|
response = client.delete(route)
|
||||||
|
except httpx.HTTPError as exc:
|
||||||
|
logger.debug("Audiobookshelf delete failed for %s: %s", route, exc)
|
||||||
|
continue
|
||||||
|
|
||||||
|
if response.status_code in (200, 202, 204):
|
||||||
|
return
|
||||||
|
if response.status_code == 404:
|
||||||
|
continue
|
||||||
|
|
||||||
|
try:
|
||||||
|
response.raise_for_status()
|
||||||
|
except httpx.HTTPStatusError as exc:
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
f"Failed to delete Audiobookshelf item '{item_id}': {exc}"
|
||||||
|
) from exc
|
||||||
|
|
||||||
|
logger.debug("Audiobookshelf item %s could not be confirmed deleted", item_id)
|
||||||
|
|
||||||
|
def resolve_folder(self) -> Tuple[str, str, str]:
|
||||||
|
"""Return the resolved folder (id, name, library name)."""
|
||||||
|
return self._ensure_folder()
|
||||||
|
|
||||||
|
def list_folders(self) -> List[Dict[str, str]]:
|
||||||
|
"""Return all folders for the configured library."""
|
||||||
|
library_name, folders = self._load_library_metadata()
|
||||||
|
results: List[Dict[str, str]] = []
|
||||||
|
for folder in folders:
|
||||||
|
folder_id = str(folder.get("id") or "").strip()
|
||||||
|
if not folder_id:
|
||||||
|
continue
|
||||||
|
name = self._folder_display_name(folder)
|
||||||
|
path = self._select_folder_path(folder)
|
||||||
|
results.append(
|
||||||
|
{
|
||||||
|
"id": folder_id,
|
||||||
|
"name": name,
|
||||||
|
"path": path,
|
||||||
|
"library": library_name,
|
||||||
|
}
|
||||||
|
)
|
||||||
|
results.sort(key=lambda entry: (entry.get("path") or entry.get("name") or entry.get("id") or "").lower())
|
||||||
|
return results
|
||||||
|
|
||||||
|
def _ensure_folder(self) -> Tuple[str, str, str]:
|
||||||
|
if self._folder_cache:
|
||||||
|
return self._folder_cache
|
||||||
|
|
||||||
|
identifier = (self._config.folder_id or "").strip()
|
||||||
|
if not identifier:
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
"Audiobookshelf folder is required; enter the folder name or ID in Settings."
|
||||||
|
)
|
||||||
|
|
||||||
|
identifier_norm = self._normalize_identifier(identifier)
|
||||||
|
library_name, folders = self._load_library_metadata()
|
||||||
|
|
||||||
|
# direct ID match
|
||||||
|
for folder in folders:
|
||||||
|
folder_id = str(folder.get("id") or "").strip()
|
||||||
|
if folder_id and folder_id == identifier:
|
||||||
|
folder_name = self._folder_display_name(folder) or folder_id
|
||||||
|
self._folder_cache = (folder_id, folder_name, library_name)
|
||||||
|
return self._folder_cache
|
||||||
|
|
||||||
|
has_path_component = "/" in identifier_norm
|
||||||
|
|
||||||
|
for folder in folders:
|
||||||
|
folder_id = str(folder.get("id") or "").strip()
|
||||||
|
if not folder_id:
|
||||||
|
continue
|
||||||
|
folder_name = self._folder_display_name(folder)
|
||||||
|
name_norm = self._normalize_identifier(folder_name)
|
||||||
|
if name_norm and name_norm == identifier_norm:
|
||||||
|
self._folder_cache = (folder_id, folder_name or folder_id, library_name)
|
||||||
|
return self._folder_cache
|
||||||
|
|
||||||
|
for candidate in self._folder_path_candidates(folder):
|
||||||
|
candidate_norm = self._normalize_identifier(candidate)
|
||||||
|
if not candidate_norm:
|
||||||
|
continue
|
||||||
|
if candidate_norm == identifier_norm:
|
||||||
|
self._folder_cache = (folder_id, folder_name or folder_id, library_name)
|
||||||
|
return self._folder_cache
|
||||||
|
if has_path_component and candidate_norm.endswith(identifier_norm):
|
||||||
|
self._folder_cache = (folder_id, folder_name or folder_id, library_name)
|
||||||
|
return self._folder_cache
|
||||||
|
if not has_path_component:
|
||||||
|
tail = candidate_norm.split("/")[-1]
|
||||||
|
if tail and tail == identifier_norm:
|
||||||
|
self._folder_cache = (folder_id, folder_name or folder_id, library_name)
|
||||||
|
return self._folder_cache
|
||||||
|
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
f"Folder '{identifier}' was not found in library '{library_name}'. "
|
||||||
|
"Enter the folder name exactly as it appears in Audiobookshelf, a trailing path segment, or paste the folder ID."
|
||||||
|
)
|
||||||
|
|
||||||
|
def _load_library_metadata(self) -> Tuple[str, List[Mapping[str, Any]]]:
|
||||||
|
try:
|
||||||
|
with self._open_client() as client:
|
||||||
|
response = client.get(self._api_path(f"libraries/{self._config.library_id}"))
|
||||||
|
response.raise_for_status()
|
||||||
|
payload = response.json()
|
||||||
|
except httpx.HTTPStatusError as exc:
|
||||||
|
status = exc.response.status_code
|
||||||
|
if status == 404:
|
||||||
|
message = f"Audiobookshelf library '{self._config.library_id}' not found."
|
||||||
|
else:
|
||||||
|
detail = (exc.response.text or "").strip()
|
||||||
|
if detail:
|
||||||
|
detail = detail[:200]
|
||||||
|
message = (
|
||||||
|
f"Failed to load Audiobookshelf library '{self._config.library_id}' "
|
||||||
|
f"(status {status}): {detail}"
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
message = (
|
||||||
|
f"Failed to load Audiobookshelf library '{self._config.library_id}' "
|
||||||
|
f"(status {status})."
|
||||||
|
)
|
||||||
|
raise AudiobookshelfUploadError(message) from exc
|
||||||
|
except httpx.HTTPError as exc:
|
||||||
|
raise AudiobookshelfUploadError(
|
||||||
|
f"Failed to reach Audiobookshelf library '{self._config.library_id}': {exc}"
|
||||||
|
) from exc
|
||||||
|
|
||||||
|
if not isinstance(payload, Mapping):
|
||||||
|
return self._config.library_id, []
|
||||||
|
|
||||||
|
library_name = str(payload.get("name") or payload.get("label") or self._config.library_id)
|
||||||
|
raw_folders = payload.get("libraryFolders") or payload.get("folders") or []
|
||||||
|
folders = [entry for entry in raw_folders if isinstance(entry, Mapping)]
|
||||||
|
return library_name, folders
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _folder_path_candidates(folder: Mapping[str, Any]) -> List[str]:
|
||||||
|
candidates: List[str] = []
|
||||||
|
for key in ("fullPath", "fullpath", "path", "folderPath", "virtualPath"):
|
||||||
|
value = folder.get(key)
|
||||||
|
if isinstance(value, str) and value.strip():
|
||||||
|
candidates.append(value)
|
||||||
|
return candidates
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _folder_display_name(folder: Mapping[str, Any]) -> str:
|
||||||
|
name = str(folder.get("name") or folder.get("label") or "").strip()
|
||||||
|
if name:
|
||||||
|
return name
|
||||||
|
path = AudiobookshelfClient._select_folder_path(folder)
|
||||||
|
if path:
|
||||||
|
tail = path.strip("/ ")
|
||||||
|
tail = tail.split("/")[-1] if tail else ""
|
||||||
|
if tail:
|
||||||
|
return tail
|
||||||
|
return str(folder.get("id") or "").strip()
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _select_folder_path(folder: Mapping[str, Any]) -> str:
|
||||||
|
for candidate in AudiobookshelfClient._folder_path_candidates(folder):
|
||||||
|
normalized = candidate.replace("\\", "/").strip()
|
||||||
|
if normalized:
|
||||||
|
return normalized
|
||||||
|
return ""
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _normalize_identifier(value: str) -> str:
|
||||||
|
token = (value or "").strip()
|
||||||
|
token = token.replace("\\", "/")
|
||||||
|
if len(token) > 1 and token[1] == ":":
|
||||||
|
token = token[2:]
|
||||||
|
token = token.strip("/ ")
|
||||||
|
return token.lower()
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _normalize_title_value(value: Optional[str]) -> str:
|
||||||
|
if not isinstance(value, str):
|
||||||
|
return ""
|
||||||
|
normalized = re.sub(r"\s+", " ", value).strip()
|
||||||
|
return normalized.casefold() if normalized else ""
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _normalize_item_title(item: Mapping[str, Any]) -> str:
|
||||||
|
if not isinstance(item, Mapping):
|
||||||
|
return ""
|
||||||
|
for key in ("title", "name", "label"):
|
||||||
|
candidate = item.get(key)
|
||||||
|
if isinstance(candidate, str) and candidate.strip():
|
||||||
|
return AudiobookshelfClient._normalize_title_value(candidate)
|
||||||
|
library_item = item.get("libraryItem")
|
||||||
|
if isinstance(library_item, Mapping):
|
||||||
|
return AudiobookshelfClient._normalize_item_title(library_item)
|
||||||
|
return ""
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _normalize_folder_id(item: Mapping[str, Any]) -> Optional[str]:
|
||||||
|
if not isinstance(item, Mapping):
|
||||||
|
return None
|
||||||
|
for key in ("folderId", "libraryFolderId", "folder_id", "folder"):
|
||||||
|
value = item.get(key)
|
||||||
|
if isinstance(value, str) and value.strip():
|
||||||
|
return value.strip().lower()
|
||||||
|
if isinstance(value, (int, float)):
|
||||||
|
return str(value).strip().lower()
|
||||||
|
library_item = item.get("libraryItem")
|
||||||
|
if isinstance(library_item, Mapping):
|
||||||
|
return AudiobookshelfClient._normalize_folder_id(library_item)
|
||||||
|
return None
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_item_id(item: Mapping[str, Any]) -> Optional[str]:
|
||||||
|
if not isinstance(item, Mapping):
|
||||||
|
return None
|
||||||
|
for key in ("id", "libraryItemId", "itemId"):
|
||||||
|
value = item.get(key)
|
||||||
|
if isinstance(value, str) and value.strip():
|
||||||
|
return value.strip()
|
||||||
|
if isinstance(value, (int, float)):
|
||||||
|
return str(value).strip()
|
||||||
|
library_item = item.get("libraryItem")
|
||||||
|
if isinstance(library_item, Mapping):
|
||||||
|
return AudiobookshelfClient._extract_item_id(library_item)
|
||||||
|
return None
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_candidate_items(payload: Any) -> List[Mapping[str, Any]]:
|
||||||
|
items: List[Mapping[str, Any]] = []
|
||||||
|
seen_ids: set[str] = set()
|
||||||
|
visited: set[int] = set()
|
||||||
|
|
||||||
|
def _visit(obj: Any) -> None:
|
||||||
|
if isinstance(obj, Mapping):
|
||||||
|
obj_id = id(obj)
|
||||||
|
if obj_id in visited:
|
||||||
|
return
|
||||||
|
visited.add(obj_id)
|
||||||
|
|
||||||
|
title = AudiobookshelfClient._normalize_item_title(obj)
|
||||||
|
item_id = AudiobookshelfClient._extract_item_id(obj)
|
||||||
|
if title and item_id:
|
||||||
|
key = item_id.strip().lower()
|
||||||
|
if key not in seen_ids:
|
||||||
|
seen_ids.add(key)
|
||||||
|
items.append(obj)
|
||||||
|
|
||||||
|
for value in obj.values():
|
||||||
|
_visit(value)
|
||||||
|
|
||||||
|
elif isinstance(obj, list):
|
||||||
|
for entry in obj:
|
||||||
|
_visit(entry)
|
||||||
|
|
||||||
|
_visit(payload)
|
||||||
|
return items
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_title(metadata: Mapping[str, Any], audio_path: Path) -> str:
|
||||||
|
title = metadata.get("title") if isinstance(metadata, Mapping) else None
|
||||||
|
candidate = str(title).strip() if isinstance(title, str) else ""
|
||||||
|
if candidate:
|
||||||
|
return candidate
|
||||||
|
return audio_path.stem or audio_path.name
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_author(metadata: Mapping[str, Any]) -> str:
|
||||||
|
authors = metadata.get("authors") if isinstance(metadata, Mapping) else None
|
||||||
|
if isinstance(authors, str):
|
||||||
|
candidate = authors.strip()
|
||||||
|
return candidate
|
||||||
|
if isinstance(authors, Iterable) and not isinstance(authors, (str, Mapping)):
|
||||||
|
names = [str(entry).strip() for entry in authors if isinstance(entry, str) and entry.strip()]
|
||||||
|
if names:
|
||||||
|
# ABS expects a comma-separated string for multiple authors.
|
||||||
|
return ", ".join(names)
|
||||||
|
return ""
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_series(metadata: Mapping[str, Any]) -> str:
|
||||||
|
series_name = metadata.get("seriesName") if isinstance(metadata, Mapping) else None
|
||||||
|
if isinstance(series_name, str) and series_name.strip():
|
||||||
|
return series_name.strip()
|
||||||
|
return ""
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def _extract_series_sequence(metadata: Mapping[str, Any]) -> str:
|
||||||
|
if not isinstance(metadata, Mapping):
|
||||||
|
return ""
|
||||||
|
|
||||||
|
preferred_keys = (
|
||||||
|
"seriesSequence",
|
||||||
|
"series_sequence",
|
||||||
|
"seriesIndex",
|
||||||
|
"series_index",
|
||||||
|
"seriesNumber",
|
||||||
|
"series_number",
|
||||||
|
"bookNumber",
|
||||||
|
"book_number",
|
||||||
|
)
|
||||||
|
|
||||||
|
for key in preferred_keys:
|
||||||
|
if key not in metadata:
|
||||||
|
continue
|
||||||
|
normalized = normalize_series_sequence(metadata.get(key))
|
||||||
|
if normalized:
|
||||||
|
return normalized
|
||||||
|
return ""
|
||||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
Binary file not shown.
Binary file not shown.
@@ -0,0 +1,210 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import json
|
||||||
|
from dataclasses import dataclass
|
||||||
|
from typing import Any, Dict, List, Mapping, Optional, Sequence, Tuple
|
||||||
|
from urllib import error, parse, request
|
||||||
|
|
||||||
|
|
||||||
|
class LLMClientError(RuntimeError):
|
||||||
|
"""Raised when an LLM request fails."""
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class LLMConfiguration:
|
||||||
|
base_url: str
|
||||||
|
api_key: str
|
||||||
|
model: str
|
||||||
|
timeout: float = 30.0
|
||||||
|
|
||||||
|
def is_configured(self) -> bool:
|
||||||
|
return bool(self.base_url.strip() and self.model.strip())
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class LLMToolCall:
|
||||||
|
name: str
|
||||||
|
arguments: str
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass(frozen=True)
|
||||||
|
class LLMCompletion:
|
||||||
|
content: Optional[str]
|
||||||
|
tool_calls: Tuple[LLMToolCall, ...]
|
||||||
|
|
||||||
|
|
||||||
|
_DEFAULT_HEADERS = {
|
||||||
|
"Content-Type": "application/json",
|
||||||
|
"Accept": "application/json",
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
def _normalized_base_url(base_url: str) -> str:
|
||||||
|
trimmed = (base_url or "").strip()
|
||||||
|
if not trimmed:
|
||||||
|
raise LLMClientError("LLM base URL is required")
|
||||||
|
if not trimmed.endswith("/"):
|
||||||
|
trimmed += "/"
|
||||||
|
return trimmed
|
||||||
|
|
||||||
|
|
||||||
|
def _build_url(base_url: str, path: str) -> str:
|
||||||
|
normalized = _normalized_base_url(base_url)
|
||||||
|
trimmed_path = path.lstrip("/")
|
||||||
|
parsed = parse.urlparse(normalized)
|
||||||
|
if parsed.path.rstrip("/").lower().endswith("/v1") and trimmed_path.startswith(
|
||||||
|
"v1/"
|
||||||
|
):
|
||||||
|
trimmed_path = trimmed_path[len("v1/") :]
|
||||||
|
return parse.urljoin(normalized, trimmed_path)
|
||||||
|
|
||||||
|
|
||||||
|
def _build_headers(api_key: str) -> Dict[str, str]:
|
||||||
|
headers = dict(_DEFAULT_HEADERS)
|
||||||
|
token = (api_key or "").strip()
|
||||||
|
if token and token.lower() != "ollama":
|
||||||
|
headers["Authorization"] = f"Bearer {token}"
|
||||||
|
return headers
|
||||||
|
|
||||||
|
|
||||||
|
def _perform_request(
|
||||||
|
method: str,
|
||||||
|
url: str,
|
||||||
|
*,
|
||||||
|
headers: Optional[Mapping[str, str]] = None,
|
||||||
|
payload: Optional[Mapping[str, Any]] = None,
|
||||||
|
timeout: float = 30.0,
|
||||||
|
) -> Any:
|
||||||
|
data_bytes: Optional[bytes] = None
|
||||||
|
if payload is not None:
|
||||||
|
data_bytes = json.dumps(payload).encode("utf-8")
|
||||||
|
request_headers = dict(headers or {})
|
||||||
|
req = request.Request(
|
||||||
|
url, data=data_bytes, headers=request_headers, method=method.upper()
|
||||||
|
)
|
||||||
|
try:
|
||||||
|
with request.urlopen(req, timeout=timeout) as response:
|
||||||
|
body = response.read()
|
||||||
|
except error.HTTPError as exc: # pragma: no cover - defensive network guard
|
||||||
|
message = exc.read().decode("utf-8", "ignore") if exc.fp else exc.reason
|
||||||
|
raise LLMClientError(f"LLM request failed ({exc.code}): {message}") from exc
|
||||||
|
except error.URLError as exc: # pragma: no cover - defensive network guard
|
||||||
|
raise LLMClientError(f"LLM request failed: {exc.reason}") from exc
|
||||||
|
except Exception as exc: # pragma: no cover - defensive network guard
|
||||||
|
raise LLMClientError("LLM request failed") from exc
|
||||||
|
|
||||||
|
if not body:
|
||||||
|
return None
|
||||||
|
try:
|
||||||
|
return json.loads(body.decode("utf-8"))
|
||||||
|
except json.JSONDecodeError as exc:
|
||||||
|
raise LLMClientError("LLM response was not valid JSON") from exc
|
||||||
|
|
||||||
|
|
||||||
|
def list_models(configuration: LLMConfiguration) -> List[Dict[str, str]]:
|
||||||
|
if not configuration.is_configured() and not configuration.base_url.strip():
|
||||||
|
raise LLMClientError("LLM configuration is incomplete")
|
||||||
|
url = _build_url(configuration.base_url, "v1/models")
|
||||||
|
headers = _build_headers(configuration.api_key)
|
||||||
|
payload = _perform_request(
|
||||||
|
"GET", url, headers=headers, timeout=configuration.timeout
|
||||||
|
)
|
||||||
|
if not isinstance(payload, Mapping):
|
||||||
|
raise LLMClientError("Unexpected response when listing models")
|
||||||
|
data = payload.get("data")
|
||||||
|
if not isinstance(data, list):
|
||||||
|
return []
|
||||||
|
models: List[Dict[str, str]] = []
|
||||||
|
for entry in data:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
identifier = str(entry.get("id") or "").strip()
|
||||||
|
if not identifier:
|
||||||
|
continue
|
||||||
|
description = str(entry.get("name") or entry.get("description") or identifier)
|
||||||
|
models.append({"id": identifier, "label": description})
|
||||||
|
return models
|
||||||
|
|
||||||
|
|
||||||
|
def generate_completion(
|
||||||
|
configuration: LLMConfiguration,
|
||||||
|
*,
|
||||||
|
system_message: str,
|
||||||
|
user_message: str,
|
||||||
|
temperature: float = 0.2,
|
||||||
|
max_tokens: Optional[int] = None,
|
||||||
|
tools: Optional[Sequence[Mapping[str, Any]]] = None,
|
||||||
|
tool_choice: Optional[Mapping[str, Any]] = None,
|
||||||
|
response_format: Optional[Mapping[str, Any]] = None,
|
||||||
|
) -> LLMCompletion:
|
||||||
|
if not configuration.is_configured():
|
||||||
|
raise LLMClientError("LLM configuration is incomplete")
|
||||||
|
|
||||||
|
url = _build_url(configuration.base_url, "v1/chat/completions")
|
||||||
|
headers = _build_headers(configuration.api_key)
|
||||||
|
payload: Dict[str, Any] = {
|
||||||
|
"model": configuration.model,
|
||||||
|
"messages": [
|
||||||
|
{"role": "system", "content": system_message},
|
||||||
|
{"role": "user", "content": user_message},
|
||||||
|
],
|
||||||
|
"temperature": temperature,
|
||||||
|
}
|
||||||
|
if max_tokens is not None:
|
||||||
|
payload["max_tokens"] = max_tokens
|
||||||
|
if tools:
|
||||||
|
payload["tools"] = list(tools)
|
||||||
|
if tool_choice:
|
||||||
|
payload["tool_choice"] = dict(tool_choice)
|
||||||
|
if response_format:
|
||||||
|
payload["response_format"] = dict(response_format)
|
||||||
|
|
||||||
|
response = _perform_request(
|
||||||
|
"POST", url, headers=headers, payload=payload, timeout=configuration.timeout
|
||||||
|
)
|
||||||
|
if not isinstance(response, Mapping):
|
||||||
|
raise LLMClientError("Unexpected response from LLM")
|
||||||
|
choices = response.get("choices")
|
||||||
|
if not isinstance(choices, list) or not choices:
|
||||||
|
raise LLMClientError("LLM response did not include choices")
|
||||||
|
first = choices[0]
|
||||||
|
if not isinstance(first, Mapping):
|
||||||
|
raise LLMClientError("LLM response choice was invalid")
|
||||||
|
message = first.get("message")
|
||||||
|
content: Optional[str] = None
|
||||||
|
tool_calls: List[LLMToolCall] = []
|
||||||
|
if isinstance(message, Mapping):
|
||||||
|
content = message.get("content")
|
||||||
|
if isinstance(content, str):
|
||||||
|
stripped = content.strip()
|
||||||
|
if stripped:
|
||||||
|
content = stripped
|
||||||
|
else:
|
||||||
|
content = None
|
||||||
|
tool_call_entries = message.get("tool_calls")
|
||||||
|
if isinstance(tool_call_entries, list):
|
||||||
|
for entry in tool_call_entries:
|
||||||
|
if not isinstance(entry, Mapping):
|
||||||
|
continue
|
||||||
|
fn = entry.get("function")
|
||||||
|
if not isinstance(fn, Mapping):
|
||||||
|
continue
|
||||||
|
name = str(fn.get("name") or "").strip()
|
||||||
|
if not name:
|
||||||
|
continue
|
||||||
|
args = fn.get("arguments", "")
|
||||||
|
if isinstance(args, (dict, list)):
|
||||||
|
arguments = json.dumps(args)
|
||||||
|
else:
|
||||||
|
arguments = str(args)
|
||||||
|
tool_calls.append(LLMToolCall(name=name, arguments=arguments))
|
||||||
|
if content:
|
||||||
|
return LLMCompletion(content=content, tool_calls=tuple(tool_calls))
|
||||||
|
text = first.get("text")
|
||||||
|
if isinstance(text, str):
|
||||||
|
stripped = text.strip()
|
||||||
|
if stripped:
|
||||||
|
content = stripped
|
||||||
|
if content or tool_calls:
|
||||||
|
return LLMCompletion(content=content, tool_calls=tuple(tool_calls))
|
||||||
|
raise LLMClientError("LLM response did not include text content")
|
||||||
+24
-149
@@ -1,164 +1,39 @@
|
|||||||
|
"""Backwards-compatible entry point that now launches the web UI."""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
import os
|
import os
|
||||||
import sys
|
|
||||||
import platform
|
import platform
|
||||||
import atexit
|
|
||||||
import signal
|
|
||||||
|
|
||||||
# Fix PyTorch DLL loading issue ([WinError 1114]) on Windows before importing PyQt6
|
# Initialise global shutdown handling (atexit, signals, Qt) as early as possible.
|
||||||
if platform.system() == "Windows":
|
from abogen import shutdown # noqa: F401
|
||||||
import ctypes
|
shutdown.register_shutdown()
|
||||||
from importlib.util import find_spec
|
|
||||||
|
|
||||||
try:
|
from abogen.utils import load_config
|
||||||
if (
|
from abogen.webui.app import main as _run_web_ui
|
||||||
(spec := find_spec("torch"))
|
|
||||||
and spec.origin
|
|
||||||
and os.path.exists(
|
|
||||||
dll_path := os.path.join(os.path.dirname(spec.origin), "lib", "c10.dll")
|
|
||||||
)
|
|
||||||
):
|
|
||||||
ctypes.CDLL(os.path.normpath(dll_path))
|
|
||||||
except Exception:
|
|
||||||
pass
|
|
||||||
|
|
||||||
# Qt platform plugin detection (fixes #59)
|
# Configure Hugging Face Hub behaviour (mirrors legacy GUI defaults).
|
||||||
try:
|
os.environ.setdefault("HF_HUB_DISABLE_TELEMETRY", "1")
|
||||||
from PyQt6.QtCore import QLibraryInfo
|
os.environ.setdefault("HF_HUB_ETAG_TIMEOUT", "10")
|
||||||
|
os.environ.setdefault("HF_HUB_DOWNLOAD_TIMEOUT", "10")
|
||||||
# Get the path to the plugins directory
|
os.environ.setdefault("HF_HUB_DISABLE_SYMLINKS_WARNING", "1")
|
||||||
plugins = QLibraryInfo.path(QLibraryInfo.LibraryPath.PluginsPath)
|
|
||||||
|
|
||||||
# Normalize path to use the OS-native separators and absolute path
|
|
||||||
platform_dir = os.path.normpath(os.path.join(plugins, "platforms"))
|
|
||||||
|
|
||||||
# Ensure we work with an absolute path for clarity
|
|
||||||
platform_dir = os.path.abspath(platform_dir)
|
|
||||||
|
|
||||||
if os.path.isdir(platform_dir):
|
|
||||||
os.environ["QT_QPA_PLATFORM_PLUGIN_PATH"] = platform_dir
|
|
||||||
print("QT_QPA_PLATFORM_PLUGIN_PATH set to:", platform_dir)
|
|
||||||
else:
|
|
||||||
print("PyQt6 platform plugins not found at", platform_dir)
|
|
||||||
except ImportError:
|
|
||||||
print("PyQt6 not installed.")
|
|
||||||
|
|
||||||
# Set application ID for Windows taskbar icon
|
|
||||||
if platform.system() == "Windows":
|
|
||||||
try:
|
|
||||||
from abogen.constants import PROGRAM_NAME, VERSION
|
|
||||||
import ctypes
|
|
||||||
|
|
||||||
app_id = f"{PROGRAM_NAME}.{VERSION}"
|
|
||||||
ctypes.windll.shell32.SetCurrentProcessExplicitAppUserModelID(app_id)
|
|
||||||
except Exception as e:
|
|
||||||
print("Warning: failed to set AppUserModelID:", e)
|
|
||||||
|
|
||||||
from PyQt6.QtWidgets import QApplication
|
|
||||||
from PyQt6.QtGui import QIcon
|
|
||||||
from PyQt6.QtCore import (
|
|
||||||
QLibraryInfo,
|
|
||||||
qInstallMessageHandler,
|
|
||||||
QtMsgType,
|
|
||||||
)
|
|
||||||
|
|
||||||
# Add the directory to Python path
|
|
||||||
sys.path.insert(0, os.path.join(os.path.dirname(__file__)))
|
|
||||||
|
|
||||||
from abogen.utils import get_resource_path, load_config, prevent_sleep_end
|
|
||||||
|
|
||||||
# Set Hugging Face Hub environment variables
|
|
||||||
os.environ["HF_HUB_DISABLE_TELEMETRY"] = "1" # Disable Hugging Face telemetry
|
|
||||||
os.environ["HF_HUB_ETAG_TIMEOUT"] = "10" # Metadata request timeout (seconds)
|
|
||||||
os.environ["HF_HUB_DOWNLOAD_TIMEOUT"] = "10" # File download timeout (seconds)
|
|
||||||
os.environ["HF_HUB_DISABLE_SYMLINKS_WARNING"] = "1" # Disable symlinks warning
|
|
||||||
if load_config().get("disable_kokoro_internet", False):
|
if load_config().get("disable_kokoro_internet", False):
|
||||||
print("INFO: Kokoro's internet access is disabled.")
|
os.environ["HF_HUB_OFFLINE"] = "1"
|
||||||
os.environ["HF_HUB_OFFLINE"] = "1" # Disable Hugging Face Hub internet access
|
|
||||||
|
|
||||||
from abogen.gui import abogen
|
# Prefer faster ROCm tuning defaults when available.
|
||||||
from abogen.constants import PROGRAM_NAME, VERSION
|
os.environ.setdefault("MIOPEN_FIND_MODE", "FAST")
|
||||||
|
os.environ.setdefault("MIOPEN_CONV_PRECISE_ROCM_TUNING", "0")
|
||||||
|
|
||||||
# Set environment variables for AMD ROCm
|
# Enable MPS GPU acceleration on Apple Silicon.
|
||||||
os.environ["MIOPEN_FIND_MODE"] = "FAST"
|
|
||||||
os.environ["MIOPEN_CONV_PRECISE_ROCM_TUNING"] = "0"
|
|
||||||
|
|
||||||
# Reset sleep states
|
|
||||||
atexit.register(prevent_sleep_end)
|
|
||||||
|
|
||||||
|
|
||||||
# Also handle signals (Ctrl+C, kill, etc.)
|
|
||||||
def _cleanup_sleep(signum, frame):
|
|
||||||
prevent_sleep_end()
|
|
||||||
sys.exit(0)
|
|
||||||
|
|
||||||
|
|
||||||
signal.signal(signal.SIGINT, _cleanup_sleep)
|
|
||||||
signal.signal(signal.SIGTERM, _cleanup_sleep)
|
|
||||||
|
|
||||||
# Ensure sys.stdout and sys.stderr are valid in GUI mode
|
|
||||||
if sys.stdout is None:
|
|
||||||
sys.stdout = open(os.devnull, "w")
|
|
||||||
if sys.stderr is None:
|
|
||||||
sys.stderr = open(os.devnull, "w")
|
|
||||||
|
|
||||||
# Enable MPS GPU acceleration on Mac Apple Silicon
|
|
||||||
if platform.system() == "Darwin" and platform.processor() == "arm":
|
if platform.system() == "Darwin" and platform.processor() == "arm":
|
||||||
os.environ["PYTORCH_ENABLE_MPS_FALLBACK"] = "1"
|
os.environ.setdefault("PYTORCH_ENABLE_MPS_FALLBACK", "1")
|
||||||
|
|
||||||
|
|
||||||
# Custom message handler to filter out specific Qt warnings
|
def main() -> None:
|
||||||
def qt_message_handler(mode, context, message):
|
"""Launch the Flask-based web UI."""
|
||||||
# In PyQt6, the mode is an enum, so we compare with the enum members
|
|
||||||
if "Wayland does not support QWindow::requestActivate()" in message:
|
|
||||||
return # Suppress this specific message
|
|
||||||
if "setGrabPopup called with a parent, QtWaylandClient" in message:
|
|
||||||
return
|
|
||||||
|
|
||||||
if mode == QtMsgType.QtWarningMsg:
|
_run_web_ui()
|
||||||
print(f"Qt Warning: {message}")
|
|
||||||
elif mode == QtMsgType.QtCriticalMsg:
|
|
||||||
print(f"Qt Critical: {message}")
|
|
||||||
elif mode == QtMsgType.QtFatalMsg:
|
|
||||||
print(f"Qt Fatal: {message}")
|
|
||||||
elif mode == QtMsgType.QtInfoMsg:
|
|
||||||
print(f"Qt Info: {message}")
|
|
||||||
|
|
||||||
|
|
||||||
# Install the custom message handler
|
if __name__ == "__main__": # pragma: no cover - manual execution hook
|
||||||
qInstallMessageHandler(qt_message_handler)
|
|
||||||
|
|
||||||
# Handle Wayland on Linux GNOME
|
|
||||||
if platform.system() == "Linux":
|
|
||||||
xdg_session = os.environ.get("XDG_SESSION_TYPE", "").lower()
|
|
||||||
desktop = os.environ.get("XDG_CURRENT_DESKTOP", "").lower()
|
|
||||||
if (
|
|
||||||
"gnome" in desktop
|
|
||||||
and xdg_session == "wayland"
|
|
||||||
and "QT_QPA_PLATFORM" not in os.environ
|
|
||||||
):
|
|
||||||
os.environ["QT_QPA_PLATFORM"] = "wayland"
|
|
||||||
|
|
||||||
|
|
||||||
def main():
|
|
||||||
"""Main entry point for console usage."""
|
|
||||||
app = QApplication(sys.argv)
|
|
||||||
|
|
||||||
# Set application icon using get_resource_path from utils
|
|
||||||
icon_path = get_resource_path("abogen.assets", "icon.ico")
|
|
||||||
if icon_path:
|
|
||||||
app.setWindowIcon(QIcon(icon_path))
|
|
||||||
|
|
||||||
# Set the .desktop name on Linux
|
|
||||||
if platform.system() == "Linux":
|
|
||||||
try:
|
|
||||||
app.setDesktopFileName("abogen")
|
|
||||||
except AttributeError:
|
|
||||||
pass
|
|
||||||
|
|
||||||
ex = abogen()
|
|
||||||
ex.show()
|
|
||||||
sys.exit(app.exec())
|
|
||||||
|
|
||||||
|
|
||||||
if __name__ == "__main__":
|
|
||||||
main()
|
main()
|
||||||
|
|||||||
@@ -0,0 +1,246 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import os
|
||||||
|
from dataclasses import replace
|
||||||
|
from functools import lru_cache
|
||||||
|
from typing import Any, Dict, Mapping, Optional
|
||||||
|
|
||||||
|
from abogen.kokoro_text_normalization import (
|
||||||
|
ApostropheConfig,
|
||||||
|
CONTRACTION_CATEGORY_DEFAULTS,
|
||||||
|
)
|
||||||
|
from abogen.llm_client import LLMConfiguration
|
||||||
|
from abogen.utils import load_config
|
||||||
|
|
||||||
|
DEFAULT_LLM_PROMPT = (
|
||||||
|
"You are assisting with audiobook preparation. Analyze the sentence and identify any apostrophes or "
|
||||||
|
"contractions that should be expanded for clarity. Call the apply_regex_replacements tool with precise "
|
||||||
|
"regex substitutions for only the words that need adjustment. If no changes are required, return an empty list.\n"
|
||||||
|
"Sentence: {{ sentence }}"
|
||||||
|
)
|
||||||
|
|
||||||
|
_LEGACY_REWRITE_ONLY_PROMPT = (
|
||||||
|
"You are assisting with audiobook preparation. Rewrite the provided sentence so apostrophes and "
|
||||||
|
"contractions are unambiguous for text-to-speech. Respond with only the rewritten sentence.\n"
|
||||||
|
"Sentence: {{ sentence }}\n"
|
||||||
|
"Context: {{ paragraph }}"
|
||||||
|
)
|
||||||
|
|
||||||
|
_SETTINGS_DEFAULTS: Dict[str, Any] = {
|
||||||
|
"llm_base_url": "",
|
||||||
|
"llm_api_key": "",
|
||||||
|
"llm_model": "",
|
||||||
|
"llm_timeout": 30.0,
|
||||||
|
"llm_prompt": DEFAULT_LLM_PROMPT,
|
||||||
|
"llm_context_mode": "sentence",
|
||||||
|
"normalization_numbers": True,
|
||||||
|
"normalization_numbers_year_style": "american",
|
||||||
|
"normalization_currency": True,
|
||||||
|
"normalization_footnotes": True,
|
||||||
|
"normalization_titles": True,
|
||||||
|
"normalization_terminal": True,
|
||||||
|
"normalization_phoneme_hints": True,
|
||||||
|
"normalization_caps_quotes": True,
|
||||||
|
"normalization_internet_slang": False,
|
||||||
|
"normalization_apostrophes_contractions": True,
|
||||||
|
"normalization_apostrophes_plural_possessives": True,
|
||||||
|
"normalization_apostrophes_sibilant_possessives": True,
|
||||||
|
"normalization_apostrophes_decades": True,
|
||||||
|
"normalization_apostrophes_leading_elisions": True,
|
||||||
|
"normalization_apostrophe_mode": "spacy",
|
||||||
|
"normalization_contraction_aux_be": True,
|
||||||
|
"normalization_contraction_aux_have": True,
|
||||||
|
"normalization_contraction_modal_will": True,
|
||||||
|
"normalization_contraction_modal_would": True,
|
||||||
|
"normalization_contraction_negation_not": True,
|
||||||
|
"normalization_contraction_let_us": True,
|
||||||
|
}
|
||||||
|
|
||||||
|
_CONTRACTION_SETTING_MAP: Dict[str, str] = {
|
||||||
|
"normalization_contraction_aux_be": "contraction_aux_be",
|
||||||
|
"normalization_contraction_aux_have": "contraction_aux_have",
|
||||||
|
"normalization_contraction_modal_will": "contraction_modal_will",
|
||||||
|
"normalization_contraction_modal_would": "contraction_modal_would",
|
||||||
|
"normalization_contraction_negation_not": "contraction_negation_not",
|
||||||
|
"normalization_contraction_let_us": "contraction_let_us",
|
||||||
|
}
|
||||||
|
|
||||||
|
_ENVIRONMENT_KEYS: Dict[str, str] = {
|
||||||
|
"llm_base_url": "ABOGEN_LLM_BASE_URL",
|
||||||
|
"llm_api_key": "ABOGEN_LLM_API_KEY",
|
||||||
|
"llm_model": "ABOGEN_LLM_MODEL",
|
||||||
|
"llm_timeout": "ABOGEN_LLM_TIMEOUT",
|
||||||
|
"llm_prompt": "ABOGEN_LLM_PROMPT",
|
||||||
|
"llm_context_mode": "ABOGEN_LLM_CONTEXT_MODE",
|
||||||
|
}
|
||||||
|
|
||||||
|
NORMALIZATION_SAMPLE_TEXTS: Dict[str, str] = {
|
||||||
|
"apostrophes": "I've heard the captain'll arrive by dusk, but they'd said the same yesterday.",
|
||||||
|
"numbers": "The ledger listed 1,204 outstanding debts totaling $57,890.",
|
||||||
|
"titles": "Dr. Smith met Mr. O'Leary outside St. John's Church on Jan. 4th.",
|
||||||
|
"punctuation": "Meet me at the docks tonight We'll decide then", # missing punctuation
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
|
@lru_cache(maxsize=1)
|
||||||
|
def _environment_defaults() -> Dict[str, Any]:
|
||||||
|
overrides: Dict[str, Any] = {}
|
||||||
|
for key, env_var in _ENVIRONMENT_KEYS.items():
|
||||||
|
default = _SETTINGS_DEFAULTS.get(key)
|
||||||
|
if default is None:
|
||||||
|
continue
|
||||||
|
value = os.environ.get(env_var)
|
||||||
|
if value is None or value == "":
|
||||||
|
continue
|
||||||
|
if isinstance(default, bool):
|
||||||
|
overrides[key] = _coerce_bool(value, default)
|
||||||
|
elif isinstance(default, float):
|
||||||
|
overrides[key] = _coerce_float(value, float(default))
|
||||||
|
else:
|
||||||
|
overrides[key] = value
|
||||||
|
return overrides
|
||||||
|
|
||||||
|
|
||||||
|
def environment_llm_defaults() -> Dict[str, Any]:
|
||||||
|
defaults = dict(_environment_defaults())
|
||||||
|
if defaults:
|
||||||
|
_apply_llm_migrations(defaults)
|
||||||
|
return defaults
|
||||||
|
|
||||||
|
|
||||||
|
def _coerce_bool(value: Any, default: bool) -> bool:
|
||||||
|
if isinstance(value, bool):
|
||||||
|
return value
|
||||||
|
if isinstance(value, str):
|
||||||
|
lowered = value.strip().lower()
|
||||||
|
if lowered in {"1", "true", "yes", "on"}:
|
||||||
|
return True
|
||||||
|
if lowered in {"0", "false", "no", "off"}:
|
||||||
|
return False
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _coerce_float(value: Any, default: float) -> float:
|
||||||
|
try:
|
||||||
|
return float(value)
|
||||||
|
except (TypeError, ValueError):
|
||||||
|
return default
|
||||||
|
|
||||||
|
|
||||||
|
def _apply_llm_migrations(settings: Dict[str, Any]) -> None:
|
||||||
|
prompt_value = str(settings.get("llm_prompt") or "")
|
||||||
|
if prompt_value.strip() == _LEGACY_REWRITE_ONLY_PROMPT.strip():
|
||||||
|
settings["llm_prompt"] = DEFAULT_LLM_PROMPT
|
||||||
|
|
||||||
|
context_mode = str(settings.get("llm_context_mode") or "").strip().lower()
|
||||||
|
if context_mode != "sentence":
|
||||||
|
settings["llm_context_mode"] = "sentence"
|
||||||
|
|
||||||
|
|
||||||
|
def _extract_settings(source: Mapping[str, Any]) -> Dict[str, Any]:
|
||||||
|
env_defaults = _environment_defaults()
|
||||||
|
extracted: Dict[str, Any] = {}
|
||||||
|
for key, default in _SETTINGS_DEFAULTS.items():
|
||||||
|
if key in source:
|
||||||
|
raw_value = source.get(key)
|
||||||
|
elif key in env_defaults:
|
||||||
|
raw_value = env_defaults[key]
|
||||||
|
else:
|
||||||
|
raw_value = default
|
||||||
|
if isinstance(default, bool):
|
||||||
|
extracted[key] = _coerce_bool(raw_value, default)
|
||||||
|
elif isinstance(default, float):
|
||||||
|
extracted[key] = _coerce_float(raw_value, default)
|
||||||
|
else:
|
||||||
|
extracted[key] = (
|
||||||
|
str(raw_value or "") if isinstance(default, str) else raw_value
|
||||||
|
)
|
||||||
|
_apply_llm_migrations(extracted)
|
||||||
|
return extracted
|
||||||
|
|
||||||
|
|
||||||
|
@lru_cache(maxsize=1)
|
||||||
|
def _cached_settings() -> Dict[str, Any]:
|
||||||
|
config = load_config() or {}
|
||||||
|
return _extract_settings(config)
|
||||||
|
|
||||||
|
|
||||||
|
def get_runtime_settings() -> Dict[str, Any]:
|
||||||
|
return dict(_cached_settings())
|
||||||
|
|
||||||
|
|
||||||
|
def clear_cached_settings() -> None:
|
||||||
|
_cached_settings.cache_clear()
|
||||||
|
|
||||||
|
|
||||||
|
def build_apostrophe_config(
|
||||||
|
*,
|
||||||
|
settings: Mapping[str, Any],
|
||||||
|
base: Optional[ApostropheConfig] = None,
|
||||||
|
) -> ApostropheConfig:
|
||||||
|
config = replace(base or ApostropheConfig())
|
||||||
|
config.convert_numbers = bool(settings.get("normalization_numbers", True))
|
||||||
|
config.convert_currency = bool(settings.get("normalization_currency", True))
|
||||||
|
config.remove_footnotes = bool(settings.get("normalization_footnotes", True))
|
||||||
|
config.year_pronunciation_mode = (
|
||||||
|
str(settings.get("normalization_numbers_year_style", "american") or "")
|
||||||
|
.strip()
|
||||||
|
.lower()
|
||||||
|
)
|
||||||
|
config.add_phoneme_hints = bool(settings.get("normalization_phoneme_hints", True))
|
||||||
|
config.contraction_mode = (
|
||||||
|
"expand"
|
||||||
|
if settings.get("normalization_apostrophes_contractions", True)
|
||||||
|
else "keep"
|
||||||
|
)
|
||||||
|
config.plural_possessive_mode = (
|
||||||
|
"collapse"
|
||||||
|
if settings.get("normalization_apostrophes_plural_possessives", True)
|
||||||
|
else "keep"
|
||||||
|
)
|
||||||
|
config.sibilant_possessive_mode = (
|
||||||
|
"mark"
|
||||||
|
if settings.get("normalization_apostrophes_sibilant_possessives", True)
|
||||||
|
else "keep"
|
||||||
|
)
|
||||||
|
config.decades_mode = (
|
||||||
|
"expand" if settings.get("normalization_apostrophes_decades", True) else "keep"
|
||||||
|
)
|
||||||
|
config.leading_elision_mode = (
|
||||||
|
"expand"
|
||||||
|
if settings.get("normalization_apostrophes_leading_elisions", True)
|
||||||
|
else "keep"
|
||||||
|
)
|
||||||
|
config.ambiguous_past_modal_mode = (
|
||||||
|
"contextual" if config.contraction_mode == "expand" else "keep"
|
||||||
|
)
|
||||||
|
category_flags = dict(CONTRACTION_CATEGORY_DEFAULTS)
|
||||||
|
for setting_key, category in _CONTRACTION_SETTING_MAP.items():
|
||||||
|
default_value = bool(_SETTINGS_DEFAULTS.get(setting_key, True))
|
||||||
|
raw_value = settings.get(setting_key, default_value)
|
||||||
|
category_flags[category] = _coerce_bool(raw_value, default_value)
|
||||||
|
config.contraction_categories = category_flags
|
||||||
|
return config
|
||||||
|
|
||||||
|
|
||||||
|
def build_llm_configuration(settings: Mapping[str, Any]) -> LLMConfiguration:
|
||||||
|
return LLMConfiguration(
|
||||||
|
base_url=str(settings.get("llm_base_url") or ""),
|
||||||
|
api_key=str(settings.get("llm_api_key") or ""),
|
||||||
|
model=str(settings.get("llm_model") or ""),
|
||||||
|
timeout=_coerce_float(
|
||||||
|
settings.get("llm_timeout"), float(_SETTINGS_DEFAULTS["llm_timeout"])
|
||||||
|
),
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def apply_overrides(
|
||||||
|
base: Mapping[str, Any], overrides: Mapping[str, Any]
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
merged: Dict[str, Any] = dict(base)
|
||||||
|
for key, value in overrides.items():
|
||||||
|
if key not in _SETTINGS_DEFAULTS:
|
||||||
|
continue
|
||||||
|
merged[key] = value
|
||||||
|
_apply_llm_migrations(merged)
|
||||||
|
return merged
|
||||||
@@ -21,7 +21,8 @@ from PyQt6.QtWidgets import (
|
|||||||
)
|
)
|
||||||
from PyQt6.QtCore import QThread, pyqtSignal
|
from PyQt6.QtCore import QThread, pyqtSignal
|
||||||
|
|
||||||
from abogen.constants import COLORS, VOICES_INTERNAL
|
from abogen.constants import COLORS
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
from abogen.spacy_utils import SPACY_MODELS
|
from abogen.spacy_utils import SPACY_MODELS
|
||||||
import abogen.hf_tracker
|
import abogen.hf_tracker
|
||||||
|
|
||||||
@@ -114,7 +115,7 @@ class PreDownloadWorker(QThread):
|
|||||||
self._voices_success = False
|
self._voices_success = False
|
||||||
return
|
return
|
||||||
|
|
||||||
voice_list = VOICES_INTERNAL
|
voice_list = get_voices("kokoro")
|
||||||
for idx, voice in enumerate(voice_list, start=1):
|
for idx, voice in enumerate(voice_list, start=1):
|
||||||
if self._cancelled:
|
if self._cancelled:
|
||||||
self._voices_success = False
|
self._voices_success = False
|
||||||
@@ -462,14 +463,14 @@ class PreDownloadDialog(QDialog):
|
|||||||
try:
|
try:
|
||||||
from huggingface_hub import try_to_load_from_cache
|
from huggingface_hub import try_to_load_from_cache
|
||||||
|
|
||||||
for voice in VOICES_INTERNAL:
|
for voice in get_voices("kokoro"):
|
||||||
if not try_to_load_from_cache(
|
if not try_to_load_from_cache(
|
||||||
repo_id="hexgrad/Kokoro-82M", filename=f"voices/{voice}.pt"
|
repo_id="hexgrad/Kokoro-82M", filename=f"voices/{voice}.pt"
|
||||||
):
|
):
|
||||||
missing.append(voice)
|
missing.append(voice)
|
||||||
except Exception:
|
except Exception:
|
||||||
# If HF missing, report all as missing
|
# If HF missing, report all as missing
|
||||||
return False, list(VOICES_INTERNAL)
|
return False, list(get_voices("kokoro"))
|
||||||
return (len(missing) == 0), missing
|
return (len(missing) == 0), missing
|
||||||
|
|
||||||
def _check_kokoro_model(self) -> bool:
|
def _check_kokoro_model(self) -> bool:
|
||||||
|
|||||||
@@ -0,0 +1,256 @@
|
|||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import json
|
||||||
|
import sqlite3
|
||||||
|
import shutil
|
||||||
|
import threading
|
||||||
|
import time
|
||||||
|
import uuid
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Dict, Iterable, List, Mapping, Optional
|
||||||
|
|
||||||
|
from .entity_analysis import normalize_token
|
||||||
|
from .utils import get_internal_cache_path, get_user_settings_dir
|
||||||
|
|
||||||
|
_DB_LOCK = threading.RLock()
|
||||||
|
_SCHEMA_VERSION = 1
|
||||||
|
|
||||||
|
|
||||||
|
def _store_path() -> Path:
|
||||||
|
try:
|
||||||
|
base_dir = Path(get_user_settings_dir())
|
||||||
|
except ModuleNotFoundError:
|
||||||
|
base_dir = Path(get_internal_cache_path("pronunciations"))
|
||||||
|
target = base_dir / "overrides.json"
|
||||||
|
target.parent.mkdir(parents=True, exist_ok=True)
|
||||||
|
return target
|
||||||
|
|
||||||
|
|
||||||
|
def _migrate_legacy_sqlite(target_json_path: Path) -> None:
|
||||||
|
try:
|
||||||
|
base_dir = Path(get_user_settings_dir())
|
||||||
|
except ModuleNotFoundError:
|
||||||
|
base_dir = Path(get_internal_cache_path("pronunciations"))
|
||||||
|
|
||||||
|
sqlite_path = base_dir / "pronunciations.db"
|
||||||
|
if not sqlite_path.exists():
|
||||||
|
return
|
||||||
|
|
||||||
|
try:
|
||||||
|
conn = sqlite3.connect(sqlite_path)
|
||||||
|
conn.row_factory = sqlite3.Row
|
||||||
|
|
||||||
|
# Check if table exists
|
||||||
|
cursor = conn.execute(
|
||||||
|
"SELECT name FROM sqlite_master WHERE type='table' AND name='overrides'"
|
||||||
|
)
|
||||||
|
if not cursor.fetchone():
|
||||||
|
conn.close()
|
||||||
|
return
|
||||||
|
|
||||||
|
cursor = conn.execute("SELECT * FROM overrides")
|
||||||
|
rows = cursor.fetchall()
|
||||||
|
|
||||||
|
data = {"version": _SCHEMA_VERSION, "overrides": {}}
|
||||||
|
|
||||||
|
for row in rows:
|
||||||
|
lang = row["language"]
|
||||||
|
if lang not in data["overrides"]:
|
||||||
|
data["overrides"][lang] = {}
|
||||||
|
|
||||||
|
entry = {
|
||||||
|
"id": str(row["id"]),
|
||||||
|
"normalized": row["normalized"],
|
||||||
|
"token": row["token"],
|
||||||
|
"language": row["language"],
|
||||||
|
"pronunciation": row["pronunciation"],
|
||||||
|
"voice": row["voice"],
|
||||||
|
"notes": row["notes"],
|
||||||
|
"context": row["context"],
|
||||||
|
"usage_count": row["usage_count"],
|
||||||
|
"created_at": row["created_at"],
|
||||||
|
"updated_at": row["updated_at"],
|
||||||
|
}
|
||||||
|
data["overrides"][lang][row["normalized"]] = entry
|
||||||
|
|
||||||
|
conn.close()
|
||||||
|
|
||||||
|
# Save to JSON
|
||||||
|
with open(target_json_path, "w", encoding="utf-8") as f:
|
||||||
|
json.dump(data, f, indent=2, ensure_ascii=False)
|
||||||
|
|
||||||
|
# Rename old DB
|
||||||
|
sqlite_path.rename(sqlite_path.with_suffix(".db.bak"))
|
||||||
|
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
def _load_db() -> Dict[str, Any]:
|
||||||
|
path = _store_path()
|
||||||
|
if not path.exists():
|
||||||
|
_migrate_legacy_sqlite(path)
|
||||||
|
if not path.exists():
|
||||||
|
return {"version": _SCHEMA_VERSION, "overrides": {}}
|
||||||
|
try:
|
||||||
|
with open(path, "r", encoding="utf-8") as f:
|
||||||
|
return json.load(f)
|
||||||
|
except (json.JSONDecodeError, OSError):
|
||||||
|
return {"version": _SCHEMA_VERSION, "overrides": {}}
|
||||||
|
|
||||||
|
|
||||||
|
def _save_db(data: Dict[str, Any]) -> None:
|
||||||
|
path = _store_path()
|
||||||
|
# Atomic write
|
||||||
|
temp_path = path.with_suffix(".tmp")
|
||||||
|
with open(temp_path, "w", encoding="utf-8") as f:
|
||||||
|
json.dump(data, f, indent=2, ensure_ascii=False)
|
||||||
|
shutil.move(str(temp_path), str(path))
|
||||||
|
|
||||||
|
|
||||||
|
def load_overrides(language: str, tokens: Iterable[str]) -> Dict[str, Dict[str, Any]]:
|
||||||
|
normalized_tokens = {normalize_token(token) for token in tokens if token}
|
||||||
|
if not normalized_tokens:
|
||||||
|
return {}
|
||||||
|
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
results: Dict[str, Dict[str, Any]] = {}
|
||||||
|
for normalized in normalized_tokens:
|
||||||
|
if normalized in lang_overrides:
|
||||||
|
results[normalized] = lang_overrides[normalized]
|
||||||
|
return results
|
||||||
|
|
||||||
|
|
||||||
|
def search_overrides(
|
||||||
|
language: str, query: str, *, limit: int = 15
|
||||||
|
) -> List[Dict[str, Any]]:
|
||||||
|
if not query:
|
||||||
|
return []
|
||||||
|
|
||||||
|
query = query.lower()
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
matches = []
|
||||||
|
for entry in lang_overrides.values():
|
||||||
|
if query in entry["normalized"] or query in entry["token"].lower():
|
||||||
|
matches.append(entry)
|
||||||
|
|
||||||
|
# Sort by usage count desc, then updated_at desc
|
||||||
|
matches.sort(
|
||||||
|
key=lambda x: (x.get("usage_count", 0), x.get("updated_at", 0)),
|
||||||
|
reverse=True,
|
||||||
|
)
|
||||||
|
return matches[:limit]
|
||||||
|
|
||||||
|
|
||||||
|
def save_override(
|
||||||
|
*,
|
||||||
|
language: str,
|
||||||
|
token: str,
|
||||||
|
pronunciation: Optional[str] = None,
|
||||||
|
voice: Optional[str] = None,
|
||||||
|
notes: Optional[str] = None,
|
||||||
|
context: Optional[str] = None,
|
||||||
|
) -> Dict[str, Any]:
|
||||||
|
normalized = normalize_token(token)
|
||||||
|
if not normalized:
|
||||||
|
raise ValueError("Provide a token to override")
|
||||||
|
|
||||||
|
timestamp = time.time()
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
overrides = db.setdefault("overrides", {})
|
||||||
|
lang_overrides = overrides.setdefault(language, {})
|
||||||
|
|
||||||
|
existing = lang_overrides.get(normalized)
|
||||||
|
|
||||||
|
if existing:
|
||||||
|
entry = existing
|
||||||
|
entry["token"] = token
|
||||||
|
entry["pronunciation"] = pronunciation
|
||||||
|
entry["voice"] = voice
|
||||||
|
entry["notes"] = notes
|
||||||
|
entry["context"] = context
|
||||||
|
entry["updated_at"] = timestamp
|
||||||
|
else:
|
||||||
|
entry = {
|
||||||
|
"id": str(uuid.uuid4()),
|
||||||
|
"normalized": normalized,
|
||||||
|
"token": token,
|
||||||
|
"language": language,
|
||||||
|
"pronunciation": pronunciation,
|
||||||
|
"voice": voice,
|
||||||
|
"notes": notes,
|
||||||
|
"context": context,
|
||||||
|
"usage_count": 0,
|
||||||
|
"created_at": timestamp,
|
||||||
|
"updated_at": timestamp,
|
||||||
|
}
|
||||||
|
lang_overrides[normalized] = entry
|
||||||
|
|
||||||
|
_save_db(db)
|
||||||
|
return entry
|
||||||
|
|
||||||
|
|
||||||
|
def delete_override(*, language: str, token: str) -> None:
|
||||||
|
normalized = normalize_token(token)
|
||||||
|
if not normalized:
|
||||||
|
return
|
||||||
|
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
if normalized in lang_overrides:
|
||||||
|
del lang_overrides[normalized]
|
||||||
|
_save_db(db)
|
||||||
|
|
||||||
|
|
||||||
|
def all_overrides(language: str) -> List[Dict[str, Any]]:
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
results = list(lang_overrides.values())
|
||||||
|
results.sort(key=lambda x: x.get("updated_at", 0), reverse=True)
|
||||||
|
return results
|
||||||
|
|
||||||
|
|
||||||
|
def increment_usage(*, language: str, token: str, amount: int = 1) -> None:
|
||||||
|
normalized = normalize_token(token)
|
||||||
|
if not normalized:
|
||||||
|
return
|
||||||
|
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
if normalized in lang_overrides:
|
||||||
|
entry = lang_overrides[normalized]
|
||||||
|
entry["usage_count"] = entry.get("usage_count", 0) + amount
|
||||||
|
entry["updated_at"] = time.time()
|
||||||
|
_save_db(db)
|
||||||
|
|
||||||
|
|
||||||
|
def get_override_stats(language: str) -> Dict[str, int]:
|
||||||
|
with _DB_LOCK:
|
||||||
|
db = _load_db()
|
||||||
|
lang_overrides = db.get("overrides", {}).get(language, {})
|
||||||
|
|
||||||
|
total = len(lang_overrides)
|
||||||
|
with_pronunciation = sum(
|
||||||
|
1 for x in lang_overrides.values() if x.get("pronunciation")
|
||||||
|
)
|
||||||
|
with_voice = sum(1 for x in lang_overrides.values() if x.get("voice"))
|
||||||
|
|
||||||
|
return {
|
||||||
|
"total": total,
|
||||||
|
"filtered": total,
|
||||||
|
"with_pronunciation": with_pronunciation,
|
||||||
|
"with_voice": with_voice,
|
||||||
|
}
|
||||||
@@ -0,0 +1,7 @@
|
|||||||
|
"""PyQt6 Desktop GUI for abogen.
|
||||||
|
|
||||||
|
This package contains the traditional PyQt6-based desktop interface.
|
||||||
|
For the web-based interface, see abogen.webui.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,209 @@
|
|||||||
|
"""PyQt adapter: ConversionThread -> ConversionRequest.
|
||||||
|
|
||||||
|
Converts a PyQt ConversionThread into a ConversionRequest that the application layer can process.
|
||||||
|
This adapter is the bridge between the PyQt layer and the application/domain layer.
|
||||||
|
|
||||||
|
The adapter is responsible for:
|
||||||
|
- Mapping ConversionThread fields to ConversionRequest fields
|
||||||
|
- Handling UI-specific state (signals, dialogs, cancellation)
|
||||||
|
- Providing PipelineProvider and VoiceResolver implementations
|
||||||
|
|
||||||
|
Subtitle file/timestamp special paths remain in ConversionThread.run() early return.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
|
import os
|
||||||
|
from pathlib import Path
|
||||||
|
from typing import Any, Callable, Dict, List, Optional
|
||||||
|
|
||||||
|
from abogen.application.conversion_config import (
|
||||||
|
ChapterChunkConfig,
|
||||||
|
Epub3ExportConfig,
|
||||||
|
PronunciationConfig,
|
||||||
|
WordSubstitutionConfig,
|
||||||
|
)
|
||||||
|
from abogen.application.conversion_request import ConversionRequest
|
||||||
|
from abogen.application.conversion_ports import ConversionCancelled, ResolvedVoice
|
||||||
|
|
||||||
|
|
||||||
|
def build_conversion_request_from_thread(thread: Any) -> ConversionRequest:
|
||||||
|
"""Convert a PyQt ConversionThread into a ConversionRequest.
|
||||||
|
|
||||||
|
This is the primary function that maps thread fields to ConversionRequest.
|
||||||
|
All fields are copied — the request is independent of the thread.
|
||||||
|
|
||||||
|
Args:
|
||||||
|
thread: PyQt ConversionThread instance
|
||||||
|
|
||||||
|
Returns:
|
||||||
|
ConversionRequest with all thread data mapped
|
||||||
|
"""
|
||||||
|
# Determine source path
|
||||||
|
source_path = None
|
||||||
|
is_direct_text = getattr(thread, "is_direct_text", False)
|
||||||
|
if not is_direct_text and thread.file_name:
|
||||||
|
source_path = Path(thread.file_name)
|
||||||
|
|
||||||
|
# Determine original filename
|
||||||
|
original_filename = ""
|
||||||
|
if getattr(thread, "from_queue", False):
|
||||||
|
base_path = getattr(thread, "save_base_path", None) or thread.file_name
|
||||||
|
else:
|
||||||
|
base_path = getattr(thread, "display_path", None) or thread.file_name
|
||||||
|
|
||||||
|
if base_path:
|
||||||
|
original_filename = os.path.basename(base_path)
|
||||||
|
|
||||||
|
# Determine output folder
|
||||||
|
output_folder = None
|
||||||
|
if thread.output_folder:
|
||||||
|
output_folder = Path(thread.output_folder)
|
||||||
|
|
||||||
|
# Build pronunciation config
|
||||||
|
pronunciation = None
|
||||||
|
pron_overrides = getattr(thread, "pronunciation_overrides", []) or []
|
||||||
|
manual_overrides = getattr(thread, "manual_overrides", []) or []
|
||||||
|
heteronym_overrides = getattr(thread, "heteronym_overrides", []) or []
|
||||||
|
norm_overrides = getattr(thread, "normalization_overrides", None)
|
||||||
|
if pron_overrides or manual_overrides or heteronym_overrides or norm_overrides:
|
||||||
|
pronunciation = PronunciationConfig(
|
||||||
|
pronunciation_overrides=pron_overrides,
|
||||||
|
manual_overrides=manual_overrides,
|
||||||
|
heteronym_overrides=heteronym_overrides,
|
||||||
|
normalization_overrides=norm_overrides,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Build epub3 config
|
||||||
|
epub3_export = None
|
||||||
|
if getattr(thread, "generate_epub3", False):
|
||||||
|
epub3_export = Epub3ExportConfig()
|
||||||
|
|
||||||
|
return ConversionRequest(
|
||||||
|
# Source
|
||||||
|
source_path=source_path,
|
||||||
|
direct_text=thread.file_name if is_direct_text else None,
|
||||||
|
original_filename=original_filename,
|
||||||
|
# TTS Settings
|
||||||
|
language=thread.lang_code,
|
||||||
|
tts_provider="kokoro", # PyQt uses Kokoro by default
|
||||||
|
voice=thread.voice,
|
||||||
|
voice_profile=getattr(thread, "voice_profile", None),
|
||||||
|
speed=thread.speed,
|
||||||
|
use_gpu=thread.use_gpu,
|
||||||
|
supertonic_total_steps=getattr(thread, "supertonic_total_steps", 5),
|
||||||
|
# Output Format
|
||||||
|
output_format=thread.output_format,
|
||||||
|
subtitle_mode=thread.subtitle_mode,
|
||||||
|
subtitle_format=getattr(thread, "subtitle_format", "srt"),
|
||||||
|
max_subtitle_words=getattr(thread, "max_subtitle_words", 50),
|
||||||
|
# Save Options
|
||||||
|
save_mode=thread.save_option,
|
||||||
|
output_folder=output_folder,
|
||||||
|
save_chapters_separately=getattr(thread, "save_chapters_separately", False),
|
||||||
|
merge_chapters_at_end=getattr(thread, "merge_chapters_at_end", True),
|
||||||
|
separate_chapters_format=getattr(thread, "separate_chapters_format", "wav"),
|
||||||
|
save_as_project=getattr(thread, "save_as_project", False),
|
||||||
|
# Timing
|
||||||
|
silence_between_chapters=getattr(thread, "silence_duration", 2.0),
|
||||||
|
chapter_intro_delay=getattr(thread, "chapter_intro_delay", 0.0),
|
||||||
|
# Content Processing
|
||||||
|
replace_single_newlines=getattr(thread, "replace_single_newlines", False),
|
||||||
|
read_title_intro=getattr(thread, "read_title_intro", False),
|
||||||
|
read_closing_outro=getattr(thread, "read_closing_outro", True),
|
||||||
|
auto_prefix_chapter_titles=getattr(thread, "auto_prefix_chapter_titles", True),
|
||||||
|
normalize_chapter_opening_caps=thread.normalize_chapter_opening_caps,
|
||||||
|
# Metadata
|
||||||
|
metadata_tags=getattr(thread, "metadata_tags", {}) or {},
|
||||||
|
# Artifacts
|
||||||
|
cover_image_path=getattr(thread, "cover_image_path", None),
|
||||||
|
cover_image_mime=getattr(thread, "cover_image_mime", None),
|
||||||
|
# Feature configs
|
||||||
|
pronunciation=pronunciation,
|
||||||
|
epub3_export=epub3_export,
|
||||||
|
chapter_chunk=ChapterChunkConfig(), # PyQt doesn't use chapter overrides from GUI
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
class PyQtEvents:
|
||||||
|
"""PyQt implementation of ConversionEvents protocol.
|
||||||
|
|
||||||
|
Wraps a ConversionThread to provide logging, progress, and cancellation.
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(self, thread: Any):
|
||||||
|
self._thread = thread
|
||||||
|
|
||||||
|
def log(self, message: str, level: str = "info") -> None:
|
||||||
|
"""Log a message via signal."""
|
||||||
|
self._thread.log_updated.emit((message, _level_to_color(level)))
|
||||||
|
|
||||||
|
def progress(self, pct: int, etr: str) -> None:
|
||||||
|
"""Update progress via signal."""
|
||||||
|
self._thread.progress_updated.emit(pct, etr)
|
||||||
|
|
||||||
|
def check_cancelled(self) -> None:
|
||||||
|
"""Check if conversion was cancelled.
|
||||||
|
|
||||||
|
Raises:
|
||||||
|
ConversionCancelled: If cancellation was requested
|
||||||
|
"""
|
||||||
|
if self._thread.cancel_requested:
|
||||||
|
raise ConversionCancelled("Conversion cancelled by user")
|
||||||
|
|
||||||
|
|
||||||
|
class PyQtPipelineProvider:
|
||||||
|
"""PyQt implementation of PipelineProvider protocol.
|
||||||
|
|
||||||
|
Wraps the existing backend from ConversionThread.
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(self, backend: Any):
|
||||||
|
self._backend = backend
|
||||||
|
|
||||||
|
def get(self, provider: str, language: str, use_gpu: bool) -> Any:
|
||||||
|
"""Get a TTS backend instance.
|
||||||
|
|
||||||
|
For PyQt, this returns the pre-initialized backend.
|
||||||
|
"""
|
||||||
|
return self._backend
|
||||||
|
|
||||||
|
def dispose_all(self) -> None:
|
||||||
|
"""Dispose all backend resources."""
|
||||||
|
pass # PyQt manages backend lifecycle in thread
|
||||||
|
|
||||||
|
|
||||||
|
class PyQtVoiceResolver:
|
||||||
|
"""PyQt implementation of VoiceResolver protocol.
|
||||||
|
|
||||||
|
Wraps load_voice_cached from the ConversionThread.
|
||||||
|
"""
|
||||||
|
|
||||||
|
def __init__(self, thread: Any):
|
||||||
|
self._thread = thread
|
||||||
|
|
||||||
|
def resolve(self, voice_spec: str) -> ResolvedVoice:
|
||||||
|
"""Resolve a voice spec into a loaded voice."""
|
||||||
|
from abogen.domain.voice_resolution import resolve_fallback_voice_spec
|
||||||
|
|
||||||
|
# Use thread's load_voice_cached method
|
||||||
|
loaded_voice = self._thread.load_voice_cached(voice_spec, self._thread.backend)
|
||||||
|
|
||||||
|
return ResolvedVoice(
|
||||||
|
provider="kokoro",
|
||||||
|
resolved_spec=voice_spec,
|
||||||
|
voice=loaded_voice,
|
||||||
|
speed=self._thread.speed,
|
||||||
|
supertonic_steps=getattr(self._thread, "supertonic_total_steps", 5),
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
def _level_to_color(level: str) -> str:
|
||||||
|
"""Map log level to PyQt color string."""
|
||||||
|
colors = {
|
||||||
|
"info": "grey",
|
||||||
|
"warning": "orange",
|
||||||
|
"error": "red",
|
||||||
|
"debug": "grey",
|
||||||
|
}
|
||||||
|
return colors.get(level, "grey")
|
||||||
+4323
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,188 @@
|
|||||||
|
import logging
|
||||||
|
import os
|
||||||
|
import sys
|
||||||
|
import platform
|
||||||
|
|
||||||
|
# Initialise global shutdown handling (atexit, signals, Qt) as early as possible.
|
||||||
|
from abogen import shutdown # noqa: F401
|
||||||
|
shutdown.register_shutdown()
|
||||||
|
|
||||||
|
from abogen.utils import get_resource_path, setup_console_logging, timed_log # noqa: E402
|
||||||
|
|
||||||
|
_log = logging.getLogger("abogen.startup")
|
||||||
|
setup_console_logging()
|
||||||
|
|
||||||
|
# Fix PyTorch DLL loading issue ([WinError 1114]) on Windows before importing PyQt6
|
||||||
|
if platform.system() == "Windows":
|
||||||
|
with timed_log("PyTorch DLLs (Windows)", logger=_log):
|
||||||
|
import ctypes
|
||||||
|
from importlib.util import find_spec
|
||||||
|
|
||||||
|
try:
|
||||||
|
if (
|
||||||
|
(spec := find_spec("torch"))
|
||||||
|
and spec.origin
|
||||||
|
and os.path.exists(
|
||||||
|
dll_path := os.path.join(os.path.dirname(spec.origin), "lib", "c10.dll")
|
||||||
|
)
|
||||||
|
):
|
||||||
|
ctypes.CDLL(os.path.normpath(dll_path))
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
# Qt platform plugin detection (fixes #59)
|
||||||
|
with timed_log("Qt platform plugin detection", logger=_log):
|
||||||
|
try:
|
||||||
|
from PyQt6.QtCore import QLibraryInfo
|
||||||
|
|
||||||
|
# Get the path to the plugins directory
|
||||||
|
plugins = QLibraryInfo.path(QLibraryInfo.LibraryPath.PluginsPath)
|
||||||
|
|
||||||
|
# Normalize path to use the OS-native separators and absolute path
|
||||||
|
platform_dir = os.path.normpath(os.path.join(plugins, "platforms"))
|
||||||
|
|
||||||
|
# Ensure we work with an absolute path for clarity
|
||||||
|
platform_dir = os.path.abspath(platform_dir)
|
||||||
|
|
||||||
|
if os.path.isdir(platform_dir):
|
||||||
|
os.environ["QT_QPA_PLATFORM_PLUGIN_PATH"] = platform_dir
|
||||||
|
_log.info("QT_QPA_PLATFORM_PLUGIN_PATH set to: %s", platform_dir)
|
||||||
|
else:
|
||||||
|
_log.warning("PyQt6 platform plugins not found at %s", platform_dir)
|
||||||
|
except ImportError:
|
||||||
|
_log.warning("PyQt6 not installed.")
|
||||||
|
|
||||||
|
|
||||||
|
# Pre-load "libxcb-cursor" on Linux (fixes #101)
|
||||||
|
if platform.system() == "Linux":
|
||||||
|
with timed_log("libxcb-cursor preload (Linux)", logger=_log):
|
||||||
|
arch = platform.machine().lower()
|
||||||
|
lib_filename = {"x86_64": "libxcb-cursor-amd64.so.0", "amd64": "libxcb-cursor-amd64.so.0", "aarch64": "libxcb-cursor-arm64.so.0", "arm64": "libxcb-cursor-arm64.so.0"}.get(arch)
|
||||||
|
if lib_filename:
|
||||||
|
import ctypes
|
||||||
|
try:
|
||||||
|
# Try to load the system libxcb-cursor.so.0 first
|
||||||
|
ctypes.CDLL('libxcb-cursor.so.0', mode=ctypes.RTLD_GLOBAL)
|
||||||
|
except OSError:
|
||||||
|
# System lib not available, load the bundled version
|
||||||
|
lib_path = get_resource_path('abogen.libs', lib_filename)
|
||||||
|
if lib_path:
|
||||||
|
try:
|
||||||
|
ctypes.CDLL(lib_path, mode=ctypes.RTLD_GLOBAL)
|
||||||
|
except OSError:
|
||||||
|
# If it fails (e.g. wrong glibc version on very old systems),
|
||||||
|
# we simply ignore it and hope the system has the library.
|
||||||
|
pass
|
||||||
|
|
||||||
|
|
||||||
|
# Set application ID for Windows taskbar icon
|
||||||
|
if platform.system() == "Windows":
|
||||||
|
with timed_log("Windows AppUserModelID", logger=_log):
|
||||||
|
try:
|
||||||
|
from abogen.constants import PROGRAM_NAME, VERSION
|
||||||
|
import ctypes
|
||||||
|
|
||||||
|
app_id = f"{PROGRAM_NAME}.{VERSION}"
|
||||||
|
ctypes.windll.shell32.SetCurrentProcessExplicitAppUserModelID(app_id)
|
||||||
|
except Exception as e:
|
||||||
|
_log.warning("Failed to set AppUserModelID: %s", e)
|
||||||
|
|
||||||
|
with timed_log("PyQt6 imports", logger=_log):
|
||||||
|
from PyQt6.QtWidgets import QApplication
|
||||||
|
from PyQt6.QtGui import QIcon
|
||||||
|
from PyQt6.QtCore import (
|
||||||
|
QLibraryInfo,
|
||||||
|
qInstallMessageHandler,
|
||||||
|
QtMsgType,
|
||||||
|
)
|
||||||
|
|
||||||
|
# Add the directory to Python path
|
||||||
|
sys.path.insert(0, os.path.join(os.path.dirname(__file__)))
|
||||||
|
|
||||||
|
# Set Hugging Face Hub environment variables
|
||||||
|
with timed_log("config load + HF env setup", logger=_log):
|
||||||
|
os.environ["HF_HUB_DISABLE_TELEMETRY"] = "1" # Disable Hugging Face telemetry
|
||||||
|
os.environ["HF_HUB_ETAG_TIMEOUT"] = "10" # Metadata request timeout (seconds)
|
||||||
|
os.environ["HF_HUB_DOWNLOAD_TIMEOUT"] = "10" # File download timeout (seconds)
|
||||||
|
os.environ["HF_HUB_DISABLE_SYMLINKS_WARNING"] = "1" # Disable symlinks warning
|
||||||
|
from abogen.utils import load_config
|
||||||
|
if load_config().get("disable_kokoro_internet", False):
|
||||||
|
_log.info("Kokoro's internet access is disabled.")
|
||||||
|
os.environ["HF_HUB_OFFLINE"] = "1" # Disable Hugging Face Hub internet access
|
||||||
|
|
||||||
|
with timed_log("GUI module import (abogen.pyqt.gui)", logger=_log):
|
||||||
|
from abogen.pyqt.gui import abogen
|
||||||
|
from abogen.constants import PROGRAM_NAME, VERSION
|
||||||
|
|
||||||
|
# Set environment variables for AMD ROCm
|
||||||
|
os.environ["MIOPEN_FIND_MODE"] = "FAST"
|
||||||
|
os.environ["MIOPEN_CONV_PRECISE_ROCM_TUNING"] = "0"
|
||||||
|
|
||||||
|
# Enable MPS GPU acceleration on Mac Apple Silicon
|
||||||
|
if platform.system() == "Darwin" and platform.processor() == "arm":
|
||||||
|
os.environ["PYTORCH_ENABLE_MPS_FALLBACK"] = "1"
|
||||||
|
|
||||||
|
|
||||||
|
# Custom message handler to filter out specific Qt warnings
|
||||||
|
def qt_message_handler(mode, context, message):
|
||||||
|
# In PyQt6, the mode is an enum, so we compare with the enum members
|
||||||
|
if "Wayland does not support QWindow::requestActivate()" in message:
|
||||||
|
return # Suppress this specific message
|
||||||
|
if "setGrabPopup called with a parent, QtWaylandClient" in message:
|
||||||
|
return
|
||||||
|
if "Failed to register with host portal" in message:
|
||||||
|
return
|
||||||
|
|
||||||
|
if mode == QtMsgType.QtWarningMsg:
|
||||||
|
print(f"Qt Warning: {message}")
|
||||||
|
elif mode == QtMsgType.QtCriticalMsg:
|
||||||
|
print(f"Qt Critical: {message}")
|
||||||
|
elif mode == QtMsgType.QtFatalMsg:
|
||||||
|
print(f"Qt Fatal: {message}")
|
||||||
|
elif mode == QtMsgType.QtInfoMsg:
|
||||||
|
print(f"Qt Info: {message}")
|
||||||
|
|
||||||
|
|
||||||
|
# Install the custom message handler
|
||||||
|
qInstallMessageHandler(qt_message_handler)
|
||||||
|
|
||||||
|
# Handle Wayland on Linux GNOME
|
||||||
|
if platform.system() == "Linux":
|
||||||
|
xdg_session = os.environ.get("XDG_SESSION_TYPE", "").lower()
|
||||||
|
desktop = os.environ.get("XDG_CURRENT_DESKTOP", "").lower()
|
||||||
|
if (
|
||||||
|
"gnome" in desktop
|
||||||
|
and xdg_session == "wayland"
|
||||||
|
and "QT_QPA_PLATFORM" not in os.environ
|
||||||
|
):
|
||||||
|
os.environ["QT_QPA_PLATFORM"] = "wayland"
|
||||||
|
|
||||||
|
|
||||||
|
def main():
|
||||||
|
"""Main entry point for console usage."""
|
||||||
|
with timed_log("QApplication creation", logger=_log):
|
||||||
|
app = QApplication(sys.argv)
|
||||||
|
|
||||||
|
# Set application icon using get_resource_path from utils
|
||||||
|
icon_path = get_resource_path("abogen.assets", "icon.ico")
|
||||||
|
if icon_path:
|
||||||
|
app.setWindowIcon(QIcon(icon_path))
|
||||||
|
|
||||||
|
# Set the .desktop name on Linux
|
||||||
|
if platform.system() == "Linux":
|
||||||
|
try:
|
||||||
|
app.setDesktopFileName("abogen")
|
||||||
|
except AttributeError:
|
||||||
|
pass
|
||||||
|
|
||||||
|
with timed_log("main window construction", logger=_log):
|
||||||
|
ex = abogen()
|
||||||
|
with timed_log("window show", logger=_log):
|
||||||
|
ex.show()
|
||||||
|
_log.info("App startup complete. Showing window.")
|
||||||
|
sys.exit(app.exec())
|
||||||
|
|
||||||
|
|
||||||
|
if __name__ == "__main__":
|
||||||
|
main()
|
||||||
@@ -0,0 +1,591 @@
|
|||||||
|
"""
|
||||||
|
Pre-download dialog and worker for Abogen
|
||||||
|
|
||||||
|
This module consolidates pre-download logic for Kokoro voices and model
|
||||||
|
and spaCy language models. The code favors clarity, avoids duplication,
|
||||||
|
and handles optional dependencies gracefully.
|
||||||
|
"""
|
||||||
|
|
||||||
|
from typing import List, Optional, Tuple
|
||||||
|
import importlib
|
||||||
|
import importlib.util
|
||||||
|
|
||||||
|
from PyQt6.QtWidgets import (
|
||||||
|
QDialog,
|
||||||
|
QVBoxLayout,
|
||||||
|
QHBoxLayout,
|
||||||
|
QLabel,
|
||||||
|
QPushButton,
|
||||||
|
QSpacerItem,
|
||||||
|
QSizePolicy,
|
||||||
|
)
|
||||||
|
from PyQt6.QtCore import QThread, pyqtSignal
|
||||||
|
|
||||||
|
from abogen.constants import COLORS
|
||||||
|
from abogen.tts_plugin.utils import get_voices
|
||||||
|
from abogen.spacy_utils import SPACY_MODELS
|
||||||
|
import abogen.hf_tracker
|
||||||
|
|
||||||
|
|
||||||
|
# Helpers
|
||||||
|
def _unique_sorted_models() -> List[str]:
|
||||||
|
"""Return a sorted list of unique spaCy model package names."""
|
||||||
|
return sorted(set(SPACY_MODELS.values()))
|
||||||
|
|
||||||
|
|
||||||
|
def _is_package_installed(pkg_name: str) -> bool:
|
||||||
|
"""Return True if a package with the given name can be imported (site-packages)."""
|
||||||
|
try:
|
||||||
|
return importlib.util.find_spec(pkg_name) is not None
|
||||||
|
except Exception:
|
||||||
|
return False
|
||||||
|
|
||||||
|
|
||||||
|
# NOTE: explicit HF cache helper removed; we use try_to_load_from_cache in-scope where needed
|
||||||
|
|
||||||
|
|
||||||
|
class PreDownloadWorker(QThread):
|
||||||
|
"""Worker thread to download required models/voices.
|
||||||
|
|
||||||
|
Emits human-readable messages via `progress`. Uses `category_done` to indicate
|
||||||
|
a category (voices/model/spacy) finished successfully. Emits `error` on exception
|
||||||
|
and `finished` after all work completes.
|
||||||
|
"""
|
||||||
|
|
||||||
|
# Emit (category, status, message)
|
||||||
|
progress = pyqtSignal(str, str, str)
|
||||||
|
category_done = pyqtSignal(str)
|
||||||
|
finished = pyqtSignal()
|
||||||
|
error = pyqtSignal(str)
|
||||||
|
|
||||||
|
def __init__(self, parent=None):
|
||||||
|
super().__init__(parent)
|
||||||
|
self._cancelled = False
|
||||||
|
# repo and filenames used for Kokoro model
|
||||||
|
self._repo_id = "hexgrad/Kokoro-82M"
|
||||||
|
self._model_files = ["kokoro-v1_0.pth", "config.json"]
|
||||||
|
# Track download success per category
|
||||||
|
self._voices_success = False
|
||||||
|
self._model_success = False
|
||||||
|
self._spacy_success = False
|
||||||
|
# Suppress HF tracker warnings during downloads
|
||||||
|
self._original_emitter = abogen.hf_tracker.show_warning_signal_emitter
|
||||||
|
|
||||||
|
def cancel(self) -> None:
|
||||||
|
self._cancelled = True
|
||||||
|
|
||||||
|
def run(self) -> None:
|
||||||
|
# Suppress HF tracker warnings during downloads
|
||||||
|
abogen.hf_tracker.show_warning_signal_emitter = None
|
||||||
|
try:
|
||||||
|
self._download_kokoro_voices()
|
||||||
|
if self._cancelled:
|
||||||
|
return
|
||||||
|
if self._voices_success:
|
||||||
|
self.category_done.emit("voices")
|
||||||
|
|
||||||
|
self._download_kokoro_model()
|
||||||
|
if self._cancelled:
|
||||||
|
return
|
||||||
|
if self._model_success:
|
||||||
|
self.category_done.emit("model")
|
||||||
|
|
||||||
|
self._download_spacy_models()
|
||||||
|
if self._cancelled:
|
||||||
|
return
|
||||||
|
if self._spacy_success:
|
||||||
|
self.category_done.emit("spacy")
|
||||||
|
|
||||||
|
self.finished.emit()
|
||||||
|
except Exception as exc: # pragma: no cover - best-effort reporting
|
||||||
|
self.error.emit(str(exc))
|
||||||
|
finally:
|
||||||
|
# Restore original emitter
|
||||||
|
abogen.hf_tracker.show_warning_signal_emitter = self._original_emitter
|
||||||
|
|
||||||
|
# Kokoro voices
|
||||||
|
def _download_kokoro_voices(self) -> None:
|
||||||
|
self._voices_success = True
|
||||||
|
try:
|
||||||
|
from huggingface_hub import hf_hub_download, try_to_load_from_cache
|
||||||
|
except Exception:
|
||||||
|
self.progress.emit(
|
||||||
|
"voice", "warning", "huggingface_hub not installed, skipping voices..."
|
||||||
|
)
|
||||||
|
self._voices_success = False
|
||||||
|
return
|
||||||
|
|
||||||
|
voice_list = get_voices("kokoro")
|
||||||
|
for idx, voice in enumerate(voice_list, start=1):
|
||||||
|
if self._cancelled:
|
||||||
|
self._voices_success = False
|
||||||
|
return
|
||||||
|
filename = f"voices/{voice}.pt"
|
||||||
|
if try_to_load_from_cache(repo_id=self._repo_id, filename=filename):
|
||||||
|
self.progress.emit(
|
||||||
|
"voice",
|
||||||
|
"installed",
|
||||||
|
f"{idx}/{len(voice_list)}: {voice} already present",
|
||||||
|
)
|
||||||
|
continue
|
||||||
|
self.progress.emit(
|
||||||
|
"voice", "downloading", f"{idx}/{len(voice_list)}: {voice}..."
|
||||||
|
)
|
||||||
|
try:
|
||||||
|
hf_hub_download(repo_id=self._repo_id, filename=filename)
|
||||||
|
self.progress.emit("voice", "downloaded", f"{voice} downloaded")
|
||||||
|
except Exception as exc:
|
||||||
|
self.progress.emit(
|
||||||
|
"voice", "warning", f"could not download {voice}: {exc}"
|
||||||
|
)
|
||||||
|
self._voices_success = False
|
||||||
|
|
||||||
|
# Kokoro model
|
||||||
|
def _download_kokoro_model(self) -> None:
|
||||||
|
self._model_success = True
|
||||||
|
try:
|
||||||
|
from huggingface_hub import hf_hub_download, try_to_load_from_cache
|
||||||
|
except Exception:
|
||||||
|
self.progress.emit(
|
||||||
|
"model", "warning", "huggingface_hub not installed, skipping model..."
|
||||||
|
)
|
||||||
|
self._model_success = False
|
||||||
|
return
|
||||||
|
for fname in self._model_files:
|
||||||
|
if self._cancelled:
|
||||||
|
self._model_success = False
|
||||||
|
return
|
||||||
|
category = "config" if fname == "config.json" else "model"
|
||||||
|
if try_to_load_from_cache(repo_id=self._repo_id, filename=fname):
|
||||||
|
self.progress.emit(
|
||||||
|
category, "installed", f"file {fname} already present"
|
||||||
|
)
|
||||||
|
continue
|
||||||
|
self.progress.emit(category, "downloading", f"file {fname}...")
|
||||||
|
try:
|
||||||
|
hf_hub_download(repo_id=self._repo_id, filename=fname)
|
||||||
|
self.progress.emit(category, "downloaded", f"file {fname} downloaded")
|
||||||
|
except Exception as exc:
|
||||||
|
self.progress.emit(
|
||||||
|
category, "warning", f"could not download file {fname}: {exc}"
|
||||||
|
)
|
||||||
|
self._model_success = False
|
||||||
|
|
||||||
|
# spaCy models
|
||||||
|
def _download_spacy_models(self) -> None:
|
||||||
|
"""Download spaCy models. Prefer missing models provided by parent.
|
||||||
|
|
||||||
|
Parent dialog will populate _spacy_models_missing during checking.
|
||||||
|
"""
|
||||||
|
self._spacy_success = True
|
||||||
|
# Determine which models to process: prefer parent-provided missing list to avoid
|
||||||
|
# re-checking everything; otherwise use the full unique list.
|
||||||
|
parent = self.parent()
|
||||||
|
models_to_process: List[str] = _unique_sorted_models()
|
||||||
|
try:
|
||||||
|
if (
|
||||||
|
parent is not None
|
||||||
|
and hasattr(parent, "_spacy_models_missing")
|
||||||
|
and parent._spacy_models_missing
|
||||||
|
):
|
||||||
|
models_to_process = list(dict.fromkeys(parent._spacy_models_missing))
|
||||||
|
except Exception:
|
||||||
|
pass
|
||||||
|
|
||||||
|
# If spaCy is not available to run the CLI, skip gracefully
|
||||||
|
try:
|
||||||
|
import spacy.cli as _spacy_cli
|
||||||
|
except Exception:
|
||||||
|
self.progress.emit(
|
||||||
|
"spacy", "warning", "spaCy not available, skipping spaCy models..."
|
||||||
|
)
|
||||||
|
self._spacy_success = False
|
||||||
|
return
|
||||||
|
|
||||||
|
for idx, model_name in enumerate(models_to_process, start=1):
|
||||||
|
if self._cancelled:
|
||||||
|
self._spacy_success = False
|
||||||
|
return
|
||||||
|
if _is_package_installed(model_name):
|
||||||
|
self.progress.emit(
|
||||||
|
"spacy",
|
||||||
|
"installed",
|
||||||
|
f"{idx}/{len(models_to_process)}: {model_name} already installed",
|
||||||
|
)
|
||||||
|
continue
|
||||||
|
self.progress.emit(
|
||||||
|
"spacy",
|
||||||
|
"downloading",
|
||||||
|
f"{idx}/{len(models_to_process)}: {model_name}...",
|
||||||
|
)
|
||||||
|
try:
|
||||||
|
_spacy_cli.download(model_name)
|
||||||
|
self.progress.emit("spacy", "downloaded", f"{model_name} downloaded")
|
||||||
|
except Exception as exc:
|
||||||
|
self.progress.emit(
|
||||||
|
"spacy", "warning", f"could not download {model_name}: {exc}"
|
||||||
|
)
|
||||||
|
self._spacy_success = False
|
||||||
|
|
||||||
|
|
||||||
|
class PreDownloadDialog(QDialog):
|
||||||
|
"""Dialog to show and control pre-download process."""
|
||||||
|
|
||||||
|
VOICE_PREFIX = "Kokoro voices: "
|
||||||
|
MODEL_PREFIX = "Kokoro model: "
|
||||||
|
CONFIG_PREFIX = "Kokoro config: "
|
||||||
|
SPACY_PREFIX = "spaCy models: "
|
||||||
|
|
||||||
|
def __init__(self, parent=None):
|
||||||
|
super().__init__(parent)
|
||||||
|
self.setWindowTitle("Pre-download Models and Voices")
|
||||||
|
self.setMinimumWidth(500)
|
||||||
|
self.worker: Optional[PreDownloadWorker] = None
|
||||||
|
self.has_missing = False
|
||||||
|
self._spacy_models_checked: List[tuple] = []
|
||||||
|
self._spacy_models_missing: List[str] = []
|
||||||
|
self._status_worker = None
|
||||||
|
|
||||||
|
# Map keywords to (label, prefix) - labels filled after UI creation
|
||||||
|
self.status_map = {
|
||||||
|
"voice": (None, self.VOICE_PREFIX),
|
||||||
|
"spacy": (None, self.SPACY_PREFIX),
|
||||||
|
"model": (None, self.MODEL_PREFIX),
|
||||||
|
"config": (None, self.CONFIG_PREFIX),
|
||||||
|
}
|
||||||
|
|
||||||
|
self.category_map = {
|
||||||
|
"voices": ["voice"],
|
||||||
|
"model": ["model", "config"],
|
||||||
|
"spacy": ["spacy"],
|
||||||
|
}
|
||||||
|
|
||||||
|
self._setup_ui()
|
||||||
|
self._start_status_check()
|
||||||
|
|
||||||
|
def _setup_ui(self) -> None:
|
||||||
|
layout = QVBoxLayout(self)
|
||||||
|
layout.setSpacing(0)
|
||||||
|
layout.setContentsMargins(15, 0, 15, 15)
|
||||||
|
|
||||||
|
desc = QLabel(
|
||||||
|
"You can pre-download all required models and voices for offline use.\n"
|
||||||
|
"This includes Kokoro voices, Kokoro model (and config), and spaCy models."
|
||||||
|
)
|
||||||
|
desc.setWordWrap(True)
|
||||||
|
layout.addWidget(desc)
|
||||||
|
|
||||||
|
# Status rows
|
||||||
|
status_layout = QVBoxLayout()
|
||||||
|
status_title = QLabel("<b>Current Status:</b>")
|
||||||
|
status_layout.addWidget(status_title)
|
||||||
|
|
||||||
|
self.voices_status = QLabel(self.VOICE_PREFIX + "⏳ Checking...")
|
||||||
|
row = QHBoxLayout()
|
||||||
|
row.addWidget(self.voices_status)
|
||||||
|
row.addStretch()
|
||||||
|
status_layout.addLayout(row)
|
||||||
|
|
||||||
|
self.model_status = QLabel(self.MODEL_PREFIX + "⏳ Checking...")
|
||||||
|
row = QHBoxLayout()
|
||||||
|
row.addWidget(self.model_status)
|
||||||
|
row.addStretch()
|
||||||
|
status_layout.addLayout(row)
|
||||||
|
|
||||||
|
self.config_status = QLabel(self.CONFIG_PREFIX + "⏳ Checking...")
|
||||||
|
row = QHBoxLayout()
|
||||||
|
row.addWidget(self.config_status)
|
||||||
|
row.addStretch()
|
||||||
|
status_layout.addLayout(row)
|
||||||
|
|
||||||
|
self.spacy_status = QLabel(self.SPACY_PREFIX + "⏳ Checking...")
|
||||||
|
row = QHBoxLayout()
|
||||||
|
row.addWidget(self.spacy_status)
|
||||||
|
row.addStretch()
|
||||||
|
status_layout.addLayout(row)
|
||||||
|
|
||||||
|
# register labels
|
||||||
|
self.status_map["voice"] = (self.voices_status, self.VOICE_PREFIX)
|
||||||
|
self.status_map["model"] = (self.model_status, self.MODEL_PREFIX)
|
||||||
|
self.status_map["config"] = (self.config_status, self.CONFIG_PREFIX)
|
||||||
|
self.status_map["spacy"] = (self.spacy_status, self.SPACY_PREFIX)
|
||||||
|
|
||||||
|
layout.addLayout(status_layout)
|
||||||
|
|
||||||
|
layout.addItem(
|
||||||
|
QSpacerItem(0, 20, QSizePolicy.Policy.Minimum, QSizePolicy.Policy.Fixed)
|
||||||
|
)
|
||||||
|
|
||||||
|
# Buttons
|
||||||
|
button_row = QHBoxLayout()
|
||||||
|
button_row.setSpacing(10)
|
||||||
|
self.download_btn = QPushButton("Download all")
|
||||||
|
self.download_btn.setMinimumWidth(100)
|
||||||
|
self.download_btn.setMinimumHeight(35)
|
||||||
|
self.download_btn.setEnabled(False)
|
||||||
|
self.download_btn.clicked.connect(self._start_download)
|
||||||
|
button_row.addWidget(self.download_btn)
|
||||||
|
|
||||||
|
self.close_btn = QPushButton("Close")
|
||||||
|
self.close_btn.setMinimumWidth(100)
|
||||||
|
self.close_btn.setMinimumHeight(35)
|
||||||
|
self.close_btn.clicked.connect(self._handle_close)
|
||||||
|
button_row.addWidget(self.close_btn)
|
||||||
|
|
||||||
|
layout.addLayout(button_row)
|
||||||
|
self.adjustSize()
|
||||||
|
|
||||||
|
# Status checking worker
|
||||||
|
class StatusCheckWorker(QThread):
|
||||||
|
voices_checked = pyqtSignal(bool, list)
|
||||||
|
model_checked = pyqtSignal(bool)
|
||||||
|
config_checked = pyqtSignal(bool)
|
||||||
|
spacy_model_checking = pyqtSignal(str)
|
||||||
|
spacy_model_result = pyqtSignal(str, bool)
|
||||||
|
spacy_checked = pyqtSignal(bool, list)
|
||||||
|
|
||||||
|
def run(self):
|
||||||
|
parent = self.parent()
|
||||||
|
if parent is None:
|
||||||
|
return
|
||||||
|
|
||||||
|
voices_ok, missing_voices = parent._check_kokoro_voices()
|
||||||
|
self.voices_checked.emit(voices_ok, missing_voices)
|
||||||
|
|
||||||
|
model_ok = parent._check_kokoro_model()
|
||||||
|
self.model_checked.emit(model_ok)
|
||||||
|
|
||||||
|
config_ok = parent._check_kokoro_config()
|
||||||
|
self.config_checked.emit(config_ok)
|
||||||
|
|
||||||
|
# Check spaCy models by package name to detect site-package installs
|
||||||
|
unique = _unique_sorted_models()
|
||||||
|
missing: List[str] = []
|
||||||
|
for name in unique:
|
||||||
|
self.spacy_model_checking.emit(name)
|
||||||
|
ok = _is_package_installed(name)
|
||||||
|
self.spacy_model_result.emit(name, ok)
|
||||||
|
if not ok:
|
||||||
|
missing.append(name)
|
||||||
|
parent._spacy_models_missing = missing
|
||||||
|
self.spacy_checked.emit(len(missing) == 0, missing)
|
||||||
|
|
||||||
|
def _start_status_check(self) -> None:
|
||||||
|
self._status_worker = self.StatusCheckWorker(self)
|
||||||
|
self._status_worker.voices_checked.connect(self._update_voices_status)
|
||||||
|
self._status_worker.model_checked.connect(self._update_model_status)
|
||||||
|
self._status_worker.config_checked.connect(self._update_config_status)
|
||||||
|
self._status_worker.spacy_model_checking.connect(self._spacy_model_checking)
|
||||||
|
self._status_worker.spacy_model_result.connect(self._spacy_model_result)
|
||||||
|
self._status_worker.spacy_checked.connect(self._update_spacy_status)
|
||||||
|
|
||||||
|
# These are initialized in __init__ to keep consistent object state
|
||||||
|
|
||||||
|
# Set checking visual state
|
||||||
|
for lbl in (
|
||||||
|
self.voices_status,
|
||||||
|
self.model_status,
|
||||||
|
self.config_status,
|
||||||
|
self.spacy_status,
|
||||||
|
):
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['ORANGE']};")
|
||||||
|
|
||||||
|
self.spacy_status.setText(self.SPACY_PREFIX + "⏳ Checking...")
|
||||||
|
self._status_worker.start()
|
||||||
|
|
||||||
|
# UI update callbacks
|
||||||
|
def _spacy_model_checking(self, name: str) -> None:
|
||||||
|
self.spacy_status.setText(f"{self.SPACY_PREFIX}Checking {name}...")
|
||||||
|
|
||||||
|
def _spacy_model_result(self, name: str, ok: bool) -> None:
|
||||||
|
self._spacy_models_checked.append((name, ok))
|
||||||
|
if not ok and name not in self._spacy_models_missing:
|
||||||
|
self._spacy_models_missing.append(name)
|
||||||
|
checked = len(self._spacy_models_checked)
|
||||||
|
missing_count = len(self._spacy_models_missing)
|
||||||
|
if missing_count:
|
||||||
|
self.spacy_status.setText(
|
||||||
|
f"{self.SPACY_PREFIX}{checked} checked, {missing_count} missing..."
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
self.spacy_status.setText(f"{self.SPACY_PREFIX}{checked} checked...")
|
||||||
|
|
||||||
|
def _update_voices_status(self, ok: bool, missing: List[str]) -> None:
|
||||||
|
if ok:
|
||||||
|
self._set_status("voice", "✓ Downloaded", COLORS["GREEN"])
|
||||||
|
else:
|
||||||
|
self.has_missing = True
|
||||||
|
if missing:
|
||||||
|
self._set_status(
|
||||||
|
"voice", f"✗ Missing {len(missing)} voices", COLORS["RED"]
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
self._set_status("voice", "✗ Not downloaded", COLORS["RED"])
|
||||||
|
|
||||||
|
def _update_model_status(self, ok: bool) -> None:
|
||||||
|
if ok:
|
||||||
|
self._set_status("model", "✓ Downloaded", COLORS["GREEN"])
|
||||||
|
else:
|
||||||
|
self.has_missing = True
|
||||||
|
self._set_status("model", "✗ Not downloaded", COLORS["RED"])
|
||||||
|
|
||||||
|
def _update_config_status(self, ok: bool) -> None:
|
||||||
|
if ok:
|
||||||
|
self._set_status("config", "✓ Downloaded", COLORS["GREEN"])
|
||||||
|
else:
|
||||||
|
self.has_missing = True
|
||||||
|
self._set_status("config", "✗ Not downloaded", COLORS["RED"])
|
||||||
|
|
||||||
|
def _update_spacy_status(self, ok: bool, missing: List[str]) -> None:
|
||||||
|
if ok:
|
||||||
|
self._set_status("spacy", "✓ Downloaded", COLORS["GREEN"])
|
||||||
|
else:
|
||||||
|
self.has_missing = True
|
||||||
|
if missing:
|
||||||
|
self._set_status(
|
||||||
|
"spacy", f"✗ Missing {len(missing)} model(s)", COLORS["RED"]
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
self._set_status("spacy", "✗ Not downloaded", COLORS["RED"])
|
||||||
|
self.download_btn.setEnabled(self.has_missing)
|
||||||
|
|
||||||
|
def _set_status(self, key: str, text: str, color: str) -> None:
|
||||||
|
lbl, prefix = self.status_map.get(key, (None, ""))
|
||||||
|
if not lbl:
|
||||||
|
return
|
||||||
|
lbl.setText(prefix + text)
|
||||||
|
lbl.setStyleSheet(f"color: {color};")
|
||||||
|
|
||||||
|
# Helper checks
|
||||||
|
def _check_kokoro_voices(self) -> Tuple[bool, List[str]]:
|
||||||
|
"""Return (ok, missing_list) for Kokoro voices check."""
|
||||||
|
missing = []
|
||||||
|
try:
|
||||||
|
from huggingface_hub import try_to_load_from_cache
|
||||||
|
|
||||||
|
for voice in get_voices("kokoro"):
|
||||||
|
if not try_to_load_from_cache(
|
||||||
|
repo_id="hexgrad/Kokoro-82M", filename=f"voices/{voice}.pt"
|
||||||
|
):
|
||||||
|
missing.append(voice)
|
||||||
|
except Exception:
|
||||||
|
# If HF missing, report all as missing
|
||||||
|
return False, list(get_voices("kokoro"))
|
||||||
|
return (len(missing) == 0), missing
|
||||||
|
|
||||||
|
def _check_kokoro_model(self) -> bool:
|
||||||
|
try:
|
||||||
|
from huggingface_hub import try_to_load_from_cache
|
||||||
|
|
||||||
|
return (
|
||||||
|
try_to_load_from_cache(
|
||||||
|
repo_id="hexgrad/Kokoro-82M", filename="kokoro-v1_0.pth"
|
||||||
|
)
|
||||||
|
is not None
|
||||||
|
)
|
||||||
|
except Exception:
|
||||||
|
return False
|
||||||
|
|
||||||
|
def _check_kokoro_config(self) -> bool:
|
||||||
|
try:
|
||||||
|
from huggingface_hub import try_to_load_from_cache
|
||||||
|
|
||||||
|
return (
|
||||||
|
try_to_load_from_cache(
|
||||||
|
repo_id="hexgrad/Kokoro-82M", filename="config.json"
|
||||||
|
)
|
||||||
|
is not None
|
||||||
|
)
|
||||||
|
except Exception:
|
||||||
|
return False
|
||||||
|
|
||||||
|
def _check_spacy_models(self) -> bool:
|
||||||
|
unique = _unique_sorted_models()
|
||||||
|
missing = [m for m in unique if not _is_package_installed(m)]
|
||||||
|
self._spacy_models_missing = missing
|
||||||
|
return len(missing) == 0
|
||||||
|
|
||||||
|
# Download control
|
||||||
|
def _start_download(self) -> None:
|
||||||
|
self.download_btn.setEnabled(False)
|
||||||
|
self.download_btn.setText("Downloading...")
|
||||||
|
# mark the start of downloads; this triggers the labels
|
||||||
|
self._on_progress("system", "starting", "Processing, please wait...")
|
||||||
|
self.worker = PreDownloadWorker(self)
|
||||||
|
self.worker.progress.connect(self._on_progress)
|
||||||
|
self.worker.category_done.connect(self._on_category_done)
|
||||||
|
self.worker.finished.connect(self._on_download_finished)
|
||||||
|
self.worker.error.connect(self._on_download_error)
|
||||||
|
self.worker.start()
|
||||||
|
|
||||||
|
def _on_progress(self, category: str, status: str, message: str) -> None:
|
||||||
|
"""Map worker (category, status, message) to UI label updates.
|
||||||
|
|
||||||
|
Status is one of: 'downloading', 'installed', 'downloaded', 'warning', 'starting'.
|
||||||
|
Category is one of: 'voice', 'model', 'spacy', 'config', or 'system'.
|
||||||
|
"""
|
||||||
|
try:
|
||||||
|
# If the category targets a specific label, update directly
|
||||||
|
if category in self.status_map:
|
||||||
|
lbl, prefix = self.status_map[category]
|
||||||
|
if not lbl:
|
||||||
|
return
|
||||||
|
# Compose message and set color based on status token
|
||||||
|
full_text = prefix + message
|
||||||
|
if len(full_text) > 60:
|
||||||
|
display_text = full_text[:57] + "..."
|
||||||
|
lbl.setText(display_text)
|
||||||
|
lbl.setToolTip(full_text)
|
||||||
|
else:
|
||||||
|
lbl.setText(full_text)
|
||||||
|
lbl.setToolTip("") # Clear tooltip if not needed
|
||||||
|
if status == "downloading":
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['ORANGE']};")
|
||||||
|
elif status in ("installed", "downloaded"):
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['GREEN']};")
|
||||||
|
elif status == "warning":
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['RED']};")
|
||||||
|
elif status == "error":
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['RED']};")
|
||||||
|
return
|
||||||
|
|
||||||
|
# System-level messages
|
||||||
|
if category == "system":
|
||||||
|
if status == "starting":
|
||||||
|
for k in self.status_map:
|
||||||
|
lbl, prefix = self.status_map[k]
|
||||||
|
if lbl:
|
||||||
|
lbl.setText(prefix + "Processing, please wait...")
|
||||||
|
lbl.setStyleSheet(f"color: {COLORS['ORANGE']};")
|
||||||
|
# other system statuses don't require action
|
||||||
|
return
|
||||||
|
except Exception:
|
||||||
|
# Do not let UI thread crash on unexpected worker message
|
||||||
|
pass
|
||||||
|
|
||||||
|
def _on_category_done(self, category: str) -> None:
|
||||||
|
for key in self.category_map.get(category, []):
|
||||||
|
self._set_status(key, "✓ Downloaded", COLORS["GREEN"])
|
||||||
|
|
||||||
|
def _on_download_finished(self) -> None:
|
||||||
|
self.has_missing = False
|
||||||
|
self.download_btn.setText("Download all")
|
||||||
|
self.download_btn.setEnabled(False)
|
||||||
|
|
||||||
|
def _on_download_error(self, error_msg: str) -> None:
|
||||||
|
self.download_btn.setText("Download all")
|
||||||
|
self.download_btn.setEnabled(True)
|
||||||
|
for key in self.status_map:
|
||||||
|
self._set_status(key, f"✗ Error - {error_msg}", COLORS["RED"])
|
||||||
|
|
||||||
|
def _handle_close(self) -> None:
|
||||||
|
if self.worker and self.worker.isRunning():
|
||||||
|
self.worker.cancel()
|
||||||
|
self.worker.wait(2000)
|
||||||
|
self.accept()
|
||||||
|
|
||||||
|
def closeEvent(self, event) -> None:
|
||||||
|
if self.worker and self.worker.isRunning():
|
||||||
|
self.worker.cancel()
|
||||||
|
self.worker.wait(2000)
|
||||||
|
super().closeEvent(event)
|
||||||
@@ -0,0 +1,881 @@
|
|||||||
|
# a simple window with a list of items in the queue, no checkboxes
|
||||||
|
# button to remove an item from the queue
|
||||||
|
# button to clear the queue
|
||||||
|
|
||||||
|
from PyQt6.QtWidgets import (
|
||||||
|
QDialog,
|
||||||
|
QVBoxLayout,
|
||||||
|
QHBoxLayout,
|
||||||
|
QDialogButtonBox,
|
||||||
|
QPushButton,
|
||||||
|
QListWidget,
|
||||||
|
QListWidgetItem,
|
||||||
|
QFileIconProvider,
|
||||||
|
QLabel,
|
||||||
|
QWidget,
|
||||||
|
QSizePolicy,
|
||||||
|
QAbstractItemView,
|
||||||
|
QCheckBox,
|
||||||
|
)
|
||||||
|
from PyQt6.QtCore import QFileInfo, Qt
|
||||||
|
from abogen.constants import COLORS
|
||||||
|
from copy import deepcopy
|
||||||
|
from PyQt6.QtGui import QFontMetrics
|
||||||
|
from abogen.utils import load_config, save_config
|
||||||
|
|
||||||
|
# Define attributes that are safe to override with global settings
|
||||||
|
OVERRIDE_FIELDS = [
|
||||||
|
"lang_code",
|
||||||
|
"speed",
|
||||||
|
"voice",
|
||||||
|
"save_option",
|
||||||
|
"output_folder",
|
||||||
|
"subtitle_mode",
|
||||||
|
"output_format",
|
||||||
|
"replace_single_newlines",
|
||||||
|
"use_silent_gaps",
|
||||||
|
"subtitle_speed_method",
|
||||||
|
"word_substitutions_enabled",
|
||||||
|
"word_substitutions_list",
|
||||||
|
"case_sensitive_substitutions",
|
||||||
|
"replace_all_caps",
|
||||||
|
"replace_numerals",
|
||||||
|
"fix_nonstandard_punctuation",
|
||||||
|
]
|
||||||
|
|
||||||
|
|
||||||
|
class ElidedLabel(QLabel):
|
||||||
|
def __init__(self, text):
|
||||||
|
super().__init__(text)
|
||||||
|
self._full_text = text
|
||||||
|
self.setSizePolicy(QSizePolicy.Policy.Expanding, QSizePolicy.Policy.Preferred)
|
||||||
|
self.setTextFormat(Qt.TextFormat.PlainText)
|
||||||
|
|
||||||
|
def setText(self, text):
|
||||||
|
self._full_text = text
|
||||||
|
super().setText(text)
|
||||||
|
self.update()
|
||||||
|
|
||||||
|
def resizeEvent(self, event):
|
||||||
|
metrics = QFontMetrics(self.font())
|
||||||
|
elided = metrics.elidedText(
|
||||||
|
self._full_text, Qt.TextElideMode.ElideRight, self.width()
|
||||||
|
)
|
||||||
|
super().setText(elided)
|
||||||
|
super().resizeEvent(event)
|
||||||
|
|
||||||
|
def fullText(self):
|
||||||
|
return self._full_text
|
||||||
|
|
||||||
|
|
||||||
|
class QueueListItemWidget(QWidget):
|
||||||
|
def __init__(self, file_name, char_count):
|
||||||
|
super().__init__()
|
||||||
|
layout = QHBoxLayout()
|
||||||
|
layout.setContentsMargins(12, 0, 6, 0)
|
||||||
|
layout.setSpacing(0)
|
||||||
|
import os
|
||||||
|
|
||||||
|
name_label = ElidedLabel(os.path.basename(file_name))
|
||||||
|
char_label = QLabel(f"Chars: {char_count}")
|
||||||
|
char_label.setStyleSheet(f"color: {COLORS['LIGHT_DISABLED']};")
|
||||||
|
char_label.setAlignment(
|
||||||
|
Qt.AlignmentFlag.AlignRight | Qt.AlignmentFlag.AlignVCenter
|
||||||
|
)
|
||||||
|
char_label.setSizePolicy(
|
||||||
|
QSizePolicy.Policy.Minimum, QSizePolicy.Policy.Preferred
|
||||||
|
)
|
||||||
|
layout.addWidget(name_label, 1)
|
||||||
|
layout.addWidget(char_label, 0)
|
||||||
|
self.setLayout(layout)
|
||||||
|
|
||||||
|
|
||||||
|
class DroppableQueueListWidget(QListWidget):
|
||||||
|
def __init__(self, parent_dialog):
|
||||||
|
super().__init__()
|
||||||
|
self.parent_dialog = parent_dialog
|
||||||
|
self.setAcceptDrops(True)
|
||||||
|
# Overlay for drag hover
|
||||||
|
self.drag_overlay = QLabel("", self)
|
||||||
|
self.drag_overlay.setAlignment(Qt.AlignmentFlag.AlignCenter)
|
||||||
|
self.drag_overlay.setStyleSheet(
|
||||||
|
f"border:2px dashed {COLORS['BLUE_BORDER_HOVER']}; border-radius:5px; padding:20px; background:{COLORS['BLUE_BG_HOVER']};"
|
||||||
|
)
|
||||||
|
self.drag_overlay.setVisible(False)
|
||||||
|
self.drag_overlay.setAttribute(
|
||||||
|
Qt.WidgetAttribute.WA_TransparentForMouseEvents, True
|
||||||
|
)
|
||||||
|
|
||||||
|
def dragEnterEvent(self, event):
|
||||||
|
if event.mimeData().hasUrls():
|
||||||
|
for url in event.mimeData().urls():
|
||||||
|
file_path = url.toLocalFile().lower()
|
||||||
|
if url.isLocalFile() and (
|
||||||
|
file_path.endswith(".txt")
|
||||||
|
or file_path.endswith((".srt", ".ass", ".vtt"))
|
||||||
|
):
|
||||||
|
self.drag_overlay.resize(self.size())
|
||||||
|
self.drag_overlay.setVisible(True)
|
||||||
|
event.acceptProposedAction()
|
||||||
|
return
|
||||||
|
self.drag_overlay.setVisible(False)
|
||||||
|
event.ignore()
|
||||||
|
|
||||||
|
def dragMoveEvent(self, event):
|
||||||
|
if event.mimeData().hasUrls():
|
||||||
|
for url in event.mimeData().urls():
|
||||||
|
file_path = url.toLocalFile().lower()
|
||||||
|
if url.isLocalFile() and (
|
||||||
|
file_path.endswith(".txt")
|
||||||
|
or file_path.endswith((".srt", ".ass", ".vtt"))
|
||||||
|
):
|
||||||
|
event.acceptProposedAction()
|
||||||
|
return
|
||||||
|
event.ignore()
|
||||||
|
|
||||||
|
def dragLeaveEvent(self, event):
|
||||||
|
self.drag_overlay.setVisible(False)
|
||||||
|
event.accept()
|
||||||
|
|
||||||
|
def dropEvent(self, event):
|
||||||
|
self.drag_overlay.setVisible(False)
|
||||||
|
if event.mimeData().hasUrls():
|
||||||
|
file_paths = [
|
||||||
|
url.toLocalFile()
|
||||||
|
for url in event.mimeData().urls()
|
||||||
|
if url.isLocalFile()
|
||||||
|
and (
|
||||||
|
url.toLocalFile().lower().endswith(".txt")
|
||||||
|
or url.toLocalFile().lower().endswith((".srt", ".ass", ".vtt"))
|
||||||
|
)
|
||||||
|
]
|
||||||
|
if file_paths:
|
||||||
|
self.parent_dialog.add_files_from_paths(file_paths)
|
||||||
|
event.acceptProposedAction()
|
||||||
|
else:
|
||||||
|
event.ignore()
|
||||||
|
else:
|
||||||
|
event.ignore()
|
||||||
|
|
||||||
|
def resizeEvent(self, event):
|
||||||
|
super().resizeEvent(event)
|
||||||
|
if hasattr(self, "drag_overlay"):
|
||||||
|
self.drag_overlay.resize(self.size())
|
||||||
|
|
||||||
|
|
||||||
|
class QueueManager(QDialog):
|
||||||
|
def __init__(self, parent, queue: list, title="Queue Manager", size=(600, 700)):
|
||||||
|
super().__init__()
|
||||||
|
self.queue = queue
|
||||||
|
self._original_queue = deepcopy(
|
||||||
|
queue
|
||||||
|
) # Store a deep copy of the original queue
|
||||||
|
self.parent = parent
|
||||||
|
self.config = load_config() # Load config for persistence
|
||||||
|
|
||||||
|
layout = QVBoxLayout()
|
||||||
|
layout.setContentsMargins(15, 15, 15, 15) # set main layout margins
|
||||||
|
layout.setSpacing(12) # set spacing between widgets in main layout
|
||||||
|
# list of queued items
|
||||||
|
self.listwidget = DroppableQueueListWidget(self)
|
||||||
|
self.listwidget.setSelectionMode(
|
||||||
|
QAbstractItemView.SelectionMode.ExtendedSelection
|
||||||
|
)
|
||||||
|
self.listwidget.setAlternatingRowColors(True)
|
||||||
|
self.listwidget.setContextMenuPolicy(Qt.ContextMenuPolicy.CustomContextMenu)
|
||||||
|
self.listwidget.customContextMenuRequested.connect(self.show_context_menu)
|
||||||
|
# Add informative instructions at the top
|
||||||
|
instructions = QLabel(
|
||||||
|
"<h2>How Queue Works?</h2>"
|
||||||
|
"You can add text and subtitle files (.txt, .srt, .ass, .vtt) directly using the '<b>Add files</b>' button below. "
|
||||||
|
"To add PDF, EPUB or markdown files, use the input box in the main window and click the <b>'Add to Queue'</b> button. "
|
||||||
|
"By default, each file in the queue keeps the configuration settings active when they were added. "
|
||||||
|
"Enabling the <b>'Override item settings with current selection'</b> option below will force all items to use the configuration currently selected in the main window. "
|
||||||
|
"You can view each file's configuration by hovering over them."
|
||||||
|
)
|
||||||
|
instructions.setAlignment(Qt.AlignmentFlag.AlignLeft)
|
||||||
|
instructions.setWordWrap(True)
|
||||||
|
layout.addWidget(instructions)
|
||||||
|
|
||||||
|
# Override Checkbox
|
||||||
|
self.override_chk = QCheckBox("Override item settings with current selection")
|
||||||
|
self.override_chk.setToolTip(
|
||||||
|
"If checked, all items in the queue will be processed using the \n"
|
||||||
|
"settings currently selected in the main window, ignoring their saved state."
|
||||||
|
)
|
||||||
|
# Load saved state (default to False)
|
||||||
|
self.override_chk.setChecked(self.config.get("queue_override_settings", False))
|
||||||
|
# Trigger process_queue to update tooltips immediately when toggled
|
||||||
|
self.override_chk.stateChanged.connect(self.process_queue)
|
||||||
|
self.override_chk.setStyleSheet("margin-bottom: 8px;")
|
||||||
|
layout.addWidget(self.override_chk)
|
||||||
|
|
||||||
|
# Overlay label for empty queue
|
||||||
|
self.empty_overlay = QLabel(
|
||||||
|
"Drag and drop your text or subtitle files here or use the 'Add files' button.",
|
||||||
|
self.listwidget,
|
||||||
|
)
|
||||||
|
self.empty_overlay.setAlignment(Qt.AlignmentFlag.AlignCenter)
|
||||||
|
self.empty_overlay.setStyleSheet(
|
||||||
|
f"color: {COLORS['LIGHT_DISABLED']}; background: transparent; padding: 20px;"
|
||||||
|
)
|
||||||
|
self.empty_overlay.setWordWrap(True)
|
||||||
|
self.empty_overlay.setAttribute(
|
||||||
|
Qt.WidgetAttribute.WA_TransparentForMouseEvents, True
|
||||||
|
)
|
||||||
|
self.empty_overlay.hide()
|
||||||
|
# add queue items to the list
|
||||||
|
self.process_queue()
|
||||||
|
|
||||||
|
button_row = QHBoxLayout()
|
||||||
|
button_row.setContentsMargins(0, 0, 0, 0) # optional: no margins for button row
|
||||||
|
button_row.setSpacing(7) # set spacing between buttons
|
||||||
|
# Add files button
|
||||||
|
add_files_button = QPushButton("Add files")
|
||||||
|
add_files_button.setFixedHeight(40)
|
||||||
|
add_files_button.clicked.connect(self.add_more_files)
|
||||||
|
button_row.addWidget(add_files_button)
|
||||||
|
|
||||||
|
# Remove button
|
||||||
|
self.remove_button = QPushButton("Remove selected")
|
||||||
|
self.remove_button.setFixedHeight(40)
|
||||||
|
self.remove_button.clicked.connect(self.remove_item)
|
||||||
|
button_row.addWidget(self.remove_button)
|
||||||
|
|
||||||
|
# Clear button
|
||||||
|
self.clear_button = QPushButton("Clear Queue")
|
||||||
|
self.clear_button.setFixedHeight(40)
|
||||||
|
self.clear_button.clicked.connect(self.clear_queue)
|
||||||
|
button_row.addWidget(self.clear_button)
|
||||||
|
|
||||||
|
layout.addLayout(button_row)
|
||||||
|
layout.addWidget(self.listwidget)
|
||||||
|
|
||||||
|
# Connect selection change to update button state
|
||||||
|
self.listwidget.currentItemChanged.connect(self.update_button_states)
|
||||||
|
self.listwidget.itemSelectionChanged.connect(self.update_button_states)
|
||||||
|
|
||||||
|
buttons = QDialogButtonBox(
|
||||||
|
QDialogButtonBox.StandardButton.Ok | QDialogButtonBox.StandardButton.Cancel,
|
||||||
|
self,
|
||||||
|
)
|
||||||
|
buttons.accepted.connect(self.accept)
|
||||||
|
buttons.rejected.connect(self.reject)
|
||||||
|
|
||||||
|
layout.addWidget(buttons)
|
||||||
|
|
||||||
|
self.setLayout(layout)
|
||||||
|
|
||||||
|
self.setWindowTitle(title)
|
||||||
|
self.resize(*size)
|
||||||
|
|
||||||
|
self.update_button_states()
|
||||||
|
|
||||||
|
def process_queue(self):
|
||||||
|
"""Process the queue items."""
|
||||||
|
import os
|
||||||
|
|
||||||
|
self.listwidget.clear()
|
||||||
|
if not self.queue:
|
||||||
|
self.empty_overlay.show()
|
||||||
|
self.update_button_states()
|
||||||
|
return
|
||||||
|
else:
|
||||||
|
self.empty_overlay.hide()
|
||||||
|
|
||||||
|
# Get current global settings and checkbox state for overrides
|
||||||
|
current_global_settings = self.get_current_attributes()
|
||||||
|
is_override_active = self.override_chk.isChecked()
|
||||||
|
|
||||||
|
icon_provider = QFileIconProvider()
|
||||||
|
for item in self.queue:
|
||||||
|
# Dynamic Attribute Retrieval Helper
|
||||||
|
def get_val(attr, default=""):
|
||||||
|
# If override is ON and attr is overrideable, use global setting
|
||||||
|
if is_override_active and attr in OVERRIDE_FIELDS:
|
||||||
|
return current_global_settings.get(attr, default)
|
||||||
|
# Otherwise return the item's saved attribute
|
||||||
|
return getattr(item, attr, default)
|
||||||
|
|
||||||
|
# Determine display file path (prefer save_base_path for original file)
|
||||||
|
display_file_path = getattr(item, "save_base_path", None) or item.file_name
|
||||||
|
processing_file_path = item.file_name
|
||||||
|
|
||||||
|
# Normalize paths for consistent display (fixes Windows path separator issues)
|
||||||
|
display_file_path = (
|
||||||
|
os.path.normpath(display_file_path)
|
||||||
|
if display_file_path
|
||||||
|
else display_file_path
|
||||||
|
)
|
||||||
|
processing_file_path = (
|
||||||
|
os.path.normpath(processing_file_path)
|
||||||
|
if processing_file_path
|
||||||
|
else processing_file_path
|
||||||
|
)
|
||||||
|
|
||||||
|
# Only show the file name, not the full path
|
||||||
|
display_name = display_file_path
|
||||||
|
|
||||||
|
if os.path.sep in display_file_path:
|
||||||
|
display_name = os.path.basename(display_file_path)
|
||||||
|
# Get icon for the display file
|
||||||
|
icon = icon_provider.icon(QFileInfo(display_file_path))
|
||||||
|
list_item = QListWidgetItem()
|
||||||
|
|
||||||
|
# Tooltip Generation
|
||||||
|
tooltip = ""
|
||||||
|
# If override is active, add the warning header on its own line
|
||||||
|
if is_override_active:
|
||||||
|
tooltip += "<b style='color: #ff9900;'>(Global Override Active)</b><br>"
|
||||||
|
|
||||||
|
output_folder = get_val("output_folder")
|
||||||
|
# For plain .txt inputs we don't need to show a separate processing file
|
||||||
|
show_processing = True
|
||||||
|
try:
|
||||||
|
if isinstance(
|
||||||
|
display_file_path, str
|
||||||
|
) and display_file_path.lower().endswith(".txt"):
|
||||||
|
show_processing = False
|
||||||
|
except Exception:
|
||||||
|
show_processing = True
|
||||||
|
|
||||||
|
tooltip += f"<b>Input File:</b> {display_file_path}<br>"
|
||||||
|
if (
|
||||||
|
show_processing
|
||||||
|
and processing_file_path
|
||||||
|
and processing_file_path != display_file_path
|
||||||
|
):
|
||||||
|
tooltip += f"<b>Processing File:</b> {processing_file_path}<br>"
|
||||||
|
|
||||||
|
tooltip += (
|
||||||
|
f"<b>Language:</b> {get_val('lang_code')}<br>"
|
||||||
|
f"<b>Speed:</b> {get_val('speed')}<br>"
|
||||||
|
f"<b>Voice:</b> {get_val('voice')}<br>"
|
||||||
|
f"<b>Save Option:</b> {get_val('save_option')}<br>"
|
||||||
|
)
|
||||||
|
if output_folder not in (None, "", "None"):
|
||||||
|
tooltip += f"<b>Output Folder:</b> {output_folder}<br>"
|
||||||
|
tooltip += (
|
||||||
|
f"<b>Subtitle Mode:</b> {get_val('subtitle_mode')}<br>"
|
||||||
|
f"<b>Output Format:</b> {get_val('output_format')}<br>"
|
||||||
|
f"<b>Characters:</b> {getattr(item, 'total_char_count', '')}<br>"
|
||||||
|
f"<b>Replace Single Newlines:</b> {get_val('replace_single_newlines', True)}<br>"
|
||||||
|
f"<b>Use Silent Gaps:</b> {get_val('use_silent_gaps', False)}<br>"
|
||||||
|
f"<b>Speed Method:</b> {get_val('subtitle_speed_method', 'tts')}"
|
||||||
|
)
|
||||||
|
# Add book handler options if present (Preserve logic: specific to file structure)
|
||||||
|
save_chapters_separately = getattr(item, "save_chapters_separately", None)
|
||||||
|
merge_chapters_at_end = getattr(item, "merge_chapters_at_end", None)
|
||||||
|
if save_chapters_separately is not None:
|
||||||
|
tooltip += f"<br><b>Save chapters separately:</b> {'Yes' if save_chapters_separately else 'No'}"
|
||||||
|
# Only show merge option if saving chapters separately
|
||||||
|
if save_chapters_separately and merge_chapters_at_end is not None:
|
||||||
|
tooltip += f"<br><b>Merge chapters at the end:</b> {'Yes' if merge_chapters_at_end else 'No'}"
|
||||||
|
list_item.setToolTip(tooltip)
|
||||||
|
list_item.setIcon(icon)
|
||||||
|
# Store both paths for context menu
|
||||||
|
list_item.setData(
|
||||||
|
Qt.ItemDataRole.UserRole,
|
||||||
|
{
|
||||||
|
"display_path": display_file_path,
|
||||||
|
"processing_path": processing_file_path,
|
||||||
|
},
|
||||||
|
)
|
||||||
|
# Use custom widget for display
|
||||||
|
char_count = getattr(item, "total_char_count", 0)
|
||||||
|
widget = QueueListItemWidget(display_file_path, char_count)
|
||||||
|
self.listwidget.addItem(list_item)
|
||||||
|
self.listwidget.setItemWidget(list_item, widget)
|
||||||
|
self.update_button_states()
|
||||||
|
|
||||||
|
def remove_item(self):
|
||||||
|
items = self.listwidget.selectedItems()
|
||||||
|
if not items:
|
||||||
|
return
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
|
||||||
|
# Remove by index to ensure correct mapping
|
||||||
|
rows = sorted([self.listwidget.row(item) for item in items], reverse=True)
|
||||||
|
# Warn user if removing multiple files
|
||||||
|
if len(rows) > 1:
|
||||||
|
reply = QMessageBox.question(
|
||||||
|
self,
|
||||||
|
"Confirm Remove",
|
||||||
|
f"Are you sure you want to remove {len(rows)} selected items from the queue?",
|
||||||
|
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
||||||
|
QMessageBox.StandardButton.No,
|
||||||
|
)
|
||||||
|
if reply != QMessageBox.StandardButton.Yes:
|
||||||
|
return
|
||||||
|
for row in rows:
|
||||||
|
if 0 <= row < len(self.queue):
|
||||||
|
del self.queue[row]
|
||||||
|
self.process_queue()
|
||||||
|
self.update_button_states()
|
||||||
|
|
||||||
|
def clear_queue(self):
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
|
||||||
|
if len(self.queue) > 1:
|
||||||
|
reply = QMessageBox.question(
|
||||||
|
self,
|
||||||
|
"Confirm Clear Queue",
|
||||||
|
f"Are you sure you want to clear {len(self.queue)} items from the queue?",
|
||||||
|
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
||||||
|
QMessageBox.StandardButton.No,
|
||||||
|
)
|
||||||
|
if reply != QMessageBox.StandardButton.Yes:
|
||||||
|
return
|
||||||
|
self.queue.clear()
|
||||||
|
self.listwidget.clear()
|
||||||
|
self.empty_overlay.resize(
|
||||||
|
self.listwidget.size()
|
||||||
|
) # Ensure overlay is sized correctly
|
||||||
|
self.empty_overlay.show() # Show the overlay when queue is empty
|
||||||
|
self.update_button_states()
|
||||||
|
|
||||||
|
def get_queue(self):
|
||||||
|
return self.queue
|
||||||
|
|
||||||
|
def get_current_attributes(self):
|
||||||
|
# Fetch current attribute values from the parent abogen GUI
|
||||||
|
attrs = {}
|
||||||
|
parent = self.parent
|
||||||
|
if parent is not None:
|
||||||
|
# lang_code: use parent's get_voice_formula and get_selected_lang
|
||||||
|
if hasattr(parent, "get_voice_formula") and hasattr(
|
||||||
|
parent, "get_selected_lang"
|
||||||
|
):
|
||||||
|
voice_formula = parent.get_voice_formula()
|
||||||
|
attrs["lang_code"] = parent.get_selected_lang(voice_formula)
|
||||||
|
attrs["voice"] = voice_formula
|
||||||
|
else:
|
||||||
|
attrs["lang_code"] = getattr(parent, "selected_lang", "")
|
||||||
|
attrs["voice"] = getattr(parent, "selected_voice", "")
|
||||||
|
# speed
|
||||||
|
if hasattr(parent, "speed_slider"):
|
||||||
|
attrs["speed"] = parent.speed_slider.value() / 100.0
|
||||||
|
else:
|
||||||
|
attrs["speed"] = getattr(parent, "speed", 1.0)
|
||||||
|
# save_option
|
||||||
|
attrs["save_option"] = getattr(parent, "save_option", "")
|
||||||
|
# output_folder
|
||||||
|
attrs["output_folder"] = getattr(parent, "selected_output_folder", "")
|
||||||
|
# subtitle_mode
|
||||||
|
if hasattr(parent, "get_actual_subtitle_mode"):
|
||||||
|
attrs["subtitle_mode"] = parent.get_actual_subtitle_mode()
|
||||||
|
else:
|
||||||
|
attrs["subtitle_mode"] = getattr(parent, "subtitle_mode", "")
|
||||||
|
# output_format
|
||||||
|
attrs["output_format"] = getattr(parent, "selected_format", "")
|
||||||
|
# total_char_count
|
||||||
|
attrs["total_char_count"] = getattr(parent, "char_count", "")
|
||||||
|
# replace_single_newlines
|
||||||
|
attrs["replace_single_newlines"] = getattr(
|
||||||
|
parent, "replace_single_newlines", True
|
||||||
|
)
|
||||||
|
# use_silent_gaps
|
||||||
|
attrs["use_silent_gaps"] = getattr(parent, "use_silent_gaps", False)
|
||||||
|
# subtitle_speed_method
|
||||||
|
attrs["subtitle_speed_method"] = getattr(
|
||||||
|
parent, "subtitle_speed_method", "tts"
|
||||||
|
)
|
||||||
|
# word substitutions
|
||||||
|
attrs["word_substitutions_enabled"] = getattr(
|
||||||
|
parent, "word_substitutions_enabled", False
|
||||||
|
)
|
||||||
|
attrs["word_substitutions_list"] = getattr(
|
||||||
|
parent, "word_substitutions_list", ""
|
||||||
|
)
|
||||||
|
attrs["case_sensitive_substitutions"] = getattr(
|
||||||
|
parent, "case_sensitive_substitutions", False
|
||||||
|
)
|
||||||
|
attrs["replace_all_caps"] = getattr(parent, "replace_all_caps", False)
|
||||||
|
attrs["replace_numerals"] = getattr(parent, "replace_numerals", False)
|
||||||
|
attrs["fix_nonstandard_punctuation"] = getattr(
|
||||||
|
parent, "fix_nonstandard_punctuation", False
|
||||||
|
)
|
||||||
|
# book handler options
|
||||||
|
attrs["save_chapters_separately"] = getattr(
|
||||||
|
parent, "save_chapters_separately", None
|
||||||
|
)
|
||||||
|
attrs["merge_chapters_at_end"] = getattr(
|
||||||
|
parent, "merge_chapters_at_end", None
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
# fallback: empty values
|
||||||
|
attrs = {
|
||||||
|
k: ""
|
||||||
|
for k in [
|
||||||
|
"lang_code",
|
||||||
|
"speed",
|
||||||
|
"voice",
|
||||||
|
"save_option",
|
||||||
|
"output_folder",
|
||||||
|
"subtitle_mode",
|
||||||
|
"output_format",
|
||||||
|
"total_char_count",
|
||||||
|
"replace_single_newlines",
|
||||||
|
]
|
||||||
|
}
|
||||||
|
attrs["save_chapters_separately"] = None
|
||||||
|
attrs["merge_chapters_at_end"] = None
|
||||||
|
return attrs
|
||||||
|
|
||||||
|
def add_files_from_paths(self, file_paths):
|
||||||
|
from abogen.domain.text_utils import calculate_text_length
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
import os
|
||||||
|
|
||||||
|
current_attrs = self.get_current_attributes()
|
||||||
|
duplicates = []
|
||||||
|
for file_path in file_paths:
|
||||||
|
|
||||||
|
class QueueItem:
|
||||||
|
pass
|
||||||
|
|
||||||
|
item = QueueItem()
|
||||||
|
item.file_name = file_path
|
||||||
|
item.save_base_path = (
|
||||||
|
file_path # For .txt files, processing and save paths are the same
|
||||||
|
)
|
||||||
|
for attr, value in current_attrs.items():
|
||||||
|
setattr(item, attr, value)
|
||||||
|
# Override subtitle_mode to "Disabled" for subtitle files
|
||||||
|
if file_path.lower().endswith((".srt", ".ass", ".vtt")):
|
||||||
|
item.subtitle_mode = "Disabled"
|
||||||
|
# Read file content and calculate total_char_count using calculate_text_length
|
||||||
|
try:
|
||||||
|
with open(file_path, "r", encoding="utf-8", errors="ignore") as f:
|
||||||
|
file_content = f.read()
|
||||||
|
item.total_char_count = calculate_text_length(file_content)
|
||||||
|
except Exception:
|
||||||
|
item.total_char_count = 0
|
||||||
|
# Prevent adding duplicate items to the queue (check all attributes)
|
||||||
|
is_duplicate = False
|
||||||
|
for queued_item in self.queue:
|
||||||
|
if (
|
||||||
|
getattr(queued_item, "file_name", None)
|
||||||
|
== getattr(item, "file_name", None)
|
||||||
|
and getattr(queued_item, "lang_code", None)
|
||||||
|
== getattr(item, "lang_code", None)
|
||||||
|
and getattr(queued_item, "speed", None)
|
||||||
|
== getattr(item, "speed", None)
|
||||||
|
and getattr(queued_item, "voice", None)
|
||||||
|
== getattr(item, "voice", None)
|
||||||
|
and getattr(queued_item, "save_option", None)
|
||||||
|
== getattr(item, "save_option", None)
|
||||||
|
and getattr(queued_item, "output_folder", None)
|
||||||
|
== getattr(item, "output_folder", None)
|
||||||
|
and getattr(queued_item, "subtitle_mode", None)
|
||||||
|
== getattr(item, "subtitle_mode", None)
|
||||||
|
and getattr(queued_item, "output_format", None)
|
||||||
|
== getattr(item, "output_format", None)
|
||||||
|
and getattr(queued_item, "total_char_count", None)
|
||||||
|
== getattr(item, "total_char_count", None)
|
||||||
|
and getattr(queued_item, "replace_single_newlines", True)
|
||||||
|
== getattr(item, "replace_single_newlines", True)
|
||||||
|
and getattr(queued_item, "use_silent_gaps", False)
|
||||||
|
== getattr(item, "use_silent_gaps", False)
|
||||||
|
and getattr(queued_item, "subtitle_speed_method", "tts")
|
||||||
|
== getattr(item, "subtitle_speed_method", "tts")
|
||||||
|
and getattr(queued_item, "save_base_path", None)
|
||||||
|
== getattr(item, "save_base_path", None)
|
||||||
|
and getattr(queued_item, "save_chapters_separately", None)
|
||||||
|
== getattr(item, "save_chapters_separately", None)
|
||||||
|
and getattr(queued_item, "merge_chapters_at_end", None)
|
||||||
|
== getattr(item, "merge_chapters_at_end", None)
|
||||||
|
):
|
||||||
|
is_duplicate = True
|
||||||
|
break
|
||||||
|
if is_duplicate:
|
||||||
|
duplicates.append(os.path.basename(file_path))
|
||||||
|
continue
|
||||||
|
self.queue.append(item)
|
||||||
|
if duplicates:
|
||||||
|
QMessageBox.warning(
|
||||||
|
self,
|
||||||
|
"Duplicate Item(s)",
|
||||||
|
f"Skipping {len(duplicates)} file(s) with the same attributes, already in the queue.",
|
||||||
|
)
|
||||||
|
self.process_queue()
|
||||||
|
self.update_button_states()
|
||||||
|
|
||||||
|
def add_more_files(self):
|
||||||
|
from PyQt6.QtWidgets import QFileDialog
|
||||||
|
|
||||||
|
# Allow .txt, .srt, .ass, and .vtt files
|
||||||
|
files, _ = QFileDialog.getOpenFileNames(
|
||||||
|
self,
|
||||||
|
"Select text or subtitle files",
|
||||||
|
"",
|
||||||
|
"Supported Files (*.txt *.srt *.ass *.vtt)",
|
||||||
|
)
|
||||||
|
if not files:
|
||||||
|
return
|
||||||
|
self.add_files_from_paths(files)
|
||||||
|
|
||||||
|
def resizeEvent(self, event):
|
||||||
|
super().resizeEvent(event)
|
||||||
|
if hasattr(self, "empty_overlay"):
|
||||||
|
self.empty_overlay.resize(self.listwidget.size())
|
||||||
|
|
||||||
|
def update_button_states(self):
|
||||||
|
# Enable Remove if at least one item is selected, else disable
|
||||||
|
if hasattr(self, "remove_button"):
|
||||||
|
selected_count = len(self.listwidget.selectedItems())
|
||||||
|
self.remove_button.setEnabled(selected_count > 0)
|
||||||
|
if selected_count > 1:
|
||||||
|
self.remove_button.setText(f"Remove selected ({selected_count})")
|
||||||
|
else:
|
||||||
|
self.remove_button.setText("Remove selected")
|
||||||
|
# Disable Clear if queue is empty
|
||||||
|
if hasattr(self, "clear_button"):
|
||||||
|
self.clear_button.setEnabled(bool(self.queue))
|
||||||
|
|
||||||
|
def show_context_menu(self, pos):
|
||||||
|
from PyQt6.QtWidgets import QMenu
|
||||||
|
from PyQt6.QtGui import QAction, QDesktopServices
|
||||||
|
from PyQt6.QtCore import QUrl
|
||||||
|
import os
|
||||||
|
|
||||||
|
global_pos = self.listwidget.viewport().mapToGlobal(pos)
|
||||||
|
selected_items = self.listwidget.selectedItems()
|
||||||
|
menu = QMenu(self)
|
||||||
|
if len(selected_items) == 1:
|
||||||
|
# Add Remove action
|
||||||
|
remove_action = QAction("Remove this item", self)
|
||||||
|
remove_action.triggered.connect(self.remove_item)
|
||||||
|
menu.addAction(remove_action)
|
||||||
|
|
||||||
|
# Get paths for determining if it's a document input
|
||||||
|
item = selected_items[0]
|
||||||
|
paths = item.data(Qt.ItemDataRole.UserRole)
|
||||||
|
if isinstance(paths, dict):
|
||||||
|
display_path = paths.get("display_path", "")
|
||||||
|
processing_path = paths.get("processing_path", "")
|
||||||
|
else:
|
||||||
|
display_path = paths
|
||||||
|
processing_path = paths
|
||||||
|
|
||||||
|
doc_exts = (".md", ".markdown", ".pdf", ".epub")
|
||||||
|
is_document_input = (
|
||||||
|
isinstance(display_path, str)
|
||||||
|
and display_path.lower().endswith(doc_exts)
|
||||||
|
) or (
|
||||||
|
isinstance(processing_path, str)
|
||||||
|
and processing_path.lower().endswith(doc_exts)
|
||||||
|
)
|
||||||
|
|
||||||
|
# Add Open file action(s)
|
||||||
|
def open_file_by_path(path_label: str):
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
|
||||||
|
p = display_path if path_label == "display" else processing_path
|
||||||
|
if not p:
|
||||||
|
QMessageBox.warning(
|
||||||
|
self, "File Not Found", "Path is not available."
|
||||||
|
)
|
||||||
|
return
|
||||||
|
|
||||||
|
# Find the queue item and resolve the target path
|
||||||
|
target_path = None
|
||||||
|
for q in self.queue:
|
||||||
|
if (
|
||||||
|
getattr(q, "save_base_path", None) == display_path
|
||||||
|
or q.file_name == display_path
|
||||||
|
):
|
||||||
|
if path_label == "display":
|
||||||
|
target_path = (
|
||||||
|
getattr(q, "save_base_path", None) or q.file_name
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
target_path = q.file_name
|
||||||
|
break
|
||||||
|
if (
|
||||||
|
getattr(q, "save_base_path", None) == processing_path
|
||||||
|
or q.file_name == processing_path
|
||||||
|
):
|
||||||
|
if path_label == "display":
|
||||||
|
target_path = (
|
||||||
|
getattr(q, "save_base_path", None) or q.file_name
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
target_path = q.file_name
|
||||||
|
break
|
||||||
|
|
||||||
|
# Fallback to the raw path if resolution failed
|
||||||
|
if not target_path:
|
||||||
|
target_path = p
|
||||||
|
|
||||||
|
if not os.path.exists(target_path):
|
||||||
|
QMessageBox.warning(
|
||||||
|
self, "File Not Found", f"The file does not exist."
|
||||||
|
)
|
||||||
|
return
|
||||||
|
QDesktopServices.openUrl(QUrl.fromLocalFile(target_path))
|
||||||
|
|
||||||
|
if is_document_input:
|
||||||
|
# For documents, show two open options
|
||||||
|
open_processed_action = QAction("Open processed file", self)
|
||||||
|
open_processed_action.triggered.connect(
|
||||||
|
lambda: open_file_by_path("processing")
|
||||||
|
)
|
||||||
|
menu.addAction(open_processed_action)
|
||||||
|
|
||||||
|
open_input_action = QAction("Open input file", self)
|
||||||
|
open_input_action.triggered.connect(
|
||||||
|
lambda: open_file_by_path("display")
|
||||||
|
)
|
||||||
|
menu.addAction(open_input_action)
|
||||||
|
else:
|
||||||
|
# For plain text files, show single open option
|
||||||
|
open_file_action = QAction("Open file", self)
|
||||||
|
open_file_action.triggered.connect(lambda: open_file_by_path("display"))
|
||||||
|
menu.addAction(open_file_action)
|
||||||
|
|
||||||
|
# Add Go to folder action
|
||||||
|
# If the queued item represents a converted document (markdown, pdf, epub)
|
||||||
|
# show two actions: Go to processed file (the cached .txt) and Go to input file (original source)
|
||||||
|
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
|
||||||
|
def open_folder_for(path_label: str):
|
||||||
|
# path_label should be either 'display' or 'processing'
|
||||||
|
p = display_path if path_label == "display" else processing_path
|
||||||
|
if not p:
|
||||||
|
QMessageBox.warning(
|
||||||
|
self, "File Not Found", "Path is not available."
|
||||||
|
)
|
||||||
|
return
|
||||||
|
# If the stored path is the display path (original) but the actual file may be
|
||||||
|
# stored on the queue object differently, try to resolve via the queue entry.
|
||||||
|
target_path = None
|
||||||
|
for q in self.queue:
|
||||||
|
if (
|
||||||
|
getattr(q, "save_base_path", None) == display_path
|
||||||
|
or q.file_name == display_path
|
||||||
|
):
|
||||||
|
if path_label == "display":
|
||||||
|
target_path = (
|
||||||
|
getattr(q, "save_base_path", None) or q.file_name
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
target_path = q.file_name
|
||||||
|
break
|
||||||
|
if (
|
||||||
|
getattr(q, "save_base_path", None) == processing_path
|
||||||
|
or q.file_name == processing_path
|
||||||
|
):
|
||||||
|
if path_label == "display":
|
||||||
|
target_path = (
|
||||||
|
getattr(q, "save_base_path", None) or q.file_name
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
target_path = q.file_name
|
||||||
|
break
|
||||||
|
# Fallback to the raw path if resolution failed
|
||||||
|
if not target_path:
|
||||||
|
target_path = p
|
||||||
|
|
||||||
|
if not os.path.exists(target_path):
|
||||||
|
QMessageBox.warning(
|
||||||
|
self,
|
||||||
|
"File Not Found",
|
||||||
|
f"The file does not exist: {target_path}",
|
||||||
|
)
|
||||||
|
return
|
||||||
|
folder = os.path.dirname(target_path)
|
||||||
|
if os.path.exists(folder):
|
||||||
|
QDesktopServices.openUrl(QUrl.fromLocalFile(folder))
|
||||||
|
|
||||||
|
if is_document_input:
|
||||||
|
processed_action = QAction("Go to processed file", self)
|
||||||
|
processed_action.triggered.connect(
|
||||||
|
lambda: open_folder_for("processing")
|
||||||
|
)
|
||||||
|
menu.addAction(processed_action)
|
||||||
|
|
||||||
|
input_action = QAction("Go to input file", self)
|
||||||
|
input_action.triggered.connect(lambda: open_folder_for("display"))
|
||||||
|
menu.addAction(input_action)
|
||||||
|
else:
|
||||||
|
# Default behavior for non-document inputs: single "Go to folder" action
|
||||||
|
go_to_folder_action = QAction("Go to folder", self)
|
||||||
|
|
||||||
|
def go_to_folder():
|
||||||
|
item = selected_items[0]
|
||||||
|
paths = item.data(Qt.ItemDataRole.UserRole)
|
||||||
|
if isinstance(paths, dict):
|
||||||
|
file_path = paths.get(
|
||||||
|
"display_path", paths.get("processing_path", "")
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
file_path = paths # Fallback for old format
|
||||||
|
# Find the queue item
|
||||||
|
for q in self.queue:
|
||||||
|
if (
|
||||||
|
getattr(q, "save_base_path", None) == file_path
|
||||||
|
or q.file_name == file_path
|
||||||
|
):
|
||||||
|
target_path = (
|
||||||
|
getattr(q, "save_base_path", None) or q.file_name
|
||||||
|
)
|
||||||
|
if not os.path.exists(target_path):
|
||||||
|
QMessageBox.warning(
|
||||||
|
self, "File Not Found", f"The file does not exist."
|
||||||
|
)
|
||||||
|
return
|
||||||
|
folder = os.path.dirname(target_path)
|
||||||
|
if os.path.exists(folder):
|
||||||
|
QDesktopServices.openUrl(QUrl.fromLocalFile(folder))
|
||||||
|
break
|
||||||
|
|
||||||
|
go_to_folder_action.triggered.connect(go_to_folder)
|
||||||
|
menu.addAction(go_to_folder_action)
|
||||||
|
|
||||||
|
elif len(selected_items) > 1:
|
||||||
|
remove_action = QAction(f"Remove selected ({len(selected_items)})", self)
|
||||||
|
remove_action.triggered.connect(self.remove_item)
|
||||||
|
menu.addAction(remove_action)
|
||||||
|
# Always add Clear Queue
|
||||||
|
clear_action = QAction("Clear Queue", self)
|
||||||
|
clear_action.triggered.connect(self.clear_queue)
|
||||||
|
menu.addAction(clear_action)
|
||||||
|
menu.exec(global_pos)
|
||||||
|
|
||||||
|
def accept(self):
|
||||||
|
# Save the override state to config so it persists globally
|
||||||
|
self.config["queue_override_settings"] = self.override_chk.isChecked()
|
||||||
|
save_config(self.config)
|
||||||
|
|
||||||
|
super().accept()
|
||||||
|
|
||||||
|
def reject(self):
|
||||||
|
# Cancel: restore original queue
|
||||||
|
from PyQt6.QtWidgets import QMessageBox
|
||||||
|
|
||||||
|
# Warn if user changed a lot (e.g., more than 1 items difference)
|
||||||
|
original_count = len(self._original_queue)
|
||||||
|
current_count = len(self.queue)
|
||||||
|
if abs(original_count - current_count) > 1:
|
||||||
|
reply = QMessageBox.question(
|
||||||
|
self,
|
||||||
|
"Confirm Cancel",
|
||||||
|
f"Are you sure you want to cancel and discard all changes?",
|
||||||
|
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
||||||
|
QMessageBox.StandardButton.No,
|
||||||
|
)
|
||||||
|
if reply != QMessageBox.StandardButton.Yes:
|
||||||
|
return
|
||||||
|
self.queue.clear()
|
||||||
|
self.queue.extend(deepcopy(self._original_queue))
|
||||||
|
super().reject()
|
||||||
|
|
||||||
|
def keyPressEvent(self, event):
|
||||||
|
from PyQt6.QtCore import Qt
|
||||||
|
|
||||||
|
if event.key() == Qt.Key.Key_Delete:
|
||||||
|
self.remove_item()
|
||||||
|
else:
|
||||||
|
super().keyPressEvent(event)
|
||||||
@@ -0,0 +1,28 @@
|
|||||||
|
# represents a queued item - book, chapters, voice, etc.
|
||||||
|
from dataclasses import dataclass
|
||||||
|
|
||||||
|
|
||||||
|
@dataclass
|
||||||
|
class QueuedItem:
|
||||||
|
file_name: str
|
||||||
|
lang_code: str
|
||||||
|
speed: float
|
||||||
|
voice: str
|
||||||
|
save_option: str
|
||||||
|
output_folder: str
|
||||||
|
subtitle_mode: str
|
||||||
|
output_format: str
|
||||||
|
total_char_count: int
|
||||||
|
replace_single_newlines: bool = True
|
||||||
|
use_silent_gaps: bool = False
|
||||||
|
subtitle_speed_method: str = "tts"
|
||||||
|
save_base_path: str = None
|
||||||
|
save_chapters_separately: bool = None
|
||||||
|
merge_chapters_at_end: bool = None
|
||||||
|
# Word Substitution fields
|
||||||
|
word_substitutions_enabled: bool = False
|
||||||
|
word_substitutions_list: str = ""
|
||||||
|
case_sensitive_substitutions: bool = False
|
||||||
|
replace_all_caps: bool = False
|
||||||
|
replace_numerals: bool = False
|
||||||
|
fix_nonstandard_punctuation: bool = False
|
||||||
File diff suppressed because it is too large
Load Diff
+7
-803
@@ -1,807 +1,11 @@
|
|||||||
# a simple window with a list of items in the queue, no checkboxes
|
"""Backwards-compatible re-export of the PyQt queue manager.
|
||||||
# button to remove an item from the queue
|
|
||||||
# button to clear the queue
|
|
||||||
|
|
||||||
from PyQt6.QtWidgets import (
|
The actual implementation lives in abogen.pyqt.queue_manager_gui.
|
||||||
QDialog,
|
"""
|
||||||
QVBoxLayout,
|
|
||||||
QHBoxLayout,
|
|
||||||
QDialogButtonBox,
|
|
||||||
QPushButton,
|
|
||||||
QListWidget,
|
|
||||||
QListWidgetItem,
|
|
||||||
QFileIconProvider,
|
|
||||||
QLabel,
|
|
||||||
QWidget,
|
|
||||||
QSizePolicy,
|
|
||||||
QAbstractItemView,
|
|
||||||
)
|
|
||||||
from PyQt6.QtCore import QFileInfo, Qt
|
|
||||||
from abogen.constants import COLORS
|
|
||||||
from copy import deepcopy
|
|
||||||
from PyQt6.QtGui import QFontMetrics
|
|
||||||
|
|
||||||
|
from __future__ import annotations
|
||||||
|
|
||||||
class ElidedLabel(QLabel):
|
from abogen.pyqt.queue_manager_gui import * # noqa: F401, F403
|
||||||
def __init__(self, text):
|
from abogen.pyqt.queue_manager_gui import QueueManager
|
||||||
super().__init__(text)
|
|
||||||
self._full_text = text
|
|
||||||
self.setSizePolicy(QSizePolicy.Policy.Expanding, QSizePolicy.Policy.Preferred)
|
|
||||||
self.setTextFormat(Qt.TextFormat.PlainText)
|
|
||||||
|
|
||||||
def setText(self, text):
|
__all__ = ["QueueManager"]
|
||||||
self._full_text = text
|
|
||||||
super().setText(text)
|
|
||||||
self.update()
|
|
||||||
|
|
||||||
def resizeEvent(self, event):
|
|
||||||
metrics = QFontMetrics(self.font())
|
|
||||||
elided = metrics.elidedText(
|
|
||||||
self._full_text, Qt.TextElideMode.ElideRight, self.width()
|
|
||||||
)
|
|
||||||
super().setText(elided)
|
|
||||||
super().resizeEvent(event)
|
|
||||||
|
|
||||||
def fullText(self):
|
|
||||||
return self._full_text
|
|
||||||
|
|
||||||
|
|
||||||
class QueueListItemWidget(QWidget):
|
|
||||||
def __init__(self, file_name, char_count):
|
|
||||||
super().__init__()
|
|
||||||
layout = QHBoxLayout()
|
|
||||||
layout.setContentsMargins(12, 0, 6, 0)
|
|
||||||
layout.setSpacing(0)
|
|
||||||
import os
|
|
||||||
|
|
||||||
name_label = ElidedLabel(os.path.basename(file_name))
|
|
||||||
char_label = QLabel(f"Chars: {char_count}")
|
|
||||||
char_label.setStyleSheet(f"color: {COLORS['LIGHT_DISABLED']};")
|
|
||||||
char_label.setAlignment(
|
|
||||||
Qt.AlignmentFlag.AlignRight | Qt.AlignmentFlag.AlignVCenter
|
|
||||||
)
|
|
||||||
char_label.setSizePolicy(
|
|
||||||
QSizePolicy.Policy.Minimum, QSizePolicy.Policy.Preferred
|
|
||||||
)
|
|
||||||
layout.addWidget(name_label, 1)
|
|
||||||
layout.addWidget(char_label, 0)
|
|
||||||
self.setLayout(layout)
|
|
||||||
|
|
||||||
|
|
||||||
class DroppableQueueListWidget(QListWidget):
|
|
||||||
def __init__(self, parent_dialog):
|
|
||||||
super().__init__()
|
|
||||||
self.parent_dialog = parent_dialog
|
|
||||||
self.setAcceptDrops(True)
|
|
||||||
# Overlay for drag hover
|
|
||||||
self.drag_overlay = QLabel("", self)
|
|
||||||
self.drag_overlay.setAlignment(Qt.AlignmentFlag.AlignCenter)
|
|
||||||
self.drag_overlay.setStyleSheet(
|
|
||||||
f"border:2px dashed {COLORS['BLUE_BORDER_HOVER']}; border-radius:5px; padding:20px; background:{COLORS['BLUE_BG_HOVER']};"
|
|
||||||
)
|
|
||||||
self.drag_overlay.setVisible(False)
|
|
||||||
self.drag_overlay.setAttribute(
|
|
||||||
Qt.WidgetAttribute.WA_TransparentForMouseEvents, True
|
|
||||||
)
|
|
||||||
|
|
||||||
def dragEnterEvent(self, event):
|
|
||||||
if event.mimeData().hasUrls():
|
|
||||||
for url in event.mimeData().urls():
|
|
||||||
file_path = url.toLocalFile().lower()
|
|
||||||
if url.isLocalFile() and (
|
|
||||||
file_path.endswith(".txt")
|
|
||||||
or file_path.endswith((".srt", ".ass", ".vtt"))
|
|
||||||
):
|
|
||||||
self.drag_overlay.resize(self.size())
|
|
||||||
self.drag_overlay.setVisible(True)
|
|
||||||
event.acceptProposedAction()
|
|
||||||
return
|
|
||||||
self.drag_overlay.setVisible(False)
|
|
||||||
event.ignore()
|
|
||||||
|
|
||||||
def dragMoveEvent(self, event):
|
|
||||||
if event.mimeData().hasUrls():
|
|
||||||
for url in event.mimeData().urls():
|
|
||||||
file_path = url.toLocalFile().lower()
|
|
||||||
if url.isLocalFile() and (
|
|
||||||
file_path.endswith(".txt")
|
|
||||||
or file_path.endswith((".srt", ".ass", ".vtt"))
|
|
||||||
):
|
|
||||||
event.acceptProposedAction()
|
|
||||||
return
|
|
||||||
event.ignore()
|
|
||||||
|
|
||||||
def dragLeaveEvent(self, event):
|
|
||||||
self.drag_overlay.setVisible(False)
|
|
||||||
event.accept()
|
|
||||||
|
|
||||||
def dropEvent(self, event):
|
|
||||||
self.drag_overlay.setVisible(False)
|
|
||||||
if event.mimeData().hasUrls():
|
|
||||||
file_paths = [
|
|
||||||
url.toLocalFile()
|
|
||||||
for url in event.mimeData().urls()
|
|
||||||
if url.isLocalFile()
|
|
||||||
and (
|
|
||||||
url.toLocalFile().lower().endswith(".txt")
|
|
||||||
or url.toLocalFile().lower().endswith((".srt", ".ass", ".vtt"))
|
|
||||||
)
|
|
||||||
]
|
|
||||||
if file_paths:
|
|
||||||
self.parent_dialog.add_files_from_paths(file_paths)
|
|
||||||
event.acceptProposedAction()
|
|
||||||
else:
|
|
||||||
event.ignore()
|
|
||||||
else:
|
|
||||||
event.ignore()
|
|
||||||
|
|
||||||
def resizeEvent(self, event):
|
|
||||||
super().resizeEvent(event)
|
|
||||||
if hasattr(self, "drag_overlay"):
|
|
||||||
self.drag_overlay.resize(self.size())
|
|
||||||
|
|
||||||
|
|
||||||
class QueueManager(QDialog):
|
|
||||||
def __init__(self, parent, queue: list, title="Queue Manager", size=(600, 700)):
|
|
||||||
super().__init__()
|
|
||||||
self.queue = queue
|
|
||||||
self._original_queue = deepcopy(
|
|
||||||
queue
|
|
||||||
) # Store a deep copy of the original queue
|
|
||||||
self.parent = parent
|
|
||||||
layout = QVBoxLayout()
|
|
||||||
layout.setContentsMargins(15, 15, 15, 15) # set main layout margins
|
|
||||||
layout.setSpacing(12) # set spacing between widgets in main layout
|
|
||||||
# list of queued items
|
|
||||||
self.listwidget = DroppableQueueListWidget(self)
|
|
||||||
self.listwidget.setSelectionMode(
|
|
||||||
QAbstractItemView.SelectionMode.ExtendedSelection
|
|
||||||
)
|
|
||||||
self.listwidget.setAlternatingRowColors(True)
|
|
||||||
self.listwidget.setContextMenuPolicy(Qt.ContextMenuPolicy.CustomContextMenu)
|
|
||||||
self.listwidget.customContextMenuRequested.connect(self.show_context_menu)
|
|
||||||
# Add informative instructions at the top
|
|
||||||
instructions = QLabel(
|
|
||||||
"<h2>How Queue Works?</h2>"
|
|
||||||
"You can add text and subtitle files (.txt, .srt, .ass, .vtt) directly using the '<b>Add files</b>' button below. "
|
|
||||||
"To add PDF, EPUB or markdown files, use the input box in the main window and click the <b>'Add to Queue'</b> button. "
|
|
||||||
"Each file in the queue keeps the configuration settings active when it was added. "
|
|
||||||
"Changing the main window configuration afterward <b>does not</b> affect files already in the queue. "
|
|
||||||
"You can view each file's configuration by hovering over them."
|
|
||||||
)
|
|
||||||
instructions.setAlignment(Qt.AlignmentFlag.AlignLeft)
|
|
||||||
instructions.setWordWrap(True)
|
|
||||||
instructions.setStyleSheet("margin-bottom: 8px;")
|
|
||||||
layout.addWidget(instructions)
|
|
||||||
# Overlay label for empty queue
|
|
||||||
self.empty_overlay = QLabel(
|
|
||||||
"Drag and drop your text or subtitle files here or use the 'Add files' button.",
|
|
||||||
self.listwidget,
|
|
||||||
)
|
|
||||||
self.empty_overlay.setAlignment(Qt.AlignmentFlag.AlignCenter)
|
|
||||||
self.empty_overlay.setStyleSheet(
|
|
||||||
f"color: {COLORS['LIGHT_DISABLED']}; background: transparent; padding: 20px;"
|
|
||||||
)
|
|
||||||
self.empty_overlay.setWordWrap(True)
|
|
||||||
self.empty_overlay.setAttribute(
|
|
||||||
Qt.WidgetAttribute.WA_TransparentForMouseEvents, True
|
|
||||||
)
|
|
||||||
self.empty_overlay.hide()
|
|
||||||
# add queue items to the list
|
|
||||||
self.process_queue()
|
|
||||||
|
|
||||||
button_row = QHBoxLayout()
|
|
||||||
button_row.setContentsMargins(0, 0, 0, 0) # optional: no margins for button row
|
|
||||||
button_row.setSpacing(7) # set spacing between buttons
|
|
||||||
# Add files button
|
|
||||||
add_files_button = QPushButton("Add files")
|
|
||||||
add_files_button.setFixedHeight(40)
|
|
||||||
add_files_button.clicked.connect(self.add_more_files)
|
|
||||||
button_row.addWidget(add_files_button)
|
|
||||||
|
|
||||||
# Remove button
|
|
||||||
self.remove_button = QPushButton("Remove selected")
|
|
||||||
self.remove_button.setFixedHeight(40)
|
|
||||||
self.remove_button.clicked.connect(self.remove_item)
|
|
||||||
button_row.addWidget(self.remove_button)
|
|
||||||
|
|
||||||
# Clear button
|
|
||||||
self.clear_button = QPushButton("Clear Queue")
|
|
||||||
self.clear_button.setFixedHeight(40)
|
|
||||||
self.clear_button.clicked.connect(self.clear_queue)
|
|
||||||
button_row.addWidget(self.clear_button)
|
|
||||||
|
|
||||||
layout.addLayout(button_row)
|
|
||||||
layout.addWidget(self.listwidget)
|
|
||||||
|
|
||||||
# Connect selection change to update button state
|
|
||||||
self.listwidget.currentItemChanged.connect(self.update_button_states)
|
|
||||||
self.listwidget.itemSelectionChanged.connect(self.update_button_states)
|
|
||||||
|
|
||||||
buttons = QDialogButtonBox(
|
|
||||||
QDialogButtonBox.StandardButton.Ok | QDialogButtonBox.StandardButton.Cancel,
|
|
||||||
self,
|
|
||||||
)
|
|
||||||
buttons.accepted.connect(self.accept)
|
|
||||||
buttons.rejected.connect(self.reject)
|
|
||||||
|
|
||||||
layout.addWidget(buttons)
|
|
||||||
|
|
||||||
self.setLayout(layout)
|
|
||||||
|
|
||||||
self.setWindowTitle(title)
|
|
||||||
self.resize(*size)
|
|
||||||
|
|
||||||
self.update_button_states()
|
|
||||||
|
|
||||||
def process_queue(self):
|
|
||||||
"""Process the queue items."""
|
|
||||||
import os
|
|
||||||
|
|
||||||
self.listwidget.clear()
|
|
||||||
if not self.queue:
|
|
||||||
self.empty_overlay.show()
|
|
||||||
self.update_button_states()
|
|
||||||
return
|
|
||||||
else:
|
|
||||||
self.empty_overlay.hide()
|
|
||||||
icon_provider = QFileIconProvider()
|
|
||||||
for item in self.queue:
|
|
||||||
# Determine display file path (prefer save_base_path for original file)
|
|
||||||
display_file_path = getattr(item, "save_base_path", None) or item.file_name
|
|
||||||
processing_file_path = item.file_name
|
|
||||||
|
|
||||||
# Normalize paths for consistent display (fixes Windows path separator issues)
|
|
||||||
display_file_path = (
|
|
||||||
os.path.normpath(display_file_path)
|
|
||||||
if display_file_path
|
|
||||||
else display_file_path
|
|
||||||
)
|
|
||||||
processing_file_path = (
|
|
||||||
os.path.normpath(processing_file_path)
|
|
||||||
if processing_file_path
|
|
||||||
else processing_file_path
|
|
||||||
)
|
|
||||||
|
|
||||||
# Only show the file name, not the full path
|
|
||||||
display_name = display_file_path
|
|
||||||
|
|
||||||
if os.path.sep in display_file_path:
|
|
||||||
display_name = os.path.basename(display_file_path)
|
|
||||||
# Get icon for the display file
|
|
||||||
icon = icon_provider.icon(QFileInfo(display_file_path))
|
|
||||||
list_item = QListWidgetItem()
|
|
||||||
# Set tooltip with detailed info
|
|
||||||
output_folder = getattr(item, "output_folder", "")
|
|
||||||
# For plain .txt inputs we don't need to show a separate processing file
|
|
||||||
show_processing = True
|
|
||||||
try:
|
|
||||||
if isinstance(
|
|
||||||
display_file_path, str
|
|
||||||
) and display_file_path.lower().endswith(".txt"):
|
|
||||||
show_processing = False
|
|
||||||
except Exception:
|
|
||||||
show_processing = True
|
|
||||||
|
|
||||||
tooltip = f"<b>Input File:</b> {display_file_path}<br>"
|
|
||||||
if (
|
|
||||||
show_processing
|
|
||||||
and processing_file_path
|
|
||||||
and processing_file_path != display_file_path
|
|
||||||
):
|
|
||||||
tooltip += f"<b>Processing File:</b> {processing_file_path}<br>"
|
|
||||||
tooltip += (
|
|
||||||
f"<b>Language:</b> {getattr(item, 'lang_code', '')}<br>"
|
|
||||||
f"<b>Speed:</b> {getattr(item, 'speed', '')}<br>"
|
|
||||||
f"<b>Voice:</b> {getattr(item, 'voice', '')}<br>"
|
|
||||||
f"<b>Save Option:</b> {getattr(item, 'save_option', '')}<br>"
|
|
||||||
)
|
|
||||||
if output_folder not in (None, "", "None"):
|
|
||||||
tooltip += f"<b>Output Folder:</b> {output_folder}<br>"
|
|
||||||
tooltip += (
|
|
||||||
f"<b>Subtitle Mode:</b> {getattr(item, 'subtitle_mode', '')}<br>"
|
|
||||||
f"<b>Output Format:</b> {getattr(item, 'output_format', '')}<br>"
|
|
||||||
f"<b>Characters:</b> {getattr(item, 'total_char_count', '')}<br>"
|
|
||||||
f"<b>Replace Single Newlines:</b> {getattr(item, 'replace_single_newlines', False)}<br>"
|
|
||||||
f"<b>Use Silent Gaps:</b> {getattr(item, 'use_silent_gaps', False)}<br>"
|
|
||||||
f"<b>Speed Method:</b> {getattr(item, 'subtitle_speed_method', 'tts')}"
|
|
||||||
)
|
|
||||||
# Add book handler options if present
|
|
||||||
save_chapters_separately = getattr(item, "save_chapters_separately", None)
|
|
||||||
merge_chapters_at_end = getattr(item, "merge_chapters_at_end", None)
|
|
||||||
if save_chapters_separately is not None:
|
|
||||||
tooltip += f"<br><b>Save chapters separately:</b> {'Yes' if save_chapters_separately else 'No'}"
|
|
||||||
# Only show merge option if saving chapters separately
|
|
||||||
if save_chapters_separately and merge_chapters_at_end is not None:
|
|
||||||
tooltip += f"<br><b>Merge chapters at the end:</b> {'Yes' if merge_chapters_at_end else 'No'}"
|
|
||||||
list_item.setToolTip(tooltip)
|
|
||||||
list_item.setIcon(icon)
|
|
||||||
# Store both paths for context menu
|
|
||||||
list_item.setData(
|
|
||||||
Qt.ItemDataRole.UserRole,
|
|
||||||
{
|
|
||||||
"display_path": display_file_path,
|
|
||||||
"processing_path": processing_file_path,
|
|
||||||
},
|
|
||||||
)
|
|
||||||
# Use custom widget for display
|
|
||||||
char_count = getattr(item, "total_char_count", 0)
|
|
||||||
widget = QueueListItemWidget(display_file_path, char_count)
|
|
||||||
self.listwidget.addItem(list_item)
|
|
||||||
self.listwidget.setItemWidget(list_item, widget)
|
|
||||||
self.update_button_states()
|
|
||||||
|
|
||||||
def remove_item(self):
|
|
||||||
items = self.listwidget.selectedItems()
|
|
||||||
if not items:
|
|
||||||
return
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
|
|
||||||
# Remove by index to ensure correct mapping
|
|
||||||
rows = sorted([self.listwidget.row(item) for item in items], reverse=True)
|
|
||||||
# Warn user if removing multiple files
|
|
||||||
if len(rows) > 1:
|
|
||||||
reply = QMessageBox.question(
|
|
||||||
self,
|
|
||||||
"Confirm Remove",
|
|
||||||
f"Are you sure you want to remove {len(rows)} selected items from the queue?",
|
|
||||||
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
|
||||||
QMessageBox.StandardButton.No,
|
|
||||||
)
|
|
||||||
if reply != QMessageBox.StandardButton.Yes:
|
|
||||||
return
|
|
||||||
for row in rows:
|
|
||||||
if 0 <= row < len(self.queue):
|
|
||||||
del self.queue[row]
|
|
||||||
self.process_queue()
|
|
||||||
self.update_button_states()
|
|
||||||
|
|
||||||
def clear_queue(self):
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
|
|
||||||
if len(self.queue) > 1:
|
|
||||||
reply = QMessageBox.question(
|
|
||||||
self,
|
|
||||||
"Confirm Clear Queue",
|
|
||||||
f"Are you sure you want to clear {len(self.queue)} items from the queue?",
|
|
||||||
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
|
||||||
QMessageBox.StandardButton.No,
|
|
||||||
)
|
|
||||||
if reply != QMessageBox.StandardButton.Yes:
|
|
||||||
return
|
|
||||||
self.queue.clear()
|
|
||||||
self.listwidget.clear()
|
|
||||||
self.empty_overlay.resize(
|
|
||||||
self.listwidget.size()
|
|
||||||
) # Ensure overlay is sized correctly
|
|
||||||
self.empty_overlay.show() # Show the overlay when queue is empty
|
|
||||||
self.update_button_states()
|
|
||||||
|
|
||||||
def get_queue(self):
|
|
||||||
return self.queue
|
|
||||||
|
|
||||||
def get_current_attributes(self):
|
|
||||||
# Fetch current attribute values from the parent abogen GUI
|
|
||||||
attrs = {}
|
|
||||||
parent = self.parent
|
|
||||||
if parent is not None:
|
|
||||||
# lang_code: use parent's get_voice_formula and get_selected_lang
|
|
||||||
if hasattr(parent, "get_voice_formula") and hasattr(
|
|
||||||
parent, "get_selected_lang"
|
|
||||||
):
|
|
||||||
voice_formula = parent.get_voice_formula()
|
|
||||||
attrs["lang_code"] = parent.get_selected_lang(voice_formula)
|
|
||||||
attrs["voice"] = voice_formula
|
|
||||||
else:
|
|
||||||
attrs["lang_code"] = getattr(parent, "selected_lang", "")
|
|
||||||
attrs["voice"] = getattr(parent, "selected_voice", "")
|
|
||||||
# speed
|
|
||||||
if hasattr(parent, "speed_slider"):
|
|
||||||
attrs["speed"] = parent.speed_slider.value() / 100.0
|
|
||||||
else:
|
|
||||||
attrs["speed"] = getattr(parent, "speed", 1.0)
|
|
||||||
# save_option
|
|
||||||
attrs["save_option"] = getattr(parent, "save_option", "")
|
|
||||||
# output_folder
|
|
||||||
attrs["output_folder"] = getattr(parent, "selected_output_folder", "")
|
|
||||||
# subtitle_mode
|
|
||||||
if hasattr(parent, "get_actual_subtitle_mode"):
|
|
||||||
attrs["subtitle_mode"] = parent.get_actual_subtitle_mode()
|
|
||||||
else:
|
|
||||||
attrs["subtitle_mode"] = getattr(parent, "subtitle_mode", "")
|
|
||||||
# output_format
|
|
||||||
attrs["output_format"] = getattr(parent, "selected_format", "")
|
|
||||||
# total_char_count
|
|
||||||
attrs["total_char_count"] = getattr(parent, "char_count", "")
|
|
||||||
# replace_single_newlines
|
|
||||||
attrs["replace_single_newlines"] = getattr(
|
|
||||||
parent, "replace_single_newlines", False
|
|
||||||
)
|
|
||||||
# use_silent_gaps
|
|
||||||
attrs["use_silent_gaps"] = getattr(parent, "use_silent_gaps", False)
|
|
||||||
# subtitle_speed_method
|
|
||||||
attrs["subtitle_speed_method"] = getattr(
|
|
||||||
parent, "subtitle_speed_method", "tts"
|
|
||||||
)
|
|
||||||
# book handler options
|
|
||||||
attrs["save_chapters_separately"] = getattr(
|
|
||||||
parent, "save_chapters_separately", None
|
|
||||||
)
|
|
||||||
attrs["merge_chapters_at_end"] = getattr(
|
|
||||||
parent, "merge_chapters_at_end", None
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
# fallback: empty values
|
|
||||||
attrs = {
|
|
||||||
k: ""
|
|
||||||
for k in [
|
|
||||||
"lang_code",
|
|
||||||
"speed",
|
|
||||||
"voice",
|
|
||||||
"save_option",
|
|
||||||
"output_folder",
|
|
||||||
"subtitle_mode",
|
|
||||||
"output_format",
|
|
||||||
"total_char_count",
|
|
||||||
"replace_single_newlines",
|
|
||||||
]
|
|
||||||
}
|
|
||||||
attrs["save_chapters_separately"] = None
|
|
||||||
attrs["merge_chapters_at_end"] = None
|
|
||||||
return attrs
|
|
||||||
|
|
||||||
def add_files_from_paths(self, file_paths):
|
|
||||||
from abogen.utils import calculate_text_length
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
import os
|
|
||||||
|
|
||||||
current_attrs = self.get_current_attributes()
|
|
||||||
duplicates = []
|
|
||||||
for file_path in file_paths:
|
|
||||||
|
|
||||||
class QueueItem:
|
|
||||||
pass
|
|
||||||
|
|
||||||
item = QueueItem()
|
|
||||||
item.file_name = file_path
|
|
||||||
item.save_base_path = (
|
|
||||||
file_path # For .txt files, processing and save paths are the same
|
|
||||||
)
|
|
||||||
for attr, value in current_attrs.items():
|
|
||||||
setattr(item, attr, value)
|
|
||||||
# Override subtitle_mode to "Disabled" for subtitle files
|
|
||||||
if file_path.lower().endswith((".srt", ".ass", ".vtt")):
|
|
||||||
item.subtitle_mode = "Disabled"
|
|
||||||
# Read file content and calculate total_char_count using calculate_text_length
|
|
||||||
try:
|
|
||||||
with open(file_path, "r", encoding="utf-8", errors="ignore") as f:
|
|
||||||
file_content = f.read()
|
|
||||||
item.total_char_count = calculate_text_length(file_content)
|
|
||||||
except Exception:
|
|
||||||
item.total_char_count = 0
|
|
||||||
# Prevent adding duplicate items to the queue (check all attributes)
|
|
||||||
is_duplicate = False
|
|
||||||
for queued_item in self.queue:
|
|
||||||
if (
|
|
||||||
getattr(queued_item, "file_name", None)
|
|
||||||
== getattr(item, "file_name", None)
|
|
||||||
and getattr(queued_item, "lang_code", None)
|
|
||||||
== getattr(item, "lang_code", None)
|
|
||||||
and getattr(queued_item, "speed", None)
|
|
||||||
== getattr(item, "speed", None)
|
|
||||||
and getattr(queued_item, "voice", None)
|
|
||||||
== getattr(item, "voice", None)
|
|
||||||
and getattr(queued_item, "save_option", None)
|
|
||||||
== getattr(item, "save_option", None)
|
|
||||||
and getattr(queued_item, "output_folder", None)
|
|
||||||
== getattr(item, "output_folder", None)
|
|
||||||
and getattr(queued_item, "subtitle_mode", None)
|
|
||||||
== getattr(item, "subtitle_mode", None)
|
|
||||||
and getattr(queued_item, "output_format", None)
|
|
||||||
== getattr(item, "output_format", None)
|
|
||||||
and getattr(queued_item, "total_char_count", None)
|
|
||||||
== getattr(item, "total_char_count", None)
|
|
||||||
and getattr(queued_item, "replace_single_newlines", False)
|
|
||||||
== getattr(item, "replace_single_newlines", False)
|
|
||||||
and getattr(queued_item, "use_silent_gaps", False)
|
|
||||||
== getattr(item, "use_silent_gaps", False)
|
|
||||||
and getattr(queued_item, "subtitle_speed_method", "tts")
|
|
||||||
== getattr(item, "subtitle_speed_method", "tts")
|
|
||||||
and getattr(queued_item, "save_base_path", None)
|
|
||||||
== getattr(item, "save_base_path", None)
|
|
||||||
and getattr(queued_item, "save_chapters_separately", None)
|
|
||||||
== getattr(item, "save_chapters_separately", None)
|
|
||||||
and getattr(queued_item, "merge_chapters_at_end", None)
|
|
||||||
== getattr(item, "merge_chapters_at_end", None)
|
|
||||||
):
|
|
||||||
is_duplicate = True
|
|
||||||
break
|
|
||||||
if is_duplicate:
|
|
||||||
duplicates.append(os.path.basename(file_path))
|
|
||||||
continue
|
|
||||||
self.queue.append(item)
|
|
||||||
if duplicates:
|
|
||||||
QMessageBox.warning(
|
|
||||||
self,
|
|
||||||
"Duplicate Item(s)",
|
|
||||||
f"Skipping {len(duplicates)} file(s) with the same attributes, already in the queue.",
|
|
||||||
)
|
|
||||||
self.process_queue()
|
|
||||||
self.update_button_states()
|
|
||||||
|
|
||||||
def add_more_files(self):
|
|
||||||
from PyQt6.QtWidgets import QFileDialog
|
|
||||||
from abogen.utils import calculate_text_length # import the function
|
|
||||||
|
|
||||||
# Allow .txt, .srt, .ass, and .vtt files
|
|
||||||
files, _ = QFileDialog.getOpenFileNames(
|
|
||||||
self,
|
|
||||||
"Select text or subtitle files",
|
|
||||||
"",
|
|
||||||
"Supported Files (*.txt *.srt *.ass *.vtt)",
|
|
||||||
)
|
|
||||||
if not files:
|
|
||||||
return
|
|
||||||
self.add_files_from_paths(files)
|
|
||||||
|
|
||||||
def resizeEvent(self, event):
|
|
||||||
super().resizeEvent(event)
|
|
||||||
if hasattr(self, "empty_overlay"):
|
|
||||||
self.empty_overlay.resize(self.listwidget.size())
|
|
||||||
|
|
||||||
def update_button_states(self):
|
|
||||||
# Enable Remove if at least one item is selected, else disable
|
|
||||||
if hasattr(self, "remove_button"):
|
|
||||||
selected_count = len(self.listwidget.selectedItems())
|
|
||||||
self.remove_button.setEnabled(selected_count > 0)
|
|
||||||
if selected_count > 1:
|
|
||||||
self.remove_button.setText(f"Remove selected ({selected_count})")
|
|
||||||
else:
|
|
||||||
self.remove_button.setText("Remove selected")
|
|
||||||
# Disable Clear if queue is empty
|
|
||||||
if hasattr(self, "clear_button"):
|
|
||||||
self.clear_button.setEnabled(bool(self.queue))
|
|
||||||
|
|
||||||
def show_context_menu(self, pos):
|
|
||||||
from PyQt6.QtWidgets import QMenu
|
|
||||||
from PyQt6.QtGui import QAction, QDesktopServices
|
|
||||||
from PyQt6.QtCore import QUrl
|
|
||||||
import os
|
|
||||||
|
|
||||||
global_pos = self.listwidget.viewport().mapToGlobal(pos)
|
|
||||||
selected_items = self.listwidget.selectedItems()
|
|
||||||
menu = QMenu(self)
|
|
||||||
if len(selected_items) == 1:
|
|
||||||
# Add Remove action
|
|
||||||
remove_action = QAction("Remove this item", self)
|
|
||||||
remove_action.triggered.connect(self.remove_item)
|
|
||||||
menu.addAction(remove_action)
|
|
||||||
|
|
||||||
# Get paths for determining if it's a document input
|
|
||||||
item = selected_items[0]
|
|
||||||
paths = item.data(Qt.ItemDataRole.UserRole)
|
|
||||||
if isinstance(paths, dict):
|
|
||||||
display_path = paths.get("display_path", "")
|
|
||||||
processing_path = paths.get("processing_path", "")
|
|
||||||
else:
|
|
||||||
display_path = paths
|
|
||||||
processing_path = paths
|
|
||||||
|
|
||||||
doc_exts = (".md", ".markdown", ".pdf", ".epub")
|
|
||||||
is_document_input = (
|
|
||||||
isinstance(display_path, str)
|
|
||||||
and display_path.lower().endswith(doc_exts)
|
|
||||||
) or (
|
|
||||||
isinstance(processing_path, str)
|
|
||||||
and processing_path.lower().endswith(doc_exts)
|
|
||||||
)
|
|
||||||
|
|
||||||
# Add Open file action(s)
|
|
||||||
def open_file_by_path(path_label: str):
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
|
|
||||||
p = display_path if path_label == "display" else processing_path
|
|
||||||
if not p:
|
|
||||||
QMessageBox.warning(
|
|
||||||
self, "File Not Found", "Path is not available."
|
|
||||||
)
|
|
||||||
return
|
|
||||||
|
|
||||||
# Find the queue item and resolve the target path
|
|
||||||
target_path = None
|
|
||||||
for q in self.queue:
|
|
||||||
if (
|
|
||||||
getattr(q, "save_base_path", None) == display_path
|
|
||||||
or q.file_name == display_path
|
|
||||||
):
|
|
||||||
if path_label == "display":
|
|
||||||
target_path = (
|
|
||||||
getattr(q, "save_base_path", None) or q.file_name
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
target_path = q.file_name
|
|
||||||
break
|
|
||||||
if (
|
|
||||||
getattr(q, "save_base_path", None) == processing_path
|
|
||||||
or q.file_name == processing_path
|
|
||||||
):
|
|
||||||
if path_label == "display":
|
|
||||||
target_path = (
|
|
||||||
getattr(q, "save_base_path", None) or q.file_name
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
target_path = q.file_name
|
|
||||||
break
|
|
||||||
|
|
||||||
# Fallback to the raw path if resolution failed
|
|
||||||
if not target_path:
|
|
||||||
target_path = p
|
|
||||||
|
|
||||||
if not os.path.exists(target_path):
|
|
||||||
QMessageBox.warning(
|
|
||||||
self, "File Not Found", f"The file does not exist."
|
|
||||||
)
|
|
||||||
return
|
|
||||||
QDesktopServices.openUrl(QUrl.fromLocalFile(target_path))
|
|
||||||
|
|
||||||
if is_document_input:
|
|
||||||
# For documents, show two open options
|
|
||||||
open_processed_action = QAction("Open processed file", self)
|
|
||||||
open_processed_action.triggered.connect(
|
|
||||||
lambda: open_file_by_path("processing")
|
|
||||||
)
|
|
||||||
menu.addAction(open_processed_action)
|
|
||||||
|
|
||||||
open_input_action = QAction("Open input file", self)
|
|
||||||
open_input_action.triggered.connect(
|
|
||||||
lambda: open_file_by_path("display")
|
|
||||||
)
|
|
||||||
menu.addAction(open_input_action)
|
|
||||||
else:
|
|
||||||
# For plain text files, show single open option
|
|
||||||
open_file_action = QAction("Open file", self)
|
|
||||||
open_file_action.triggered.connect(lambda: open_file_by_path("display"))
|
|
||||||
menu.addAction(open_file_action)
|
|
||||||
|
|
||||||
# Add Go to folder action
|
|
||||||
# If the queued item represents a converted document (markdown, pdf, epub)
|
|
||||||
# show two actions: Go to processed file (the cached .txt) and Go to input file (original source)
|
|
||||||
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
|
|
||||||
def open_folder_for(path_label: str):
|
|
||||||
# path_label should be either 'display' or 'processing'
|
|
||||||
p = display_path if path_label == "display" else processing_path
|
|
||||||
if not p:
|
|
||||||
QMessageBox.warning(
|
|
||||||
self, "File Not Found", "Path is not available."
|
|
||||||
)
|
|
||||||
return
|
|
||||||
# If the stored path is the display path (original) but the actual file may be
|
|
||||||
# stored on the queue object differently, try to resolve via the queue entry.
|
|
||||||
target_path = None
|
|
||||||
for q in self.queue:
|
|
||||||
if (
|
|
||||||
getattr(q, "save_base_path", None) == display_path
|
|
||||||
or q.file_name == display_path
|
|
||||||
):
|
|
||||||
if path_label == "display":
|
|
||||||
target_path = (
|
|
||||||
getattr(q, "save_base_path", None) or q.file_name
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
target_path = q.file_name
|
|
||||||
break
|
|
||||||
if (
|
|
||||||
getattr(q, "save_base_path", None) == processing_path
|
|
||||||
or q.file_name == processing_path
|
|
||||||
):
|
|
||||||
if path_label == "display":
|
|
||||||
target_path = (
|
|
||||||
getattr(q, "save_base_path", None) or q.file_name
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
target_path = q.file_name
|
|
||||||
break
|
|
||||||
# Fallback to the raw path if resolution failed
|
|
||||||
if not target_path:
|
|
||||||
target_path = p
|
|
||||||
|
|
||||||
if not os.path.exists(target_path):
|
|
||||||
QMessageBox.warning(
|
|
||||||
self,
|
|
||||||
"File Not Found",
|
|
||||||
f"The file does not exist: {target_path}",
|
|
||||||
)
|
|
||||||
return
|
|
||||||
folder = os.path.dirname(target_path)
|
|
||||||
if os.path.exists(folder):
|
|
||||||
QDesktopServices.openUrl(QUrl.fromLocalFile(folder))
|
|
||||||
|
|
||||||
if is_document_input:
|
|
||||||
processed_action = QAction("Go to processed file", self)
|
|
||||||
processed_action.triggered.connect(
|
|
||||||
lambda: open_folder_for("processing")
|
|
||||||
)
|
|
||||||
menu.addAction(processed_action)
|
|
||||||
|
|
||||||
input_action = QAction("Go to input file", self)
|
|
||||||
input_action.triggered.connect(lambda: open_folder_for("display"))
|
|
||||||
menu.addAction(input_action)
|
|
||||||
else:
|
|
||||||
# Default behavior for non-document inputs: single "Go to folder" action
|
|
||||||
go_to_folder_action = QAction("Go to folder", self)
|
|
||||||
|
|
||||||
def go_to_folder():
|
|
||||||
item = selected_items[0]
|
|
||||||
paths = item.data(Qt.ItemDataRole.UserRole)
|
|
||||||
if isinstance(paths, dict):
|
|
||||||
file_path = paths.get(
|
|
||||||
"display_path", paths.get("processing_path", "")
|
|
||||||
)
|
|
||||||
else:
|
|
||||||
file_path = paths # Fallback for old format
|
|
||||||
# Find the queue item
|
|
||||||
for q in self.queue:
|
|
||||||
if (
|
|
||||||
getattr(q, "save_base_path", None) == file_path
|
|
||||||
or q.file_name == file_path
|
|
||||||
):
|
|
||||||
target_path = (
|
|
||||||
getattr(q, "save_base_path", None) or q.file_name
|
|
||||||
)
|
|
||||||
if not os.path.exists(target_path):
|
|
||||||
QMessageBox.warning(
|
|
||||||
self, "File Not Found", f"The file does not exist."
|
|
||||||
)
|
|
||||||
return
|
|
||||||
folder = os.path.dirname(target_path)
|
|
||||||
if os.path.exists(folder):
|
|
||||||
QDesktopServices.openUrl(QUrl.fromLocalFile(folder))
|
|
||||||
break
|
|
||||||
|
|
||||||
go_to_folder_action.triggered.connect(go_to_folder)
|
|
||||||
menu.addAction(go_to_folder_action)
|
|
||||||
|
|
||||||
elif len(selected_items) > 1:
|
|
||||||
remove_action = QAction(f"Remove selected ({len(selected_items)})", self)
|
|
||||||
remove_action.triggered.connect(self.remove_item)
|
|
||||||
menu.addAction(remove_action)
|
|
||||||
# Always add Clear Queue
|
|
||||||
clear_action = QAction("Clear Queue", self)
|
|
||||||
clear_action.triggered.connect(self.clear_queue)
|
|
||||||
menu.addAction(clear_action)
|
|
||||||
menu.exec(global_pos)
|
|
||||||
|
|
||||||
def accept(self):
|
|
||||||
# Accept: keep changes
|
|
||||||
super().accept()
|
|
||||||
|
|
||||||
def reject(self):
|
|
||||||
# Cancel: restore original queue
|
|
||||||
from PyQt6.QtWidgets import QMessageBox
|
|
||||||
|
|
||||||
# Warn if user changed a lot (e.g., more than 1 items difference)
|
|
||||||
original_count = len(self._original_queue)
|
|
||||||
current_count = len(self.queue)
|
|
||||||
if abs(original_count - current_count) > 1:
|
|
||||||
reply = QMessageBox.question(
|
|
||||||
self,
|
|
||||||
"Confirm Cancel",
|
|
||||||
f"Are you sure you want to cancel and discard all changes?",
|
|
||||||
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No,
|
|
||||||
QMessageBox.StandardButton.No,
|
|
||||||
)
|
|
||||||
if reply != QMessageBox.StandardButton.Yes:
|
|
||||||
return
|
|
||||||
self.queue.clear()
|
|
||||||
self.queue.extend(deepcopy(self._original_queue))
|
|
||||||
super().reject()
|
|
||||||
|
|
||||||
def keyPressEvent(self, event):
|
|
||||||
from PyQt6.QtCore import Qt
|
|
||||||
|
|
||||||
if event.key() == Qt.Key.Key_Delete:
|
|
||||||
self.remove_item()
|
|
||||||
else:
|
|
||||||
super().keyPressEvent(event)
|
|
||||||
|
|||||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user