mirror of
https://github.com/denizsafak/abogen.git
synced 2026-09-20 11:40:57 +02:00
Compare commits
12
Commits
94e6b3f62e
..
main
| Author | SHA1 | Date | |
|---|---|---|---|
 Deniz Şafak |
08e2ee8b85 | ||
|
Deniz Şafak
|
be74c69507 | ||
|
Deniz Şafak
|
ffac4a4da9 | ||
|
Deniz Şafak
|
5432de7ac5 | ||
|
Deniz Şafak
|
823f5be029 | ||
|
Deniz Şafak
|
aaa6ac112b | ||
|
Deniz Şafak
|
11274ad6bf | ||
|
Deniz Şafak
|
f340b976db | ||
|
Deniz Şafak
|
9da15aefa4 | ||
|
Deniz Şafak
|
919aea9295 | ||
|
SimonFoobar648
|
ce1fc0c880 | ||
|
Sanjay Santhanam
|
7340d52ebb |
@@ -40,3 +40,6 @@ test_assets/
|
||||
dev_notes/
|
||||
.claude/
|
||||
.coverage
|
||||
|
||||
# CodeGraph index (local, machine-specific)
|
||||
.codegraph/
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
# AGENTS.md — Segmentation & Subtitle System Contract
|
||||
|
||||
This document is the source of truth for how text is split for **voice
|
||||
processing** (TTS engine segmentation) and **subtitle processing**, across
|
||||
languages, TTS engines, and subtitle modes. It was written after a bug where
|
||||
sentence modes "processed all text as a whole" (one merged engine segment →
|
||||
one giant subtitle). **Do not change this behavior without updating this
|
||||
table.**
|
||||
|
||||
## Voice processing — split pattern passed to the TTS engine
|
||||
|
||||
`get_split_pattern(language, mode)` in `abogen/domain/split_pattern.py` is the
|
||||
default; the spaCy pre-TTS path overrides it. Both UIs must stay in sync:
|
||||
`spacy_pre_tts_segmentation` (`abogen/domain/conversion_pipeline.py`, WebUI)
|
||||
and the inline branch in `abogen/pyqt/conversion.py` (~line 860, PyQt).
|
||||
|
||||
| Subtitle mode | English (en-US/en-GB) | Non-English, spaCy ON | Non-English, spaCy OFF | CJK (ja/zh) |
|
||||
|---|---|---|---|---|
|
||||
| Disabled | `\n` | spaCy pre-split, engine `\n` | `\n+` | `(?<=[.!?؟。!?।])\s*\|\n+` |
|
||||
| Line | `\n` | spaCy pre-split, engine `\n` | `\n` | `(?<=[.!?؟。!?।])\s*\|\n+` |
|
||||
| Sentence | `\n` | spaCy pre-split, engine `\n` | `(?<=[.!?؟。!?।])\s+\|\n+` | `(?<=[.!?؟。!?।])\s*\|\n+` |
|
||||
| Sentence + Comma | `\n` | spaCy pre-split, engine `\n` | `(?<=[.!?,؟。!?،،、।])\s+\|\n+` (commas kept) | `(?<=[.!?,؟。!?،،、।])\s*\|\n+` |
|
||||
| Sentence + Highlighting | `\n+` | `\n+` | `\n+` | `\n+` |
|
||||
| N words ("5 words") | `\n` (→ Disabled) | `\n+` | `\n+` | Disabled CJK pattern |
|
||||
|
||||
Rules baked into this table:
|
||||
|
||||
- **English voice splitting is ALWAYS newline-only** for Disabled, Line,
|
||||
Sentence, and Sentence + Comma. English sentence/comma boundaries are
|
||||
produced ONLY at subtitle time (spaCy post-TTS / regex fallback). Never add
|
||||
punctuation to the English engine pattern.
|
||||
- **Non-English + spaCy ON**: spaCy pre-segments the text (pre-TTS); the
|
||||
engine pattern is `\n` for Sentence AND Sentence + Comma — **never commas**.
|
||||
spaCy is skipped when the toggle is off, mode is Disabled/Line, or input is
|
||||
a subtitle file.
|
||||
- **Non-English + spaCy OFF** (toggle off, spaCy failure, subtitle input): the
|
||||
default pattern is used — Sentence + Comma KEEPS its commas here. This is
|
||||
the intentional fallback, not a bug.
|
||||
- CJK: punctuation-based patterns for Disabled/Line (historical); spacing is
|
||||
`\s*` (no spaces needed between CJK chars).
|
||||
- Engine-level extra chunking (applies after the pattern): kokoro English
|
||||
re-chunks at ~510 phonemes; kokoro non-English at ~400 chars; supertonic
|
||||
caps each part at 300 chars.
|
||||
|
||||
## Subtitle processing — post-TTS, from tokens
|
||||
|
||||
| Mode | Behavior |
|
||||
|---|---|
|
||||
| Disabled | no subtitles |
|
||||
| Line | one entry per TTS segment (line) |
|
||||
| Sentence | sentence boundaries: English → spaCy; others → regex on `[.!?…]` |
|
||||
| Sentence + Comma | sentence + comma boundaries at subtitle time (both languages) — commas never affect voice |
|
||||
| Sentence + Highlighting | karaoke `{\kf…}` per word, grouped by sentence |
|
||||
| N words | groups of N words by whitespace counting |
|
||||
|
||||
Token granularity (timing quality): kokoro English emits **per-word tokens**
|
||||
with timestamps; kokoro non-English and supertonic emit **no tokens** → each
|
||||
engine segment becomes one FakeToken, split by regex with proportional timing
|
||||
when it contains multiple sentences.
|
||||
|
||||
## Hard invariants (breaking these reintroduces the original bug)
|
||||
|
||||
1. `Pipeline.__call__` (`abogen/tts_plugin/utils.py`) must yield ONE `Segment`
|
||||
per engine segment (with tokens) — never merge segments back into the
|
||||
whole text. `SynthesizedAudio.segments` carries the per-segment data;
|
||||
engines expose it in `plugins/kokoro/engine.py` and
|
||||
`plugins/supertonic/engine.py`.
|
||||
2. `tts_segments` (`abogen/domain/conversion_pipeline.py`) restores trailing
|
||||
whitespace on segment-boundary tokens ONLY for real per-word tokens, never
|
||||
for FakeToken fallbacks.
|
||||
3. `_to_language_enum` must return `lang_code` as-is when it is already a
|
||||
`Language` enum (`str(Language.ES)` is `"Language.ES"`, which silently
|
||||
resolved to EN_US and disabled spaCy pre-TTS for every language in WebUI).
|
||||
4. English must never use spaCy for PRE-TTS segmentation — only for subtitles.
|
||||
|
||||
## Guarded by tests
|
||||
|
||||
- `tests/test_split_pattern.py` — English newline-only; non-English sentence
|
||||
patterns; CJK behavior.
|
||||
- `tests/test_domain_conversion_pipeline.py` — `tts_segments` / spaCy
|
||||
segmentation helpers.
|
||||
- Full suite: `python -m pytest tests/ -q` (expect 1566+ passing).
|
||||
@@ -721,7 +721,7 @@ This project is available under the MIT License - see the [LICENSE](https://gith
|
||||
[Kokoro](https://github.com/hexgrad/kokoro) is licensed under [Apache-2.0](https://github.com/hexgrad/kokoro/blob/main/LICENSE) which allows commercial use, modification, distribution, and private use.
|
||||
|
||||
## `Star History`
|
||||
[](https://www.star-history.com/#denizsafak/abogen&Date)
|
||||
[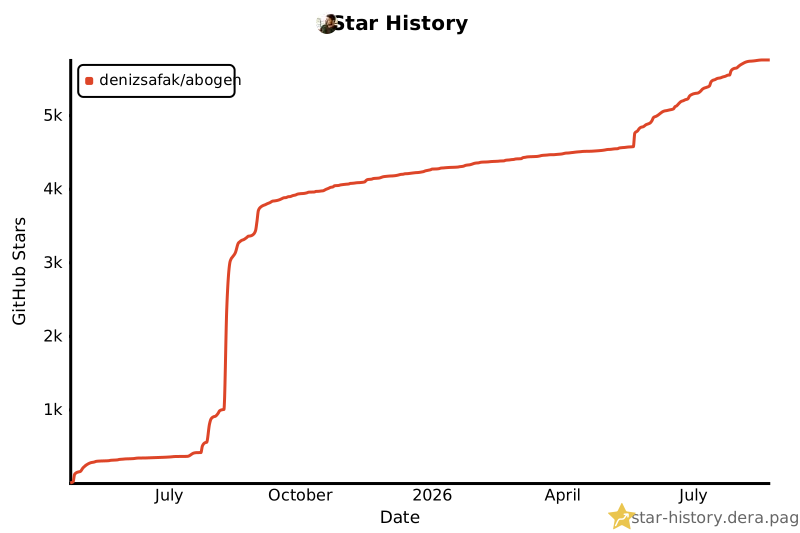](https://star-history.dera.page/#denizsafak/abogen&Date)
|
||||
|
||||
> [!NOTE]
|
||||
> Abogen supports subtitle generation for all languages. However, word-level subtitle modes (e.g., "1 word", "2 words", "3 words", etc.) are only available for English because [Kokoro provides timestamp tokens only for English text](https://github.com/hexgrad/kokoro/blob/6d87f4ae7abc2d14dbc4b3ef2e5f19852e861ac2/kokoro/pipeline.py#L383). For non-English languages, Abogen uses a duration-based fallback that supports sentence-level and comma-based subtitle modes ("Line", "Sentence", "Sentence + Comma"). If you need word-level subtitles for other languages, please request that feature in the [Kokoro project](https://github.com/hexgrad/kokoro).
|
||||
|
||||
@@ -11,6 +11,7 @@ Called by shutdown.py at process exit and by run_conversion() per-conversion.
|
||||
from __future__ import annotations
|
||||
|
||||
import gc
|
||||
import sys
|
||||
from typing import Callable
|
||||
|
||||
_UI_CLEANUPS: list[Callable[[], None]] = []
|
||||
@@ -19,8 +20,12 @@ _UI_CLEANUPS: list[Callable[[], None]] = []
|
||||
def flush_cuda() -> None:
|
||||
"""Run GC and release CUDA cache. Safe to call multiple times."""
|
||||
gc.collect()
|
||||
# Skip entirely if torch was never imported — importing it here just to
|
||||
# check would add several seconds to shutdown with nothing to flush.
|
||||
if "torch" not in sys.modules:
|
||||
return
|
||||
try:
|
||||
import torch
|
||||
torch = sys.modules["torch"]
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
+6
-5
@@ -70,11 +70,12 @@ SUPPORTED_INPUT_FORMATS = [
|
||||
"vtt",
|
||||
]
|
||||
|
||||
# Supported languages for subtitle generation
|
||||
# Currently, only English (EN_US, EN_GB) are supported for subtitle generation.
|
||||
# This is because tokens that contain timestamps are not generated for other languages in the Kokoro pipeline.
|
||||
# Please refer to: https://github.com/hexgrad/kokoro/blob/6d87f4ae7abc2d14dbc4b3ef2e5f19852e861ac2/kokoro/pipeline.py
|
||||
SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION = [Language.EN_US, Language.EN_GB]
|
||||
# Supported languages for subtitle generation.
|
||||
# All languages are supported: only English emits per-word timestamped tokens
|
||||
# in the Kokoro pipeline, but other languages fall back to segment-level fake
|
||||
# tokens (see abogen.domain.tokens.FakeToken), so subtitles are still
|
||||
# generated at segment granularity.
|
||||
SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION = list(Language)
|
||||
|
||||
# Voice and sample text mapping
|
||||
SAMPLE_VOICE_TEXTS = {
|
||||
|
||||
@@ -33,7 +33,7 @@ def build_ffmpeg_command(path: Path, fmt: str, metadata: Optional[Dict[str, str]
|
||||
if fmt == "mp3":
|
||||
base += ["-c:a", "libmp3lame", "-qscale:a", "2"]
|
||||
elif fmt == "opus":
|
||||
base += ["-c:a", "libopus", "-b:a", "24000"]
|
||||
base += ["-c:a", "libopus", "-b:a", "128000"]
|
||||
elif fmt == "m4b":
|
||||
base += ["-c:a", "aac", "-q:a", "2", "-movflags", "+faststart+use_metadata_tags"]
|
||||
else:
|
||||
|
||||
@@ -60,7 +60,7 @@ def spacy_pre_tts_segmentation(
|
||||
text_segments is a list of sentences (always at least one element).
|
||||
active_split_pattern is the regex to use for TTS backend splitting.
|
||||
"""
|
||||
from abogen.domain.split_pattern import PUNCTUATION_COMMAS, get_split_pattern
|
||||
from abogen.domain.split_pattern import get_split_pattern
|
||||
|
||||
def _log(msg: str) -> None:
|
||||
if log_callback:
|
||||
@@ -99,25 +99,22 @@ def spacy_pre_tts_segmentation(
|
||||
|
||||
_log(f"spaCy: Text segmented into {len(spacy_sentences)} sentences...")
|
||||
|
||||
# Compute split_pattern override based on subtitle mode
|
||||
spacing_pattern = r"\s*" if lang_enum in _CJK_LANGS else r"\s+"
|
||||
|
||||
if subtitle_mode_str == "Sentence + Comma":
|
||||
active_split = r"(?<=[{}]){}|\n+".format(PUNCTUATION_COMMAS, spacing_pattern)
|
||||
else:
|
||||
# Sentence mode: spaCy already split, only split on newlines
|
||||
active_split = "\n"
|
||||
# spaCy already split at sentence boundaries; the engine only needs to
|
||||
# split on newlines. Commas are never used in the engine split pattern
|
||||
# for non-English (Sentence + Comma splits at commas only at subtitle
|
||||
# time, like English).
|
||||
active_split = "\n"
|
||||
|
||||
return spacy_sentences, active_split
|
||||
|
||||
|
||||
def _to_language_enum(lang_code: Any) -> Language:
|
||||
"""Convert lang_code to Language enum."""
|
||||
"""Convert lang_code to Language enum (ISO code or Language enum)."""
|
||||
if isinstance(lang_code, Language):
|
||||
return lang_code
|
||||
try:
|
||||
return Language.from_str(str(lang_code))
|
||||
except (ValueError, AttributeError):
|
||||
except ValueError:
|
||||
return Language.EN_US
|
||||
|
||||
|
||||
@@ -176,6 +173,8 @@ def tts_segments(
|
||||
segment_iter = backend(text, **kwargs)
|
||||
|
||||
chunk_start = current_time
|
||||
prev_tokens: Optional[List[Dict[str, Any]]] = None
|
||||
prev_was_fallback = True
|
||||
|
||||
for segment in segment_iter:
|
||||
graphemes_raw = getattr(segment, "graphemes", "") or ""
|
||||
@@ -188,8 +187,10 @@ def tts_segments(
|
||||
duration = len(audio) / SAMPLE_RATE
|
||||
|
||||
tokens_list = getattr(segment, "tokens", [])
|
||||
was_fallback = False
|
||||
if not tokens_list and graphemes:
|
||||
tokens_list = [FakeToken(graphemes, 0, duration)]
|
||||
was_fallback = True
|
||||
|
||||
tokens = [
|
||||
{
|
||||
@@ -201,6 +202,18 @@ def tts_segments(
|
||||
for tok in tokens_list
|
||||
]
|
||||
|
||||
# When the engine splits text on a punctuation pattern, the
|
||||
# whitespace between segments is consumed by the split. Restore a
|
||||
# trailing space on the boundary token of the previous segment so
|
||||
# subtitle processing sees the original spacing (only for real
|
||||
# per-word tokens; FakeToken fallbacks split via their own logic).
|
||||
if (
|
||||
not prev_was_fallback
|
||||
and prev_tokens
|
||||
and not prev_tokens[-1].get("whitespace")
|
||||
):
|
||||
prev_tokens[-1]["whitespace"] = " "
|
||||
|
||||
yield SegmentResult(
|
||||
graphemes=graphemes,
|
||||
audio=audio,
|
||||
@@ -209,6 +222,8 @@ def tts_segments(
|
||||
tokens=tokens,
|
||||
)
|
||||
|
||||
prev_tokens = tokens
|
||||
prev_was_fallback = was_fallback
|
||||
chunk_start += duration
|
||||
|
||||
|
||||
|
||||
@@ -212,8 +212,12 @@ class Language(str, Enum):
|
||||
|
||||
@property
|
||||
def supports_subtitle_tokens(self) -> bool:
|
||||
"""True if this language generates timestamped tokens for subtitles."""
|
||||
return self in (self.EN_US, self.EN_GB)
|
||||
"""True if this language supports subtitle generation.
|
||||
|
||||
All languages are supported: languages without per-word timestamped
|
||||
tokens fall back to segment-level fake tokens in the pipeline.
|
||||
"""
|
||||
return True
|
||||
|
||||
@classmethod
|
||||
def from_str(cls, value: str) -> Language:
|
||||
|
||||
@@ -5,10 +5,10 @@ from __future__ import annotations
|
||||
from abogen.domain.enums import Language, SubtitleMode
|
||||
|
||||
# Canonical punctuation sets covering all supported scripts:
|
||||
# ASCII (. ! ?), Arabic ؟, CJK (。!?), Devanagari ।
|
||||
PUNCTUATION_SENTENCE = r".!?؟。!?।"
|
||||
# ASCII (. ! ?), ellipsis (…), Arabic ؟, CJK (。!?), Devanagari ।
|
||||
PUNCTUATION_SENTENCE = r".!?…؟。!?।"
|
||||
# Commas: ASCII , CJK fullwidth ,CJK ideographic 、
|
||||
PUNCTUATION_SENTENCE_COMMA = r".!?,?。!?،,、।"
|
||||
PUNCTUATION_SENTENCE_COMMA = r".!?…,?。!?،,、।"
|
||||
PUNCTUATION_COMMAS = ",,、"
|
||||
|
||||
|
||||
@@ -16,7 +16,7 @@ def get_split_pattern(language: Language, subtitle_mode: str) -> str:
|
||||
"""Get the appropriate split pattern based on language and subtitle mode.
|
||||
|
||||
Args:
|
||||
language: Language enum value.
|
||||
language: Language enum value, ISO code, or kokoro letter code.
|
||||
subtitle_mode: Subtitle mode ("Sentence", "Sentence + Comma", "Line", etc.)
|
||||
|
||||
Returns:
|
||||
@@ -27,9 +27,18 @@ def get_split_pattern(language: Language, subtitle_mode: str) -> str:
|
||||
except ValueError:
|
||||
mode = SubtitleMode.DISABLED
|
||||
|
||||
# For English, always use newline splitting only
|
||||
# English: spaCy is NOT used for pre-TTS segmentation (it is only used
|
||||
# for post-TTS subtitle boundaries), so sentence boundaries for English
|
||||
# are applied at subtitle time, not in the TTS engine. Disabled, Line,
|
||||
# Sentence, and Sentence + Comma all keep newline-only engine splitting.
|
||||
if language in (Language.EN_US, Language.EN_GB):
|
||||
return "\n"
|
||||
if mode in (
|
||||
SubtitleMode.DISABLED,
|
||||
SubtitleMode.LINE,
|
||||
SubtitleMode.SENTENCE,
|
||||
SubtitleMode.SENTENCE_COMMA,
|
||||
):
|
||||
return "\n"
|
||||
|
||||
# Determine spacing pattern based on language
|
||||
spacing = r"\s*" if language.is_cjk else r"\s+"
|
||||
|
||||
@@ -13,6 +13,34 @@ from typing import List, Optional, Tuple
|
||||
from abogen.domain.enums import Language, SubtitleMode
|
||||
from abogen.domain.split_pattern import PUNCTUATION_SENTENCE, PUNCTUATION_SENTENCE_COMMA
|
||||
|
||||
_CLOSING_DELIMS = "\"\"\"\"'\"”’»›)]}」』"
|
||||
|
||||
|
||||
def _is_sentence_boundary(
|
||||
token: dict,
|
||||
current_sentence: List[dict],
|
||||
separator: str,
|
||||
) -> bool:
|
||||
"""Check whether token ends a sentence, considering closing quotes and brackets."""
|
||||
ws = token.get("whitespace", "") or ""
|
||||
if not ws:
|
||||
return False
|
||||
|
||||
# For Line mode, a newline in whitespace or text marks line boundary
|
||||
if separator == r"\n":
|
||||
return "\n" in ws or "\n" in str(token.get("text", ""))
|
||||
|
||||
text = str(token.get("text", ""))
|
||||
if re.search(rf"{separator}[{re.escape(_CLOSING_DELIMS)}]*$", text):
|
||||
return True
|
||||
|
||||
if len(current_sentence) >= 2 and text and all(c in _CLOSING_DELIMS for c in text):
|
||||
prev_text = str(current_sentence[-2].get("text", ""))
|
||||
if re.search(rf"{separator}$", prev_text):
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
|
||||
def process_subtitle_tokens(
|
||||
tokens_with_timestamps: List[dict],
|
||||
@@ -42,37 +70,55 @@ def process_subtitle_tokens(
|
||||
if not tokens_with_timestamps:
|
||||
return
|
||||
|
||||
if not isinstance(language, Language):
|
||||
try:
|
||||
language = Language.from_str(str(language))
|
||||
except ValueError:
|
||||
language = Language.EN_US
|
||||
|
||||
if isinstance(subtitle_mode, SubtitleMode):
|
||||
subtitle_mode_str = subtitle_mode.value
|
||||
else:
|
||||
subtitle_mode_str = str(subtitle_mode)
|
||||
|
||||
processed_tokens = tokens_with_timestamps
|
||||
|
||||
# For English with spaCy enabled and sentence-based modes, use spaCy for sentence boundaries
|
||||
# spaCy is disabled when subtitle mode is "Disabled" or "Line"
|
||||
use_spacy_for_english = (
|
||||
use_spacy_segmentation
|
||||
and subtitle_mode not in [SubtitleMode.DISABLED, SubtitleMode.LINE]
|
||||
and subtitle_mode_str not in [SubtitleMode.DISABLED.value, SubtitleMode.LINE.value, "Disabled", "Line"]
|
||||
and language in [Language.EN_US, Language.EN_GB]
|
||||
and subtitle_mode in [SubtitleMode.SENTENCE, SubtitleMode.SENTENCE_COMMA]
|
||||
and subtitle_mode_str in [SubtitleMode.SENTENCE.value, SubtitleMode.SENTENCE_COMMA.value, "Sentence", "Sentence + Comma"]
|
||||
)
|
||||
|
||||
if subtitle_mode == SubtitleMode.SENTENCE_HIGHLIGHT:
|
||||
if subtitle_mode_str in (SubtitleMode.SENTENCE_HIGHLIGHT.value, "Sentence + Highlighting"):
|
||||
_process_karaoke_highlighting(
|
||||
processed_tokens, subtitle_entries, max_subtitle_words, fallback_end_time
|
||||
)
|
||||
elif subtitle_mode in [SubtitleMode.SENTENCE, SubtitleMode.SENTENCE_COMMA, SubtitleMode.LINE]:
|
||||
if use_spacy_for_english and subtitle_mode != SubtitleMode.LINE:
|
||||
elif subtitle_mode_str in [
|
||||
SubtitleMode.SENTENCE.value,
|
||||
SubtitleMode.SENTENCE_COMMA.value,
|
||||
SubtitleMode.LINE.value,
|
||||
"Sentence",
|
||||
"Sentence + Comma",
|
||||
"Line",
|
||||
]:
|
||||
if use_spacy_for_english and subtitle_mode_str not in (SubtitleMode.LINE.value, "Line"):
|
||||
_process_spacy_sentences(
|
||||
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||
subtitle_mode, language, fallback_end_time
|
||||
subtitle_mode_str, language, fallback_end_time
|
||||
)
|
||||
else:
|
||||
_process_regex_sentences(
|
||||
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||
subtitle_mode, fallback_end_time
|
||||
subtitle_mode_str, fallback_end_time
|
||||
)
|
||||
else:
|
||||
# Word count-based grouping (e.g., "5" for 5-word groups)
|
||||
_process_word_count(
|
||||
processed_tokens, subtitle_entries, max_subtitle_words,
|
||||
subtitle_mode, fallback_end_time
|
||||
subtitle_mode_str, fallback_end_time
|
||||
)
|
||||
|
||||
|
||||
@@ -91,10 +137,8 @@ def _process_karaoke_highlighting(
|
||||
current_sentence.append(token)
|
||||
word_count += 1
|
||||
|
||||
# Split sentences based on separator or word count
|
||||
if (
|
||||
re.search(separator, token["text"]) and token.get("whitespace") == " "
|
||||
) or word_count >= max_subtitle_words:
|
||||
is_boundary = _is_sentence_boundary(token, current_sentence, separator)
|
||||
if is_boundary or word_count >= max_subtitle_words:
|
||||
if current_sentence:
|
||||
# Create karaoke subtitle entry for this sentence
|
||||
start_time = current_sentence[0]["start"]
|
||||
@@ -109,13 +153,18 @@ def _process_karaoke_highlighting(
|
||||
if t.get("end") is not None and t.get("start") is not None
|
||||
else 0.5
|
||||
)
|
||||
duration_cs = int(duration * 100)
|
||||
try:
|
||||
duration_cs = int(duration * 100)
|
||||
except (ValueError, OverflowError, TypeError):
|
||||
duration_cs = 50
|
||||
# Add karaoke effect
|
||||
karaoke_text += f"{{\\kf{duration_cs}}}{t['text']}{t.get('whitespace', '') or ''}"
|
||||
karaoke_text += f"{{\\kf{duration_cs}}}{t.get('text', '')}{t.get('whitespace', '') or ''}"
|
||||
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, karaoke_text.strip())
|
||||
)
|
||||
text_stripped = karaoke_text.strip()
|
||||
if text_stripped:
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, text_stripped)
|
||||
)
|
||||
current_sentence = []
|
||||
word_count = 0
|
||||
|
||||
@@ -128,9 +177,14 @@ def _process_karaoke_highlighting(
|
||||
karaoke_text = ""
|
||||
for t in current_sentence:
|
||||
duration = t["end"] - t["start"] if t.get("end") and t.get("start") else 0.5
|
||||
duration_cs = int(duration * 100)
|
||||
karaoke_text += f"{{\\kf{duration_cs}}}{t['text']}{t.get('whitespace', '') or ''}"
|
||||
subtitle_entries.append((start_time, end_time, karaoke_text.strip()))
|
||||
try:
|
||||
duration_cs = int(duration * 100)
|
||||
except (ValueError, OverflowError, TypeError):
|
||||
duration_cs = 50
|
||||
karaoke_text += f"{{\\kf{duration_cs}}}{t.get('text', '')}{t.get('whitespace', '') or ''}"
|
||||
text_stripped = karaoke_text.strip()
|
||||
if text_stripped:
|
||||
subtitle_entries.append((start_time, end_time, text_stripped))
|
||||
|
||||
# Fallback for last entry
|
||||
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||
@@ -166,7 +220,7 @@ def _process_spacy_sentences(
|
||||
# Build full text and track character positions to token indices
|
||||
full_text = ""
|
||||
for token in tokens:
|
||||
text_part = token["text"] + (token.get("whitespace") or "")
|
||||
text_part = str(token.get("text", "")) + (token.get("whitespace") or "")
|
||||
full_text += text_part
|
||||
|
||||
# Get sentence boundaries from spaCy
|
||||
@@ -174,7 +228,7 @@ def _process_spacy_sentences(
|
||||
sentence_boundaries = [sent.end_char for sent in doc.sents]
|
||||
|
||||
# For "Sentence + Comma" mode, also split on commas
|
||||
if subtitle_mode == SubtitleMode.SENTENCE_COMMA:
|
||||
if subtitle_mode in (SubtitleMode.SENTENCE_COMMA.value, "Sentence + Comma"):
|
||||
comma_positions = [
|
||||
i + 1 for i, c in enumerate(full_text) if c == ","
|
||||
]
|
||||
@@ -182,6 +236,56 @@ def _process_spacy_sentences(
|
||||
set(sentence_boundaries + comma_positions)
|
||||
)
|
||||
|
||||
# spaCy does not treat ellipsis ("...", "..", "…") as a sentence
|
||||
# boundary ("Lorem ipsum... Lorem..." stays one sentence), so ellipsis
|
||||
# runs followed by whitespace/end would merge into a single subtitle
|
||||
# entry. Add explicit boundaries after them. Single dots ("Mr.") stay
|
||||
# spaCy's responsibility so abbreviations don't regress.
|
||||
for m in re.finditer(r"\.{2,}(?=[\s\"'”’»›)\]}]|$)|…(?=[\s\"'”’»›)\]}]|$)", full_text):
|
||||
sentence_boundaries.append(m.end())
|
||||
# Double newlines are paragraph breaks: always split, even when spaCy
|
||||
# sees no sentence boundary.
|
||||
for m in re.finditer(r"\n{2,}", full_text):
|
||||
sentence_boundaries.append(m.end())
|
||||
sentence_boundaries = sorted(set(sentence_boundaries))
|
||||
|
||||
# Multi-sentence single FakeToken handling
|
||||
if len(tokens) == 1 and len(sentence_boundaries) > 1:
|
||||
single = tokens[0]
|
||||
start_time = single.get("start", 0.0) or 0.0
|
||||
end_time = single.get("end")
|
||||
duration = (end_time - start_time) if (end_time is not None and end_time > start_time) else 0.0
|
||||
|
||||
prev_pos = 0
|
||||
cur_start = start_time
|
||||
total_chars = max(len(full_text), 1)
|
||||
|
||||
for i, b_pos in enumerate(sentence_boundaries):
|
||||
piece = full_text[prev_pos:b_pos].strip()
|
||||
if not piece:
|
||||
prev_pos = b_pos
|
||||
continue
|
||||
if i == len(sentence_boundaries) - 1:
|
||||
cur_end = end_time if end_time is not None else (cur_start + 1.0)
|
||||
else:
|
||||
cur_end = cur_start + duration * len(piece) / total_chars
|
||||
subtitle_entries.append((cur_start, cur_end, piece))
|
||||
cur_start = cur_end
|
||||
prev_pos = b_pos
|
||||
|
||||
if prev_pos < len(full_text):
|
||||
remainder = full_text[prev_pos:].strip()
|
||||
if remainder:
|
||||
remainder_end = end_time
|
||||
if remainder_end is None:
|
||||
remainder_end = fallback_end_time
|
||||
if remainder_end is None:
|
||||
remainder_end = cur_start
|
||||
subtitle_entries.append((cur_start, remainder_end, remainder))
|
||||
|
||||
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||
return
|
||||
|
||||
# Group tokens by sentence boundaries
|
||||
current_sentence = []
|
||||
word_count = 0
|
||||
@@ -191,7 +295,7 @@ def _process_spacy_sentences(
|
||||
for token in tokens:
|
||||
current_sentence.append(token)
|
||||
word_count += 1
|
||||
text_len = len(token["text"]) + len(token.get("whitespace") or "")
|
||||
text_len = len(str(token.get("text", ""))) + len(token.get("whitespace") or "")
|
||||
current_char_pos += text_len
|
||||
|
||||
# Check if we've hit a sentence boundary or max words
|
||||
@@ -204,15 +308,19 @@ def _process_spacy_sentences(
|
||||
start_time = current_sentence[0]["start"]
|
||||
end_time = current_sentence[-1]["end"]
|
||||
sentence_text = "".join(
|
||||
t["text"] + (t.get("whitespace") or "")
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "")
|
||||
for t in current_sentence
|
||||
)
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text.strip())
|
||||
)
|
||||
).strip()
|
||||
if sentence_text:
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text)
|
||||
)
|
||||
current_sentence = []
|
||||
word_count = 0
|
||||
if at_boundary:
|
||||
while (
|
||||
boundary_idx < len(sentence_boundaries)
|
||||
and current_char_pos >= sentence_boundaries[boundary_idx]
|
||||
):
|
||||
boundary_idx += 1
|
||||
|
||||
# Add remaining tokens
|
||||
@@ -220,12 +328,13 @@ def _process_spacy_sentences(
|
||||
start_time = current_sentence[0]["start"]
|
||||
end_time = current_sentence[-1]["end"]
|
||||
sentence_text = "".join(
|
||||
t["text"] + (t.get("whitespace") or "")
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "")
|
||||
for t in current_sentence
|
||||
)
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text.strip())
|
||||
)
|
||||
).strip()
|
||||
if sentence_text:
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text)
|
||||
)
|
||||
|
||||
# Fallback for last entry
|
||||
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||
@@ -240,9 +349,9 @@ def _process_regex_sentences(
|
||||
) -> None:
|
||||
"""Process tokens using regex for sentence boundary detection."""
|
||||
# Define separator pattern based on mode
|
||||
if subtitle_mode == SubtitleMode.LINE:
|
||||
if subtitle_mode in (SubtitleMode.LINE.value, "Line"):
|
||||
separator = r"\n"
|
||||
elif subtitle_mode == SubtitleMode.SENTENCE:
|
||||
elif subtitle_mode in (SubtitleMode.SENTENCE.value, "Sentence"):
|
||||
separator = rf"[{PUNCTUATION_SENTENCE}]"
|
||||
else: # Sentence + Comma
|
||||
separator = rf"[{PUNCTUATION_SENTENCE_COMMA}]"
|
||||
@@ -255,22 +364,22 @@ def _process_regex_sentences(
|
||||
word_count += 1
|
||||
|
||||
# Split sentences based on separator or word count
|
||||
if (
|
||||
re.search(separator, token["text"]) and token.get("whitespace") == " "
|
||||
) or word_count >= max_subtitle_words:
|
||||
is_boundary = _is_sentence_boundary(token, current_sentence, separator)
|
||||
if is_boundary or word_count >= max_subtitle_words:
|
||||
if current_sentence:
|
||||
# Create subtitle entry for this sentence
|
||||
start_time = current_sentence[0]["start"]
|
||||
end_time = current_sentence[-1]["end"]
|
||||
|
||||
# Simplified text joining logic
|
||||
sentence_text = ""
|
||||
for t in current_sentence:
|
||||
sentence_text += t["text"] + (t.get("whitespace") or "")
|
||||
sentence_text = "".join(
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "")
|
||||
for t in current_sentence
|
||||
).strip()
|
||||
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text.strip())
|
||||
)
|
||||
if sentence_text:
|
||||
subtitle_entries.append(
|
||||
(start_time, end_time, sentence_text)
|
||||
)
|
||||
current_sentence = []
|
||||
word_count = 0
|
||||
|
||||
@@ -279,23 +388,39 @@ def _process_regex_sentences(
|
||||
start_time = current_sentence[0]["start"]
|
||||
end_time = current_sentence[-1]["end"]
|
||||
|
||||
sentence_text = ""
|
||||
for t in current_sentence:
|
||||
sentence_text += t["text"] + (t.get("whitespace") or "")
|
||||
sentence_text = sentence_text.strip()
|
||||
sentence_text = "".join(
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "")
|
||||
for t in current_sentence
|
||||
).strip()
|
||||
|
||||
if len(current_sentence) == 1:
|
||||
parts = re.split(rf"(?<={separator})\s+", sentence_text)
|
||||
split_pat = (
|
||||
r"\n+"
|
||||
if separator == r"\n"
|
||||
else rf"(?<={separator})\s+|(?<={separator}[{re.escape(_CLOSING_DELIMS)}])\s+"
|
||||
)
|
||||
parts = [p.strip() for p in re.split(split_pat, sentence_text) if p.strip()]
|
||||
if len(parts) > 1:
|
||||
d = end_time - start_time
|
||||
d = (end_time - start_time) if (end_time is not None and start_time is not None and end_time > start_time) else 0.0
|
||||
total_len = max(len(sentence_text), 1)
|
||||
cur_s = start_time if start_time is not None else 0.0
|
||||
for i, p in enumerate(parts):
|
||||
e = end_time if i == len(parts) - 1 else start_time + d * len(p) / len(sentence_text)
|
||||
subtitle_entries.append((start_time, e, p.strip()))
|
||||
start_time = e
|
||||
if i == len(parts) - 1 and end_time is not None:
|
||||
e = end_time
|
||||
else:
|
||||
e = cur_s + d * len(p) / total_len
|
||||
subtitle_entries.append((cur_s, e, p))
|
||||
cur_s = e
|
||||
current_sentence = []
|
||||
|
||||
if current_sentence:
|
||||
subtitle_entries.append((start_time, end_time, sentence_text))
|
||||
if current_sentence and sentence_text:
|
||||
safe_start = start_time if start_time is not None else 0.0
|
||||
safe_end = end_time
|
||||
if safe_end is None:
|
||||
safe_end = fallback_end_time
|
||||
if safe_end is None:
|
||||
safe_end = safe_start
|
||||
subtitle_entries.append((safe_start, safe_end, sentence_text))
|
||||
|
||||
# Fallback for last entry
|
||||
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||
@@ -328,27 +453,29 @@ def _process_word_count(
|
||||
# Split after counting N spaces
|
||||
if space_count >= word_count:
|
||||
text = "".join(
|
||||
t["text"] + (t.get("whitespace") or "")
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "")
|
||||
for t in current_group
|
||||
)
|
||||
subtitle_entries.append(
|
||||
(
|
||||
current_group[0]["start"],
|
||||
current_group[-1]["end"],
|
||||
text.strip(),
|
||||
).strip()
|
||||
if text:
|
||||
subtitle_entries.append(
|
||||
(
|
||||
current_group[0]["start"],
|
||||
current_group[-1]["end"],
|
||||
text,
|
||||
)
|
||||
)
|
||||
)
|
||||
current_group = []
|
||||
space_count = 0
|
||||
|
||||
# Add any remaining tokens
|
||||
if current_group:
|
||||
text = "".join(
|
||||
t["text"] + (t.get("whitespace") or "") for t in current_group
|
||||
)
|
||||
subtitle_entries.append(
|
||||
(current_group[0]["start"], current_group[-1]["end"], text.strip())
|
||||
)
|
||||
str(t.get("text", "")) + (t.get("whitespace") or "") for t in current_group
|
||||
).strip()
|
||||
if text:
|
||||
subtitle_entries.append(
|
||||
(current_group[0]["start"], current_group[-1]["end"], text)
|
||||
)
|
||||
|
||||
# Fallback for last entry
|
||||
_apply_fallback_end_time(subtitle_entries, fallback_end_time)
|
||||
|
||||
@@ -9,15 +9,26 @@ from collections import Counter
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Dict, Iterable, List, Mapping, Optional, Tuple
|
||||
|
||||
try: # pragma: no cover - fallback when spaCy not available during tests
|
||||
import spacy # type: ignore[import-not-found]
|
||||
except Exception: # pragma: no cover - spaCy optional during runtime bootstrap
|
||||
spacy = None
|
||||
|
||||
_Language = Any # type: ignore[misc,assignment]
|
||||
Doc = Any # type: ignore[misc,assignment]
|
||||
Span = Any # type: ignore[misc,assignment]
|
||||
|
||||
_SPACY: Any = None
|
||||
_SPACY_LOADED = False
|
||||
|
||||
|
||||
def _get_spacy() -> Any:
|
||||
"""Import spaCy lazily (it pulls in torch/thinc, ~2s at startup)."""
|
||||
global _SPACY, _SPACY_LOADED
|
||||
if not _SPACY_LOADED:
|
||||
_SPACY_LOADED = True
|
||||
try: # pragma: no cover - fallback when spaCy not available during tests
|
||||
import spacy # type: ignore[import-not-found]
|
||||
except Exception: # pragma: no cover - spaCy optional during runtime bootstrap
|
||||
spacy = None
|
||||
_SPACY = spacy
|
||||
return _SPACY
|
||||
|
||||
|
||||
_TITLE_PREFIXES = (
|
||||
"mr",
|
||||
@@ -167,6 +178,7 @@ def _resolve_model_name(language: str) -> str:
|
||||
|
||||
|
||||
def _load_model(language: str) -> Any:
|
||||
spacy = _get_spacy()
|
||||
if spacy is None:
|
||||
raise EntityModelError(
|
||||
"spaCy is not available. Install spaCy to enable entity extraction."
|
||||
|
||||
@@ -5,10 +5,21 @@ import re
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Dict, Iterable, List, Mapping, Optional, Sequence, Tuple
|
||||
|
||||
try: # pragma: no cover - optional dependency
|
||||
import spacy # type: ignore
|
||||
except Exception: # pragma: no cover - spaCy may be unavailable in minimal environments
|
||||
spacy = None
|
||||
_SPACY: Any = None
|
||||
_SPACY_LOADED = False
|
||||
|
||||
|
||||
def _get_spacy() -> Any:
|
||||
"""Import spaCy lazily (it pulls in torch/thinc, ~2s at startup)."""
|
||||
global _SPACY, _SPACY_LOADED
|
||||
if not _SPACY_LOADED:
|
||||
_SPACY_LOADED = True
|
||||
try: # pragma: no cover - optional dependency
|
||||
import spacy # type: ignore
|
||||
except Exception: # pragma: no cover - spaCy may be unavailable in minimal environments
|
||||
spacy = None
|
||||
_SPACY = spacy
|
||||
return _SPACY
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
@@ -184,6 +195,7 @@ def _build_replacement_sentence(
|
||||
|
||||
|
||||
def _load_spacy(language: str) -> Any:
|
||||
spacy = _get_spacy()
|
||||
if spacy is None:
|
||||
return None
|
||||
|
||||
@@ -221,7 +233,7 @@ def extract_heteronym_overrides(
|
||||
if not lang.startswith("en"):
|
||||
return []
|
||||
|
||||
if spacy is None:
|
||||
if _get_spacy() is None:
|
||||
return []
|
||||
|
||||
nlp = _load_spacy(lang)
|
||||
|
||||
@@ -220,8 +220,10 @@ class AssWriter(SubtitleWriter):
|
||||
|
||||
style = "Default"
|
||||
if self.config.mode == SubtitleMode.SENTENCE_HIGHLIGHT:
|
||||
# Add karaoke tags for highlighting
|
||||
text = self._add_karaoke_tags(text)
|
||||
# Entries from process_subtitle_tokens already carry per-word
|
||||
# {\kf...} timing; only synthesize simplified tags when absent.
|
||||
if "{\\k" not in text:
|
||||
text = self._add_karaoke_tags(text)
|
||||
style = "Highlight"
|
||||
|
||||
alignment_tag = r"{\an5}" if self._is_centered else ""
|
||||
@@ -248,6 +250,19 @@ class AssWriter(SubtitleWriter):
|
||||
return f"{hours}:{minutes:02d}:{secs:05.2f}"
|
||||
|
||||
|
||||
def _coerce_mode(mode: str) -> SubtitleMode:
|
||||
"""Parse a subtitle mode, tolerating word-count strings like "5 words".
|
||||
|
||||
Word-count modes are grouped upstream (subtitle_generation) and the writer
|
||||
only branches on SubtitleMode.SENTENCE_HIGHLIGHT, so any non-highlight
|
||||
fallback is behaviorally equivalent for the writers.
|
||||
"""
|
||||
try:
|
||||
return SubtitleMode(mode)
|
||||
except ValueError:
|
||||
return SubtitleMode.SENTENCE
|
||||
|
||||
|
||||
def create_subtitle_writer(
|
||||
path: Path,
|
||||
format: str,
|
||||
@@ -257,7 +272,7 @@ def create_subtitle_writer(
|
||||
) -> SubtitleWriter:
|
||||
"""Factory function to create subtitle writer."""
|
||||
fmt = SubtitleFormat(format.lower())
|
||||
mode = SubtitleMode(mode)
|
||||
mode = _coerce_mode(mode)
|
||||
align = SubtitleAlignment(alignment.lower())
|
||||
|
||||
config = SubtitleConfig(
|
||||
|
||||
@@ -672,6 +672,15 @@ def tokenize_with_spans(text: str) -> List[Tuple[str, int, int]]:
|
||||
]
|
||||
|
||||
|
||||
_OPENING_PUNCTUATION_CHARS = "«‹“‘([{¡¿「『"
|
||||
_CLOSING_PUNCTUATION_CHARS = "»›”’)]}」』"
|
||||
_STANDARD_PUNCTUATION_CHARS = ",.;:!?%"
|
||||
|
||||
_OPENING_PUNCT_CLASS = re.escape(_OPENING_PUNCTUATION_CHARS)
|
||||
_CLOSING_PUNCT_CLASS = re.escape(_CLOSING_PUNCTUATION_CHARS)
|
||||
_STANDARD_PUNCT_CLASS = re.escape(_STANDARD_PUNCTUATION_CHARS)
|
||||
|
||||
|
||||
def _cleanup_spacing(text: str) -> str:
|
||||
if not text:
|
||||
return text
|
||||
@@ -679,22 +688,39 @@ def _cleanup_spacing(text: str) -> str:
|
||||
for marker in ("\ufeff", "\u200b", "\u200c", "\u200d", "\u2060"):
|
||||
text = text.replace(marker, "")
|
||||
|
||||
# Collapse spaces before closing punctuation.
|
||||
text = re.sub(r"\s+([,.;:!?%])", r"\1", text)
|
||||
text = re.sub(r"\s+([’\"”»›)\]\}])", r"\1", text)
|
||||
# Collapse spaces before standard punctuation and unambiguous closing quotes/brackets.
|
||||
text = re.sub(rf"\s+([{_STANDARD_PUNCT_CLASS}])", r"\1", text)
|
||||
text = re.sub(rf"\s+([{_CLOSING_PUNCT_CLASS}])", r"\1", text)
|
||||
|
||||
# Remove spaces directly after opening punctuation/quotes.
|
||||
text = re.sub(r"([«‹“‘\"'(\[\{])\s+", r"\1", text)
|
||||
# Remove spaces directly after unambiguous opening punctuation/quotes.
|
||||
text = re.sub(rf"([{_OPENING_PUNCT_CLASS}])\s+", r"\1", text)
|
||||
|
||||
# Handle ambiguous straight quotes (\", ')
|
||||
# 1. Remove spaces directly after opening straight quotes:
|
||||
# e.g. ' \" word' -> ' \"word', '^\" word' -> '\"word', '(\" word' -> '(\"word'
|
||||
text = re.sub(rf"(^|[\s{_OPENING_PUNCT_CLASS}])([\"\'])\s+", r"\1\2", text)
|
||||
# 2. Collapse spaces directly before closing straight quotes:
|
||||
# e.g. 'word \" ' -> 'word\" ', 'word \".' -> 'word\".'
|
||||
text = re.sub(rf"\s+([\"\'])([\s{_STANDARD_PUNCT_CLASS}{_CLOSING_PUNCT_CLASS}]|$)", r"\1\2", text)
|
||||
|
||||
# Ensure spaces exist after sentence punctuation when followed by a word/quote.
|
||||
text = re.sub(r"([,.;:!?%])(?![\s”'\"’»›)])", r"\1 ", text)
|
||||
text = re.sub(r"([”\"’])(?![\s.,;:!?\"”’»›)])", r"\1 ", text)
|
||||
# Runs of punctuation ("...", "?!?", "!!") must stay together: no space
|
||||
# inside the run, only after it ("a...b" -> "a... b").
|
||||
text = re.sub(rf"([{_STANDARD_PUNCT_CLASS}])(?![\s{_STANDARD_PUNCT_CLASS}{_CLOSING_PUNCT_CLASS}\"\'”’»›)])", r"\1 ", text)
|
||||
# Ensure space after unambiguous closing quote when followed by a word (e.g. '”Next' -> '” Next')
|
||||
text = re.sub(rf"([{_CLOSING_PUNCT_CLASS}])(?![\s{_STANDARD_PUNCT_CLASS}{_CLOSING_PUNCT_CLASS}\"\'”’»›)])", r"\1 ", text)
|
||||
# Straight double quote closing (preceded by non-whitespace) followed directly by a word/number/opening
|
||||
text = re.sub(rf"(\S\")([A-Za-z0-9{_OPENING_PUNCT_CLASS}])", r"\1 \2", text)
|
||||
# Straight single quote closing (preceded by punctuation, not internal word apostrophe) followed by a word
|
||||
text = re.sub(rf"([{_STANDARD_PUNCT_CLASS}{_CLOSING_PUNCT_CLASS}]\')([A-Za-z0-9{_OPENING_PUNCT_CLASS}])", r"\1 \2", text)
|
||||
|
||||
# Tighten hyphen/em dash spacing between word characters.
|
||||
text = re.sub(r"(?<=\w)\s*([-–—])\s*(?=\w)", r"\1", text)
|
||||
|
||||
# Normalize multiple spaces.
|
||||
text = re.sub(r"\s{2,}", " ", text)
|
||||
# Normalize multiple spaces, preserving paragraph breaks (double
|
||||
# newlines must survive so the TTS engine can split on them).
|
||||
text = re.sub(r"[^\S\n]{2,}", " ", text)
|
||||
text = re.sub(r"\n{3,}", "\n\n", text)
|
||||
return text.strip()
|
||||
|
||||
|
||||
@@ -1622,8 +1648,18 @@ def normalize_apostrophes(
|
||||
results.append((tok, category, norm))
|
||||
normalized_tokens.append(norm)
|
||||
|
||||
filtered = [token for token in normalized_tokens if token]
|
||||
normalized_text = _cleanup_spacing(" ".join(filtered))
|
||||
out_pieces: List[str] = []
|
||||
last_end = 0
|
||||
for (tok, start, end), norm in zip(token_entries, normalized_tokens):
|
||||
if start > last_end:
|
||||
out_pieces.append(text[last_end:start])
|
||||
out_pieces.append(norm)
|
||||
last_end = end
|
||||
if last_end < len(text):
|
||||
out_pieces.append(text[last_end:])
|
||||
|
||||
reconstructed = "".join(out_pieces)
|
||||
normalized_text = _cleanup_spacing(reconstructed)
|
||||
return normalized_text, results
|
||||
|
||||
|
||||
@@ -1824,7 +1860,10 @@ def _normalize_grouped_numbers(text: str, cfg: ApostropheConfig) -> str:
|
||||
for digit in trimmed_fraction:
|
||||
if not digit.isdigit():
|
||||
return token
|
||||
digit_words.append(_DIGIT_WORDS[int(digit)])
|
||||
try:
|
||||
digit_words.append(_DIGIT_WORDS[int(digit)])
|
||||
except (ValueError, IndexError):
|
||||
return token
|
||||
|
||||
spoken = f"{integer_words} point {' '.join(digit_words)}"
|
||||
return f"minus {spoken}" if is_negative else spoken
|
||||
@@ -1846,18 +1885,27 @@ def _normalize_grouped_numbers(text: str, cfg: ApostropheConfig) -> str:
|
||||
# Magnitude case: $2.5 million -> two point five million dollars
|
||||
if "." in amount_str:
|
||||
integer_part, fraction_part = amount_str.split(".", 1)
|
||||
integer_val = int(integer_part)
|
||||
try:
|
||||
integer_val = int(integer_part)
|
||||
except ValueError:
|
||||
return match.group(0)
|
||||
integer_words = _int_to_words(integer_val, language)
|
||||
|
||||
# Spell out fraction digits
|
||||
digit_words = []
|
||||
for digit in fraction_part:
|
||||
if digit.isdigit():
|
||||
digit_words.append(_DIGIT_WORDS[int(digit)])
|
||||
try:
|
||||
digit_words.append(_DIGIT_WORDS[int(digit)])
|
||||
except (ValueError, IndexError):
|
||||
return match.group(0)
|
||||
|
||||
amount_spoken = f"{integer_words} point {' '.join(digit_words)}"
|
||||
else:
|
||||
amount_spoken = _int_to_words(int(amount), language)
|
||||
try:
|
||||
amount_spoken = _int_to_words(int(amount), language)
|
||||
except (ValueError, OverflowError):
|
||||
return match.group(0)
|
||||
|
||||
currency_names = {
|
||||
"$": "dollars",
|
||||
|
||||
@@ -45,9 +45,9 @@ import urllib.parse
|
||||
import textwrap
|
||||
|
||||
# Setup logging
|
||||
logging.basicConfig(
|
||||
level=logging.INFO, format="%(asctime)s - %(levelname)s - %(message)s"
|
||||
)
|
||||
from abogen.utils import setup_console_logging
|
||||
|
||||
setup_console_logging()
|
||||
|
||||
_HTML_TAG_PATTERN = re.compile(r"<[^>]+>")
|
||||
_LEADING_DASH_PATTERN = re.compile(r"^\s*[-–—]\s*")
|
||||
|
||||
+17
-19
@@ -1,5 +1,6 @@
|
||||
import os
|
||||
import time
|
||||
import logging
|
||||
import hashlib # For generating unique cache filenames
|
||||
from pathlib import Path
|
||||
from platformdirs import user_desktop_dir
|
||||
@@ -22,6 +23,7 @@ from abogen.constants import (
|
||||
)
|
||||
from abogen.infrastructure.subtitle_writer import make_subtitle_writer, resolve_subtitle_format
|
||||
from abogen.domain.split_pattern import get_split_pattern
|
||||
from abogen.domain.enums import Language
|
||||
from abogen.domain.subtitle_processor import (
|
||||
parse_subtitle_file,
|
||||
process_subtitle_entries,
|
||||
@@ -49,6 +51,8 @@ import abogen.hf_tracker as hf_tracker
|
||||
import static_ffmpeg
|
||||
import threading # for efficient waiting
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
|
||||
# Configuration constants
|
||||
@@ -63,7 +67,6 @@ from abogen.subtitle_utils import (
|
||||
sanitize_name_for_os,
|
||||
split_text_by_voice_markers
|
||||
)
|
||||
from abogen.domain.split_pattern import PUNCTUATION_COMMAS
|
||||
|
||||
class CountdownDialog(QDialog):
|
||||
"""Base dialog with auto-accept countdown functionality"""
|
||||
@@ -347,7 +350,7 @@ class ConversionThread(QThread):
|
||||
return samples_processed
|
||||
|
||||
def run(self):
|
||||
print(
|
||||
logger.info(
|
||||
f"\nVoice: {self.voice}\nLanguage: {self.lang_code}\nSpeed: {self.speed}\nGPU: {self.use_gpu}\nFile: {self.file_name}\nSubtitle mode: {self.subtitle_mode}\nOutput format: {self.output_format}\nSave option: {self.save_option}\n"
|
||||
)
|
||||
try:
|
||||
@@ -872,12 +875,11 @@ class ConversionThread(QThread):
|
||||
)
|
||||
spacy_sentences = None
|
||||
active_split_pattern = self.split_pattern
|
||||
spacing_pattern = r"\s*" if self.lang_code in ["z", "j"] else r"\s+"
|
||||
|
||||
# Pre-load spaCy model for English if it will be needed for subtitle generation
|
||||
if (
|
||||
use_spacy
|
||||
and self.lang_code in ["a", "b"]
|
||||
and self.lang_code in (Language.EN_US, Language.EN_GB)
|
||||
and self.subtitle_mode in ["Sentence", "Sentence + Comma"]
|
||||
):
|
||||
from abogen.spacy_utils import get_spacy_model
|
||||
@@ -894,7 +896,7 @@ class ConversionThread(QThread):
|
||||
)
|
||||
)
|
||||
|
||||
if use_spacy and self.lang_code not in ["a", "b"]:
|
||||
if use_spacy and self.lang_code not in (Language.EN_US, Language.EN_GB):
|
||||
# Non-English: use spaCy for pre-TTS segmentation
|
||||
self.log_updated.emit(
|
||||
("\nUsing spaCy for sentence segmentation (pre-TTS)...", "grey")
|
||||
@@ -913,15 +915,11 @@ class ConversionThread(QThread):
|
||||
"grey",
|
||||
)
|
||||
)
|
||||
# For Sentence + Comma mode, still split on commas within spaCy sentences
|
||||
if self.subtitle_mode == "Sentence + Comma":
|
||||
active_split_pattern = r"(?<=[{}]){}|\n+".format(
|
||||
PUNCTUATION_COMMAS, spacing_pattern
|
||||
)
|
||||
else:
|
||||
active_split_pattern = (
|
||||
"\n" # Use newline splitting for Sentence mode
|
||||
)
|
||||
# spaCy already split at sentence boundaries; the
|
||||
# engine only splits on newlines. Commas are never
|
||||
# used in the engine split pattern (Sentence +
|
||||
# Comma splits at commas only at subtitle time).
|
||||
active_split_pattern = "\n"
|
||||
else:
|
||||
self.log_updated.emit(
|
||||
("\nspaCy: Fallback to default segmentation...", "grey")
|
||||
@@ -932,10 +930,10 @@ class ConversionThread(QThread):
|
||||
|
||||
# Print active split pattern used by the TTS engine once for this batch
|
||||
try:
|
||||
print(f"Using split pattern: {active_split_pattern!r}")
|
||||
logger.info(f"Using split pattern: {active_split_pattern!r}")
|
||||
except Exception:
|
||||
# Print must never break processing
|
||||
print("Using split pattern: (unprintable)")
|
||||
# Logging must never break processing
|
||||
logger.warning("Using split pattern: (unprintable)")
|
||||
|
||||
for text_segment in text_segments:
|
||||
def _qt_check_cancel() -> bool:
|
||||
@@ -1011,7 +1009,7 @@ class ConversionThread(QThread):
|
||||
audio_sink=merged_sink if merge_chapters_at_end else None,
|
||||
subtitle_mode=self.subtitle_mode,
|
||||
max_subtitle_words=self.max_subtitle_words,
|
||||
lang_code=self.lang_code,
|
||||
language=self.lang_code,
|
||||
use_spacy_segmentation=getattr(self, "use_spacy_segmentation", False),
|
||||
)
|
||||
|
||||
@@ -1444,7 +1442,7 @@ class VoicePreviewThread(QThread):
|
||||
return os.path.join(self.cache_dir, filename)
|
||||
|
||||
def run(self):
|
||||
print(
|
||||
logger.info(
|
||||
f"\nVoice: {self.voice}\nLanguage: {self.lang_code}\nSpeed: {self.speed}\nGPU: {self.use_gpu}\n"
|
||||
)
|
||||
|
||||
|
||||
+172
-112
@@ -5,9 +5,12 @@ import tempfile
|
||||
import platform
|
||||
import base64
|
||||
import re
|
||||
import logging
|
||||
from abogen.pyqt.queue_manager_gui import QueueManager
|
||||
from abogen.pyqt.queued_item import QueuedItem
|
||||
|
||||
_log = logging.getLogger("abogen.gui")
|
||||
|
||||
import abogen.hf_tracker as hf_tracker
|
||||
import hashlib # Added for cache path generation
|
||||
from PyQt6.QtWidgets import (
|
||||
@@ -75,6 +78,7 @@ from abogen.domain.text_utils import calculate_text_length
|
||||
|
||||
from abogen.pyqt.conversion import ConversionThread, VoicePreviewThread, PlayAudioThread, ChapterOptionsDialog, TimestampDetectionDialog
|
||||
from abogen.pyqt.book_handler import HandlerDialog
|
||||
from abogen.domain.enums import Language
|
||||
from abogen.constants import (
|
||||
PROGRAM_NAME,
|
||||
VERSION,
|
||||
@@ -88,8 +92,9 @@ from abogen.constants import (
|
||||
from abogen.tts_plugin.utils import get_voices
|
||||
import threading
|
||||
from abogen.pyqt.voice_formula_gui import VoiceFormulaDialog
|
||||
from abogen.voice_profiles import load_profiles
|
||||
from abogen.voice_profiles import load_profiles, resolve_profile_language
|
||||
from abogen.domain.settings_core import all_settings_defaults
|
||||
from plugins.kokoro.engine import language_for_code, language_for_voice_id
|
||||
|
||||
# Module-level default cache for use outside __init__
|
||||
_DEFAULTS = all_settings_defaults()
|
||||
@@ -132,6 +137,28 @@ class ThreadSafeLogSignal(QObject):
|
||||
self.log_signal.emit(message)
|
||||
|
||||
|
||||
_UPDATE_CHECK_URL = "https://raw.githubusercontent.com/denizsafak/abogen/refs/heads/main/abogen/VERSION"
|
||||
_UPDATE_CHECK_TIMEOUT = 8 # seconds; bounds offline/DNS hangs so the GUI never blocks
|
||||
|
||||
|
||||
class _UpdateCheckThread(QThread):
|
||||
"""Fetch the remote VERSION file off the GUI thread."""
|
||||
|
||||
succeeded = pyqtSignal(str)
|
||||
failed = pyqtSignal(str)
|
||||
|
||||
def run(self):
|
||||
import urllib.request
|
||||
|
||||
try:
|
||||
with urllib.request.urlopen(
|
||||
_UPDATE_CHECK_URL, timeout=_UPDATE_CHECK_TIMEOUT
|
||||
) as response:
|
||||
self.succeeded.emit(response.read().decode().strip())
|
||||
except Exception as exc: # offline, DNS hang, HTTP error, ...
|
||||
self.failed.emit(str(exc))
|
||||
|
||||
|
||||
class IconProvider(QFileIconProvider):
|
||||
def icon(self, fileInfo):
|
||||
return super().icon(fileInfo)
|
||||
@@ -397,11 +424,7 @@ class InputBox(QLabel):
|
||||
# Re-enable subtitle and replace newlines controls when cleared
|
||||
window = self.window()
|
||||
if hasattr(window, "subtitle_combo"):
|
||||
# Only enable if language supports it
|
||||
current_lang = getattr(window, "selected_lang", "a")
|
||||
window.subtitle_combo.setEnabled(
|
||||
current_lang in SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION
|
||||
)
|
||||
window.subtitle_combo.setEnabled(True)
|
||||
if hasattr(window, "replace_newlines_combo"):
|
||||
window.replace_newlines_combo.setEnabled(True)
|
||||
|
||||
@@ -941,7 +964,7 @@ class abogen(QWidget):
|
||||
self.selected_lang = None
|
||||
else:
|
||||
self.selected_voice = self.config.get("selected_voice", _d["selected_voice"])
|
||||
self.selected_lang = self.selected_voice[0] if self.selected_voice else None
|
||||
self.selected_lang = language_for_voice_id(self.selected_voice)
|
||||
self.is_converting = False
|
||||
self.subtitle_mode = self.config.get("subtitle_mode", _d["subtitle_mode"])
|
||||
self.max_subtitle_words = self.config.get("max_subtitle_words", _d["max_subtitle_words"])
|
||||
@@ -988,7 +1011,12 @@ class abogen(QWidget):
|
||||
self.queued_items = []
|
||||
self.current_queue_index = 0
|
||||
|
||||
self.initUI()
|
||||
from abogen.utils import timed_log
|
||||
import logging
|
||||
_startup_log = logging.getLogger("abogen.startup")
|
||||
|
||||
with timed_log("GUI initUI (widget building)", logger=_startup_log):
|
||||
self.initUI()
|
||||
self.speed_slider.setValue(int(self.config.get("speed", _d["speed"]) * 100))
|
||||
self.update_speed_label()
|
||||
# Set initial selection: prefer profile, else voice
|
||||
@@ -1003,13 +1031,17 @@ class abogen(QWidget):
|
||||
if self.selected_profile_name:
|
||||
from abogen.voice_profiles import load_profiles
|
||||
|
||||
entry = load_profiles().get(self.selected_profile_name, {})
|
||||
with timed_log("voice profile load", logger=_startup_log):
|
||||
entry = load_profiles().get(self.selected_profile_name, {})
|
||||
if isinstance(entry, dict):
|
||||
self.mixed_voice_state = entry.get("voices", [])
|
||||
self.selected_lang = entry.get("language")
|
||||
self.selected_lang = resolve_profile_language(entry)
|
||||
else:
|
||||
self.mixed_voice_state = entry
|
||||
self.selected_lang = entry[0][0] if entry and entry[0] else None
|
||||
self.selected_lang = (
|
||||
language_for_voice_id(entry[0]) if entry and entry[0] else Language.EN_US
|
||||
)
|
||||
self.update_subtitle_options_availability()
|
||||
if self.save_option == "Choose output folder" and self.selected_output_folder:
|
||||
self.save_path_label.setText(self.selected_output_folder)
|
||||
self.save_path_row_widget.show()
|
||||
@@ -1175,6 +1207,7 @@ class abogen(QWidget):
|
||||
"Sentence + Comma: Subtitles will be generated for each sentence and comma.\n"
|
||||
"Sentence + Highlighting: Subtitles with word-by-word karaoke highlighting.\n"
|
||||
"1+ word: Subtitles will be generated for each word(s).\n\n"
|
||||
"Word-count and highlighting modes are only available for English.\n"
|
||||
"Supported languages for subtitle generation:\n"
|
||||
+ "\n".join(
|
||||
f'"{lang}" => {LANGUAGE_DESCRIPTIONS.get(lang, lang)}'
|
||||
@@ -1753,8 +1786,9 @@ class abogen(QWidget):
|
||||
|
||||
def update_subtitle_options_availability(self):
|
||||
"""
|
||||
Update the enabled state of subtitle options based on the selected language.
|
||||
For non-English languages, only sentence-based and line-based modes are supported.
|
||||
Update the enabled state of subtitle options based on the selected
|
||||
language and input type. Subtitle generation works for every language,
|
||||
but word-count and highlighting modes are only available for English.
|
||||
"""
|
||||
# Check if current file is a subtitle file
|
||||
is_subtitle_input = False
|
||||
@@ -1763,16 +1797,14 @@ class abogen(QWidget):
|
||||
):
|
||||
is_subtitle_input = True
|
||||
|
||||
if self.selected_lang not in SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION:
|
||||
self.subtitle_combo.setEnabled(False)
|
||||
self.subtitle_format_combo.setEnabled(False)
|
||||
return
|
||||
|
||||
# Only enable subtitle_combo if it's NOT a subtitle input
|
||||
self.subtitle_combo.setEnabled(not is_subtitle_input)
|
||||
self.subtitle_format_combo.setEnabled(True)
|
||||
|
||||
is_english = self.selected_lang in ["a", "b"]
|
||||
is_english = self.selected_lang in (
|
||||
Language.EN_US,
|
||||
Language.EN_GB,
|
||||
)
|
||||
|
||||
# Items to keep enabled for non-English
|
||||
allowed_modes = ["Disabled", "Line", "Sentence", "Sentence + Comma"]
|
||||
@@ -1787,10 +1819,7 @@ class abogen(QWidget):
|
||||
if is_english:
|
||||
item.setEnabled(True)
|
||||
else:
|
||||
if text in allowed_modes:
|
||||
item.setEnabled(True)
|
||||
else:
|
||||
item.setEnabled(False)
|
||||
item.setEnabled(text in allowed_modes)
|
||||
|
||||
# If current selection is disabled, switch to a valid one
|
||||
current_text = self.subtitle_combo.currentText()
|
||||
@@ -1809,7 +1838,7 @@ class abogen(QWidget):
|
||||
|
||||
def on_voice_changed(self, index):
|
||||
voice = self.voice_combo.itemData(index)
|
||||
self.selected_voice, self.selected_lang = voice, voice[0]
|
||||
self.selected_voice, self.selected_lang = voice, language_for_voice_id(voice)
|
||||
self.config["selected_voice"] = voice
|
||||
save_config(self.config)
|
||||
# Enable/disable subtitle options based on language
|
||||
@@ -1826,10 +1855,12 @@ class abogen(QWidget):
|
||||
# set mixed voices and language
|
||||
if isinstance(entry, dict):
|
||||
self.mixed_voice_state = entry.get("voices", [])
|
||||
self.selected_lang = entry.get("language")
|
||||
self.selected_lang = resolve_profile_language(entry)
|
||||
else:
|
||||
self.mixed_voice_state = entry
|
||||
self.selected_lang = entry[0][0] if entry and entry[0] else None
|
||||
self.selected_lang = (
|
||||
language_for_voice_id(entry[0]) if entry and entry[0] else Language.EN_US
|
||||
)
|
||||
self.selected_voice = None
|
||||
self.config["selected_profile_name"] = pname
|
||||
self.config.pop("selected_voice", None)
|
||||
@@ -1839,7 +1870,7 @@ class abogen(QWidget):
|
||||
else:
|
||||
self.mixed_voice_state = None
|
||||
self.selected_profile_name = None
|
||||
self.selected_voice, self.selected_lang = data, data[0]
|
||||
self.selected_voice, self.selected_lang = data, language_for_voice_id(data)
|
||||
self.config["selected_voice"] = data
|
||||
if "selected_profile_name" in self.config:
|
||||
del self.config["selected_profile_name"]
|
||||
@@ -1850,8 +1881,9 @@ class abogen(QWidget):
|
||||
from abogen.voice_profiles import load_profiles
|
||||
|
||||
entry = load_profiles().get(profile_name, {})
|
||||
lang = entry.get("language") if isinstance(entry, dict) else None
|
||||
enable = lang in SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION
|
||||
enable = (
|
||||
resolve_profile_language(entry) in SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION
|
||||
)
|
||||
self.subtitle_combo.setEnabled(enable)
|
||||
self.subtitle_format_combo.setEnabled(enable)
|
||||
|
||||
@@ -2233,18 +2265,18 @@ class abogen(QWidget):
|
||||
else:
|
||||
return self.selected_voice
|
||||
|
||||
def get_selected_lang(self, voice_formula) -> str:
|
||||
def get_selected_lang(self, voice_formula) -> Language:
|
||||
if self.selected_profile_name:
|
||||
from abogen.voice_profiles import load_profiles
|
||||
|
||||
entry = load_profiles().get(self.selected_profile_name, {})
|
||||
selected_lang = entry.get("language")
|
||||
selected_lang = resolve_profile_language(entry)
|
||||
else:
|
||||
selected_lang = self.selected_voice[0] if self.selected_voice else None
|
||||
selected_lang = language_for_voice_id(self.selected_voice)
|
||||
# fallback: extract from formula if missing
|
||||
if not selected_lang:
|
||||
m = re.search(r"\b([a-z])", voice_formula)
|
||||
selected_lang = m.group(1) if m else None
|
||||
selected_lang = language_for_code(m.group(1)) if m else Language.EN_US
|
||||
return selected_lang
|
||||
|
||||
def get_actual_subtitle_mode(self) -> str:
|
||||
@@ -2420,7 +2452,7 @@ class abogen(QWidget):
|
||||
self.update_log((gpu_msg, gpu_ok))
|
||||
self.update_log("Loading modules...")
|
||||
|
||||
lang_code = self.selected_lang or "a"
|
||||
lang_code = self.selected_lang or Language.EN_US
|
||||
load_thread = LoadPipelineThread(
|
||||
pipeline_loaded_callback, lang_code=lang_code, use_gpu=gpu_ok
|
||||
)
|
||||
@@ -2751,12 +2783,12 @@ class abogen(QWidget):
|
||||
from abogen.voice_profiles import load_profiles
|
||||
|
||||
entry = load_profiles().get(self.selected_profile_name, {})
|
||||
lang_to_cache = entry.get("language")
|
||||
lang_to_cache = resolve_profile_language(entry)
|
||||
else:
|
||||
lang_to_cache = self.selected_lang
|
||||
if not lang_to_cache and self.mixed_voice_state:
|
||||
lang_to_cache = (
|
||||
self.mixed_voice_state[0][0][0]
|
||||
language_for_voice_id(self.mixed_voice_state[0][0])
|
||||
if self.mixed_voice_state and self.mixed_voice_state[0][0]
|
||||
else None
|
||||
)
|
||||
@@ -2860,7 +2892,7 @@ class abogen(QWidget):
|
||||
)
|
||||
self.loading_movie.start()
|
||||
|
||||
lang = self.selected_lang or "a"
|
||||
lang = self.selected_lang or Language.EN_US
|
||||
load_thread = LoadPipelineThread(
|
||||
self._on_pipeline_loaded_for_preview, lang_code=lang, use_gpu=self.gpu_ok
|
||||
)
|
||||
@@ -2892,17 +2924,17 @@ class abogen(QWidget):
|
||||
from abogen.voice_profiles import load_profiles
|
||||
|
||||
entry = load_profiles().get(self.selected_profile_name, {})
|
||||
lang = entry.get("language")
|
||||
lang = resolve_profile_language(entry)
|
||||
else:
|
||||
lang = self.selected_lang
|
||||
if not lang and self.mixed_voice_state:
|
||||
lang = (
|
||||
self.mixed_voice_state[0][0][0]
|
||||
language_for_voice_id(self.mixed_voice_state[0][0])
|
||||
if self.mixed_voice_state and self.mixed_voice_state[0][0]
|
||||
else None
|
||||
)
|
||||
else:
|
||||
lang = self.selected_voice[0]
|
||||
lang = language_for_voice_id(self.selected_voice)
|
||||
voice = self.selected_voice
|
||||
|
||||
# use same gpu/cpu logic as in conversion
|
||||
@@ -3163,14 +3195,25 @@ class abogen(QWidget):
|
||||
save_config(self.config)
|
||||
|
||||
def cleanup_conversion_thread(self):
|
||||
# Stop conversion thread
|
||||
# Stop conversion thread (bounded wait so closing never hangs)
|
||||
if (
|
||||
hasattr(self, "conversion_thread")
|
||||
and self.conversion_thread is not None
|
||||
and self.conversion_thread.isRunning()
|
||||
):
|
||||
_log.info("Close: stopping conversion thread")
|
||||
start = time.perf_counter()
|
||||
self.conversion_thread.cancel()
|
||||
self.conversion_thread.wait()
|
||||
if not self.conversion_thread.wait(2000):
|
||||
_log.warning("Close: conversion thread did not stop in 2s, terminating")
|
||||
self.conversion_thread.terminate()
|
||||
self.conversion_thread.wait(1000)
|
||||
_log.info(
|
||||
"Close: conversion thread stopped in %.2fs",
|
||||
time.perf_counter() - start,
|
||||
)
|
||||
else:
|
||||
_log.info("Close: no running conversion thread")
|
||||
|
||||
def cleanup_preview_threads(self):
|
||||
# Stop preview generation thread
|
||||
@@ -3179,8 +3222,13 @@ class abogen(QWidget):
|
||||
and self.preview_thread is not None
|
||||
and self.preview_thread.isRunning()
|
||||
):
|
||||
_log.info("Close: terminating preview thread")
|
||||
start = time.perf_counter()
|
||||
self.preview_thread.terminate()
|
||||
self.preview_thread.wait()
|
||||
self.preview_thread.wait(1000)
|
||||
_log.info(
|
||||
"Close: preview thread stopped in %.2fs", time.perf_counter() - start
|
||||
)
|
||||
|
||||
# Stop audio playback thread
|
||||
if (
|
||||
@@ -3188,8 +3236,13 @@ class abogen(QWidget):
|
||||
and self.play_audio_thread is not None
|
||||
and self.play_audio_thread.isRunning()
|
||||
):
|
||||
_log.info("Close: stopping audio playback thread")
|
||||
start = time.perf_counter()
|
||||
self.play_audio_thread.stop()
|
||||
self.play_audio_thread.wait()
|
||||
self.play_audio_thread.wait(1000)
|
||||
_log.info(
|
||||
"Close: audio thread stopped in %.2fs", time.perf_counter() - start
|
||||
)
|
||||
|
||||
# Cleanup pygame mixer if initialized
|
||||
try:
|
||||
@@ -3200,6 +3253,7 @@ class abogen(QWidget):
|
||||
pass
|
||||
|
||||
def closeEvent(self, event):
|
||||
_log.info("Close: window close requested (converting=%s)", self.is_converting)
|
||||
if self.is_converting:
|
||||
box = QMessageBox(self)
|
||||
box.setIcon(QMessageBox.Icon.Warning)
|
||||
@@ -3212,16 +3266,14 @@ class abogen(QWidget):
|
||||
)
|
||||
box.setDefaultButton(QMessageBox.StandardButton.No)
|
||||
if box.exec() == QMessageBox.StandardButton.Yes:
|
||||
from abogen import shutdown
|
||||
shutdown.request_shutdown()
|
||||
_log.info("Close: user confirmed exit during conversion")
|
||||
self.cleanup_conversion_thread()
|
||||
self.cleanup_preview_threads()
|
||||
event.accept()
|
||||
else:
|
||||
_log.info("Close: user cancelled exit")
|
||||
event.ignore()
|
||||
else:
|
||||
from abogen import shutdown
|
||||
shutdown.request_shutdown()
|
||||
self.cleanup_conversion_thread()
|
||||
self.cleanup_preview_threads()
|
||||
event.accept()
|
||||
@@ -3948,7 +4000,9 @@ Categories=AudioVideo;Audio;Utility;
|
||||
initial_state = entry.get("voices", [])
|
||||
else:
|
||||
initial_state = entry
|
||||
self.selected_lang = entry[0][0] if entry and entry[0] else None
|
||||
self.selected_lang = (
|
||||
language_for_voice_id(entry[0]) if entry and entry[0] else Language.EN_US
|
||||
)
|
||||
dialog = VoiceFormulaDialog(
|
||||
self, initial_state=initial_state, selected_profile=selected_profile
|
||||
)
|
||||
@@ -4045,75 +4099,85 @@ Categories=AudioVideo;Audio;Utility;
|
||||
self.check_for_updates_startup()
|
||||
|
||||
def check_for_updates_startup(self):
|
||||
import urllib.request
|
||||
|
||||
def show_update_message(remote_version, local_version):
|
||||
msg_box = QMessageBox(self)
|
||||
msg_box.setIcon(QMessageBox.Icon.Information)
|
||||
msg_box.setWindowTitle("Update Available")
|
||||
msg_box.setText(
|
||||
f"A new version of {PROGRAM_NAME} is available! ({local_version} > {remote_version})"
|
||||
)
|
||||
msg_box.setInformativeText(
|
||||
f"If you installed via pip, update by running:\n"
|
||||
f"pip install --upgrade {PROGRAM_NAME}\n\n"
|
||||
f"If you're using the Windows portable version, run 'WINDOWS_INSTALL.bat' again.\n\n"
|
||||
"Alternatively, visit the GitHub repository for more information. "
|
||||
"Would you like to view the changelog?"
|
||||
)
|
||||
msg_box.setStandardButtons(
|
||||
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No
|
||||
)
|
||||
msg_box.setDefaultButton(QMessageBox.StandardButton.Yes)
|
||||
if msg_box.exec() == QMessageBox.StandardButton.Yes:
|
||||
try:
|
||||
QDesktopServices.openUrl(QUrl(GITHUB_URL + "/releases/latest"))
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
# Reset flag to track if we should show "no updates" message
|
||||
# Network I/O runs in a worker thread: urlopen without a timeout on
|
||||
# the GUI thread froze the whole app when offline (DNS/connect can
|
||||
# hang for minutes). Results return via signals on the GUI thread.
|
||||
thread = getattr(self, "_update_check_thread", None)
|
||||
if thread is not None:
|
||||
try:
|
||||
if thread.isRunning():
|
||||
return
|
||||
except RuntimeError:
|
||||
pass # previous thread already finished/deleted
|
||||
show_result = (
|
||||
hasattr(self, "_show_update_check_result")
|
||||
and self._show_update_check_result
|
||||
)
|
||||
self._show_update_check_result = False
|
||||
self._update_check_thread = _UpdateCheckThread(self)
|
||||
self._update_check_thread.succeeded.connect(
|
||||
lambda remote_raw: self._on_update_check_done(remote_raw, show_result)
|
||||
)
|
||||
self._update_check_thread.failed.connect(
|
||||
lambda err: self._on_update_check_failed(err, show_result)
|
||||
)
|
||||
self._update_check_thread.finished.connect(
|
||||
self._update_check_thread.deleteLater
|
||||
)
|
||||
self._update_check_thread.start()
|
||||
|
||||
def _on_update_check_done(self, remote_raw, show_result):
|
||||
remote_version = remote_raw.strip()
|
||||
local_version = VERSION
|
||||
try:
|
||||
update_url = "https://raw.githubusercontent.com/denizsafak/abogen/refs/heads/main/abogen/VERSION"
|
||||
with urllib.request.urlopen(update_url) as response:
|
||||
remote_raw = response.read().decode().strip()
|
||||
local_raw = VERSION
|
||||
remote_num = int("".join(remote_version.split(".")))
|
||||
local_num = int("".join(local_version.split(".")))
|
||||
except ValueError:
|
||||
return
|
||||
if remote_num > local_num:
|
||||
# Use QTimer to ensure UI is ready, then show update message.
|
||||
QTimer.singleShot(
|
||||
1000,
|
||||
lambda: self._show_update_message(remote_version, local_version),
|
||||
)
|
||||
elif show_result:
|
||||
QMessageBox.information(
|
||||
self,
|
||||
"Up to Date",
|
||||
f"You are running the latest version of {PROGRAM_NAME} ({local_version}).",
|
||||
)
|
||||
|
||||
# Parse version numbers
|
||||
remote_version = remote_raw
|
||||
local_version = local_raw
|
||||
def _on_update_check_failed(self, err, show_result):
|
||||
if show_result:
|
||||
QMessageBox.warning(
|
||||
self,
|
||||
"Update Check Failed",
|
||||
f"Could not check for updates:\n{err}",
|
||||
)
|
||||
|
||||
def _show_update_message(self, remote_version, local_version):
|
||||
msg_box = QMessageBox(self)
|
||||
msg_box.setIcon(QMessageBox.Icon.Information)
|
||||
msg_box.setWindowTitle("Update Available")
|
||||
msg_box.setText(
|
||||
f"A new version of {PROGRAM_NAME} is available! ({local_version} > {remote_version})"
|
||||
)
|
||||
msg_box.setInformativeText(
|
||||
f"If you installed via pip, update by running:\n"
|
||||
f"pip install --upgrade {PROGRAM_NAME}\n\n"
|
||||
f"If you're using the Windows portable version, run 'WINDOWS_INSTALL.bat' again.\n\n"
|
||||
"Alternatively, visit the GitHub repository for more information. "
|
||||
"Would you like to view the changelog?"
|
||||
)
|
||||
msg_box.setStandardButtons(
|
||||
QMessageBox.StandardButton.Yes | QMessageBox.StandardButton.No
|
||||
)
|
||||
msg_box.setDefaultButton(QMessageBox.StandardButton.Yes)
|
||||
if msg_box.exec() == QMessageBox.StandardButton.Yes:
|
||||
try:
|
||||
remote_num = int("".join(remote_version.split(".")))
|
||||
local_num = int("".join(local_version.split(".")))
|
||||
except ValueError as ve:
|
||||
return
|
||||
|
||||
if remote_num > local_num:
|
||||
# Use QTimer to ensure UI is ready, then show update message.
|
||||
QTimer.singleShot(
|
||||
1000, lambda: show_update_message(remote_version, local_version)
|
||||
)
|
||||
elif show_result:
|
||||
# Show "no updates" message if manually checking
|
||||
QMessageBox.information(
|
||||
self,
|
||||
"Up to Date",
|
||||
f"You are running the latest version of {PROGRAM_NAME} ({local_version}).",
|
||||
)
|
||||
except Exception as e:
|
||||
if show_result:
|
||||
QMessageBox.warning(
|
||||
self,
|
||||
"Update Check Failed",
|
||||
f"Could not check for updates:\n{str(e)}",
|
||||
)
|
||||
pass
|
||||
QDesktopServices.openUrl(QUrl(GITHUB_URL + "/releases/latest"))
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def clear_cache_files(self):
|
||||
"""Clear cache files created by the program."""
|
||||
@@ -4216,8 +4280,6 @@ Categories=AudioVideo;Audio;Utility;
|
||||
|
||||
def set_max_log_lines(self):
|
||||
"""Open a dialog to set the maximum lines in the log window."""
|
||||
from PyQt6.QtWidgets import QInputDialog
|
||||
|
||||
value, ok = QInputDialog.getInt(
|
||||
self,
|
||||
"Max Lines in Log Window",
|
||||
@@ -4239,8 +4301,6 @@ Categories=AudioVideo;Audio;Utility;
|
||||
|
||||
def set_max_subtitle_words(self):
|
||||
"""Open a dialog to set the maximum words per subtitle"""
|
||||
from PyQt6.QtWidgets import QInputDialog
|
||||
|
||||
current_value = self.config.get("max_subtitle_words", _DEFAULTS["max_subtitle_words"])
|
||||
|
||||
value, ok = QInputDialog.getInt(
|
||||
|
||||
+97
-75
@@ -1,3 +1,4 @@
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
import platform
|
||||
@@ -6,103 +7,113 @@ import platform
|
||||
from abogen import shutdown # noqa: F401
|
||||
shutdown.register_shutdown()
|
||||
|
||||
from abogen.utils import get_resource_path, setup_console_logging, timed_log # noqa: E402
|
||||
|
||||
_log = logging.getLogger("abogen.startup")
|
||||
setup_console_logging()
|
||||
|
||||
# Fix PyTorch DLL loading issue ([WinError 1114]) on Windows before importing PyQt6
|
||||
if platform.system() == "Windows":
|
||||
import ctypes
|
||||
from importlib.util import find_spec
|
||||
with timed_log("PyTorch DLLs (Windows)", logger=_log):
|
||||
import ctypes
|
||||
from importlib.util import find_spec
|
||||
|
||||
try:
|
||||
if (
|
||||
(spec := find_spec("torch"))
|
||||
and spec.origin
|
||||
and os.path.exists(
|
||||
dll_path := os.path.join(os.path.dirname(spec.origin), "lib", "c10.dll")
|
||||
)
|
||||
):
|
||||
ctypes.CDLL(os.path.normpath(dll_path))
|
||||
except Exception:
|
||||
pass
|
||||
try:
|
||||
if (
|
||||
(spec := find_spec("torch"))
|
||||
and spec.origin
|
||||
and os.path.exists(
|
||||
dll_path := os.path.join(os.path.dirname(spec.origin), "lib", "c10.dll")
|
||||
)
|
||||
):
|
||||
ctypes.CDLL(os.path.normpath(dll_path))
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
# Qt platform plugin detection (fixes #59)
|
||||
try:
|
||||
from PyQt6.QtCore import QLibraryInfo
|
||||
with timed_log("Qt platform plugin detection", logger=_log):
|
||||
try:
|
||||
from PyQt6.QtCore import QLibraryInfo
|
||||
|
||||
# Get the path to the plugins directory
|
||||
plugins = QLibraryInfo.path(QLibraryInfo.LibraryPath.PluginsPath)
|
||||
# Get the path to the plugins directory
|
||||
plugins = QLibraryInfo.path(QLibraryInfo.LibraryPath.PluginsPath)
|
||||
|
||||
# Normalize path to use the OS-native separators and absolute path
|
||||
platform_dir = os.path.normpath(os.path.join(plugins, "platforms"))
|
||||
# Normalize path to use the OS-native separators and absolute path
|
||||
platform_dir = os.path.normpath(os.path.join(plugins, "platforms"))
|
||||
|
||||
# Ensure we work with an absolute path for clarity
|
||||
platform_dir = os.path.abspath(platform_dir)
|
||||
# Ensure we work with an absolute path for clarity
|
||||
platform_dir = os.path.abspath(platform_dir)
|
||||
|
||||
if os.path.isdir(platform_dir):
|
||||
os.environ["QT_QPA_PLATFORM_PLUGIN_PATH"] = platform_dir
|
||||
print("QT_QPA_PLATFORM_PLUGIN_PATH set to:", platform_dir)
|
||||
else:
|
||||
print("PyQt6 platform plugins not found at", platform_dir)
|
||||
except ImportError:
|
||||
print("PyQt6 not installed.")
|
||||
if os.path.isdir(platform_dir):
|
||||
os.environ["QT_QPA_PLATFORM_PLUGIN_PATH"] = platform_dir
|
||||
_log.info("QT_QPA_PLATFORM_PLUGIN_PATH set to: %s", platform_dir)
|
||||
else:
|
||||
_log.warning("PyQt6 platform plugins not found at %s", platform_dir)
|
||||
except ImportError:
|
||||
_log.warning("PyQt6 not installed.")
|
||||
|
||||
|
||||
from abogen.utils import get_resource_path
|
||||
|
||||
# Pre-load "libxcb-cursor" on Linux (fixes #101)
|
||||
if platform.system() == "Linux":
|
||||
arch = platform.machine().lower()
|
||||
lib_filename = {"x86_64": "libxcb-cursor-amd64.so.0", "amd64": "libxcb-cursor-amd64.so.0", "aarch64": "libxcb-cursor-arm64.so.0", "arm64": "libxcb-cursor-arm64.so.0"}.get(arch)
|
||||
if lib_filename:
|
||||
import ctypes
|
||||
try:
|
||||
# Try to load the system libxcb-cursor.so.0 first
|
||||
ctypes.CDLL('libxcb-cursor.so.0', mode=ctypes.RTLD_GLOBAL)
|
||||
except OSError:
|
||||
# System lib not available, load the bundled version
|
||||
lib_path = get_resource_path('abogen.libs', lib_filename)
|
||||
if lib_path:
|
||||
try:
|
||||
ctypes.CDLL(lib_path, mode=ctypes.RTLD_GLOBAL)
|
||||
except OSError:
|
||||
# If it fails (e.g. wrong glibc version on very old systems),
|
||||
# we simply ignore it and hope the system has the library.
|
||||
pass
|
||||
with timed_log("libxcb-cursor preload (Linux)", logger=_log):
|
||||
arch = platform.machine().lower()
|
||||
lib_filename = {"x86_64": "libxcb-cursor-amd64.so.0", "amd64": "libxcb-cursor-amd64.so.0", "aarch64": "libxcb-cursor-arm64.so.0", "arm64": "libxcb-cursor-arm64.so.0"}.get(arch)
|
||||
if lib_filename:
|
||||
import ctypes
|
||||
try:
|
||||
# Try to load the system libxcb-cursor.so.0 first
|
||||
ctypes.CDLL('libxcb-cursor.so.0', mode=ctypes.RTLD_GLOBAL)
|
||||
except OSError:
|
||||
# System lib not available, load the bundled version
|
||||
lib_path = get_resource_path('abogen.libs', lib_filename)
|
||||
if lib_path:
|
||||
try:
|
||||
ctypes.CDLL(lib_path, mode=ctypes.RTLD_GLOBAL)
|
||||
except OSError:
|
||||
# If it fails (e.g. wrong glibc version on very old systems),
|
||||
# we simply ignore it and hope the system has the library.
|
||||
pass
|
||||
|
||||
|
||||
# Set application ID for Windows taskbar icon
|
||||
if platform.system() == "Windows":
|
||||
try:
|
||||
from abogen.constants import PROGRAM_NAME, VERSION
|
||||
import ctypes
|
||||
with timed_log("Windows AppUserModelID", logger=_log):
|
||||
try:
|
||||
from abogen.constants import PROGRAM_NAME, VERSION
|
||||
import ctypes
|
||||
|
||||
app_id = f"{PROGRAM_NAME}.{VERSION}"
|
||||
ctypes.windll.shell32.SetCurrentProcessExplicitAppUserModelID(app_id)
|
||||
except Exception as e:
|
||||
print("Warning: failed to set AppUserModelID:", e)
|
||||
app_id = f"{PROGRAM_NAME}.{VERSION}"
|
||||
ctypes.windll.shell32.SetCurrentProcessExplicitAppUserModelID(app_id)
|
||||
except Exception as e:
|
||||
_log.warning("Failed to set AppUserModelID: %s", e)
|
||||
|
||||
from PyQt6.QtWidgets import QApplication
|
||||
from PyQt6.QtGui import QIcon
|
||||
from PyQt6.QtCore import (
|
||||
QLibraryInfo,
|
||||
qInstallMessageHandler,
|
||||
QtMsgType,
|
||||
)
|
||||
with timed_log("PyQt6 imports", logger=_log):
|
||||
from PyQt6.QtWidgets import QApplication
|
||||
from PyQt6.QtGui import QIcon
|
||||
from PyQt6.QtCore import (
|
||||
QLibraryInfo,
|
||||
qInstallMessageHandler,
|
||||
QtMsgType,
|
||||
)
|
||||
|
||||
# Add the directory to Python path
|
||||
sys.path.insert(0, os.path.join(os.path.dirname(__file__)))
|
||||
|
||||
# Set Hugging Face Hub environment variables
|
||||
os.environ["HF_HUB_DISABLE_TELEMETRY"] = "1" # Disable Hugging Face telemetry
|
||||
os.environ["HF_HUB_ETAG_TIMEOUT"] = "10" # Metadata request timeout (seconds)
|
||||
os.environ["HF_HUB_DOWNLOAD_TIMEOUT"] = "10" # File download timeout (seconds)
|
||||
os.environ["HF_HUB_DISABLE_SYMLINKS_WARNING"] = "1" # Disable symlinks warning
|
||||
from abogen.utils import load_config
|
||||
if load_config().get("disable_kokoro_internet", False):
|
||||
print("INFO: Kokoro's internet access is disabled.")
|
||||
os.environ["HF_HUB_OFFLINE"] = "1" # Disable Hugging Face Hub internet access
|
||||
with timed_log("config load + HF env setup", logger=_log):
|
||||
os.environ["HF_HUB_DISABLE_TELEMETRY"] = "1" # Disable Hugging Face telemetry
|
||||
os.environ["HF_HUB_ETAG_TIMEOUT"] = "10" # Metadata request timeout (seconds)
|
||||
os.environ["HF_HUB_DOWNLOAD_TIMEOUT"] = "10" # File download timeout (seconds)
|
||||
os.environ["HF_HUB_DISABLE_SYMLINKS_WARNING"] = "1" # Disable symlinks warning
|
||||
from abogen.utils import load_config
|
||||
if load_config().get("disable_kokoro_internet", False):
|
||||
_log.info("Kokoro's internet access is disabled.")
|
||||
os.environ["HF_HUB_OFFLINE"] = "1" # Disable Hugging Face Hub internet access
|
||||
|
||||
from abogen.pyqt.gui import abogen
|
||||
from abogen.constants import PROGRAM_NAME, VERSION
|
||||
with timed_log("GUI module import (abogen.pyqt.gui)", logger=_log):
|
||||
from abogen.pyqt.gui import abogen
|
||||
from abogen.constants import PROGRAM_NAME, VERSION
|
||||
|
||||
# Set environment variables for AMD ROCm
|
||||
os.environ["MIOPEN_FIND_MODE"] = "FAST"
|
||||
@@ -150,7 +161,11 @@ if platform.system() == "Linux":
|
||||
|
||||
def main():
|
||||
"""Main entry point for console usage."""
|
||||
app = QApplication(sys.argv)
|
||||
with timed_log("QApplication creation", logger=_log):
|
||||
app = QApplication(sys.argv)
|
||||
|
||||
# Qt shutdown hook must be connected AFTER QApplication exists
|
||||
shutdown.install_qt_hook()
|
||||
|
||||
# Set application icon using get_resource_path from utils
|
||||
icon_path = get_resource_path("abogen.assets", "icon.ico")
|
||||
@@ -164,9 +179,16 @@ def main():
|
||||
except AttributeError:
|
||||
pass
|
||||
|
||||
ex = abogen()
|
||||
ex.show()
|
||||
sys.exit(app.exec())
|
||||
with timed_log("main window construction", logger=_log):
|
||||
ex = abogen()
|
||||
with timed_log("window show", logger=_log):
|
||||
ex.show()
|
||||
_log.info("App startup complete. Showing window.")
|
||||
rc = app.exec()
|
||||
# Restore the default Qt message handler BEFORE interpreter shutdown.
|
||||
# A Python message handler invoked during Qt teardown segfaults (SIGSEGV).
|
||||
qInstallMessageHandler(None)
|
||||
sys.exit(rc)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
|
||||
@@ -28,7 +28,6 @@ from PyQt6.QtWidgets import (
|
||||
from PyQt6.QtCore import Qt, QTimer, QPoint, QRect, QSize
|
||||
from PyQt6.QtGui import QPixmap, QIcon, QAction
|
||||
from abogen.constants import (
|
||||
SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION,
|
||||
LANGUAGE_DESCRIPTIONS,
|
||||
COLORS,
|
||||
)
|
||||
@@ -949,7 +948,9 @@ class VoiceFormulaDialog(QDialog):
|
||||
lang = state.get("language") if isinstance(state, dict) else None
|
||||
# apply language selection
|
||||
if lang:
|
||||
i = self.language_combo.findData(lang)
|
||||
from abogen.voice_profiles import resolve_profile_language
|
||||
|
||||
i = self.language_combo.findData(resolve_profile_language(state))
|
||||
if i >= 0:
|
||||
self.language_combo.blockSignals(True)
|
||||
self.language_combo.setCurrentIndex(i)
|
||||
@@ -1571,9 +1572,10 @@ class VoiceFormulaDialog(QDialog):
|
||||
parent.selected_profile_name = None
|
||||
lang = self.language_combo.currentData()
|
||||
parent.selected_lang = lang
|
||||
parent.subtitle_combo.setEnabled(
|
||||
lang in SUPPORTED_LANGUAGES_FOR_SUBTITLE_GENERATION
|
||||
)
|
||||
if hasattr(parent, "update_subtitle_options_availability"):
|
||||
parent.update_subtitle_options_availability()
|
||||
else:
|
||||
parent.subtitle_combo.setEnabled(True)
|
||||
# Reset start flag and trigger preview
|
||||
self._started = False
|
||||
parent.preview_voice()
|
||||
|
||||
+21
-3
@@ -14,10 +14,14 @@ Per-conversion cleanup lives in run_conversion() finally block.
|
||||
from __future__ import annotations
|
||||
|
||||
import atexit
|
||||
import logging
|
||||
import signal
|
||||
import sys
|
||||
import time
|
||||
from typing import Callable
|
||||
|
||||
_log = logging.getLogger("abogen.shutdown")
|
||||
|
||||
_CLEANUP_FUNCS: list[Callable[[], None]] = []
|
||||
_EXECUTED = False
|
||||
|
||||
@@ -32,11 +36,17 @@ def _run_cleanups() -> None:
|
||||
if _EXECUTED:
|
||||
return
|
||||
_EXECUTED = True
|
||||
_log.info("Shutdown: starting %d cleanup hook(s)", len(_CLEANUP_FUNCS))
|
||||
for fn in _CLEANUP_FUNCS:
|
||||
start = time.perf_counter()
|
||||
try:
|
||||
fn()
|
||||
except Exception:
|
||||
pass
|
||||
_log.info(
|
||||
"Shutdown: %s done in %.2fs", fn.__name__, time.perf_counter() - start
|
||||
)
|
||||
_log.info("Shutdown: all cleanups finished")
|
||||
|
||||
|
||||
# ---- Process-level cleanup functions ----
|
||||
@@ -117,13 +127,19 @@ def register_shutdown() -> None:
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
# Qt hook — connect AFTER QApplication is created
|
||||
install_qt_hook()
|
||||
|
||||
|
||||
def install_qt_hook() -> None:
|
||||
"""Connect Qt aboutToQuit to cleanup. Must run AFTER QApplication is created."""
|
||||
try:
|
||||
from PyQt6.QtWidgets import QApplication
|
||||
|
||||
app = QApplication.instance()
|
||||
if app is not None:
|
||||
if app is not None and not getattr(app, "_abogen_cleanup_connected", False):
|
||||
app.aboutToQuit.connect(_run_cleanups)
|
||||
app._abogen_cleanup_connected = True
|
||||
_log.info("Shutdown: Qt aboutToQuit hook connected")
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
@@ -132,13 +148,15 @@ register_shutdown._registered = False
|
||||
|
||||
|
||||
def _on_signal(signum: int, _frame) -> None:
|
||||
_log.info("Shutdown: signal %s received", signum)
|
||||
_run_cleanups()
|
||||
sys.exit(0)
|
||||
|
||||
|
||||
def request_shutdown() -> None:
|
||||
"""Programmatically trigger cleanup (e.g., from GUI closeEvent)."""
|
||||
_log.info("Shutdown: cleanup requested")
|
||||
_run_cleanups()
|
||||
|
||||
|
||||
__all__ = ["register_shutdown", "request_shutdown", "register_cleanup"]
|
||||
__all__ = ["register_shutdown", "install_qt_hook", "request_shutdown", "register_cleanup"]
|
||||
|
||||
@@ -6,10 +6,9 @@ from dataclasses import dataclass
|
||||
from functools import lru_cache
|
||||
from typing import Any, Dict, Optional, Tuple
|
||||
|
||||
try: # pragma: no cover - optional dependency
|
||||
import spacy
|
||||
except Exception: # pragma: no cover - spaCy unavailable at runtime
|
||||
spacy = None
|
||||
# spaCy is intentionally NOT imported at module level: importing it pulls in
|
||||
# thinc -> torch, which costs seconds of startup time. It is imported lazily
|
||||
# inside _load_spacy_model below.
|
||||
|
||||
# Lazy spaCy type hints to avoid a hard dependency at import time.
|
||||
Language = Any # type: ignore[assignment]
|
||||
@@ -37,7 +36,9 @@ _DEFAULT_MODEL = os.environ.get("ABOGEN_SPACY_MODEL", "en_core_web_sm")
|
||||
|
||||
@lru_cache(maxsize=1)
|
||||
def _load_spacy_model(model: str = _DEFAULT_MODEL) -> Optional[Language]:
|
||||
if spacy is None:
|
||||
try: # pragma: no cover - optional dependency
|
||||
import spacy
|
||||
except Exception: # pragma: no cover - spaCy unavailable at runtime
|
||||
logger.debug("spaCy is not installed; skipping contraction disambiguation")
|
||||
return None
|
||||
|
||||
|
||||
@@ -57,7 +57,9 @@ def get_spacy_model(language: Language, log_callback=None):
|
||||
print(msg)
|
||||
|
||||
if not isinstance(language, Language):
|
||||
raise TypeError(f"language must be Language enum, got {type(language).__name__}: {language!r}")
|
||||
raise TypeError(
|
||||
f"language must be Language enum, got {type(language).__name__}: {language!r}"
|
||||
)
|
||||
|
||||
if language in _nlp_cache:
|
||||
return _nlp_cache[language]
|
||||
|
||||
@@ -79,6 +79,44 @@ class SynthesisRequest:
|
||||
format: AudioFormat
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class TokenTiming:
|
||||
"""Per-token timing within a synthesized segment.
|
||||
|
||||
Attributes:
|
||||
text: Token text.
|
||||
whitespace: Whitespace following the token ("" if none).
|
||||
start: Start time in seconds (relative to segment start).
|
||||
end: End time in seconds (relative to segment start).
|
||||
"""
|
||||
|
||||
text: str
|
||||
whitespace: str = ""
|
||||
start: float = 0.0
|
||||
end: float = 0.0
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class AudioSegment:
|
||||
"""One contiguous synthesized segment (sentence-level chunk).
|
||||
|
||||
Engines that split the input text (via ``split_pattern``) expose each
|
||||
chunk as its own AudioSegment so hosts can report per-sentence progress
|
||||
and build subtitles from per-token timings.
|
||||
|
||||
Attributes:
|
||||
graphemes: The text this segment was synthesized from.
|
||||
audio: Raw float32 PCM audio bytes for this segment.
|
||||
sample_rate: Sample rate of ``audio``.
|
||||
tokens: Per-token timing details, when the engine provides them.
|
||||
"""
|
||||
|
||||
graphemes: str
|
||||
audio: bytes
|
||||
sample_rate: int
|
||||
tokens: tuple[TokenTiming, ...] = ()
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class SynthesizedAudio:
|
||||
"""Immutable value object for synthesized audio result.
|
||||
@@ -87,11 +125,15 @@ class SynthesizedAudio:
|
||||
data: Raw audio bytes.
|
||||
format: Audio format of the result.
|
||||
duration: Duration of the audio.
|
||||
segments: Per-segment details when the engine split the text into
|
||||
sentence-level chunks (empty for engines that only produce a
|
||||
single merged result).
|
||||
"""
|
||||
|
||||
data: bytes
|
||||
format: AudioFormat
|
||||
duration: Duration
|
||||
segments: tuple[AudioSegment, ...] = ()
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
|
||||
@@ -169,15 +169,38 @@ class Pipeline:
|
||||
)
|
||||
|
||||
result = session.synthesize(request)
|
||||
audio_array = np.frombuffer(result.data, dtype=np.float32)
|
||||
|
||||
from dataclasses import dataclass
|
||||
from dataclasses import dataclass, field
|
||||
|
||||
@dataclass
|
||||
class Token:
|
||||
text: str
|
||||
whitespace: str = ""
|
||||
start_ts: float = 0.0
|
||||
end_ts: float = 0.0
|
||||
|
||||
@dataclass
|
||||
class Segment:
|
||||
graphemes: str
|
||||
audio: np.ndarray
|
||||
tokens: list[Any] = field(default_factory=list)
|
||||
|
||||
if result.segments:
|
||||
for seg in result.segments:
|
||||
audio_array = np.frombuffer(seg.audio, dtype=np.float32)
|
||||
tokens = [
|
||||
Token(
|
||||
text=tok.text,
|
||||
whitespace=tok.whitespace,
|
||||
start_ts=tok.start,
|
||||
end_ts=tok.end,
|
||||
)
|
||||
for tok in seg.tokens
|
||||
]
|
||||
yield Segment(graphemes=seg.graphemes, audio=audio_array, tokens=tokens)
|
||||
return
|
||||
|
||||
audio_array = np.frombuffer(result.data, dtype=np.float32)
|
||||
yield Segment(graphemes=text, audio=audio_array)
|
||||
|
||||
def load_single_voice(self, voice_name: str) -> Any:
|
||||
|
||||
+133
-10
@@ -6,7 +6,9 @@ import re
|
||||
import shutil
|
||||
import subprocess
|
||||
import sys
|
||||
import time
|
||||
import warnings
|
||||
from contextlib import contextmanager
|
||||
from threading import Thread
|
||||
from typing import Dict, Optional
|
||||
|
||||
@@ -14,6 +16,8 @@ from functools import lru_cache
|
||||
|
||||
from dotenv import load_dotenv, find_dotenv
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _load_environment() -> None:
|
||||
explicit_path = os.environ.get("ABOGEN_ENV_FILE")
|
||||
@@ -29,6 +33,125 @@ _load_environment()
|
||||
|
||||
warnings.filterwarnings("ignore")
|
||||
|
||||
# --- Console log colorization via rich (mirrors AutoSubSync's approach) ---
|
||||
|
||||
try: # rich is a declared dependency, but degrade gracefully if unavailable
|
||||
from rich.console import Console
|
||||
from rich.highlighter import NullHighlighter
|
||||
from rich.logging import RichHandler
|
||||
|
||||
_RICH_AVAILABLE = True
|
||||
except Exception: # pragma: no cover - fallback to plain logging
|
||||
Console = None
|
||||
NullHighlighter = None
|
||||
RichHandler = None
|
||||
_RICH_AVAILABLE = False
|
||||
|
||||
|
||||
def _console_supports_color() -> bool:
|
||||
if os.environ.get("NO_COLOR"):
|
||||
return False
|
||||
try:
|
||||
return bool(sys.stderr.isatty())
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
|
||||
_RICH_CONSOLE = None
|
||||
if Console is not None:
|
||||
try:
|
||||
_RICH_CONSOLE = Console(stderr=True, no_color=not _console_supports_color())
|
||||
except Exception: # pragma: no cover - defensive
|
||||
_RICH_CONSOLE = None
|
||||
|
||||
|
||||
_ANSI_ESCAPE_RE = re.compile(r"\x1b\[[0-9;]*[A-Za-z]")
|
||||
|
||||
if RichHandler is not None:
|
||||
|
||||
class RichConsoleHandler(RichHandler):
|
||||
"""RichHandler with default settings, except raw ANSI escapes are
|
||||
stripped from messages first (werkzeug colorizes its own log lines
|
||||
when attached to a TTY; without this they render as literal "[36m"
|
||||
fragments)."""
|
||||
|
||||
def emit(self, record):
|
||||
# Werkzeug logs its dev-server banner at INFO but hardcodes a
|
||||
# "WARNING: " prefix into the message text. Promote the record so
|
||||
# the level tag matches the content.
|
||||
try:
|
||||
message = _ANSI_ESCAPE_RE.sub("", record.getMessage())
|
||||
except Exception: # pragma: no cover - defensive
|
||||
message = ""
|
||||
if record.levelno < logging.WARNING and message.startswith("WARNING: "):
|
||||
record.levelno = logging.WARNING
|
||||
record.levelname = "WARNING"
|
||||
super().emit(record)
|
||||
|
||||
def render_message(self, record, message):
|
||||
message = _ANSI_ESCAPE_RE.sub("", message)
|
||||
if message.startswith("WARNING: "):
|
||||
message = message[len("WARNING: ") :]
|
||||
return super().render_message(record, message)
|
||||
|
||||
else: # pragma: no cover - rich unavailable fallback
|
||||
RichConsoleHandler = None # type: ignore[assignment, misc]
|
||||
|
||||
|
||||
def console_handler(show_level=True):
|
||||
"""Build a colored console handler. Rich's RichHandler when available
|
||||
(no timestamps, colored level tags), plain StreamHandler otherwise."""
|
||||
if _RICH_CONSOLE is not None and RichConsoleHandler is not None:
|
||||
return RichConsoleHandler(
|
||||
console=_RICH_CONSOLE,
|
||||
show_path=False,
|
||||
show_time=False,
|
||||
rich_tracebacks=True,
|
||||
)
|
||||
handler = logging.StreamHandler(sys.stderr)
|
||||
prefix = "%(levelname)s - " if show_level else ""
|
||||
handler.setFormatter(logging.Formatter(f"{prefix}%(message)s"))
|
||||
return handler
|
||||
|
||||
|
||||
def setup_console_logging(level=logging.INFO):
|
||||
"""Configure the root logger once with a colored console handler."""
|
||||
root = logging.getLogger()
|
||||
if not root.handlers:
|
||||
root.addHandler(console_handler())
|
||||
root.setLevel(level)
|
||||
|
||||
|
||||
@contextmanager
|
||||
def timed_log(label, logger=None, level=logging.INFO):
|
||||
"""Context manager that logs the wall-clock time a block of code takes.
|
||||
|
||||
Used to surface which load/startup steps are slow. The elapsed time is
|
||||
colorized: green < 1s, yellow 1-5s, red > 5s.
|
||||
"""
|
||||
log = logger or logging.getLogger(__name__)
|
||||
start = time.perf_counter()
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
elapsed = time.perf_counter() - start
|
||||
if _RICH_AVAILABLE and _RICH_CONSOLE is not None and not _RICH_CONSOLE.no_color:
|
||||
if elapsed >= 5.0:
|
||||
color = "red"
|
||||
elif elapsed >= 1.0:
|
||||
color = "yellow"
|
||||
else:
|
||||
color = "green"
|
||||
log.log(
|
||||
level,
|
||||
"Loaded %s in %s",
|
||||
f"[cyan]{label}[/cyan]",
|
||||
f"[{color}]{elapsed:.2f}s[/{color}]",
|
||||
extra={"markup": True, "highlighter": NullHighlighter()},
|
||||
)
|
||||
else:
|
||||
log.log(level, "Loaded %s in %.2fs", label, elapsed)
|
||||
|
||||
|
||||
def detect_encoding(file_path):
|
||||
try:
|
||||
@@ -320,10 +443,6 @@ default_encoding = sys.getfilesystemencoding()
|
||||
|
||||
|
||||
def create_process(cmd, stdin=None, text=True, capture_output=False):
|
||||
import logging
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# Configure root logger to output to console if not already configured
|
||||
root = logging.getLogger()
|
||||
if not root.handlers:
|
||||
@@ -372,8 +491,8 @@ def create_process(cmd, stdin=None, text=True, capture_output=False):
|
||||
}
|
||||
)
|
||||
|
||||
# Print the command being executed
|
||||
print(f"Executing: {cmd if isinstance(cmd, str) else ' '.join(cmd)}")
|
||||
# Log the command being executed
|
||||
logger.info(f"Executing: {cmd if isinstance(cmd, str) else ' '.join(cmd)}")
|
||||
|
||||
proc = subprocess.Popen(cmd, **kwargs)
|
||||
|
||||
@@ -494,7 +613,7 @@ def prevent_sleep_start():
|
||||
)
|
||||
else:
|
||||
# Non-systemd distro or systemd tools not installed: skip inhibition rather than crash
|
||||
print(
|
||||
logger.warning(
|
||||
"systemd-inhibit not found: skipping sleep inhibition on this Linux system."
|
||||
)
|
||||
|
||||
@@ -527,9 +646,13 @@ class LoadPipelineThread(Thread):
|
||||
try:
|
||||
from abogen.domain.pipeline_factory import create_pipeline_for_job
|
||||
|
||||
backend = create_pipeline_for_job(
|
||||
"kokoro", language=self.lang_code, use_gpu=self.use_gpu
|
||||
)
|
||||
with timed_log(
|
||||
f"TTS pipeline (lang={self.lang_code}, gpu={self.use_gpu})",
|
||||
logger=logging.getLogger("abogen.startup"),
|
||||
):
|
||||
backend = create_pipeline_for_job(
|
||||
"kokoro", language=self.lang_code, use_gpu=self.use_gpu
|
||||
)
|
||||
self.callback(backend, None)
|
||||
except Exception as e:
|
||||
self.callback(None, str(e))
|
||||
|
||||
@@ -2,6 +2,7 @@ import json
|
||||
import os
|
||||
from typing import Any, Dict, Iterable, List, Tuple
|
||||
|
||||
from abogen.domain.enums import Language
|
||||
from abogen.tts_plugin.utils import get_voices, is_plugin_registered
|
||||
from abogen.utils import get_user_config_path
|
||||
|
||||
@@ -176,13 +177,35 @@ def save_profile(name: str, *, language: str, voices: Iterable) -> None:
|
||||
raise ValueError("At least one voice with a weight above zero is required")
|
||||
|
||||
if not language:
|
||||
language = "a"
|
||||
language = Language.EN_US
|
||||
|
||||
profiles = load_profiles()
|
||||
profiles[name] = {"provider": "kokoro", "language": language, "voices": normalized}
|
||||
save_profiles(profiles)
|
||||
|
||||
|
||||
def resolve_profile_language(entry: Any) -> Language:
|
||||
"""Resolve a profile's stored language to a Language enum.
|
||||
|
||||
New profiles store ISO codes (Language enum values); legacy profiles may
|
||||
store kokoro letter codes ("a", "b", ...). Unparseable values fall back
|
||||
to EN_US.
|
||||
"""
|
||||
|
||||
raw = entry.get("language") if isinstance(entry, dict) else None
|
||||
if isinstance(raw, Language):
|
||||
return raw
|
||||
text = str(raw or "").strip()
|
||||
if not text:
|
||||
return Language.EN_US
|
||||
try:
|
||||
return Language.from_str(text)
|
||||
except ValueError:
|
||||
from plugins.kokoro.engine import language_for_code
|
||||
|
||||
return language_for_code(text)
|
||||
|
||||
|
||||
def remove_profile(name: str) -> None:
|
||||
delete_profile(name)
|
||||
|
||||
|
||||
+65
-43
@@ -9,11 +9,19 @@ from flask import Flask
|
||||
|
||||
from abogen import shutdown # noqa: F401
|
||||
shutdown.register_shutdown()
|
||||
from abogen.utils import get_user_cache_path, get_user_output_path, get_user_settings_dir
|
||||
from abogen.utils import (
|
||||
get_user_cache_path,
|
||||
get_user_output_path,
|
||||
get_user_settings_dir,
|
||||
setup_console_logging,
|
||||
timed_log,
|
||||
)
|
||||
|
||||
from .conversion_runner import run_conversion_job
|
||||
from .service import build_service
|
||||
|
||||
_logger = logging.getLogger("abogen.startup")
|
||||
|
||||
|
||||
class _SuppressSuccessfulAccessFilter(logging.Filter):
|
||||
"""Filter out successful (HTTP 200) werkzeug access logs."""
|
||||
@@ -79,53 +87,57 @@ def _get_secret_key() -> str:
|
||||
|
||||
|
||||
def create_app(config: Optional[dict[str, Any]] = None) -> Flask:
|
||||
uploads_dir, outputs_dir = _default_dirs()
|
||||
with timed_log("default directories", logger=_logger):
|
||||
uploads_dir, outputs_dir = _default_dirs()
|
||||
|
||||
app = Flask(
|
||||
__name__,
|
||||
static_folder="static",
|
||||
template_folder="templates",
|
||||
)
|
||||
base_config = {
|
||||
"SECRET_KEY": _get_secret_key(),
|
||||
"UPLOAD_FOLDER": str(uploads_dir),
|
||||
"OUTPUT_FOLDER": str(outputs_dir),
|
||||
"MAX_CONTENT_LENGTH": 1024 * 1024 * 400, # 400 MB uploads
|
||||
# Large books can submit four form fields per chapter. Werkzeug's
|
||||
# defaults reject those requests before the wizard route can process
|
||||
# them, even though the encoded payload is much smaller than the upload
|
||||
# limit above.
|
||||
"MAX_FORM_MEMORY_SIZE": 10 * 1024 * 1024,
|
||||
"MAX_FORM_PARTS": 10_000,
|
||||
}
|
||||
if config:
|
||||
base_config.update(config)
|
||||
app.config.update(base_config)
|
||||
with timed_log("Flask app creation + config", logger=_logger):
|
||||
app = Flask(
|
||||
__name__,
|
||||
static_folder="static",
|
||||
template_folder="templates",
|
||||
)
|
||||
base_config = {
|
||||
"SECRET_KEY": _get_secret_key(),
|
||||
"UPLOAD_FOLDER": str(uploads_dir),
|
||||
"OUTPUT_FOLDER": str(outputs_dir),
|
||||
"MAX_CONTENT_LENGTH": 1024 * 1024 * 400, # 400 MB uploads
|
||||
# Large books can submit four form fields per chapter. Werkzeug's
|
||||
# defaults reject those requests before the wizard route can process
|
||||
# them, even though the encoded payload is much smaller than the upload
|
||||
# limit above.
|
||||
"MAX_FORM_MEMORY_SIZE": 10 * 1024 * 1024,
|
||||
"MAX_FORM_PARTS": 10_000,
|
||||
}
|
||||
if config:
|
||||
base_config.update(config)
|
||||
app.config.update(base_config)
|
||||
|
||||
service = build_service(
|
||||
runner=run_conversion_job,
|
||||
output_root=Path(app.config["OUTPUT_FOLDER"]),
|
||||
uploads_root=Path(app.config["UPLOAD_FOLDER"]),
|
||||
)
|
||||
with timed_log("conversion service (incl. queue state load)", logger=_logger):
|
||||
service = build_service(
|
||||
runner=run_conversion_job,
|
||||
output_root=Path(app.config["OUTPUT_FOLDER"]),
|
||||
uploads_root=Path(app.config["UPLOAD_FOLDER"]),
|
||||
)
|
||||
app.extensions["conversion_service"] = service
|
||||
|
||||
from abogen.webui.routes import (
|
||||
main_bp,
|
||||
jobs_bp,
|
||||
settings_bp,
|
||||
voices_bp,
|
||||
entities_bp,
|
||||
books_bp,
|
||||
api_bp,
|
||||
)
|
||||
with timed_log("blueprint registration", logger=_logger):
|
||||
from abogen.webui.routes import (
|
||||
main_bp,
|
||||
jobs_bp,
|
||||
settings_bp,
|
||||
voices_bp,
|
||||
entities_bp,
|
||||
books_bp,
|
||||
api_bp,
|
||||
)
|
||||
|
||||
app.register_blueprint(main_bp)
|
||||
app.register_blueprint(jobs_bp, url_prefix="/jobs")
|
||||
app.register_blueprint(settings_bp, url_prefix="/settings")
|
||||
app.register_blueprint(voices_bp, url_prefix="/voices")
|
||||
app.register_blueprint(entities_bp, url_prefix="/overrides")
|
||||
app.register_blueprint(books_bp, url_prefix="/find-books")
|
||||
app.register_blueprint(api_bp, url_prefix="/api")
|
||||
app.register_blueprint(main_bp)
|
||||
app.register_blueprint(jobs_bp, url_prefix="/jobs")
|
||||
app.register_blueprint(settings_bp, url_prefix="/settings")
|
||||
app.register_blueprint(voices_bp, url_prefix="/voices")
|
||||
app.register_blueprint(entities_bp, url_prefix="/overrides")
|
||||
app.register_blueprint(books_bp, url_prefix="/find-books")
|
||||
app.register_blueprint(api_bp, url_prefix="/api")
|
||||
|
||||
global _access_log_filter_attached
|
||||
if not _access_log_filter_attached:
|
||||
@@ -137,6 +149,16 @@ def create_app(config: Optional[dict[str, Any]] = None) -> Flask:
|
||||
|
||||
|
||||
def main() -> None:
|
||||
setup_console_logging()
|
||||
# Route Flask's dev-server banner through our logger instead of click.echo.
|
||||
import flask.cli as flask_cli
|
||||
|
||||
def _show_server_banner(debug, app_import_path):
|
||||
_logger.info(" * Serving Flask app %r", app_import_path)
|
||||
_logger.info(" * Debug mode: %s", "on" if debug else "off")
|
||||
|
||||
flask_cli.show_server_banner = _show_server_banner
|
||||
|
||||
app = create_app()
|
||||
host = os.environ.get("ABOGEN_HOST", "0.0.0.0")
|
||||
port = int(os.environ.get("ABOGEN_PORT", "8808"))
|
||||
|
||||
@@ -47,10 +47,17 @@ def _resolve_voice_setting(value: str) -> tuple[str, Optional[str], Optional[str
|
||||
|
||||
|
||||
def _load_pipeline(language: Language, use_gpu: bool) -> Any:
|
||||
device = "cpu"
|
||||
if use_gpu:
|
||||
device = _select_device()
|
||||
return create_pipeline("kokoro", language=language, device=device)
|
||||
import logging
|
||||
from abogen.utils import timed_log
|
||||
|
||||
with timed_log(
|
||||
f"TTS pipeline (lang={language}, gpu={use_gpu})",
|
||||
logger=logging.getLogger("abogen.startup"),
|
||||
):
|
||||
device = "cpu"
|
||||
if use_gpu:
|
||||
device = _select_device()
|
||||
return create_pipeline("kokoro", language=language, device=device)
|
||||
|
||||
|
||||
def _extract_cases_from_text(text: str) -> List[Tuple[str, str]]:
|
||||
|
||||
@@ -809,6 +809,8 @@ def build_pending_job_from_extraction(
|
||||
analysis_requested=initial_analysis,
|
||||
)
|
||||
|
||||
apply_book_step_form(pending, form, settings=settings, profiles=profiles_map)
|
||||
|
||||
return PendingBuildResult(
|
||||
pending=pending,
|
||||
selected_speaker_config=selected_speaker_config or None,
|
||||
|
||||
@@ -17,7 +17,7 @@ from typing import Any, Callable, Dict, Iterable, List, Optional, Mapping
|
||||
from abogen.domain.metadata_helpers import normalize_metadata_map
|
||||
|
||||
from abogen.domain.enums import Language
|
||||
from abogen.utils import get_internal_cache_path, get_user_settings_dir
|
||||
from abogen.utils import console_handler, get_internal_cache_path, get_user_settings_dir
|
||||
|
||||
|
||||
|
||||
@@ -32,9 +32,7 @@ STATE_VERSION = 8
|
||||
|
||||
_JOB_LOGGER = logging.getLogger("abogen.jobs")
|
||||
if not _JOB_LOGGER.handlers:
|
||||
handler = logging.StreamHandler(sys.stdout)
|
||||
handler.setFormatter(logging.Formatter("%(asctime)s [%(levelname)s] %(message)s", "%Y-%m-%d %H:%M:%S"))
|
||||
_JOB_LOGGER.addHandler(handler)
|
||||
_JOB_LOGGER.addHandler(console_handler())
|
||||
_JOB_LOGGER.propagate = False
|
||||
_JOB_LOGGER.setLevel(logging.DEBUG)
|
||||
|
||||
|
||||
@@ -22,9 +22,11 @@ from abogen.tts_plugin.errors import EngineError
|
||||
from abogen.tts_plugin.manifest import VoiceManifest
|
||||
from abogen.tts_plugin.types import (
|
||||
AudioFormat,
|
||||
AudioSegment,
|
||||
Duration,
|
||||
SynthesisRequest,
|
||||
SynthesizedAudio,
|
||||
TokenTiming,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -73,17 +75,27 @@ def engine_language(lang: Language) -> str:
|
||||
return _KOKORO_LANG_MAP.get(lang, "a")
|
||||
|
||||
|
||||
def language_for_voice_id(voice_id: str) -> Language:
|
||||
def language_for_code(code: str | None) -> Language:
|
||||
"""Map a kokoro engine language code (single letter) to a Language enum.
|
||||
|
||||
Used to resolve legacy data such as old profile files that stored
|
||||
kokoro letter codes. This is kokoro-specific knowledge that stays
|
||||
inside the engine. Unparseable values fall back to EN_US.
|
||||
"""
|
||||
letter = str(code or "").strip()[:1].lower()
|
||||
if letter in _CODE_TO_LANGUAGE:
|
||||
return _CODE_TO_LANGUAGE[letter]
|
||||
return Language.EN_US
|
||||
|
||||
|
||||
def language_for_voice_id(voice_id: str | None) -> Language:
|
||||
"""Determine which Language a voice belongs to from its voice ID.
|
||||
|
||||
Kokoro voice IDs encode language as a prefix (e.g. "af_heart" → "a" → EN_US).
|
||||
This is kokoro-specific knowledge that stays inside the engine.
|
||||
Callers pass a voice ID string; the engine returns a Language enum.
|
||||
"""
|
||||
prefix = str(voice_id or "").strip()[:1].lower()
|
||||
if prefix in _CODE_TO_LANGUAGE:
|
||||
return _CODE_TO_LANGUAGE[prefix]
|
||||
return Language.EN_US
|
||||
return language_for_code(voice_id)
|
||||
|
||||
|
||||
class KokoroSession:
|
||||
@@ -107,7 +119,9 @@ class KokoroSession:
|
||||
speed = request.parameters.values.get("speed", 1.0)
|
||||
split_pattern = request.parameters.values.get("split_pattern", None)
|
||||
|
||||
sample_rate = _KOKORO_SAMPLE_RATE
|
||||
audio_parts: list[np.ndarray] = []
|
||||
segments: list[AudioSegment] = []
|
||||
for segment in self._pipeline(
|
||||
request.text,
|
||||
voice=voice,
|
||||
@@ -117,7 +131,28 @@ class KokoroSession:
|
||||
audio = segment.audio
|
||||
if hasattr(audio, "numpy"):
|
||||
audio = audio.numpy()
|
||||
audio_parts.append(np.asarray(audio, dtype="float32"))
|
||||
audio = np.asarray(audio, dtype="float32")
|
||||
if audio.size == 0:
|
||||
continue
|
||||
audio_parts.append(audio)
|
||||
|
||||
tokens = tuple(
|
||||
TokenTiming(
|
||||
text=str(tok.text),
|
||||
whitespace=str(tok.whitespace or ""),
|
||||
start=float(tok.start_ts or 0.0),
|
||||
end=float(tok.end_ts or 0.0),
|
||||
)
|
||||
for tok in (getattr(segment, "tokens", None) or [])
|
||||
)
|
||||
segments.append(
|
||||
AudioSegment(
|
||||
graphemes=str(getattr(segment, "graphemes", "") or ""),
|
||||
audio=audio.tobytes(),
|
||||
sample_rate=sample_rate,
|
||||
tokens=tokens,
|
||||
)
|
||||
)
|
||||
|
||||
if not audio_parts:
|
||||
return SynthesizedAudio(
|
||||
@@ -128,12 +163,13 @@ class KokoroSession:
|
||||
|
||||
combined = np.concatenate(audio_parts).astype("float32", copy=False)
|
||||
audio_bytes = combined.tobytes()
|
||||
duration_seconds = len(combined) / _KOKORO_SAMPLE_RATE
|
||||
duration_seconds = len(combined) / sample_rate
|
||||
|
||||
return SynthesizedAudio(
|
||||
data=audio_bytes,
|
||||
format=AudioFormat(mime="audio/wav", extension="wav"),
|
||||
duration=Duration(seconds=duration_seconds),
|
||||
segments=tuple(segments),
|
||||
)
|
||||
except EngineError:
|
||||
raise
|
||||
|
||||
@@ -19,6 +19,7 @@ from abogen.tts_plugin.errors import EngineError
|
||||
from abogen.tts_plugin.manifest import VoiceManifest
|
||||
from abogen.tts_plugin.types import (
|
||||
AudioFormat,
|
||||
AudioSegment,
|
||||
Duration,
|
||||
SynthesisRequest,
|
||||
SynthesizedAudio,
|
||||
@@ -113,6 +114,7 @@ class SuperTonicSession:
|
||||
total_steps = int(total_steps)
|
||||
|
||||
audio_parts: list[np.ndarray] = []
|
||||
segments: list[AudioSegment] = []
|
||||
for segment in self._pipeline(
|
||||
request.text,
|
||||
voice=voice,
|
||||
@@ -120,7 +122,17 @@ class SuperTonicSession:
|
||||
split_pattern=split_pattern,
|
||||
total_steps=total_steps,
|
||||
):
|
||||
audio_parts.append(segment.audio)
|
||||
audio = np.asarray(segment.audio, dtype="float32")
|
||||
if audio.size == 0:
|
||||
continue
|
||||
audio_parts.append(audio)
|
||||
segments.append(
|
||||
AudioSegment(
|
||||
graphemes=str(getattr(segment, "graphemes", "") or ""),
|
||||
audio=audio.tobytes(),
|
||||
sample_rate=self._pipeline.sample_rate,
|
||||
)
|
||||
)
|
||||
|
||||
if not audio_parts:
|
||||
return SynthesizedAudio(
|
||||
@@ -139,6 +151,7 @@ class SuperTonicSession:
|
||||
data=audio_bytes,
|
||||
format=AudioFormat(mime="audio/wav", extension="wav"),
|
||||
duration=Duration(seconds=duration_seconds),
|
||||
segments=tuple(segments),
|
||||
)
|
||||
except EngineError:
|
||||
raise
|
||||
|
||||
@@ -50,6 +50,7 @@ dependencies = [
|
||||
"num2words>=0.5.13",
|
||||
"httpx>=0.27.0",
|
||||
"PyQt6>=6.5.0",
|
||||
"rich>=13.0.0",
|
||||
]
|
||||
|
||||
classifiers = [
|
||||
|
||||
+6
-1
@@ -119,7 +119,7 @@ class TestLanguage:
|
||||
def test_supports_subtitle_tokens(self):
|
||||
assert Language.EN_US.supports_subtitle_tokens is True
|
||||
assert Language.EN_GB.supports_subtitle_tokens is True
|
||||
assert Language.ZH.supports_subtitle_tokens is False
|
||||
assert Language.ZH.supports_subtitle_tokens is True
|
||||
|
||||
def test_from_str_case_insensitive(self):
|
||||
assert Language.from_str("EN-US") == Language.EN_US
|
||||
@@ -129,3 +129,8 @@ class TestLanguage:
|
||||
def test_from_str_invalid(self):
|
||||
with pytest.raises(ValueError, match="Invalid Language"):
|
||||
Language.from_str("en")
|
||||
|
||||
def test_kokoro_letter_codes_not_accepted_by_domain(self):
|
||||
# Letter codes are kokoro-engine internals, not domain API.
|
||||
with pytest.raises(ValueError):
|
||||
Language.from_str("a")
|
||||
|
||||
@@ -196,3 +196,42 @@ class TestKokoroVoiceLister:
|
||||
assert isinstance(voice.tags, tuple)
|
||||
assert len(voice.tags) > 0
|
||||
engine.dispose()
|
||||
|
||||
|
||||
# ──────────────────────────────────────────────────────────────
|
||||
# Language mapping helpers
|
||||
# ──────────────────────────────────────────────────────────────
|
||||
|
||||
class TestKokoroLanguageMapping:
|
||||
"""Language resolution helpers: the letter codes live in the engine only."""
|
||||
|
||||
def test_language_for_code(self) -> None:
|
||||
from abogen.domain.enums import Language
|
||||
from plugins.kokoro.engine import language_for_code
|
||||
|
||||
assert language_for_code("a") == Language.EN_US
|
||||
assert language_for_code("b") == Language.EN_GB
|
||||
assert language_for_code("e") == Language.ES
|
||||
assert language_for_code("f") == Language.FR
|
||||
assert language_for_code("h") == Language.HI
|
||||
assert language_for_code("i") == Language.IT
|
||||
assert language_for_code("j") == Language.JA
|
||||
assert language_for_code("p") == Language.PT_BR
|
||||
assert language_for_code("z") == Language.ZH
|
||||
|
||||
def test_language_for_code_fallbacks(self) -> None:
|
||||
from abogen.domain.enums import Language
|
||||
from plugins.kokoro.engine import language_for_code
|
||||
|
||||
assert language_for_code("x") == Language.EN_US
|
||||
assert language_for_code("") == Language.EN_US
|
||||
|
||||
def test_language_for_voice_id(self) -> None:
|
||||
from abogen.domain.enums import Language
|
||||
from plugins.kokoro.engine import language_for_voice_id
|
||||
|
||||
assert language_for_voice_id("af_heart") == Language.EN_US
|
||||
assert language_for_voice_id("bf_emma") == Language.EN_GB
|
||||
assert language_for_voice_id("ef_dora") == Language.ES
|
||||
assert language_for_voice_id("zf_xiaobei") == Language.ZH
|
||||
assert language_for_voice_id("") == Language.EN_US
|
||||
|
||||
@@ -0,0 +1,49 @@
|
||||
import sys
|
||||
import types
|
||||
from pathlib import Path
|
||||
from types import SimpleNamespace
|
||||
|
||||
|
||||
_real_routes = sys.modules.get("abogen.webui.routes")
|
||||
# Import routes.utils.form without executing routes/__init__.py (which imports
|
||||
# every blueprint). Use a temporary namespace package, then restore the real
|
||||
# module so later tests can still `from abogen.webui.routes import ...`.
|
||||
routes_package = types.ModuleType("abogen.webui.routes")
|
||||
routes_package.__path__ = [
|
||||
str(Path(__file__).parents[1] / "abogen" / "webui" / "routes")
|
||||
]
|
||||
sys.modules["abogen.webui.routes"] = routes_package
|
||||
|
||||
from abogen.webui.routes.utils.form import ( # noqa: E402
|
||||
build_pending_job_from_extraction,
|
||||
load_settings,
|
||||
)
|
||||
|
||||
if _real_routes is not None:
|
||||
sys.modules["abogen.webui.routes"] = _real_routes
|
||||
else:
|
||||
del sys.modules["abogen.webui.routes"]
|
||||
|
||||
|
||||
def test_user_metadata_overrides_extraction_fallback(tmp_path: Path) -> None:
|
||||
extraction = SimpleNamespace(
|
||||
chapters=[SimpleNamespace(title="Chapter 1", text="Text")],
|
||||
metadata={"title": "423d828962c34d2b8a53bbe91176305a"},
|
||||
cover_image=None,
|
||||
cover_mime=None,
|
||||
total_characters=4,
|
||||
combined_text="Text",
|
||||
)
|
||||
|
||||
result = build_pending_job_from_extraction(
|
||||
stored_path=tmp_path / "book.txt",
|
||||
original_name="book.txt",
|
||||
extraction=extraction,
|
||||
form={"meta_title": "My Book", "meta_author": "Ada Author"},
|
||||
settings=load_settings(),
|
||||
profiles={},
|
||||
)
|
||||
|
||||
assert result.pending.metadata_tags["title"] == "My Book"
|
||||
assert result.pending.metadata_tags["author"] == "Ada Author"
|
||||
assert result.pending.metadata_tags["authors"] == "Ada Author"
|
||||
@@ -90,3 +90,10 @@ def test_manual_override_normalization():
|
||||
assert normalize_manual_override_token("The") == "the"
|
||||
assert normalize_manual_override_token(" A ") == "a"
|
||||
assert normalize_manual_override_token("word") == "word"
|
||||
|
||||
|
||||
def test_paragraph_breaks_and_ellipsis_preserved():
|
||||
normalized = normalize("Test. Lorem ipsum...\n\nLorem...\n\nLorem ...")
|
||||
assert "\n\n" in normalized
|
||||
assert ". . ." not in normalized
|
||||
assert "Lorem..." in normalized
|
||||
|
||||
@@ -9,7 +9,7 @@ from abogen.domain.enums import Language
|
||||
from abogen.domain.split_pattern import get_split_pattern
|
||||
|
||||
|
||||
# --- English always returns \n ---
|
||||
# --- English: newline-only for Disabled/Line, punctuation-based for sentence modes ---
|
||||
|
||||
class TestEnglish:
|
||||
def test_english_sentence(self):
|
||||
|
||||
@@ -0,0 +1,402 @@
|
||||
"""Comprehensive tests for subtitle generation across different models, modes, and text scenarios.
|
||||
|
||||
Tests include:
|
||||
- Quotation mark handling (straight quotes, curly quotes, guillemets, dialogs)
|
||||
- No spurious spaces after opening quotes (e.g., test "word word" vs test " word word")
|
||||
- Proper sentence boundary detection for quoted dialogues (e.g., "Hello." She said.)
|
||||
- Paragraph handling and multi-line text
|
||||
- All subtitle modes (Line, Sentence, Sentence + Comma, Sentence + Highlighting, N-words)
|
||||
- Both TTS model token styles (Kokoro per-word tokens and Supertonic FakeTokens)
|
||||
- Non-English and multilingual scenarios
|
||||
"""
|
||||
|
||||
import pytest
|
||||
|
||||
from abogen.domain.enums import Language, SubtitleMode
|
||||
from abogen.domain.normalization import prepare_text_for_tts
|
||||
from abogen.domain.subtitle_generation import (
|
||||
process_subtitle_tokens,
|
||||
PUNCTUATION_SENTENCE,
|
||||
PUNCTUATION_SENTENCE_COMMA,
|
||||
)
|
||||
|
||||
|
||||
class TestQuoteNormalizationAndSpacing:
|
||||
"""Verify text normalization correctly preserves quotation mark spacing."""
|
||||
|
||||
def test_straight_quote_mid_sentence_no_extra_space(self):
|
||||
"""Input 'test "word word"' should keep space before quote and no space after."""
|
||||
text = 'test "word word"'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert '" word' not in normalized
|
||||
assert 'test "' in normalized or 'test "word' in normalized
|
||||
|
||||
def test_straight_quote_at_start_no_extra_space(self):
|
||||
"""Input '"word word"' should not have a leading space after opening quote."""
|
||||
text = '"word word"'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert not normalized.startswith('" ')
|
||||
assert normalized.startswith('"word')
|
||||
|
||||
def test_dialogue_quote_spacing(self):
|
||||
"""He said, "Hello world." should preserve proper comma-space-quote-word sequence."""
|
||||
text = 'He said, "Hello world."'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert 'said, "' in normalized or 'said,"' not in normalized
|
||||
assert '" Hello' not in normalized
|
||||
assert '"Hello' in normalized
|
||||
|
||||
def test_quote_with_contraction(self):
|
||||
"""Contraction inside quotes like "Don't go!" should expand cleanly without extra spaces."""
|
||||
text = '"Don\'t go!"'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert '" Do not' not in normalized
|
||||
assert '"Do not' in normalized or '"Don\'t' in normalized
|
||||
|
||||
def test_curly_quotes_preserved(self):
|
||||
"""Curly quotes like “Hello world.” should not have spurious spacing."""
|
||||
text = '“Hello world.”'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert '“ ' not in normalized
|
||||
assert ' ”' not in normalized
|
||||
|
||||
def test_spanish_opening_punctuation(self):
|
||||
"""Spanish inverted exclamation ¡Hola! should not have space after ¡."""
|
||||
text = '¡Hola mundo!'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert '¡ ' not in normalized
|
||||
|
||||
def test_french_guillemets_spacing(self):
|
||||
"""French guillemets « Bonjour » should clean up spaces properly."""
|
||||
text = '« Bonjour »'
|
||||
normalized = prepare_text_for_tts(text)
|
||||
assert '« ' not in normalized
|
||||
assert ' »' not in normalized
|
||||
|
||||
|
||||
class TestKokoroPerWordTokenSubtitles:
|
||||
"""Tests using Kokoro-style per-word tokens with individual timestamps."""
|
||||
|
||||
def test_quoted_phrase_subtitles(self):
|
||||
"""Tokens for 'test "word word"' produce subtitle without space after quote."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.3, "text": "test", "whitespace": " "},
|
||||
{"start": 0.3, "end": 0.35, "text": '"', "whitespace": ""},
|
||||
{"start": 0.35, "end": 0.7, "text": "word", "whitespace": " "},
|
||||
{"start": 0.7, "end": 1.0, "text": "word", "whitespace": ""},
|
||||
{"start": 1.0, "end": 1.05, "text": '"', "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 1
|
||||
assert entries[0][2] == 'test "word word"'
|
||||
|
||||
def test_dialogue_sentence_splitting_regex(self):
|
||||
"""Dialogue ending with ." should split into separate sentence subtitles."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.05, "text": '"', "whitespace": ""},
|
||||
{"start": 0.05, "end": 0.5, "text": "Hello", "whitespace": " "},
|
||||
{"start": 0.5, "end": 0.9, "text": "world.", "whitespace": ""},
|
||||
{"start": 0.9, "end": 0.95, "text": '"', "whitespace": " "},
|
||||
{"start": 0.95, "end": 1.4, "text": "She", "whitespace": " "},
|
||||
{"start": 1.4, "end": 1.8, "text": "smiled.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert entries[0][2] == '"Hello world."'
|
||||
assert entries[1][2] == "She smiled."
|
||||
assert entries[0][0] == 0.0
|
||||
assert entries[0][1] == 0.95
|
||||
assert entries[1][0] == 0.95
|
||||
assert entries[1][1] == 1.8
|
||||
|
||||
def test_question_exclamation_dialogue_splitting(self):
|
||||
"""Dialogue with ?" and !" should split sentences cleanly."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.05, "text": '"', "whitespace": ""},
|
||||
{"start": 0.05, "end": 0.4, "text": "Why?", "whitespace": ""},
|
||||
{"start": 0.4, "end": 0.45, "text": '"', "whitespace": " "},
|
||||
{"start": 0.45, "end": 0.8, "text": "she", "whitespace": " "},
|
||||
{"start": 0.8, "end": 1.2, "text": "asked.", "whitespace": " "},
|
||||
{"start": 1.2, "end": 1.25, "text": '"', "whitespace": ""},
|
||||
{"start": 1.25, "end": 1.7, "text": "Because!", "whitespace": ""},
|
||||
{"start": 1.7, "end": 1.75, "text": '"', "whitespace": " "},
|
||||
{"start": 1.75, "end": 2.0, "text": "he", "whitespace": " "},
|
||||
{"start": 2.0, "end": 2.4, "text": "replied.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 4
|
||||
assert entries[0][2] == '"Why?"'
|
||||
assert entries[1][2] == "she asked."
|
||||
assert entries[2][2] == '"Because!"'
|
||||
assert entries[3][2] == "he replied."
|
||||
|
||||
def test_sentence_comma_mode_with_quotes(self):
|
||||
"""Sentence + Comma mode splits at commas and sentence boundaries."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.4, "text": "First,", "whitespace": " "},
|
||||
{"start": 0.4, "end": 0.8, "text": "she", "whitespace": " "},
|
||||
{"start": 0.8, "end": 1.2, "text": "said,", "whitespace": " "},
|
||||
{"start": 1.2, "end": 1.25, "text": '"', "whitespace": ""},
|
||||
{"start": 1.25, "end": 1.6, "text": "wait.", "whitespace": ""},
|
||||
{"start": 1.6, "end": 1.65, "text": '"', "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence + Comma",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) >= 2
|
||||
assert "First," in entries[0][2]
|
||||
|
||||
def test_karaoke_highlighting_with_quotes(self):
|
||||
"""Sentence + Highlighting generates valid karaoke tags with quotes."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.05, "text": '"', "whitespace": ""},
|
||||
{"start": 0.05, "end": 0.5, "text": "Hello", "whitespace": " "},
|
||||
{"start": 0.5, "end": 0.9, "text": "world.", "whitespace": ""},
|
||||
{"start": 0.9, "end": 0.95, "text": '"', "whitespace": " "},
|
||||
{"start": 0.95, "end": 1.4, "text": "She", "whitespace": " "},
|
||||
{"start": 1.4, "end": 1.8, "text": "said.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence + Highlighting",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert '{\\kf' in entries[0][2]
|
||||
assert '{\\kf' in entries[1][2]
|
||||
assert '"' in entries[0][2]
|
||||
|
||||
def test_word_count_mode_with_quotes(self):
|
||||
"""N-words mode (e.g. '3 words') groups tokens by space count."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.3, "text": "One", "whitespace": " "},
|
||||
{"start": 0.3, "end": 0.35, "text": '"', "whitespace": ""},
|
||||
{"start": 0.35, "end": 0.7, "text": "two", "whitespace": " "},
|
||||
{"start": 0.7, "end": 1.0, "text": "three", "whitespace": ""},
|
||||
{"start": 1.0, "end": 1.05, "text": '"', "whitespace": " "},
|
||||
{"start": 1.05, "end": 1.4, "text": "four", "whitespace": " "},
|
||||
{"start": 1.4, "end": 1.8, "text": "five", "whitespace": " "},
|
||||
{"start": 1.8, "end": 2.2, "text": "six.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="3",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert entries[0][2] == 'One "two three"'
|
||||
assert entries[1][2] == "four five six."
|
||||
|
||||
|
||||
class TestSupertonicAndFakeTokenSubtitles:
|
||||
"""Tests using Supertonic / non-English Kokoro FakeTokens (segment-level stubs)."""
|
||||
|
||||
def test_faketoken_multi_sentence_regex_split(self):
|
||||
"""A single FakeToken containing multiple sentences should split proportionally."""
|
||||
tokens = [
|
||||
{
|
||||
"start": 0.0,
|
||||
"end": 6.0,
|
||||
"text": 'First sentence. "Second quoted sentence." Third sentence.',
|
||||
"whitespace": "",
|
||||
}
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.ES, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 3
|
||||
assert entries[0][2] == "First sentence."
|
||||
assert entries[1][2] == '"Second quoted sentence."'
|
||||
assert entries[2][2] == "Third sentence."
|
||||
assert entries[0][0] == 0.0
|
||||
assert entries[2][1] == 6.0
|
||||
|
||||
def test_faketoken_multi_sentence_spacy_split(self):
|
||||
"""A single FakeToken in English with spaCy should split into separate sentences."""
|
||||
tokens = [
|
||||
{
|
||||
"start": 0.0,
|
||||
"end": 6.0,
|
||||
"text": 'The sun rose high. "Are you ready?" she asked. "Always," he replied.',
|
||||
"whitespace": "",
|
||||
}
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=True
|
||||
)
|
||||
assert len(entries) >= 2
|
||||
assert entries[0][0] == 0.0
|
||||
assert entries[-1][1] == 6.0
|
||||
for e in entries:
|
||||
assert not e[2].startswith('" ')
|
||||
|
||||
def test_faketoken_single_sentence_with_quotes(self):
|
||||
"""Single sentence FakeToken preserves quotes cleanly."""
|
||||
tokens = [
|
||||
{
|
||||
"start": 1.0,
|
||||
"end": 3.5,
|
||||
"text": '"This is a single quoted thought."',
|
||||
"whitespace": "",
|
||||
}
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.FR, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 1
|
||||
assert entries[0][2] == '"This is a single quoted thought."'
|
||||
assert entries[0][0] == 1.0
|
||||
assert entries[0][1] == 3.5
|
||||
|
||||
def test_line_mode_with_faketokens(self):
|
||||
"""Line mode emits one subtitle per line / segment."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 2.0, "text": 'Line 1 with "quotes"', "whitespace": "\n"},
|
||||
{"start": 2.0, "end": 4.0, "text": 'Line 2 with "more quotes"', "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Line",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert entries[0][2] == 'Line 1 with "quotes"'
|
||||
assert entries[1][2] == 'Line 2 with "more quotes"'
|
||||
|
||||
|
||||
class TestComplexParagraphsAndEdgeCases:
|
||||
"""Tests for paragraphs, multiple newlines, and unusual punctuation combinations."""
|
||||
|
||||
def test_paragraph_multi_line_token_flow(self):
|
||||
"""Text spanning paragraphs with multiple sentences."""
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.5, "text": "Paragraph", "whitespace": " "},
|
||||
{"start": 0.5, "end": 1.0, "text": "one.", "whitespace": "\n\n"},
|
||||
{"start": 1.0, "end": 1.5, "text": "Paragraph", "whitespace": " "},
|
||||
{"start": 1.5, "end": 2.0, "text": "two.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert entries[0][2] == "Paragraph one."
|
||||
assert entries[1][2] == "Paragraph two."
|
||||
|
||||
def test_nested_quotes_and_parentheses(self):
|
||||
"""Sentence with nested quotes and parentheses: He said, "(Wait) 'now'!" """
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.3, "text": "He", "whitespace": " "},
|
||||
{"start": 0.3, "end": 0.6, "text": "said,", "whitespace": " "},
|
||||
{"start": 0.6, "end": 0.65, "text": '"', "whitespace": ""},
|
||||
{"start": 0.65, "end": 0.7, "text": "(", "whitespace": ""},
|
||||
{"start": 0.7, "end": 1.0, "text": "Wait", "whitespace": ""},
|
||||
{"start": 1.0, "end": 1.05, "text": ")", "whitespace": " "},
|
||||
{"start": 1.05, "end": 1.1, "text": "'", "whitespace": ""},
|
||||
{"start": 1.1, "end": 1.4, "text": "now", "whitespace": ""},
|
||||
{"start": 1.4, "end": 1.45, "text": "'!", "whitespace": ""},
|
||||
{"start": 1.45, "end": 1.5, "text": '"', "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 1
|
||||
assert entries[0][2] == 'He said, "(Wait) \'now\'!"'
|
||||
|
||||
def test_trailing_quotes_and_ellipsis(self):
|
||||
"""Sentence ending with ellipsis and quote: "I wonder..." """
|
||||
tokens = [
|
||||
{"start": 0.0, "end": 0.05, "text": '"', "whitespace": ""},
|
||||
{"start": 0.05, "end": 0.3, "text": "I", "whitespace": " "},
|
||||
{"start": 0.3, "end": 0.8, "text": "wonder...", "whitespace": ""},
|
||||
{"start": 0.8, "end": 0.85, "text": '"', "whitespace": " "},
|
||||
{"start": 0.85, "end": 1.2, "text": "he", "whitespace": " "},
|
||||
{"start": 1.2, "end": 1.6, "text": "mused.", "whitespace": ""},
|
||||
]
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
tokens, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=False
|
||||
)
|
||||
assert len(entries) == 2
|
||||
assert entries[0][2] == '"I wonder..."'
|
||||
assert entries[1][2] == "he mused."
|
||||
|
||||
|
||||
class TestEllipsisAndParagraphBreaks:
|
||||
"""Regression: '...' sentences merged into one entry; '\\n\\n' flattened.
|
||||
|
||||
spaCy does not treat ellipsis as a sentence boundary, so
|
||||
'Lorem ipsum... Lorem...' stayed a single subtitle entry. And
|
||||
_cleanup_spacing collapsed paragraph breaks before TTS.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def _tok(text_ws, dur=0.5):
|
||||
toks, t = [], 0.0
|
||||
for text, ws in text_ws:
|
||||
toks.append({"start": t, "end": t + dur, "text": text, "whitespace": ws})
|
||||
t += dur
|
||||
return toks, t
|
||||
|
||||
def test_spacy_splits_ellipsis_sentences(self):
|
||||
# Kokoro-style tokens: '...' arrives as 3 dot tokens.
|
||||
toks, end = self._tok([
|
||||
("Test", ""), (".", " "), ("Lorem", " "), ("ipsum", ""),
|
||||
(".", ""), (".", ""), (".", " "),
|
||||
("Lorem", ""), (".", ""), (".", ""), (".", ""),
|
||||
])
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
toks, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=True,
|
||||
fallback_end_time=end,
|
||||
)
|
||||
assert [e[2] for e in entries] == ["Test.", "Lorem ipsum...", "Lorem..."]
|
||||
|
||||
def test_spacy_keeps_abbreviations_intact(self):
|
||||
toks, end = self._tok([
|
||||
("Mr.", " "), ("Smith", " "), ("went", " "), ("home", ""),
|
||||
(".", " "), ("He", " "), ("slept", ""), (".", ""),
|
||||
])
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
toks, entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=True,
|
||||
fallback_end_time=end,
|
||||
)
|
||||
assert [e[2] for e in entries] == ["Mr. Smith went home.", "He slept."]
|
||||
|
||||
def test_spacy_splits_faketoken_ellipsis(self):
|
||||
entries = []
|
||||
process_subtitle_tokens(
|
||||
[{"start": 0.0, "end": 3.0,
|
||||
"text": "Lorem ipsum... Lorem... Lorem...", "whitespace": ""}],
|
||||
entries, max_subtitle_words=50, subtitle_mode="Sentence",
|
||||
language=Language.EN_US, use_spacy_segmentation=True,
|
||||
fallback_end_time=3.0,
|
||||
)
|
||||
assert [e[2] for e in entries] == ["Lorem ipsum...", "Lorem...", "Lorem..."]
|
||||
@@ -177,6 +177,19 @@ class TestAssWriter:
|
||||
assert "Highlight" in content
|
||||
assert r"{\k100}" in content
|
||||
|
||||
def test_highlight_mode_preserves_existing_karaoke_tags(self, tmp_path):
|
||||
path = tmp_path / "test.ass"
|
||||
config = SubtitleConfig(
|
||||
format=SubtitleFormat.ASS,
|
||||
mode=SubtitleMode.SENTENCE_HIGHLIGHT,
|
||||
)
|
||||
writer = AssWriter(path, config)
|
||||
writer.write_entry(start=0.0, end=1.0, text=r"{\kf20}Hello {\kf20}world.")
|
||||
writer.close()
|
||||
content = path.read_text()
|
||||
assert r"{\kf20}Hello {\kf20}world." in content
|
||||
assert r"{\k100}" not in content
|
||||
|
||||
def test_centered_alignment(self, tmp_path):
|
||||
path = tmp_path / "test.ass"
|
||||
config = SubtitleConfig(
|
||||
@@ -243,6 +256,12 @@ class TestCreateSubtitleWriter:
|
||||
with pytest.raises(ValueError):
|
||||
create_subtitle_writer(path, "xyz", "Line")
|
||||
|
||||
def test_word_count_mode(self, tmp_path):
|
||||
path = tmp_path / "test.srt"
|
||||
writer = create_subtitle_writer(path, "srt", "5 words", max_words=5)
|
||||
assert isinstance(writer, SrtWriter)
|
||||
writer.close()
|
||||
|
||||
|
||||
# ===================================================================
|
||||
# Context manager
|
||||
|
||||
@@ -0,0 +1,28 @@
|
||||
"""Tests for voice profile language resolution."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from abogen.domain.enums import Language
|
||||
from abogen.voice_profiles import resolve_profile_language
|
||||
|
||||
|
||||
class TestResolveProfileLanguage:
|
||||
|
||||
def test_iso_code(self) -> None:
|
||||
assert resolve_profile_language({"language": "en-US"}) == Language.EN_US
|
||||
assert resolve_profile_language({"language": "es"}) == Language.ES
|
||||
|
||||
def test_enum_value(self) -> None:
|
||||
assert resolve_profile_language({"language": Language.ZH}) == Language.ZH
|
||||
|
||||
def test_legacy_kokoro_letter(self) -> None:
|
||||
assert resolve_profile_language({"language": "a"}) == Language.EN_US
|
||||
assert resolve_profile_language({"language": "e"}) == Language.ES
|
||||
assert resolve_profile_language({"language": "z"}) == Language.ZH
|
||||
|
||||
def test_missing_or_unparseable_falls_back(self) -> None:
|
||||
assert resolve_profile_language({}) == Language.EN_US
|
||||
assert resolve_profile_language({"language": ""}) == Language.EN_US
|
||||
assert resolve_profile_language({"language": "xx"}) == Language.EN_US
|
||||
assert resolve_profile_language(None) == Language.EN_US
|
||||
assert resolve_profile_language([]) == Language.EN_US
|
||||
Reference in New Issue
Block a user